Cover vs
Season 2, same 18 PDFs: Cover caught 100% of 149 private details, 0 leaked, 12 over-redacted, 3.2 s per PDF. Alibaba Qwen 3 caught 75%, 50 leaked, 188 over-redacted, 4.5 min per PDF. Of 12 engines ranked by mistakes (leaked private details weigh most, and over-redactions count too), Alibaba Qwen 3 places 4th and Cover 1st.
Sending PDFs with private identity information to a cloud Ai like Claude or ChatGPT is a bad idea. But could a local Ai on your own computer redact them instead? This bake-off runs Cover’s engine and the leading local Ai engines on the same 18 bank, tax and medical PDFs. So far the local Ai engines fall behind Cover in three ways: they over-redact, most are slow, and none offer a fast way to fix their mistakes.
PDF selection focuses on money, home and insurance documents. Real-world samples for anyone asking Ai about their own money, or accountants and tax pros who redact a client's documents before asking Ai for a second opinion. Watch Cover's engine improve with each release, even outpacing Google's tech.
- Money 9
- Home 5
- Health & insurance 3
- Taxes 1
| # | engine | PII accuracy | Over-redaction | Speed |
|---|---|---|---|---|
| 1 | 🥇 Cover | Excellent | Very good | Excellent |
| 2 | 🥈 Gemma 4Google | Very good | Very poor | Good |
| 3 | 🥉 Phi-4Microsoft | Good | Very poor | Poor |
| 4 | Qwen 3Alibaba | Good | Very poor | Very poor |
| 5 | Qwen 2.5Alibaba | Poor | Very poor | Good |
| 6 | DeepSeek R1DeepSeek | Poor | Very poor | Very poor |
| 7 | Llama 3.1Meta | Poor | Very poor | Good |
| 8 | Apple IntelligenceApple | Very poor | Very poor | Excellent |
| 9 | Gemma 3Google | Poor | Very poor | Good |
| 10 | Privacy FilterOpenAI | Poor | Very poor | Very good |
| 11 | RampartAmerica.gov | Very poor | Very poor | Excellent |
| 12 | NemotronOpenMed | Very poor | Very poor | Excellent |
Per-page side-by-sides
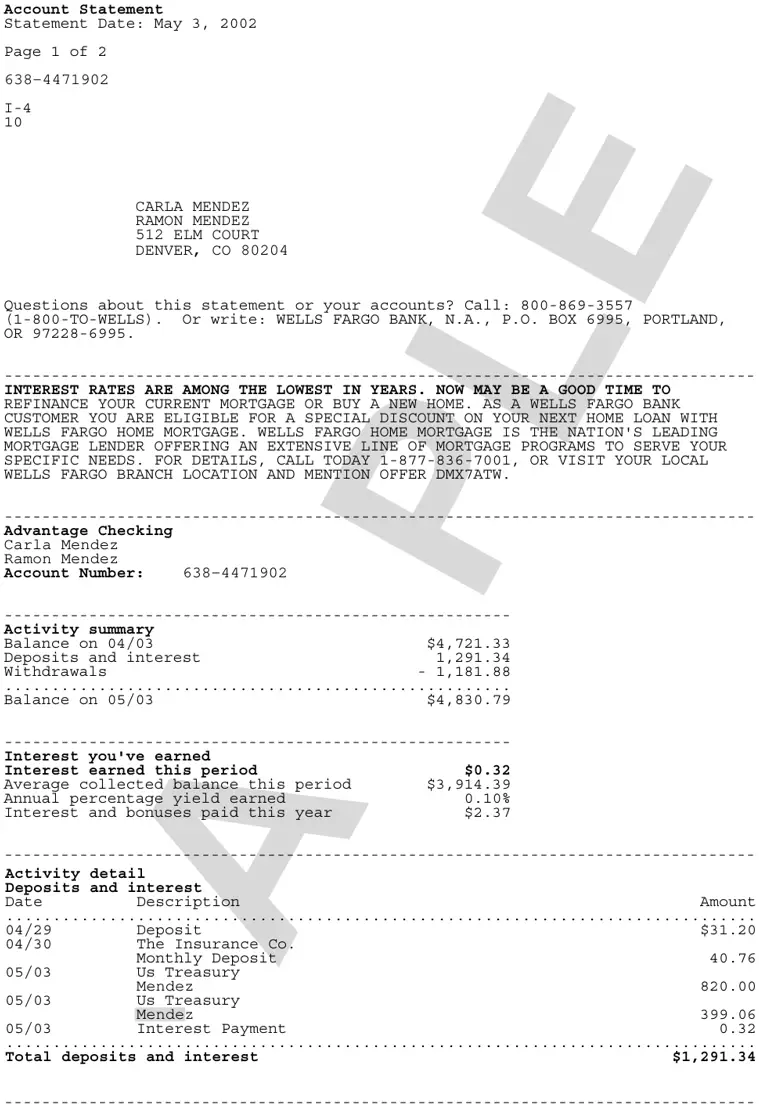
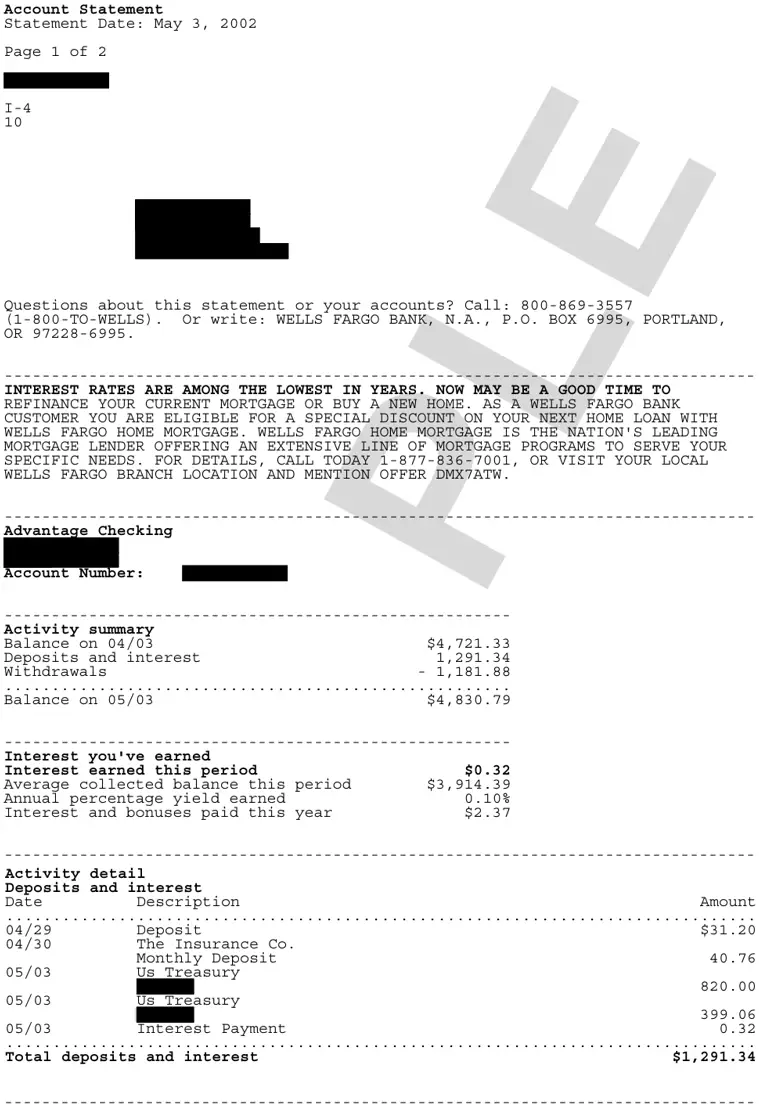
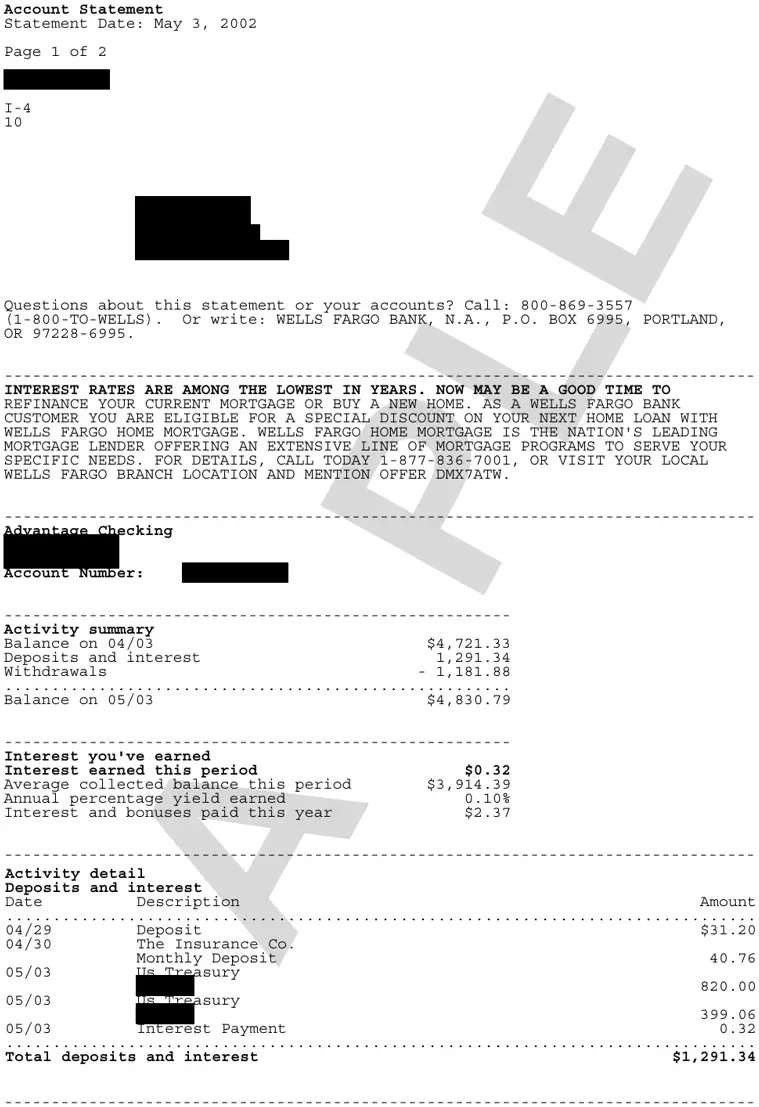
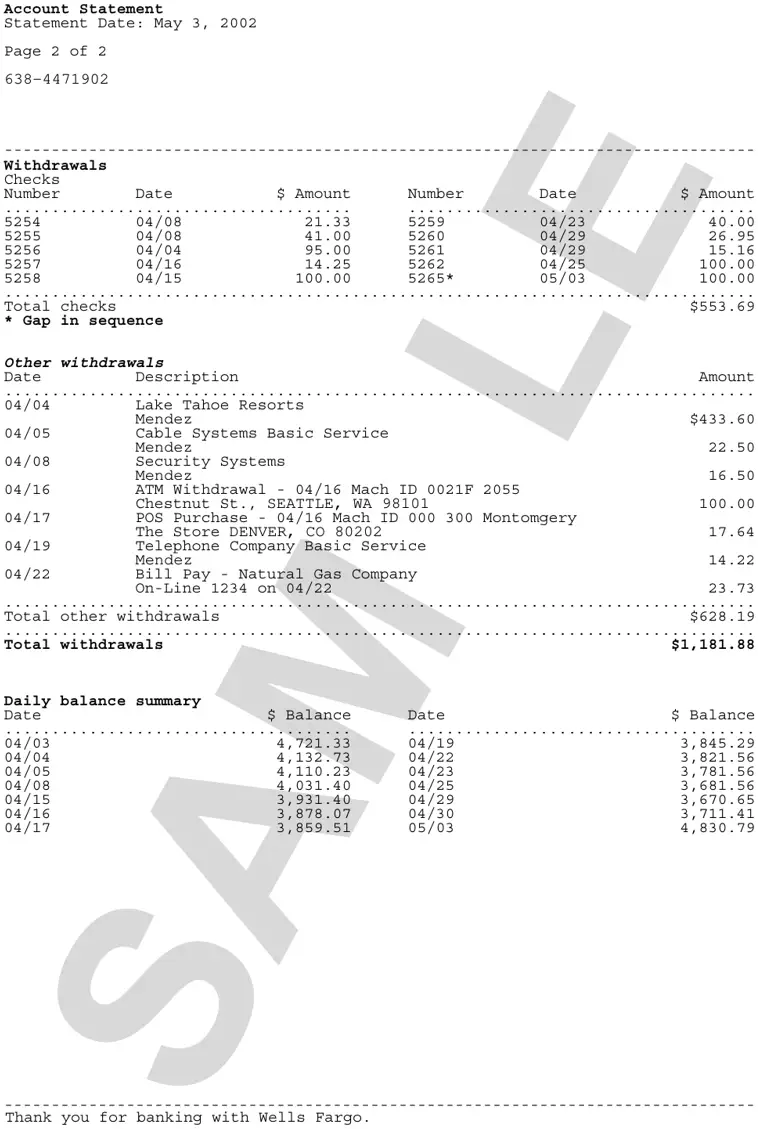
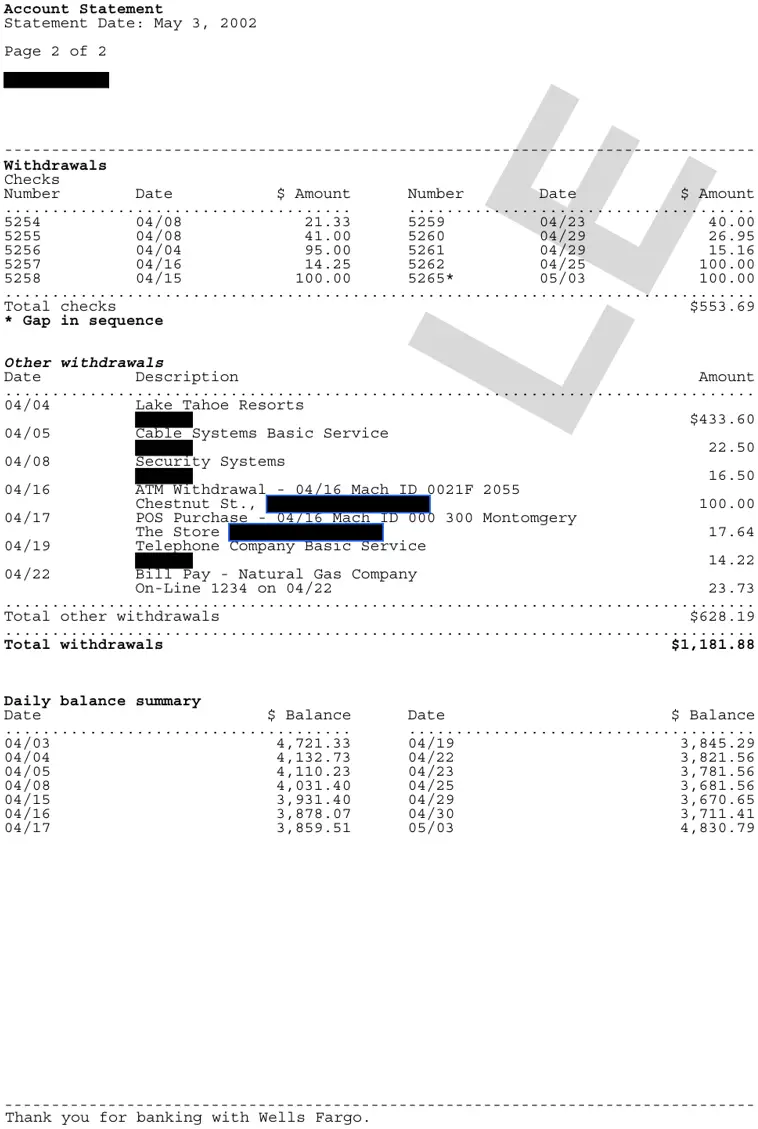
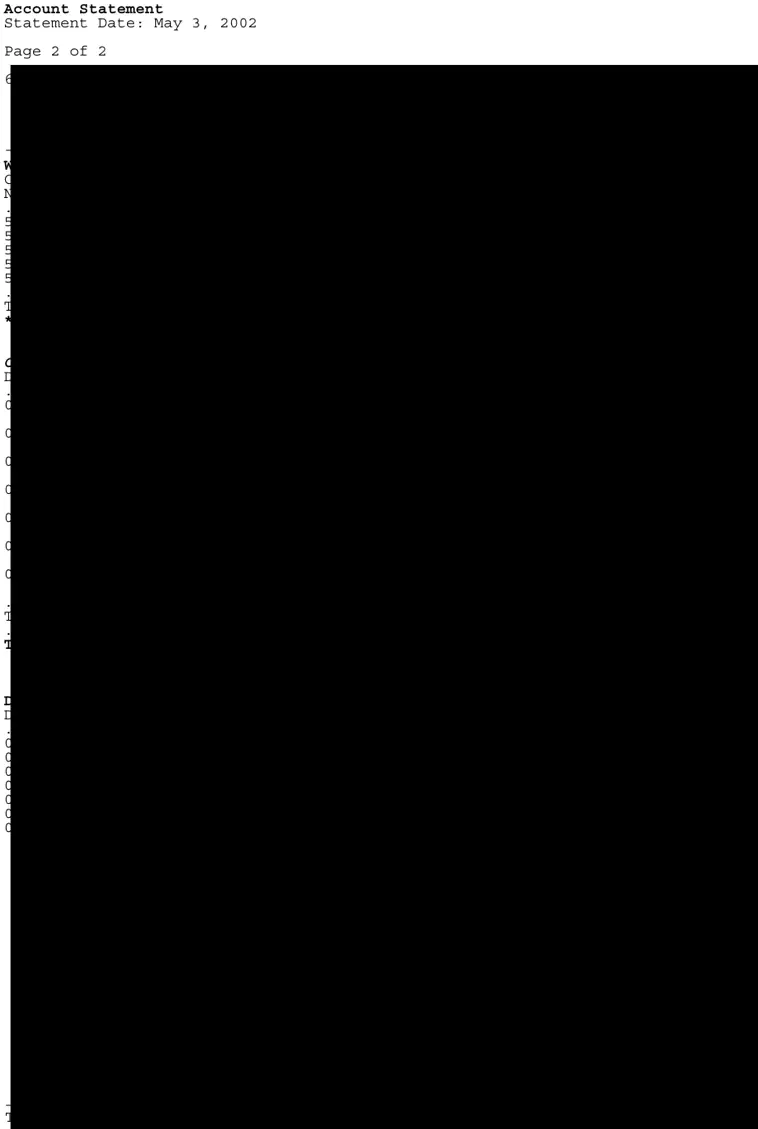
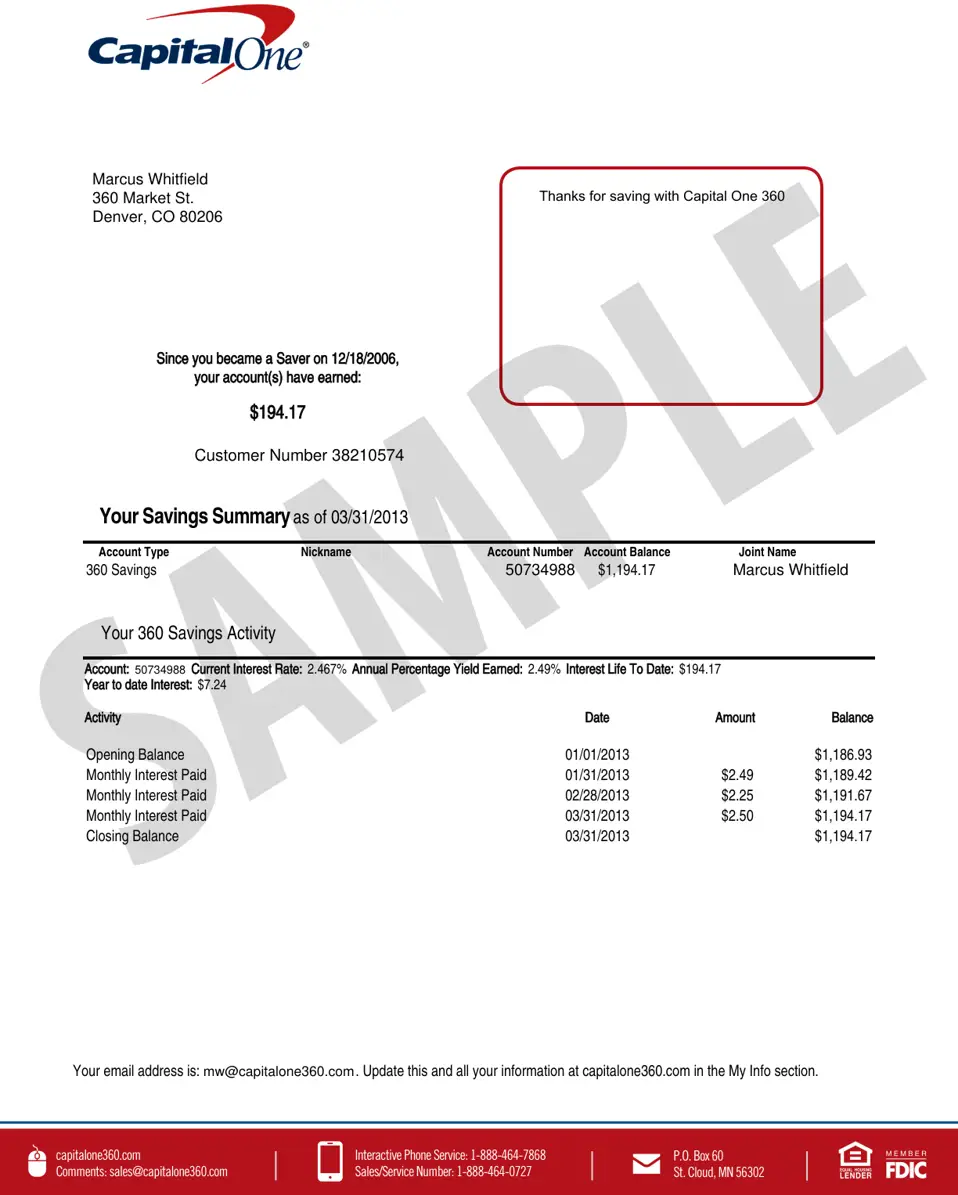
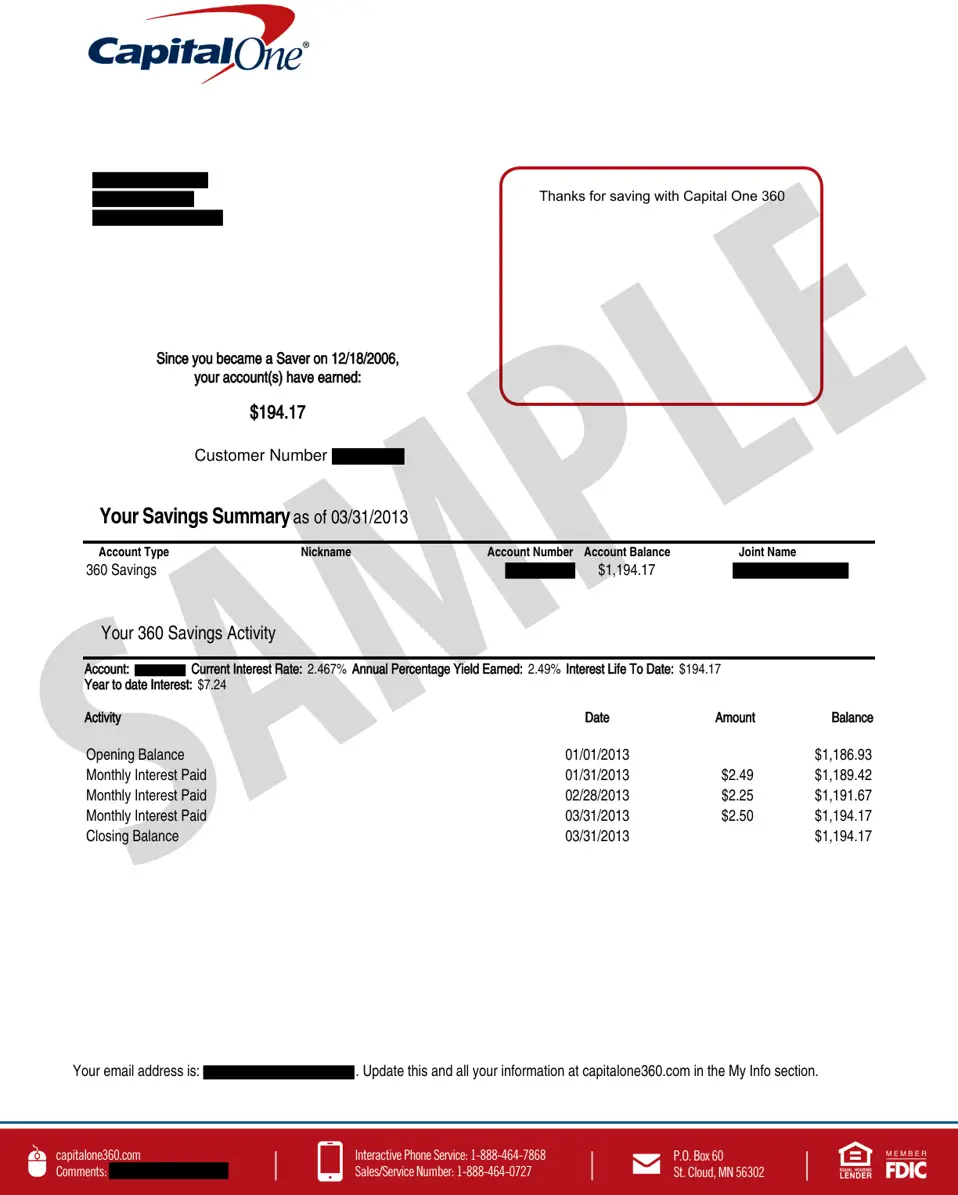
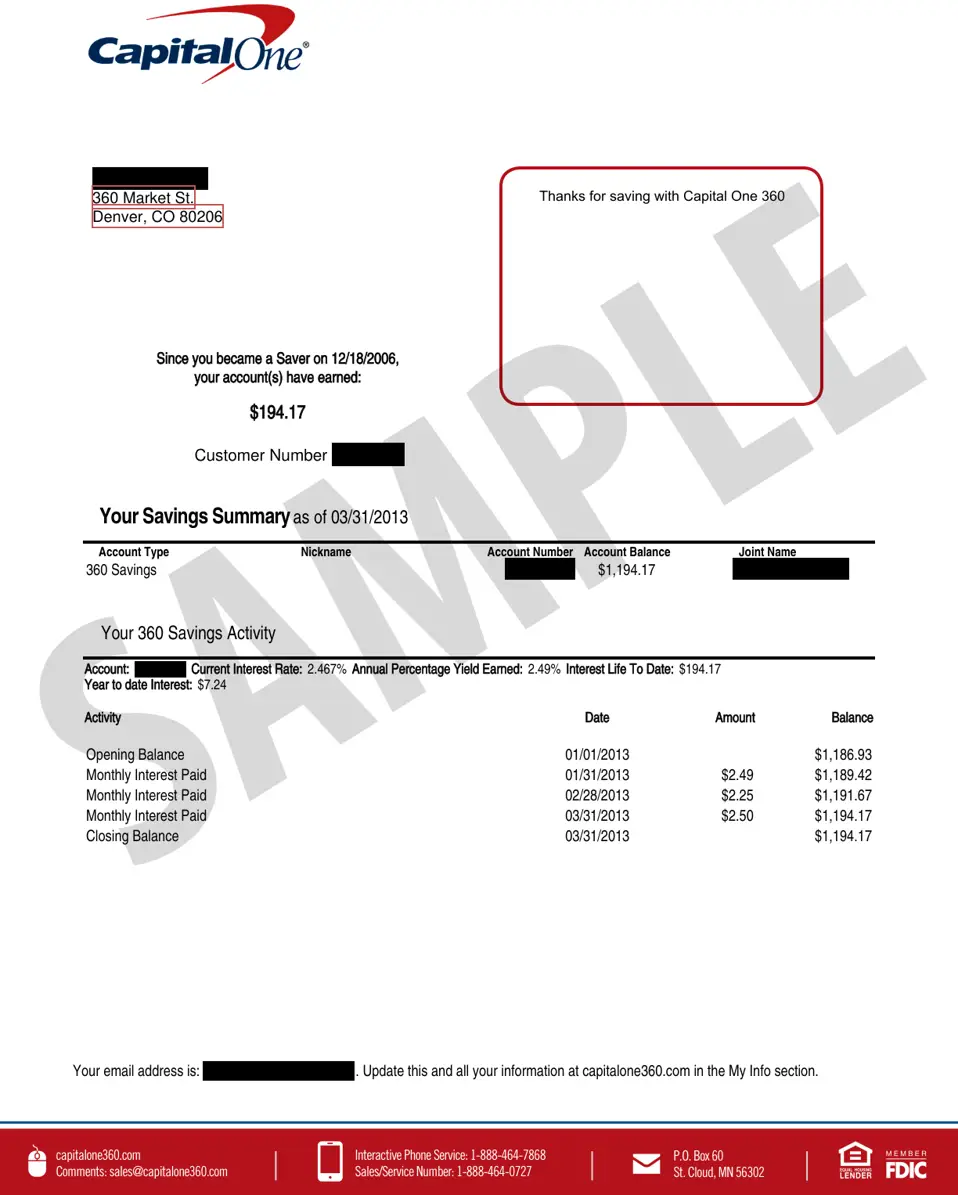
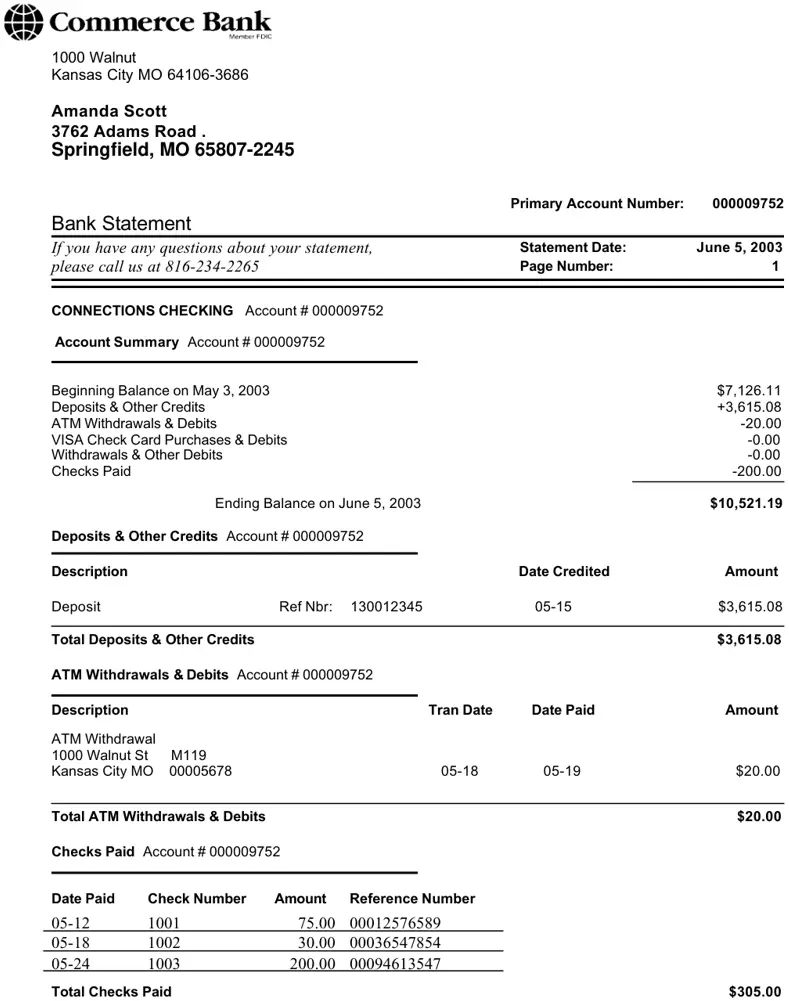
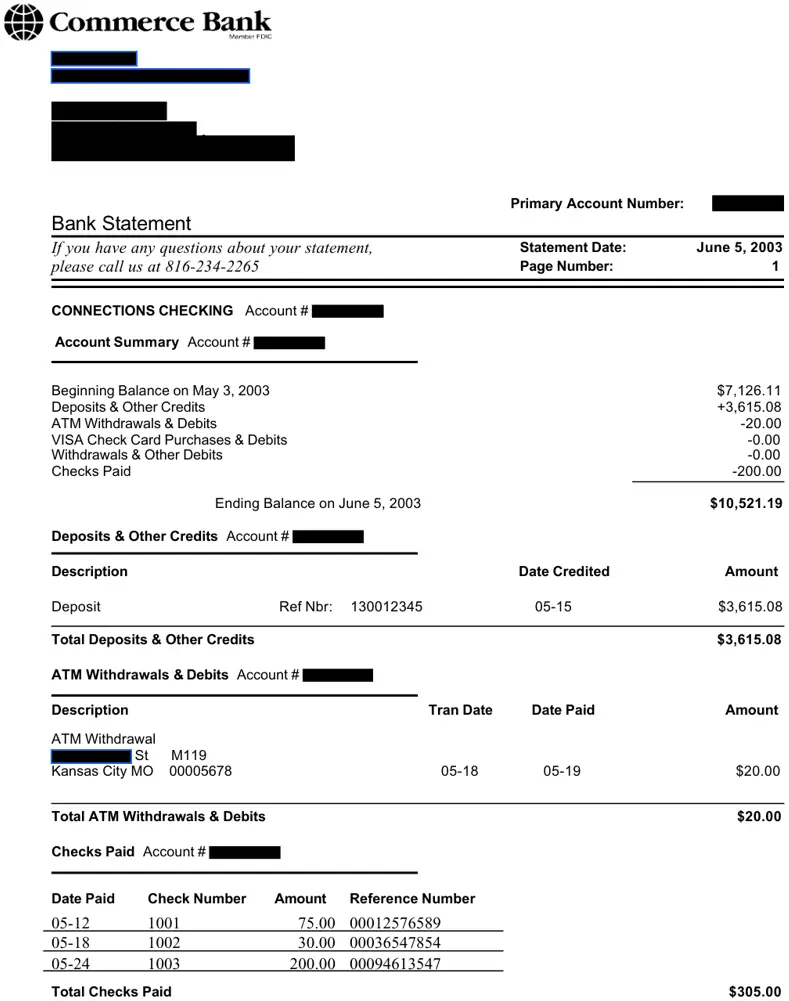
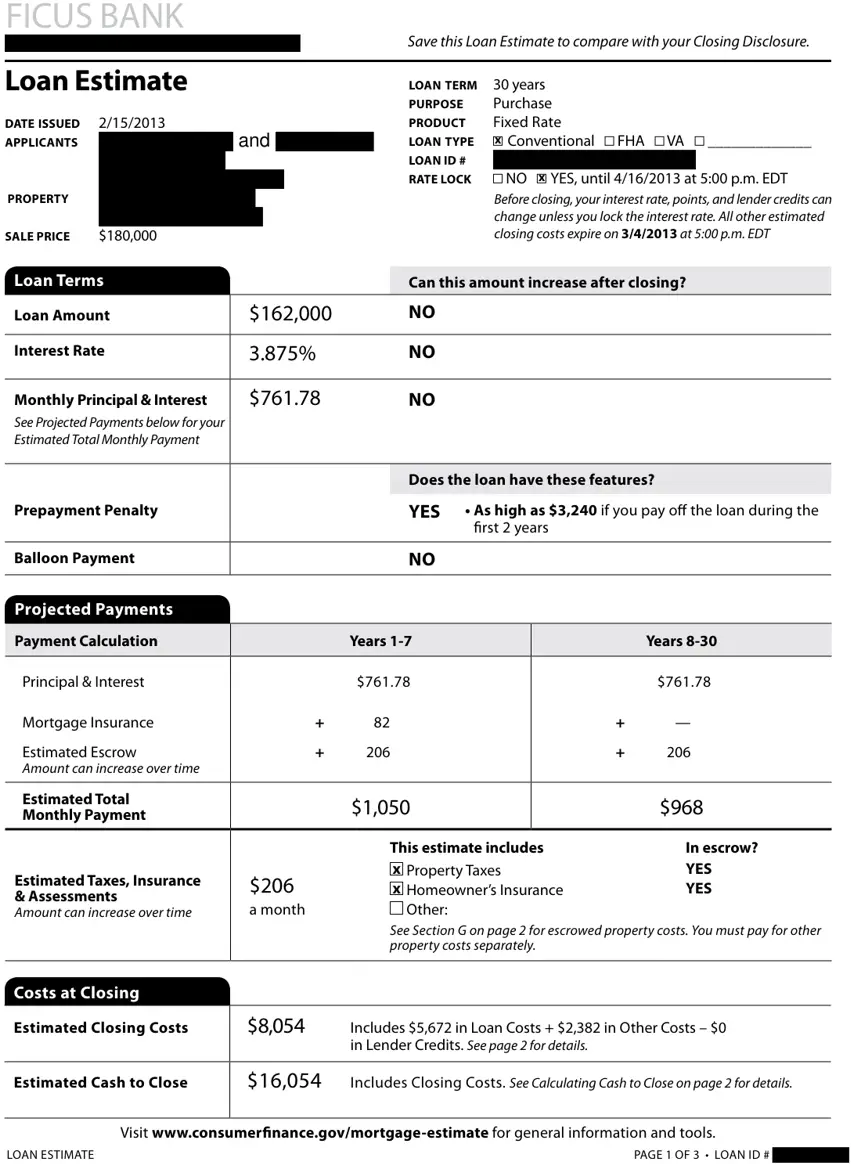
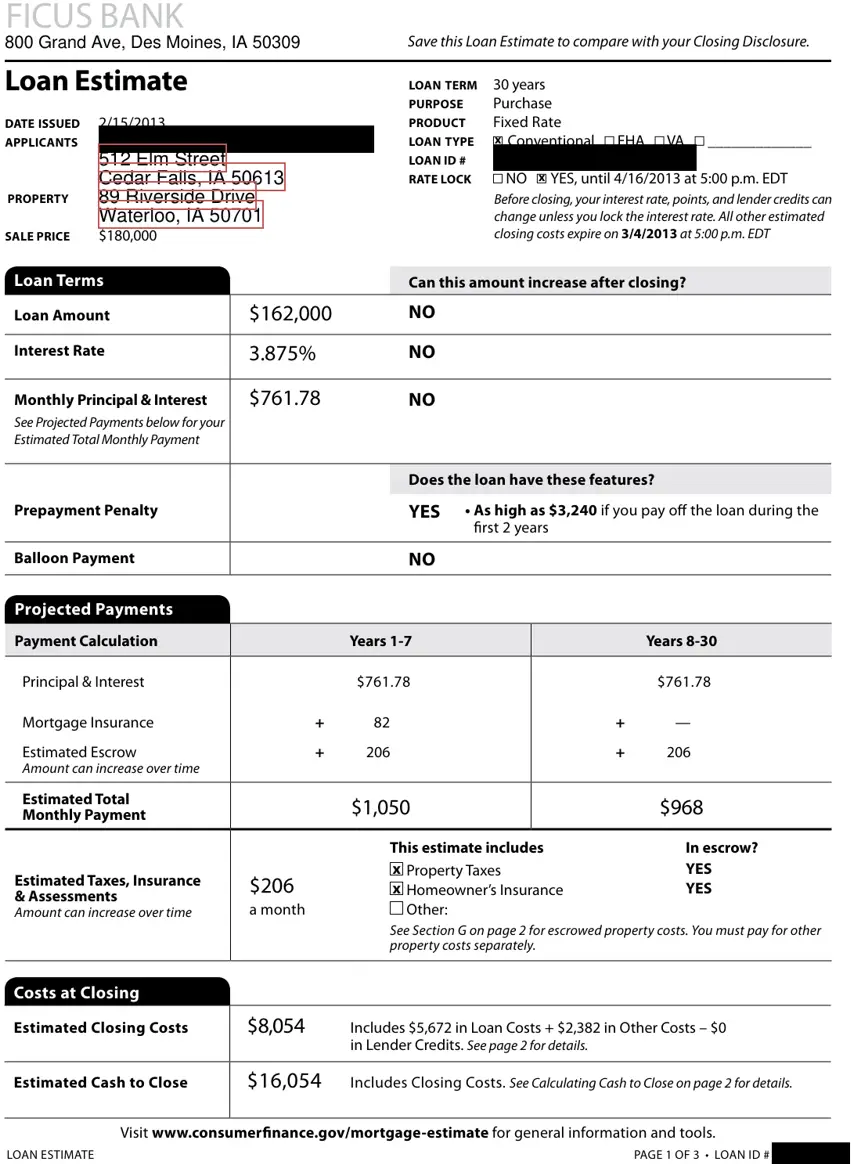
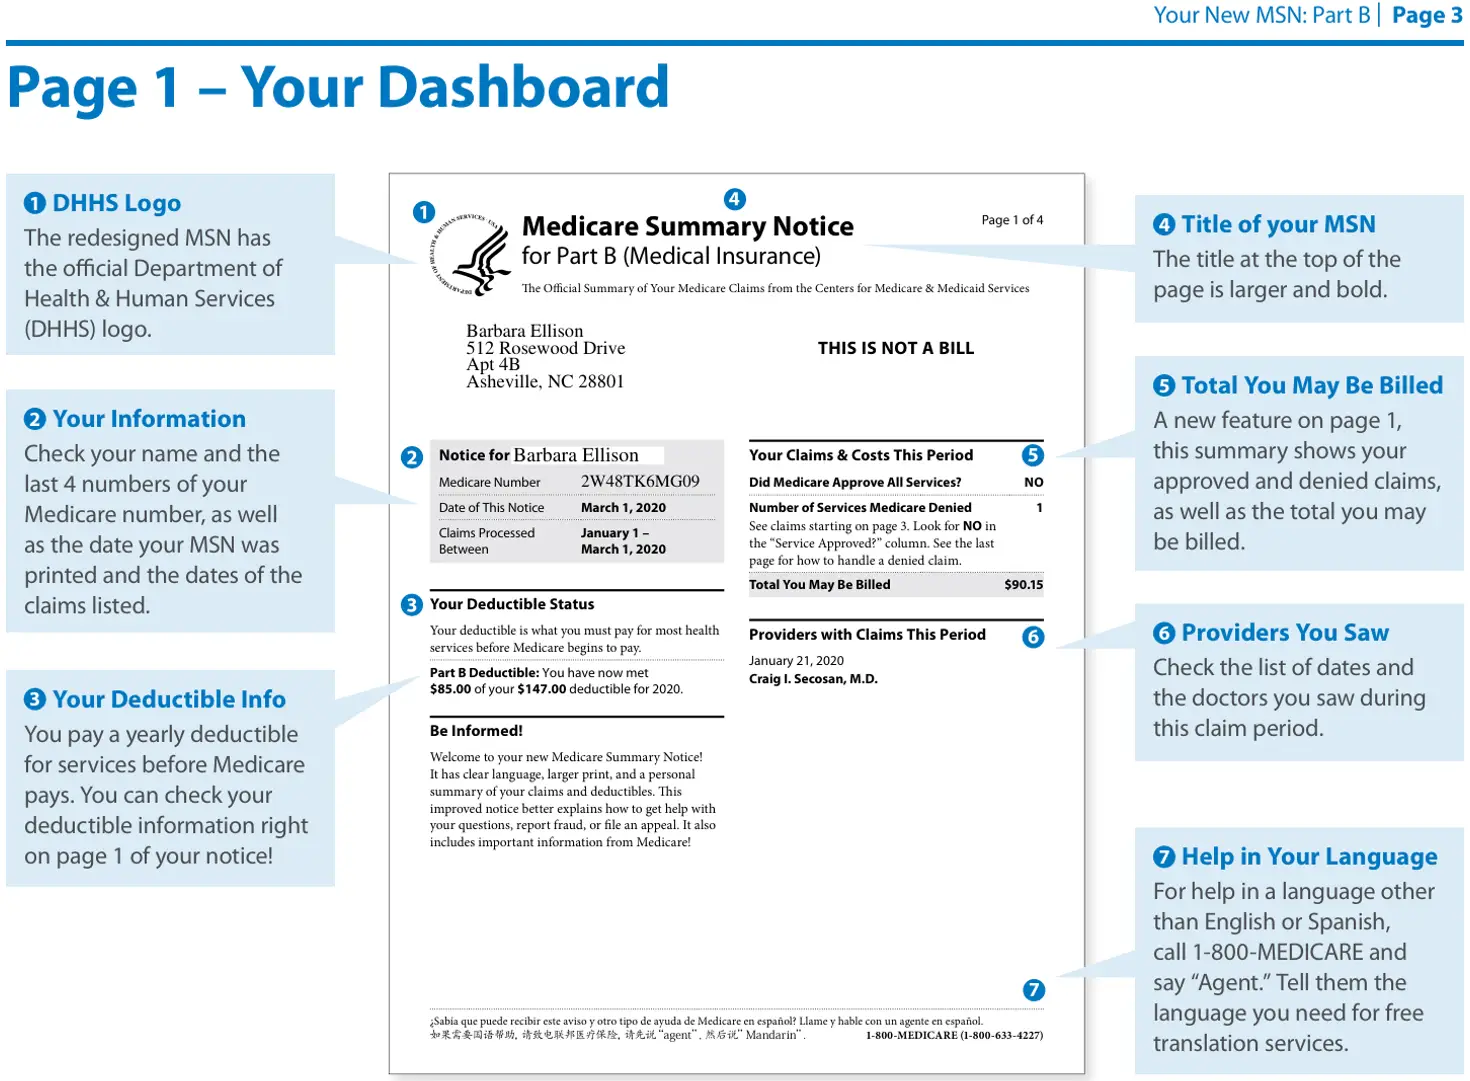
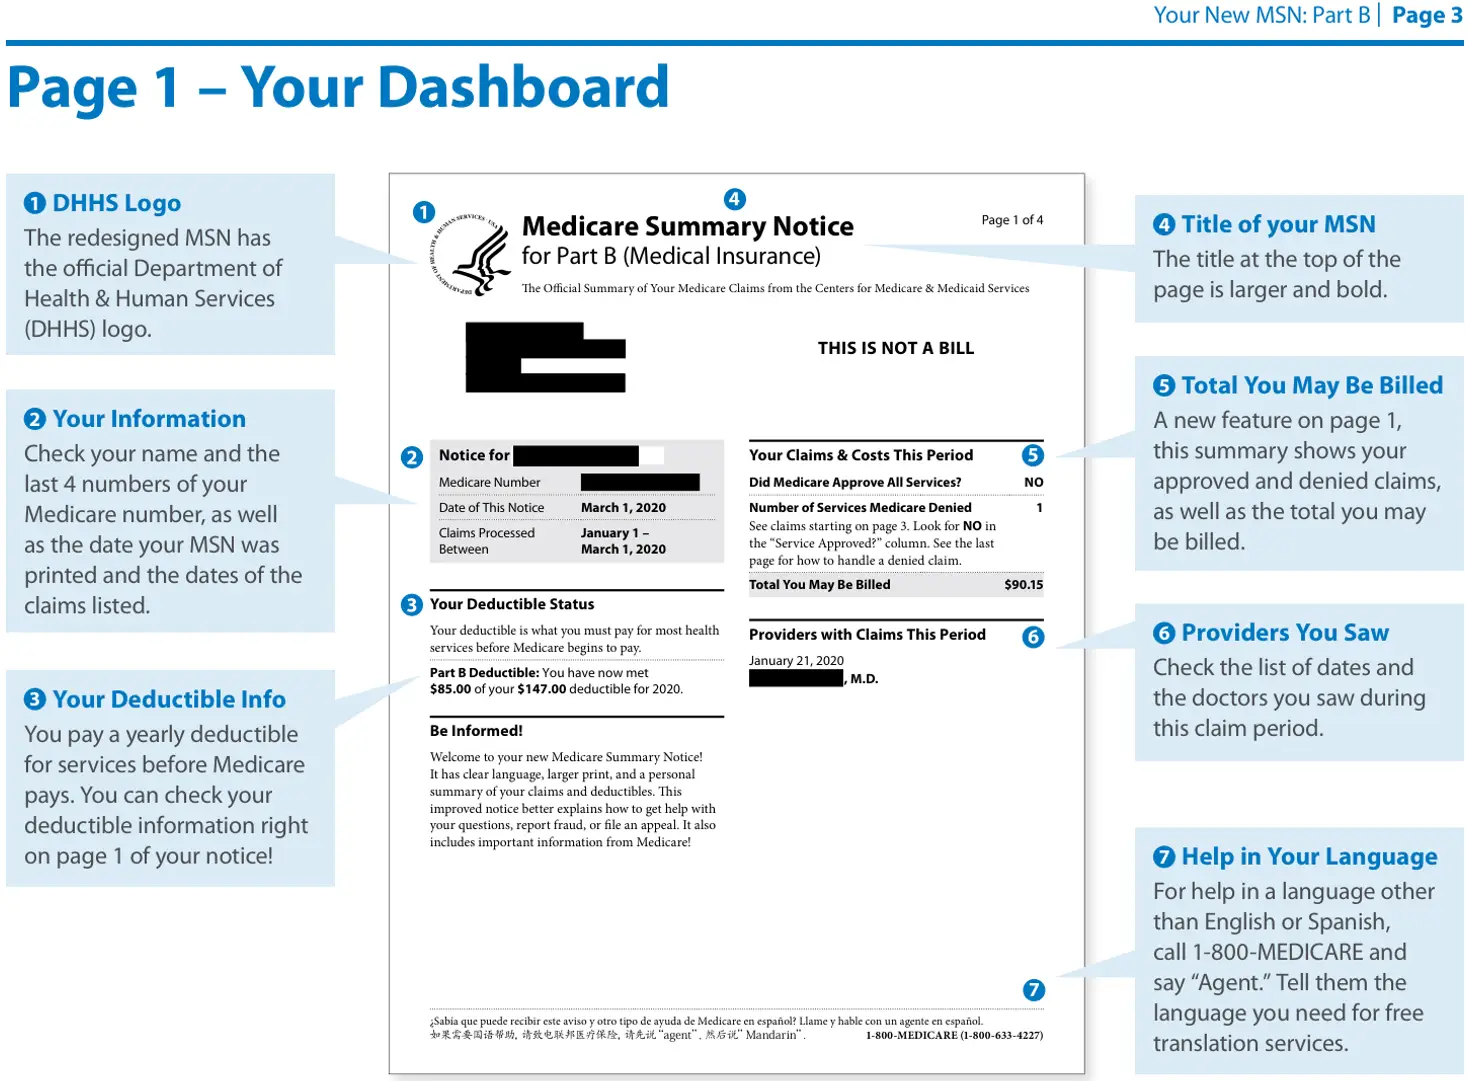
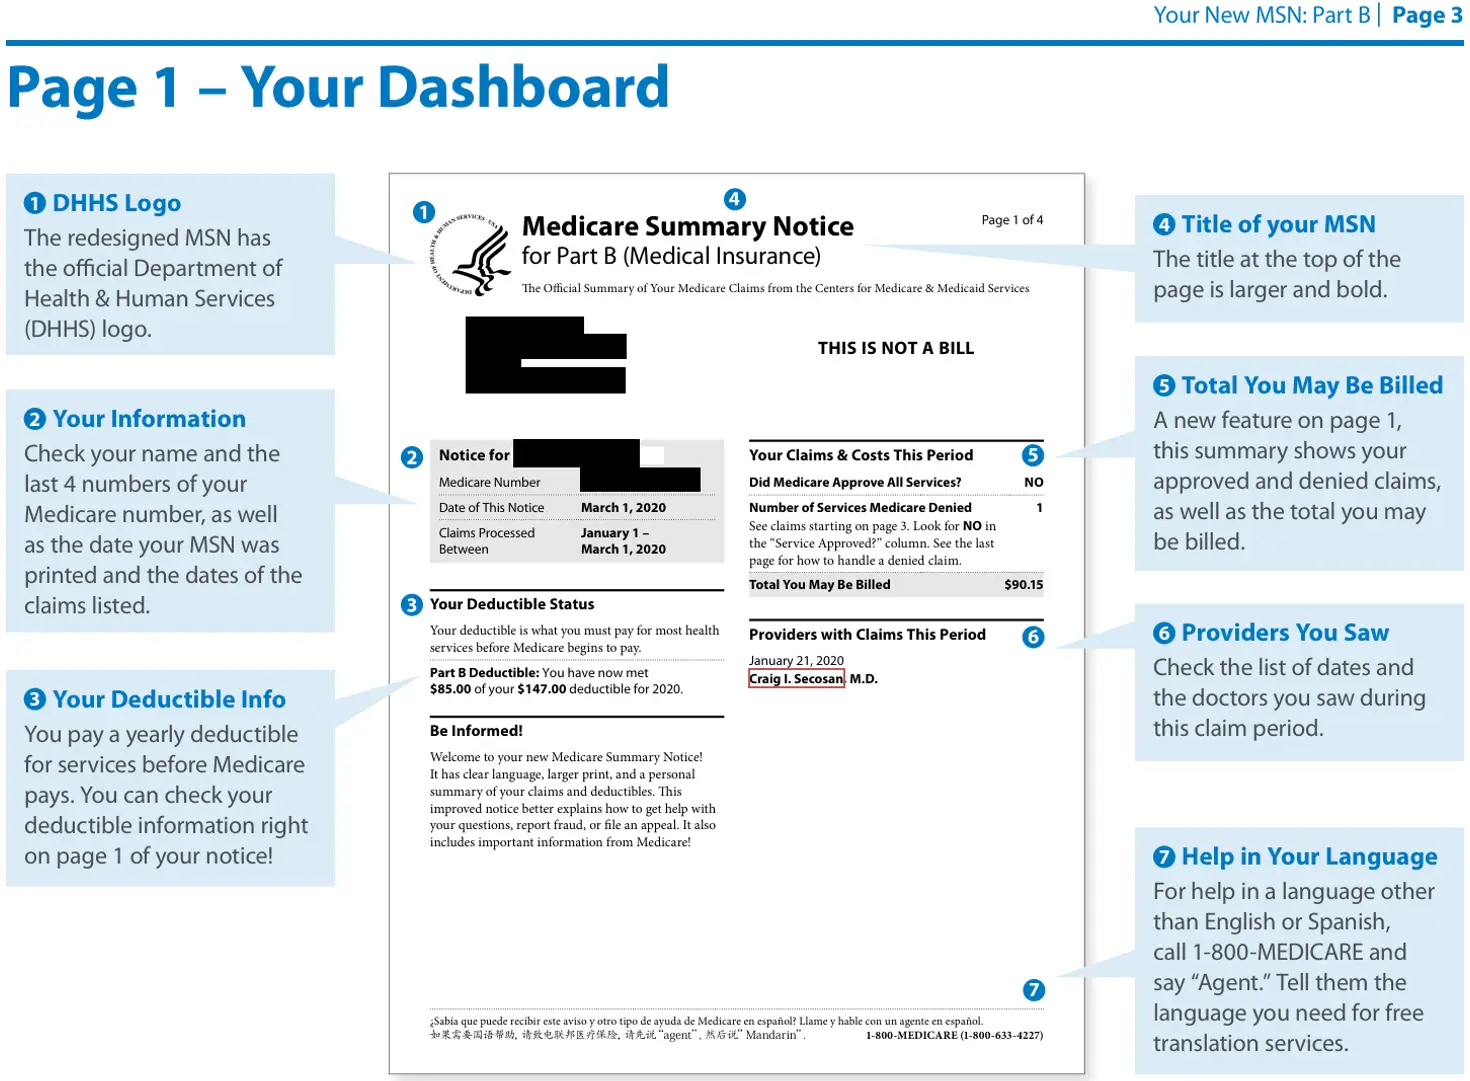
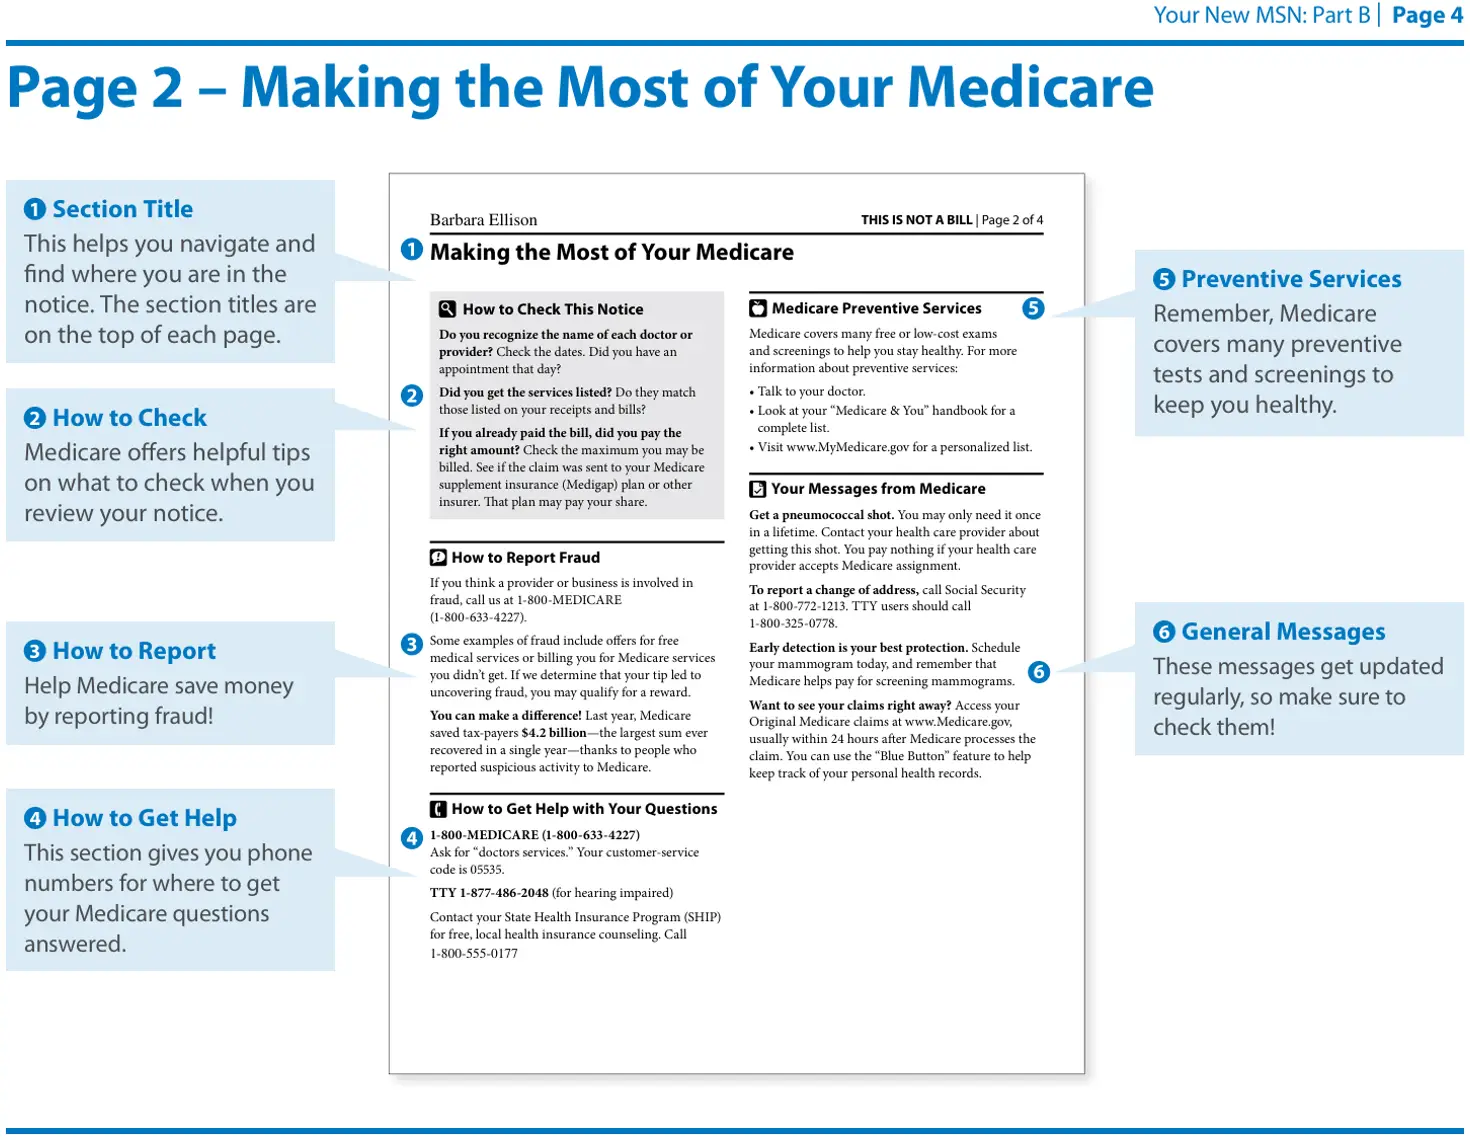
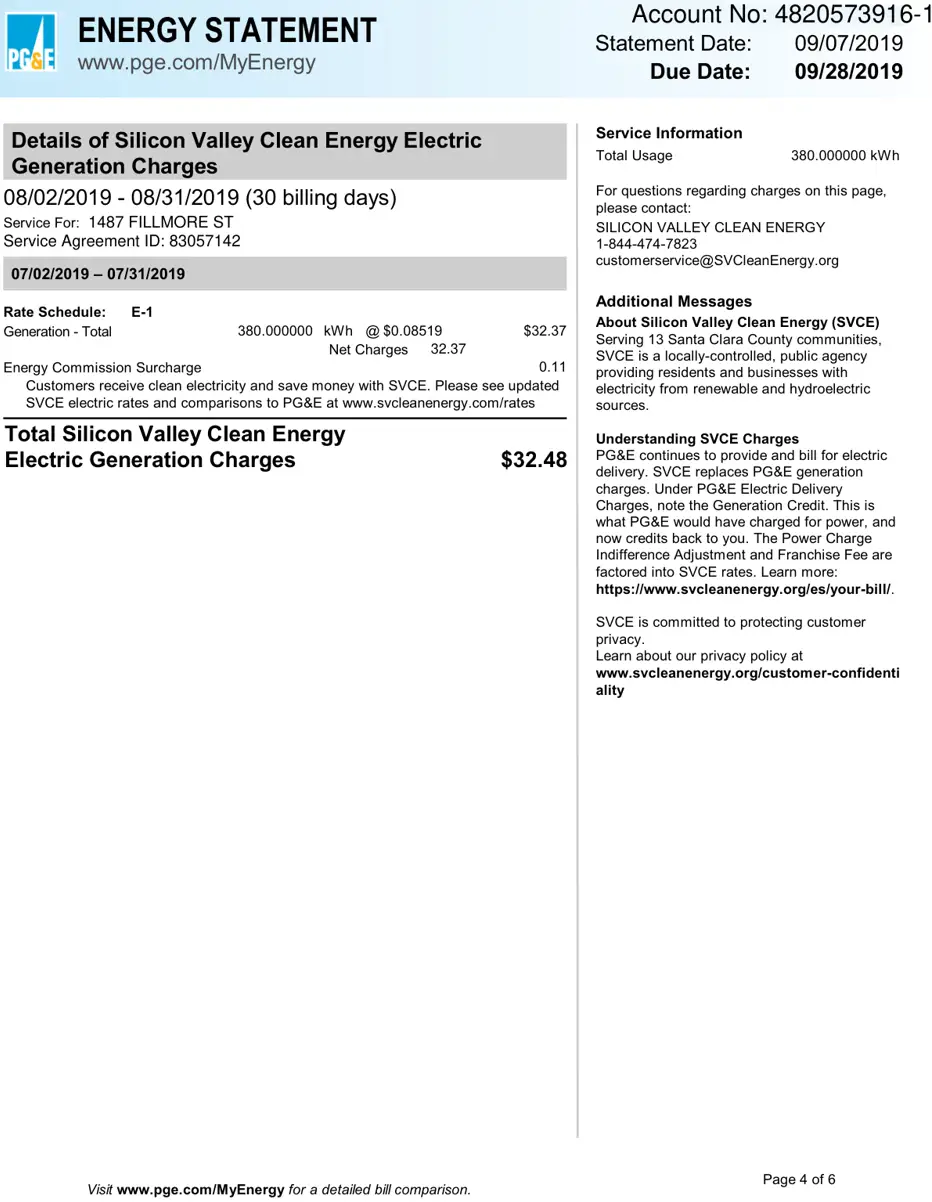
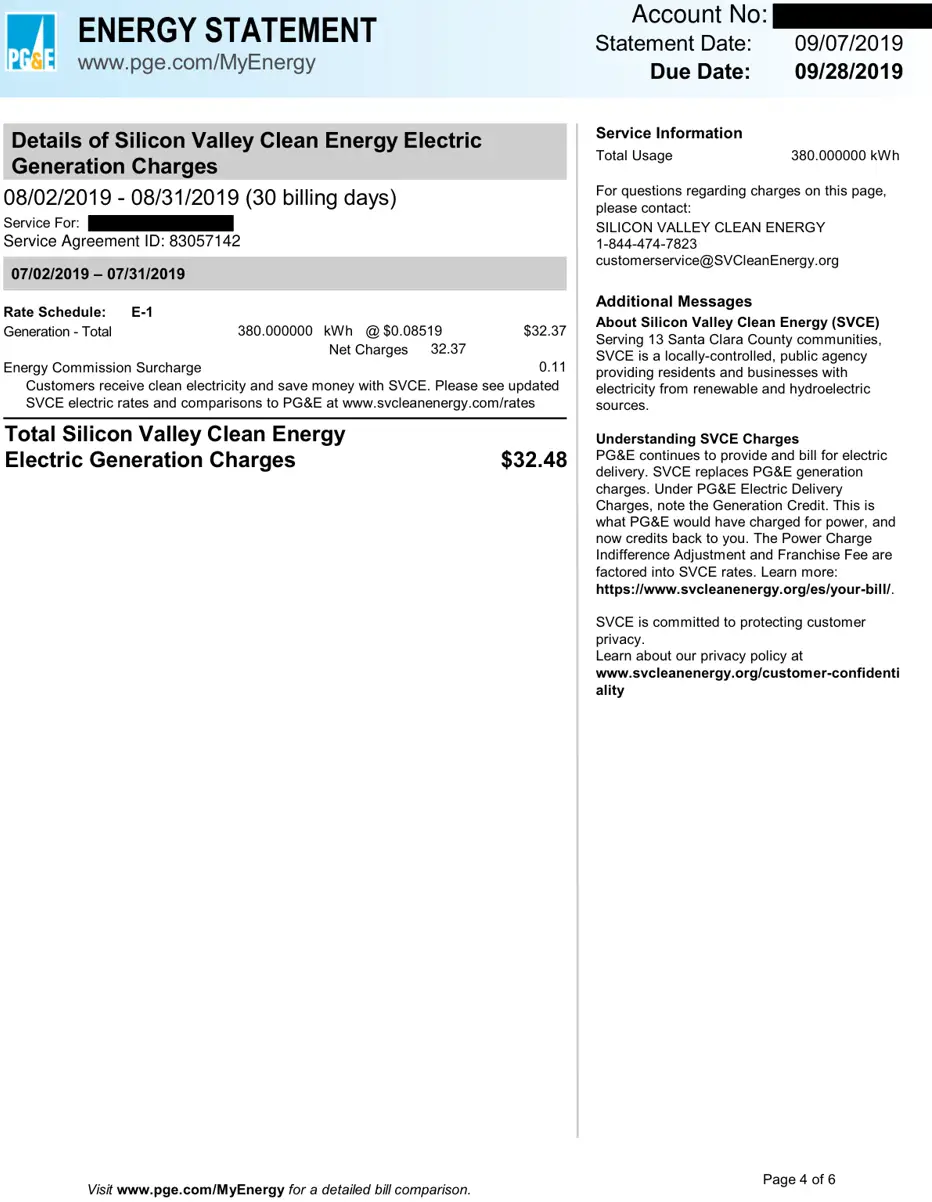
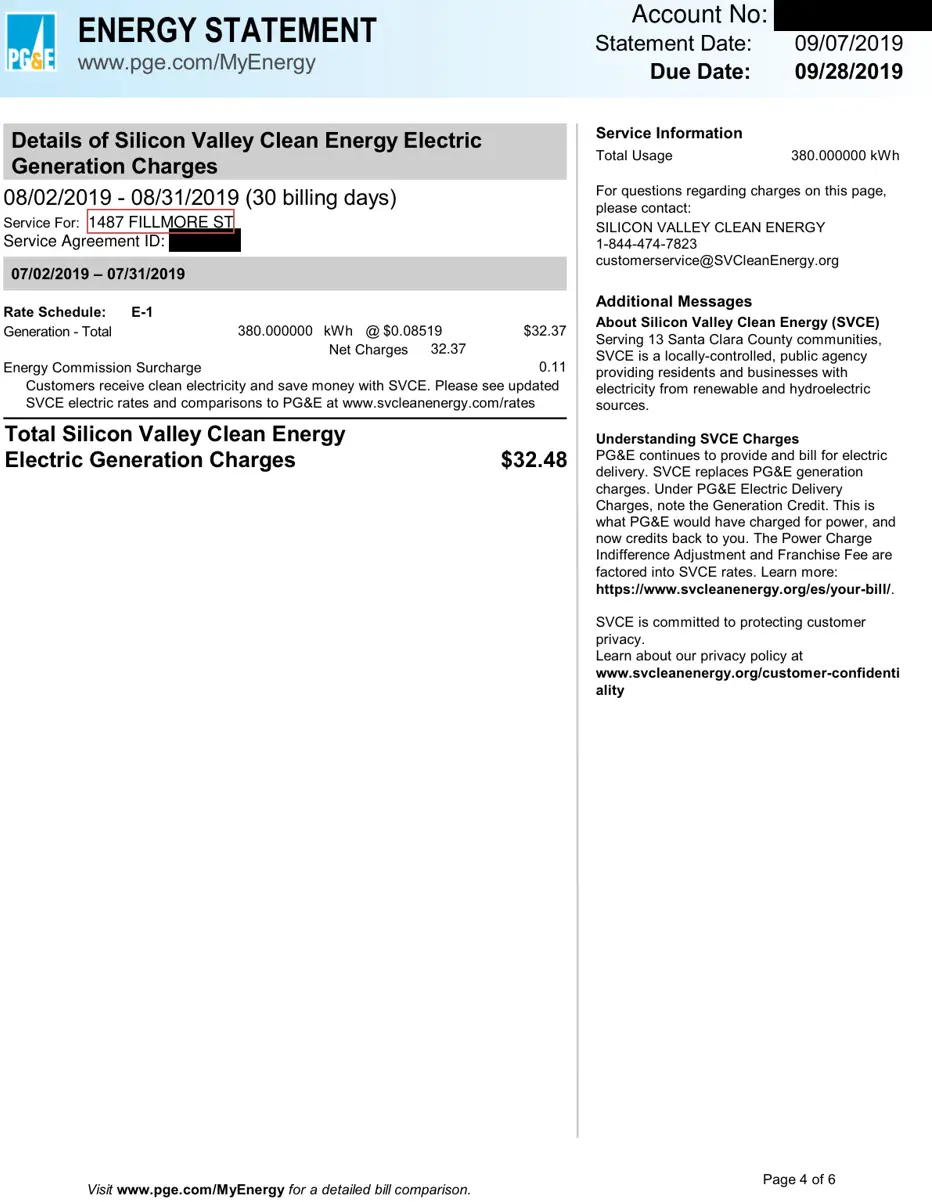
Check out the actual pages below and how each engine redacted them, side by side with the original.
A reasoning model that spends most of its time thinking: about four and a half minutes per PDF, the slowest here, and it still catches only 76% of the PII.A reasoning model that spends most of its time thinking rather than detecting. It is the slowest engine in the field at about four and a half minutes per PDF, just ahead of DeepSeek, and the thinking does not buy much: it catches 76% of the PII to Cover's 100%, over-redacts about thirteen times more (188 against 14), and takes roughly ninety times longer per document.
- One-click edits fix any box instantly; no re-prompting (LLMs over-redact).
- Fully offline files never leave your device.
- Seconds per file no datacenter hardware to buy or maintain.
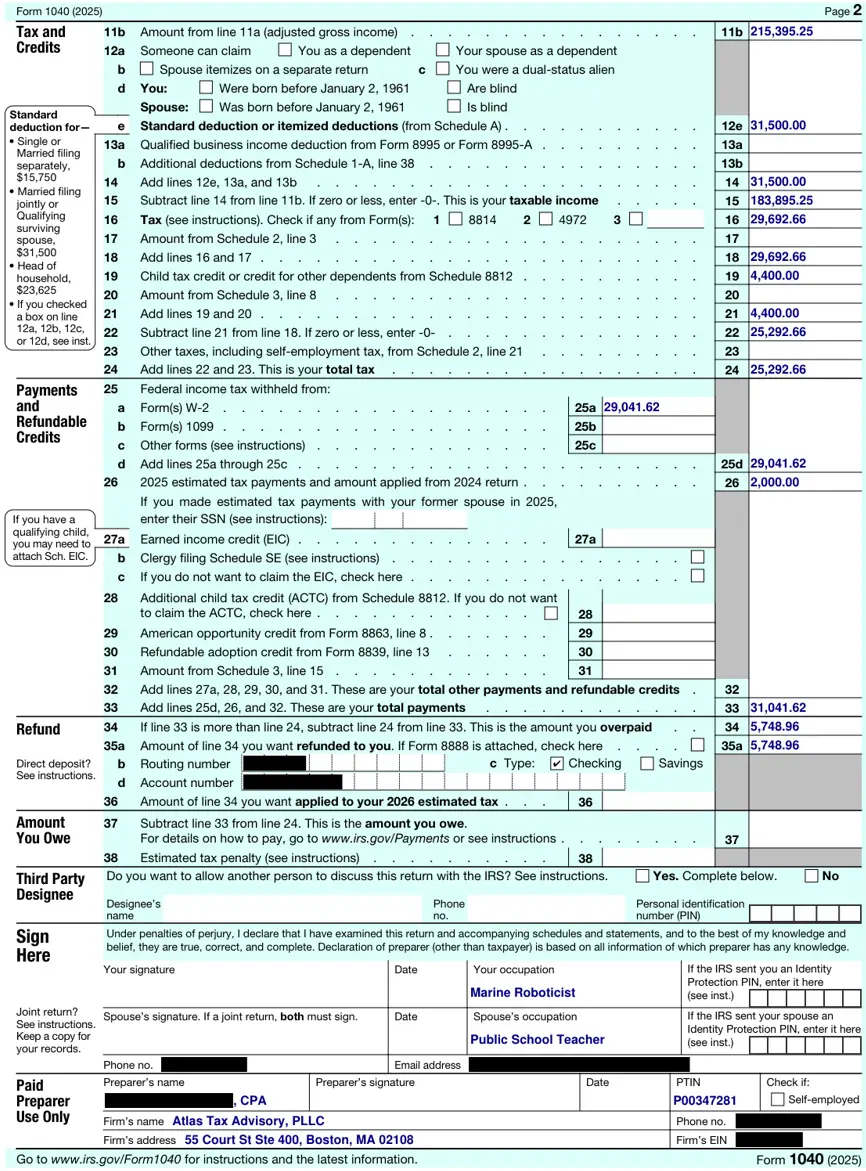
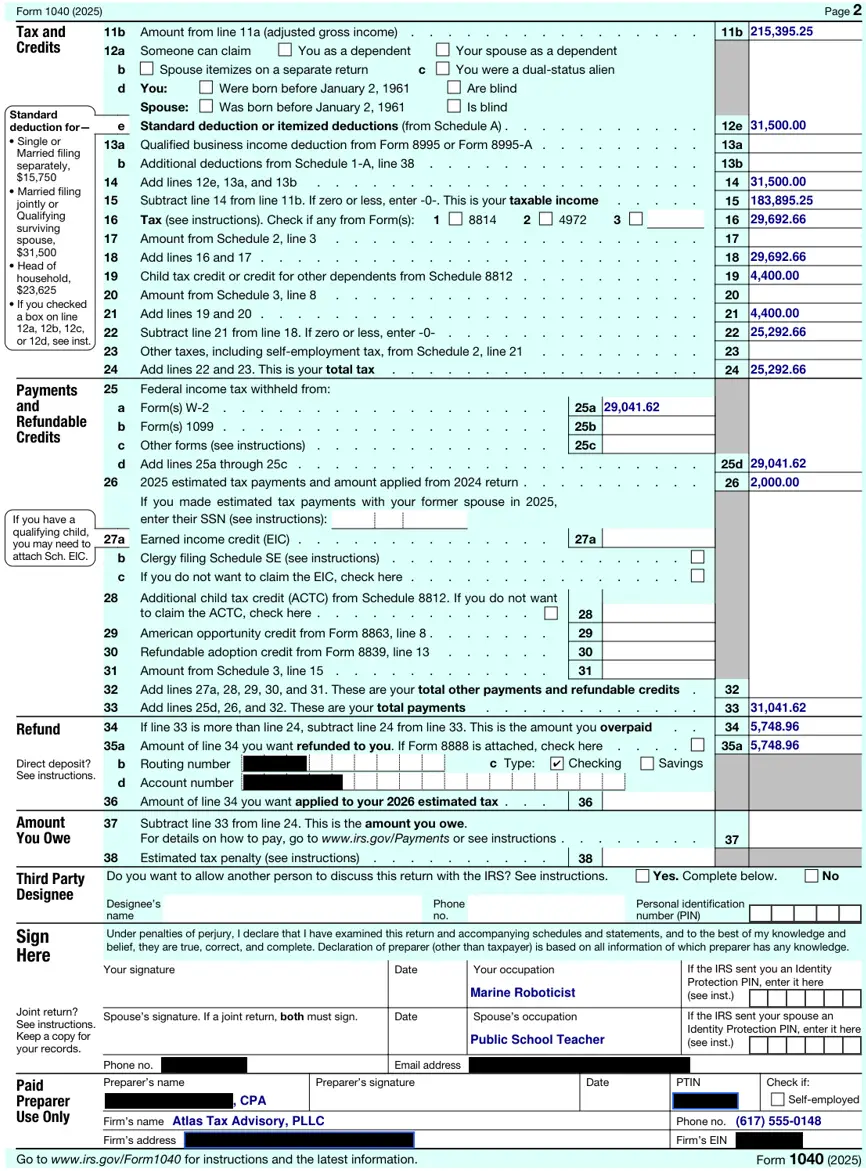
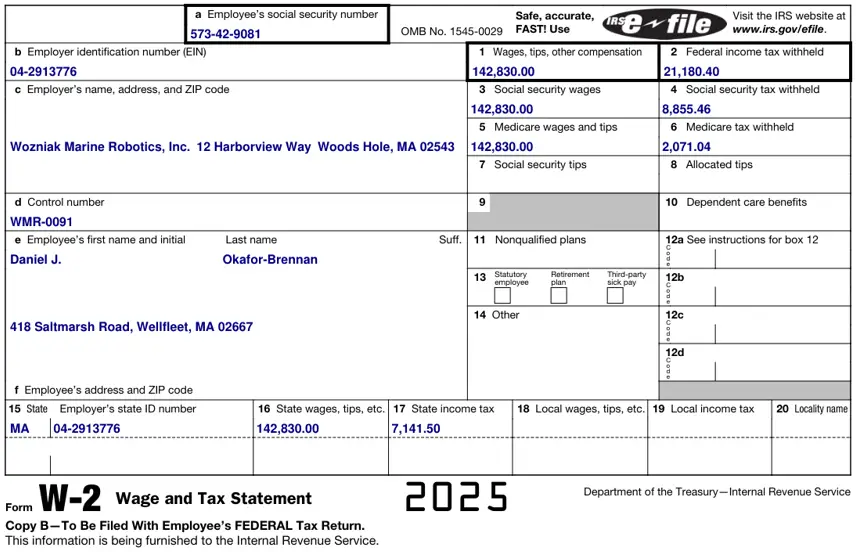
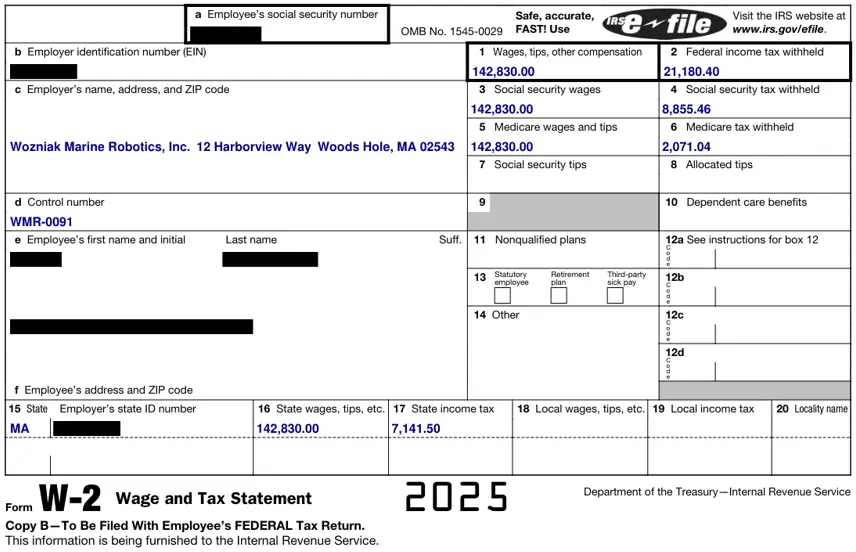
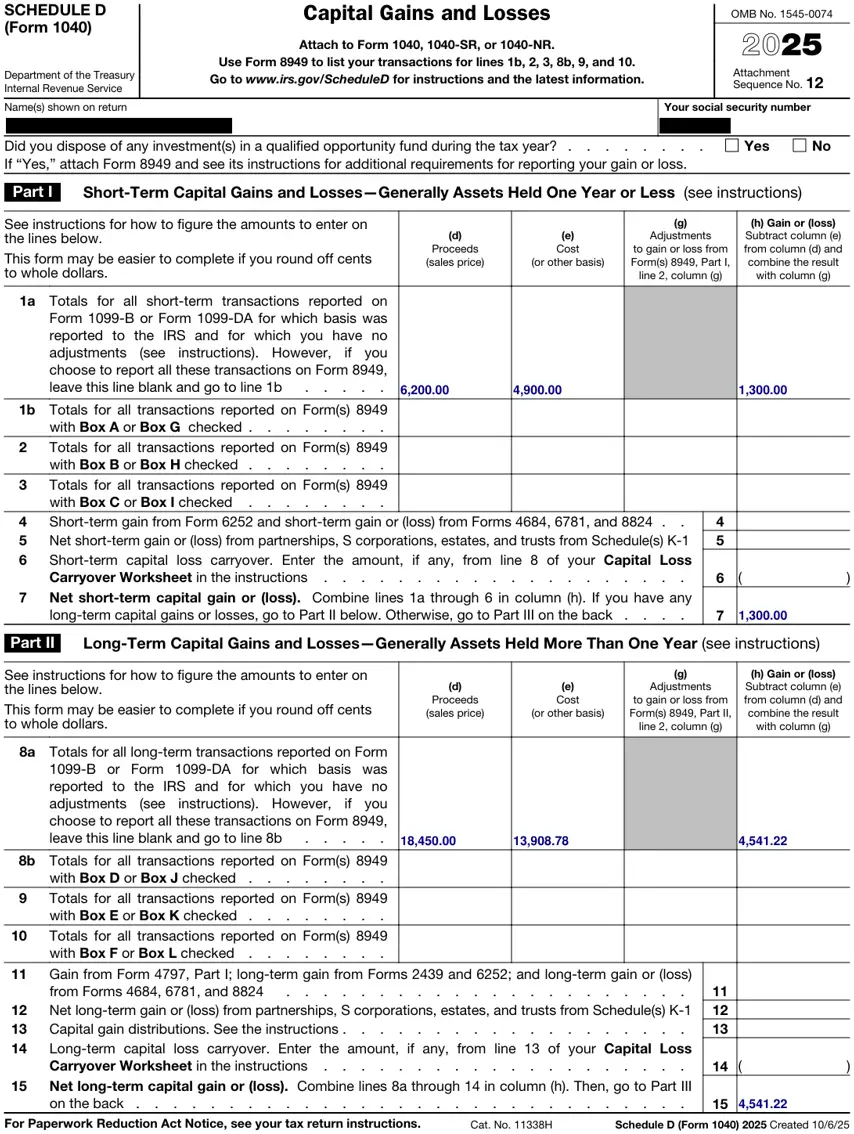
2025_Tax_Return_Okafor-Brennan.pdf
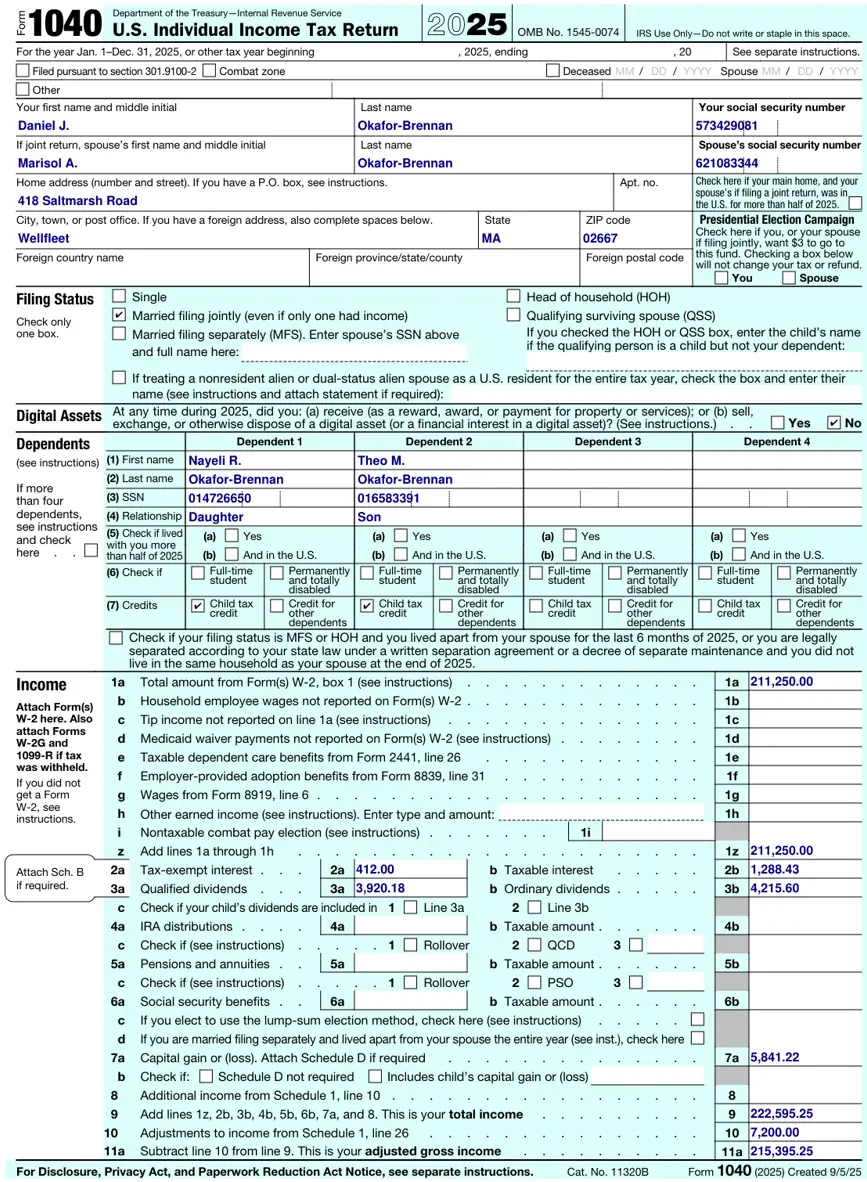
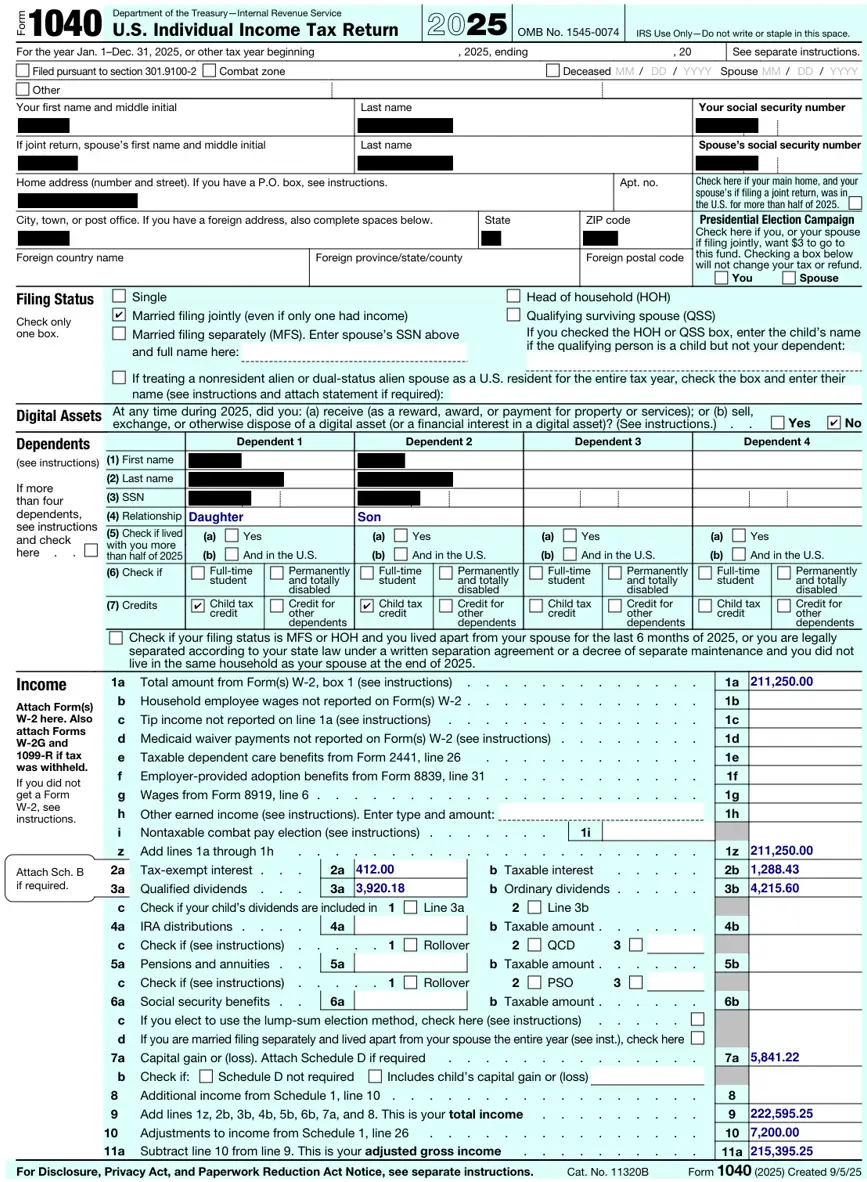
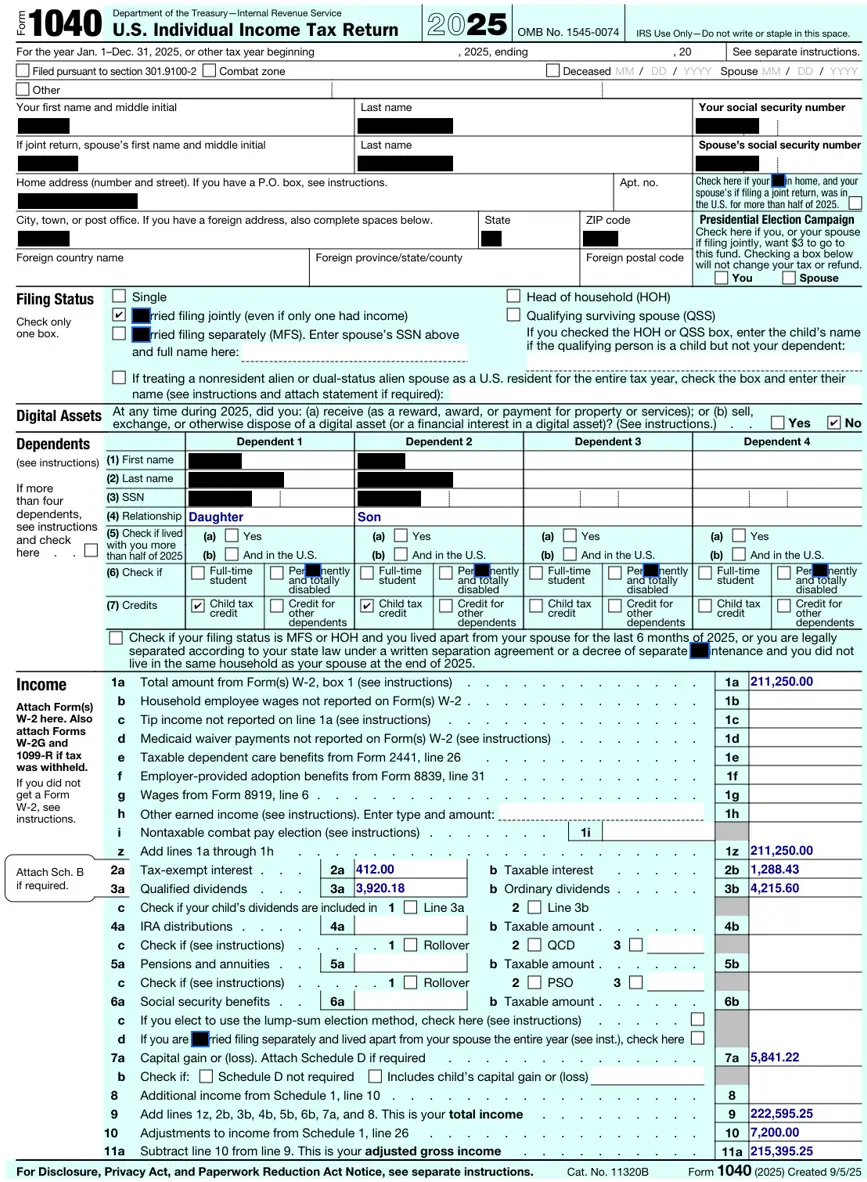
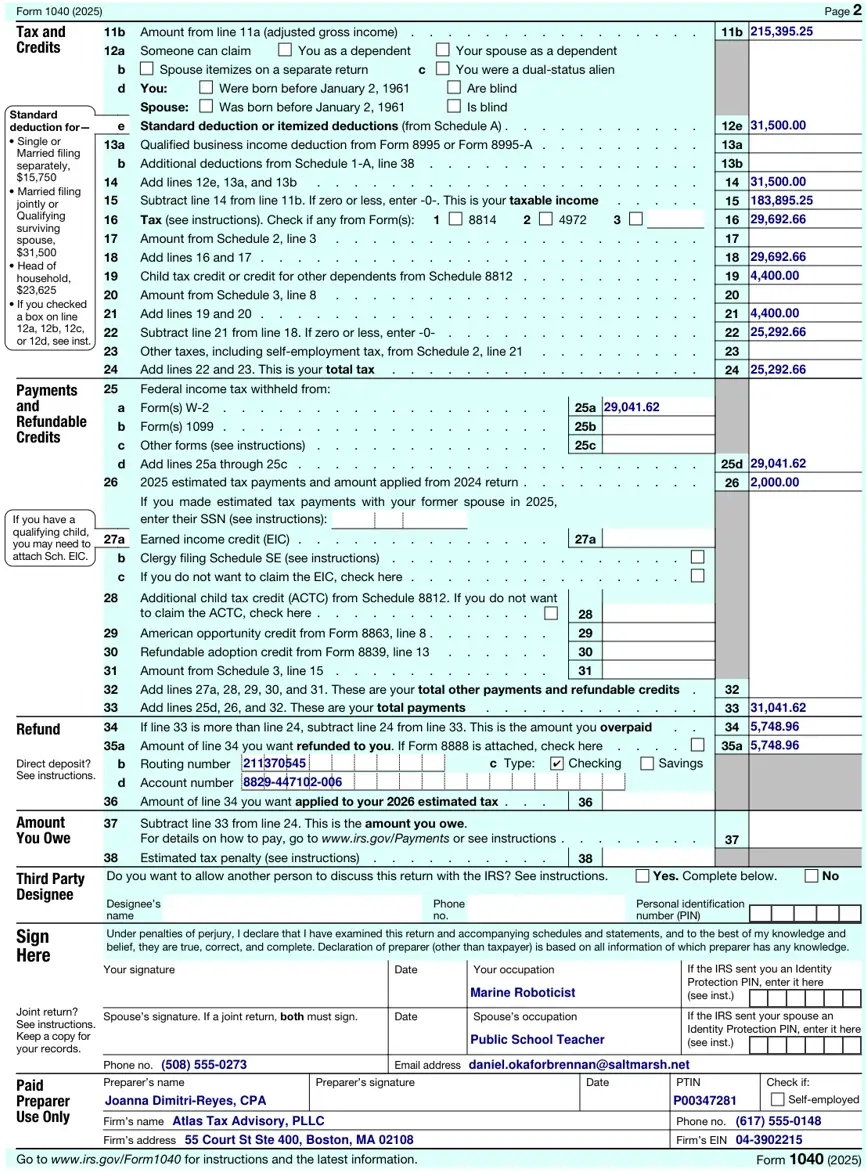
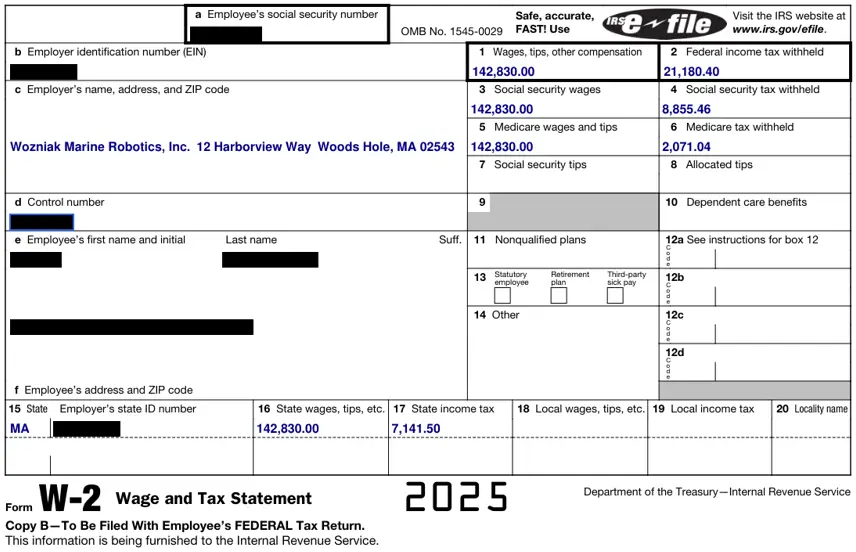
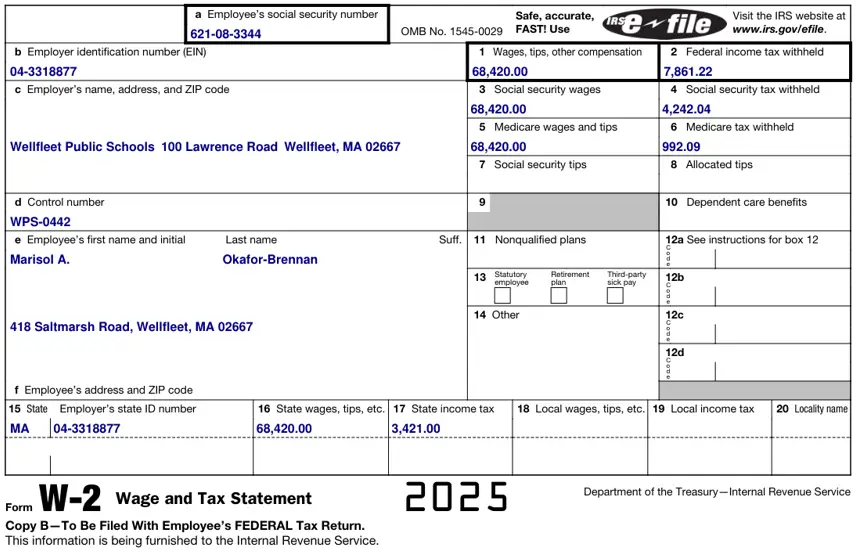
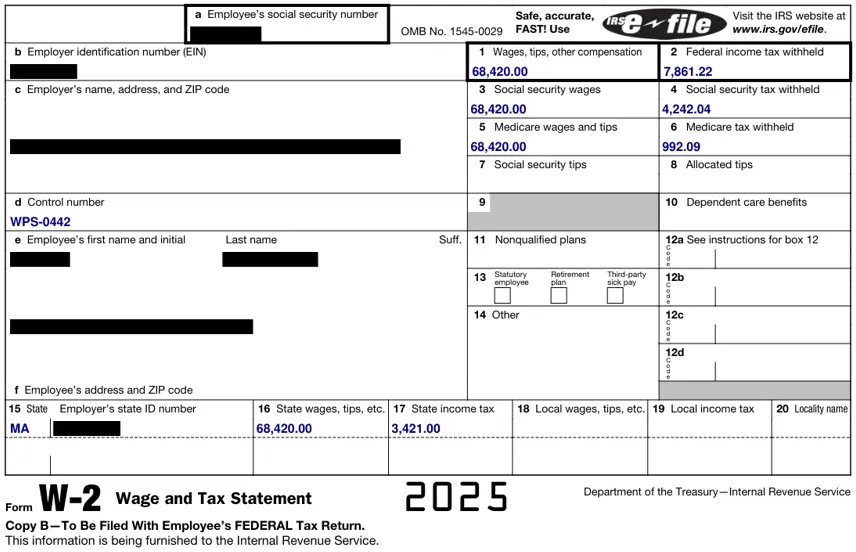
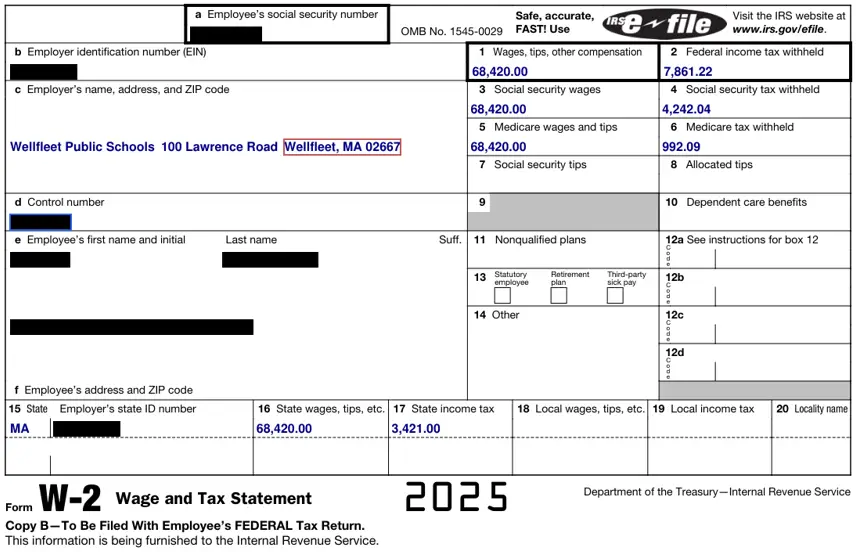
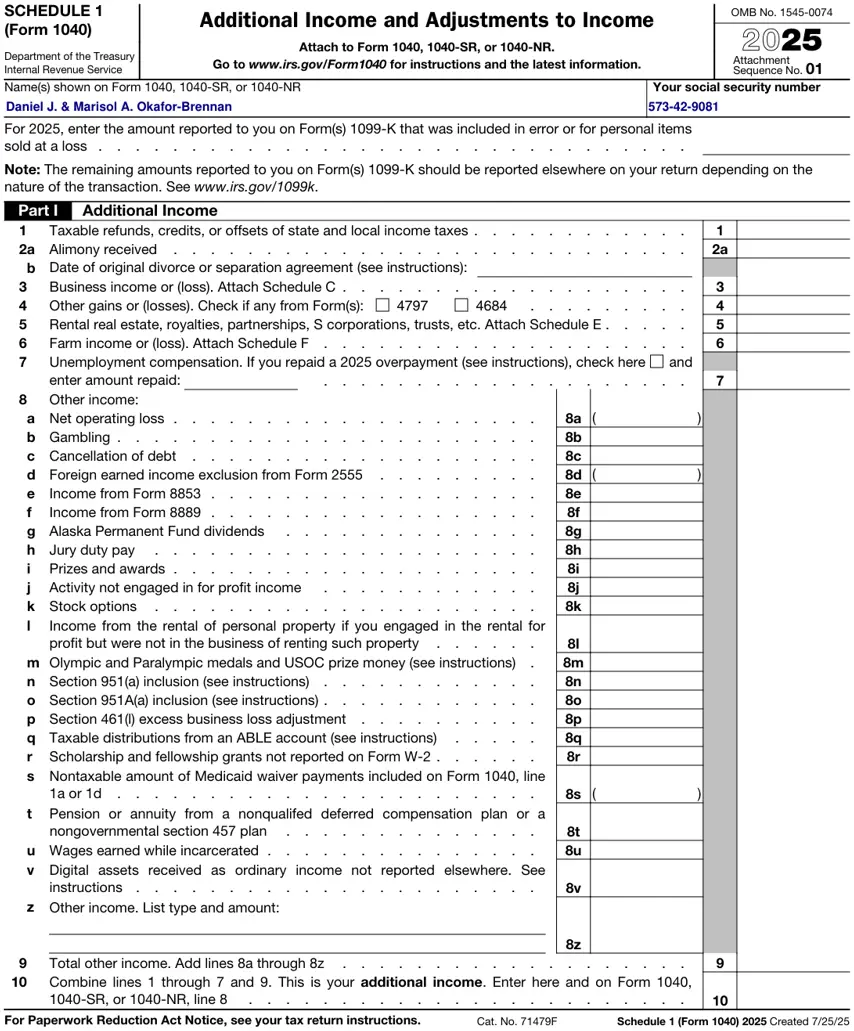
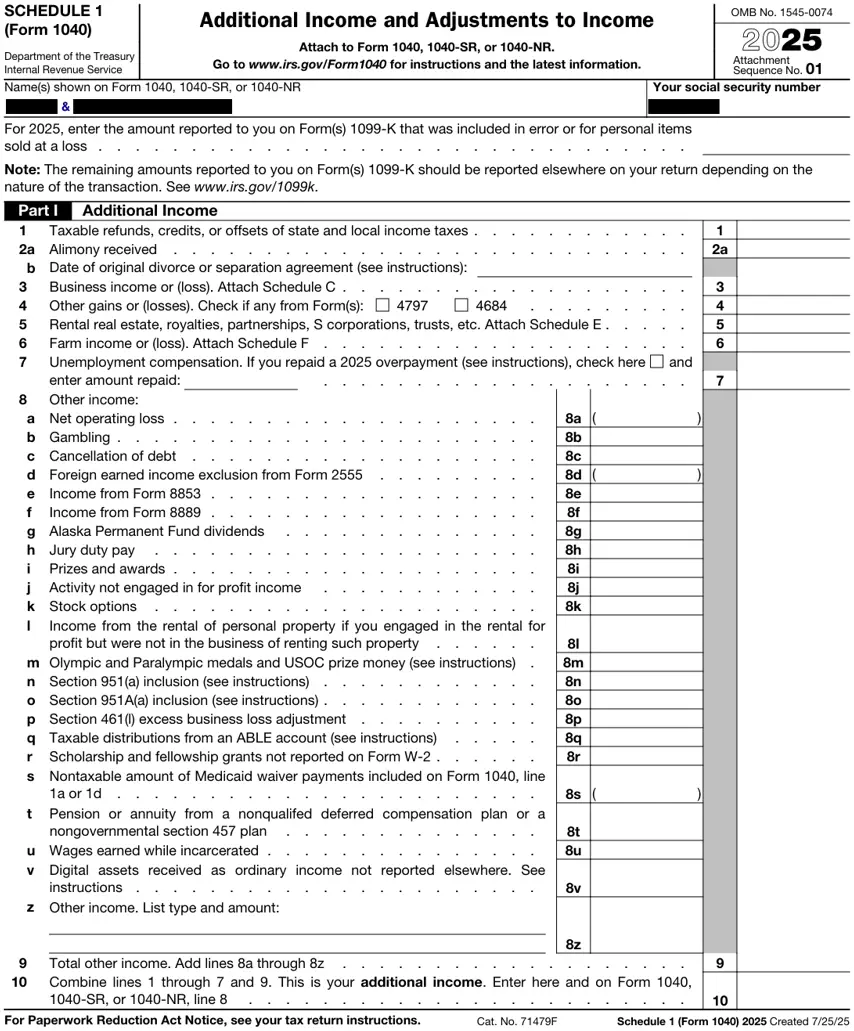
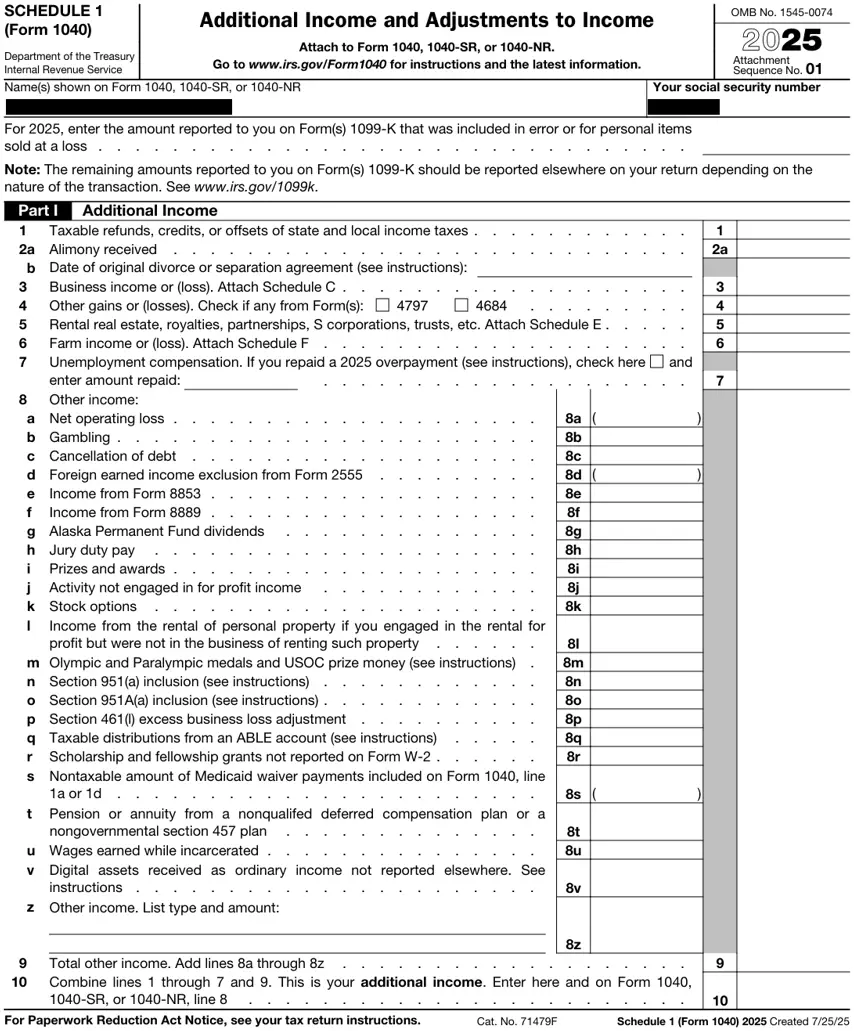
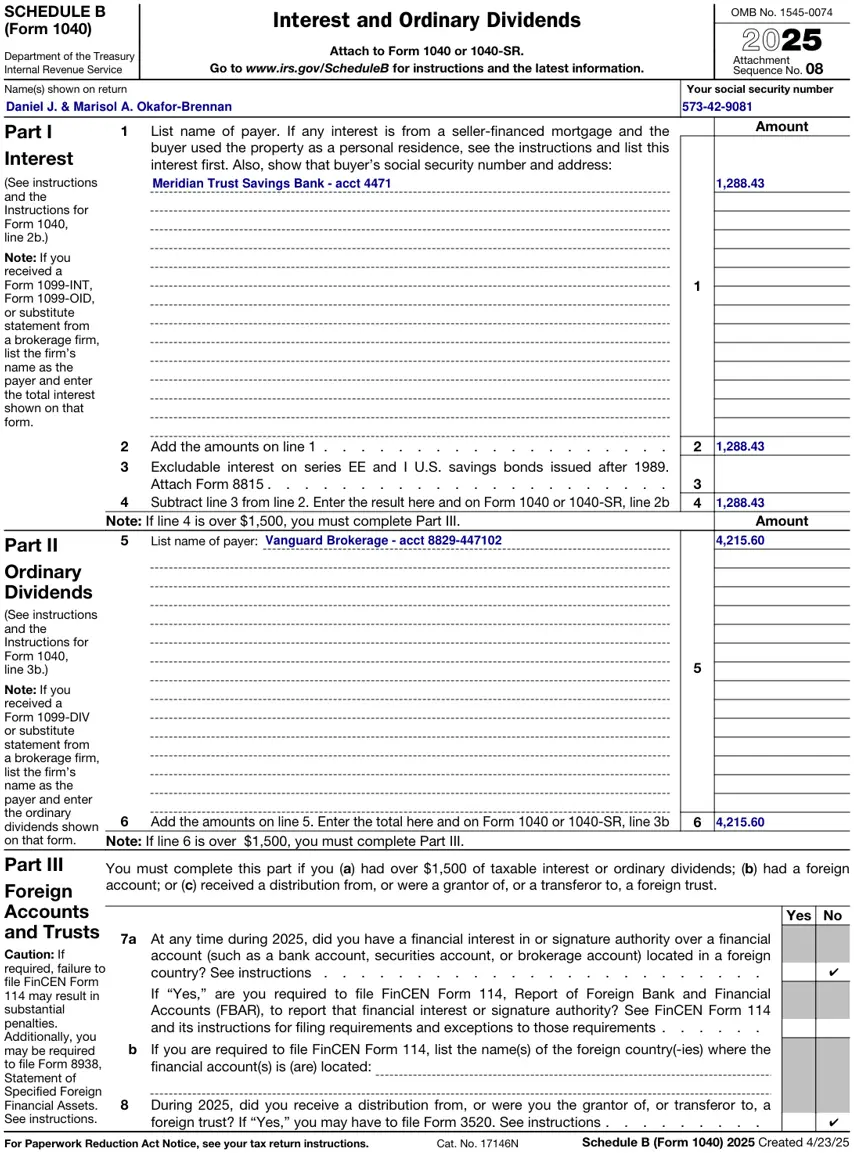
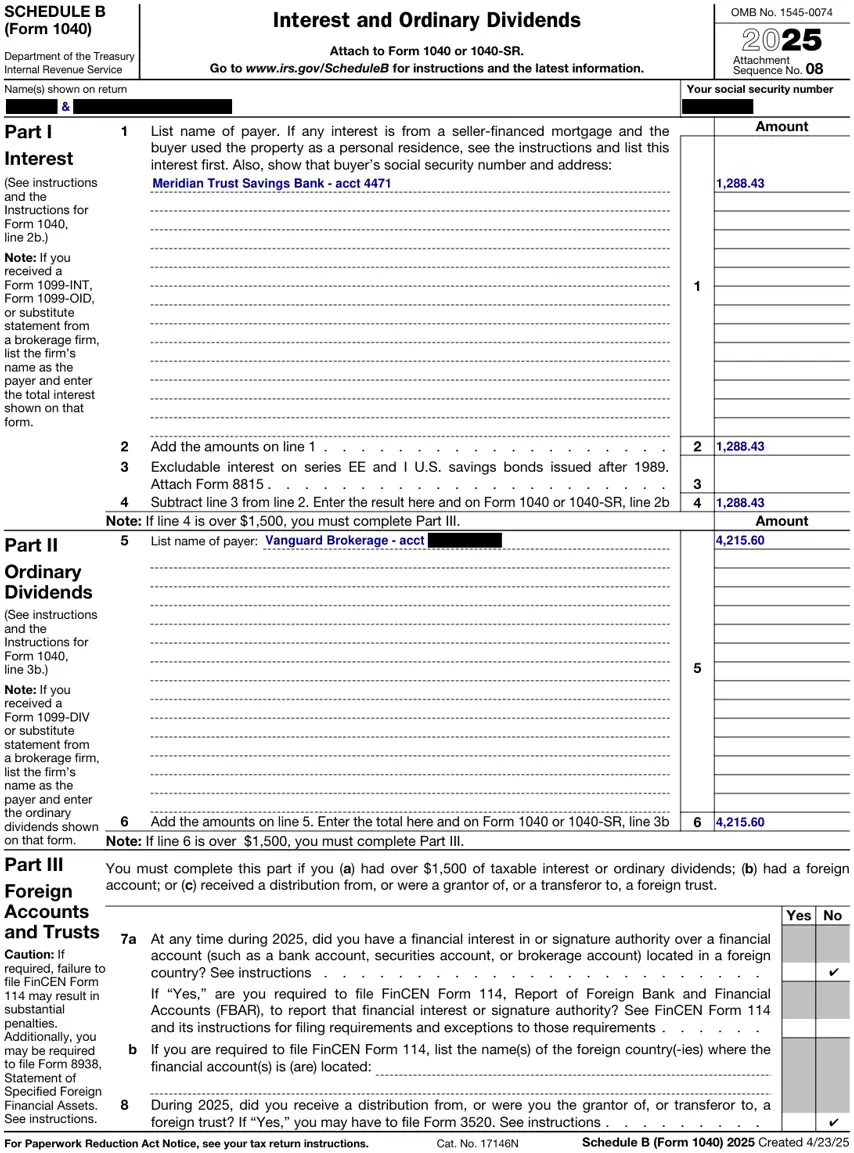
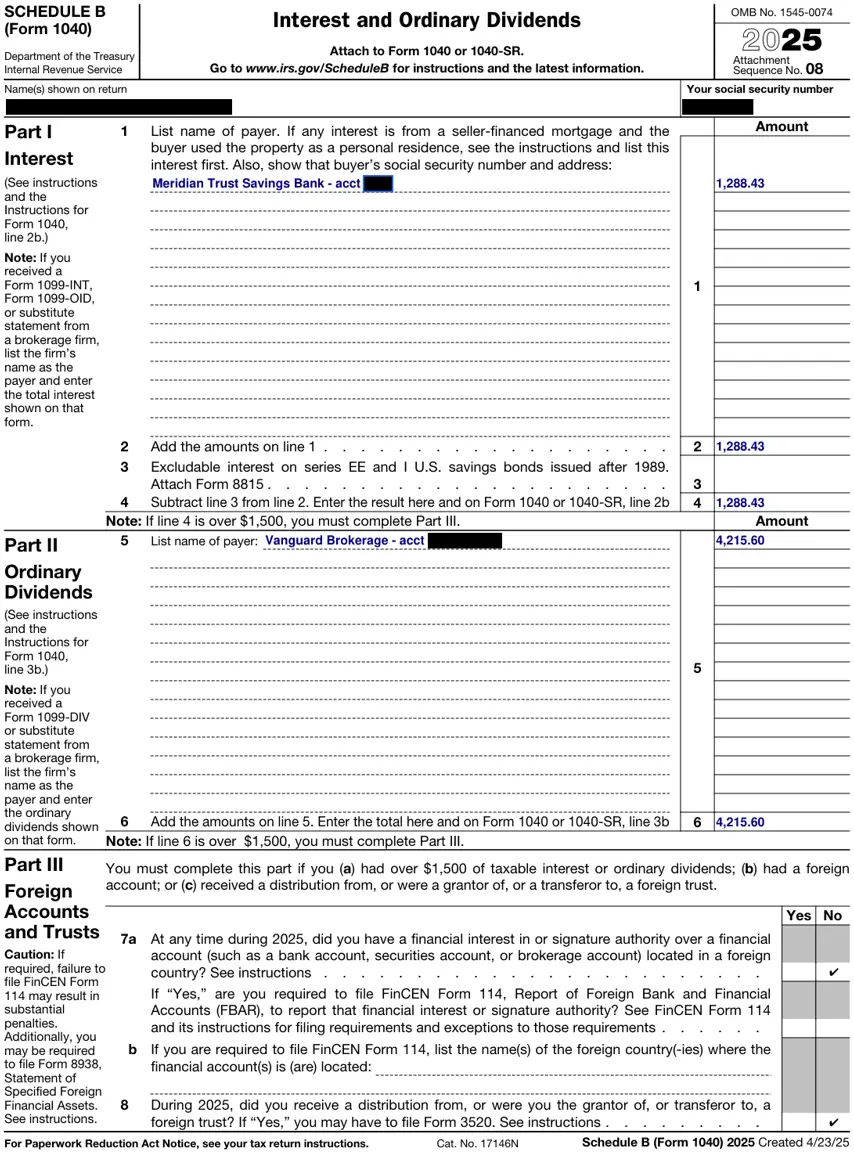
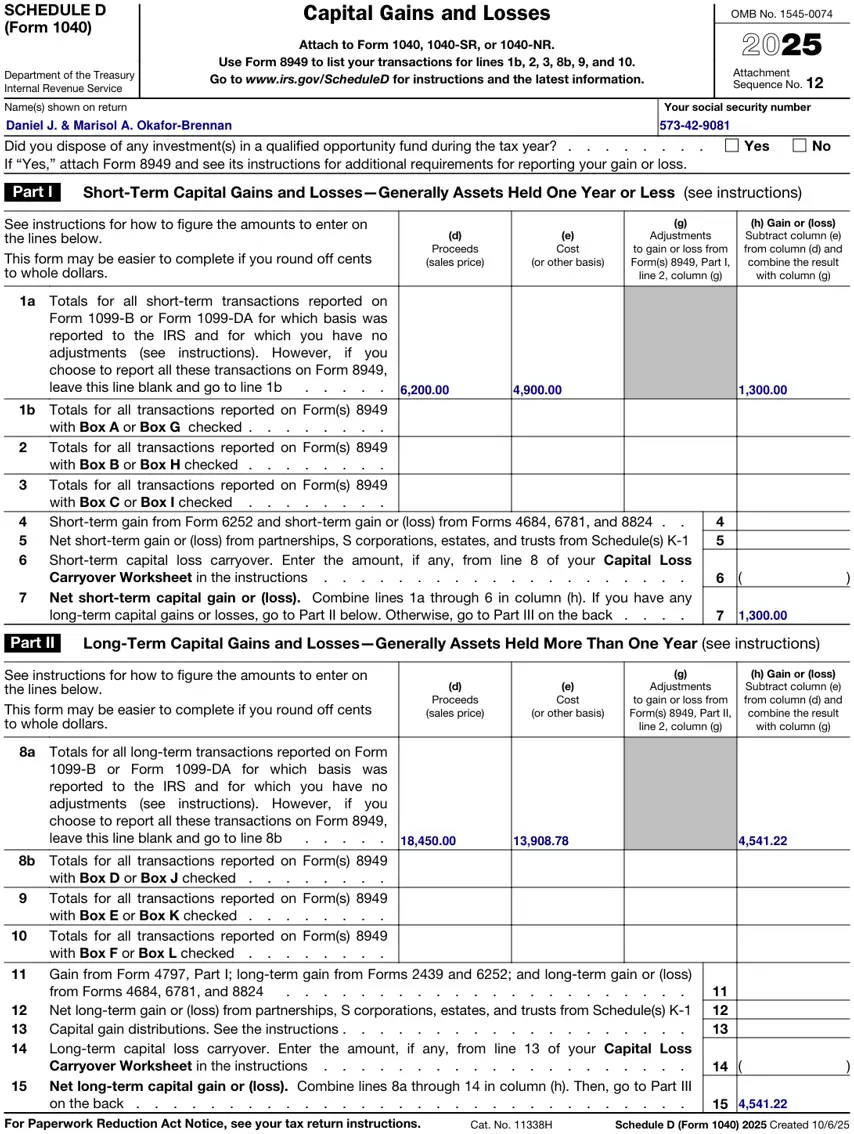
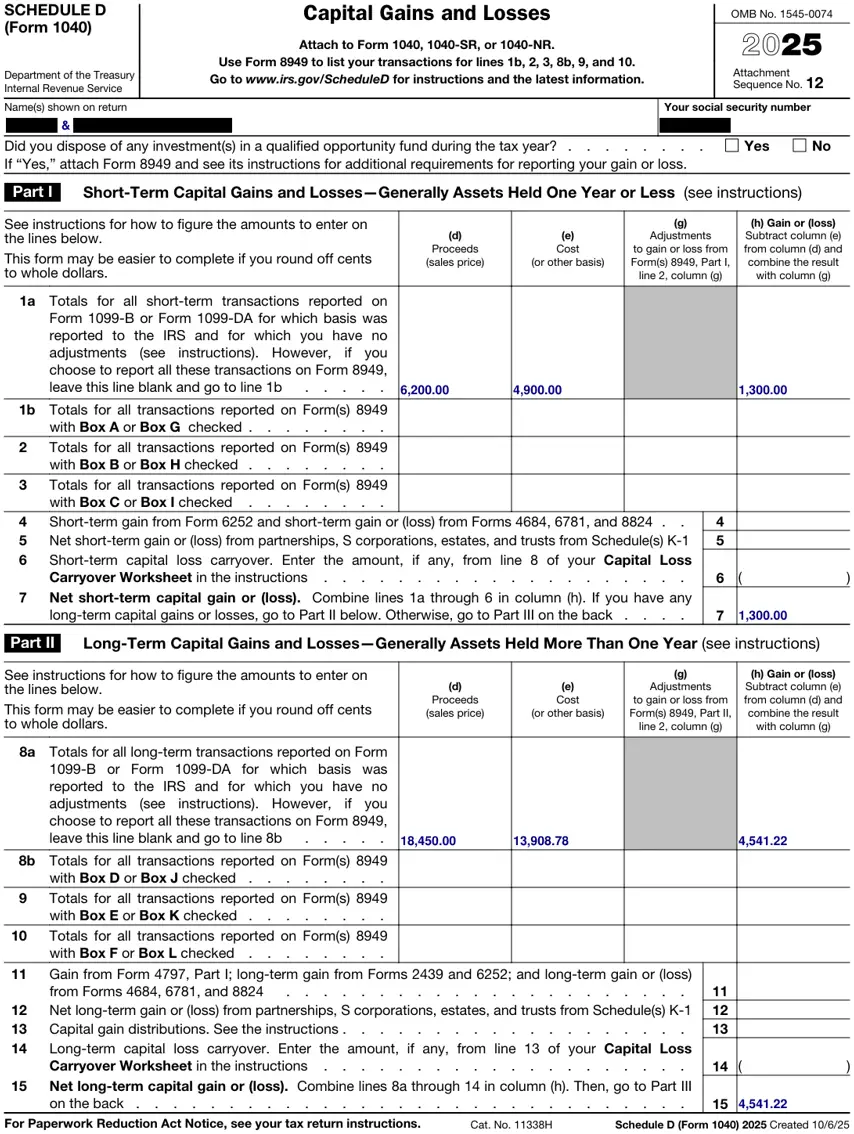
WellsFargo-sample-statement.pdf
capitalone-sample-estatement.pdf
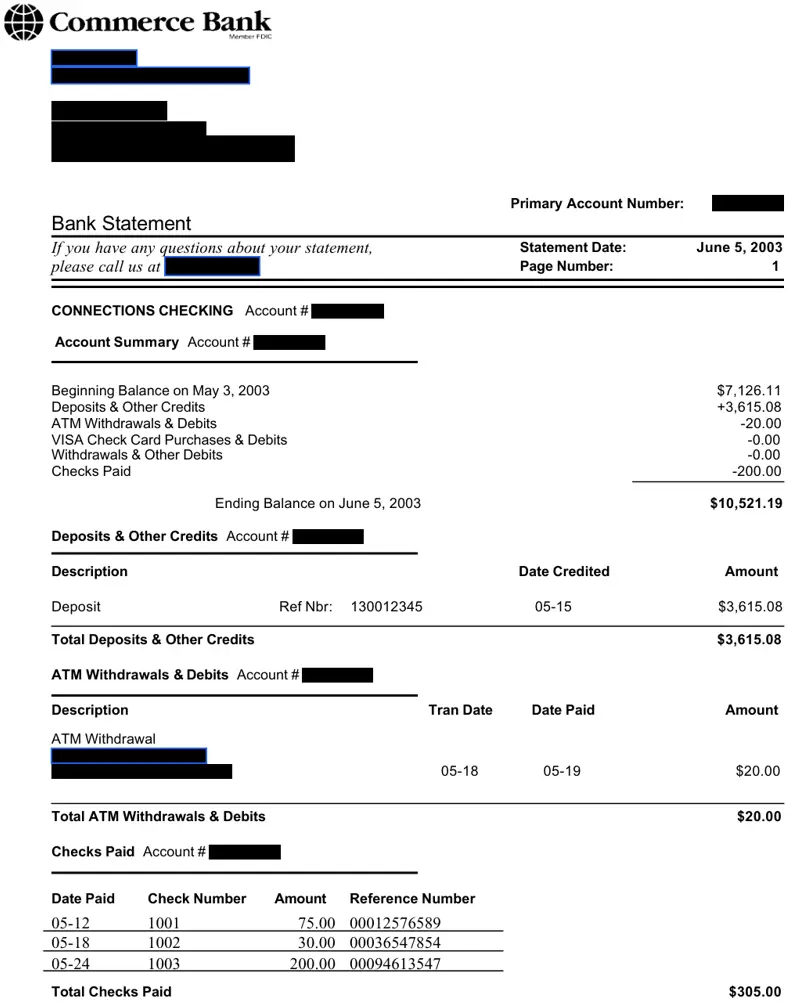
commercebank-sample-statement.pdf
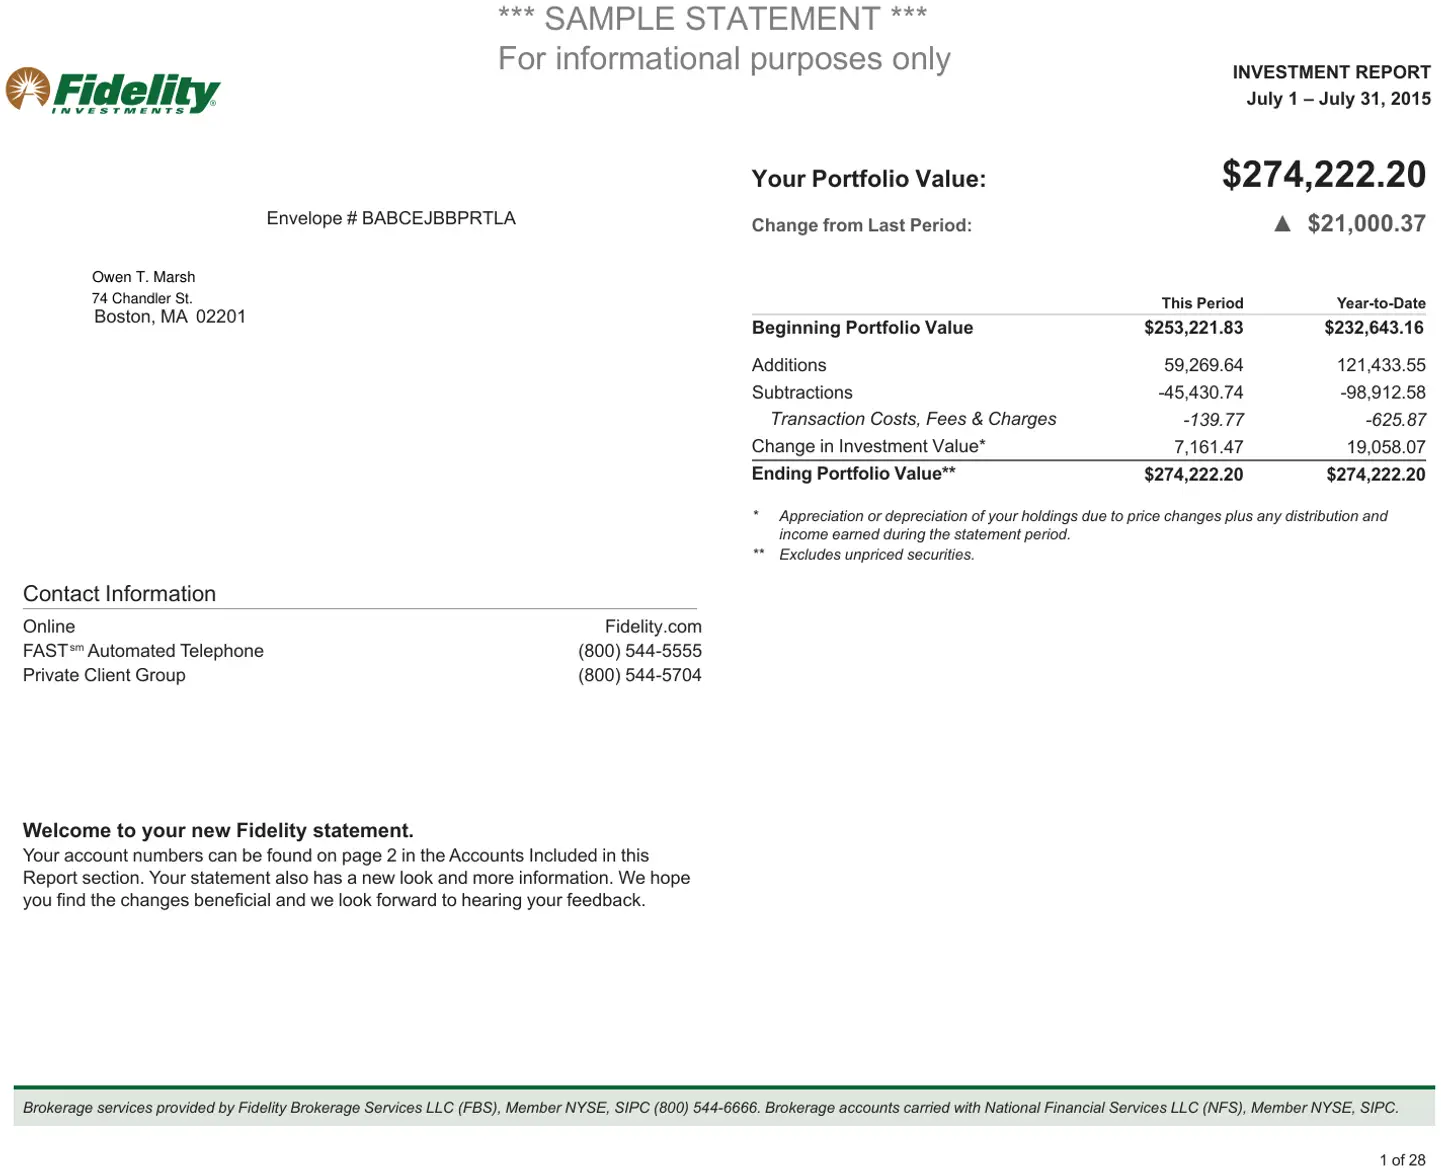
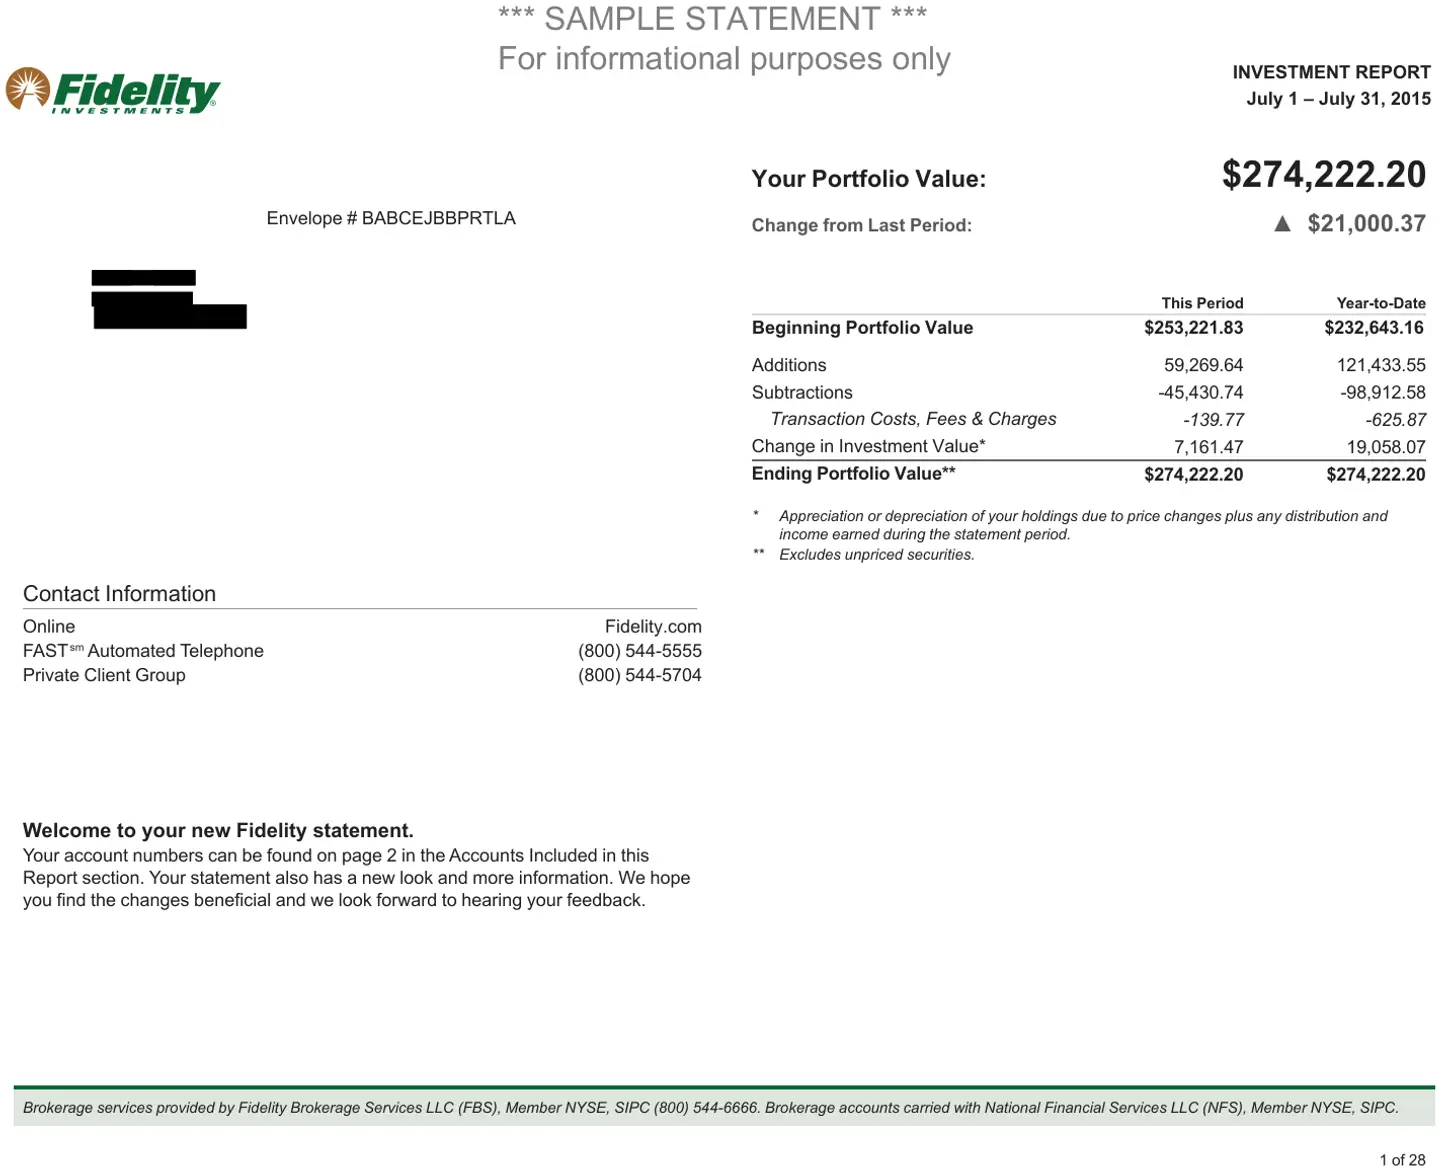
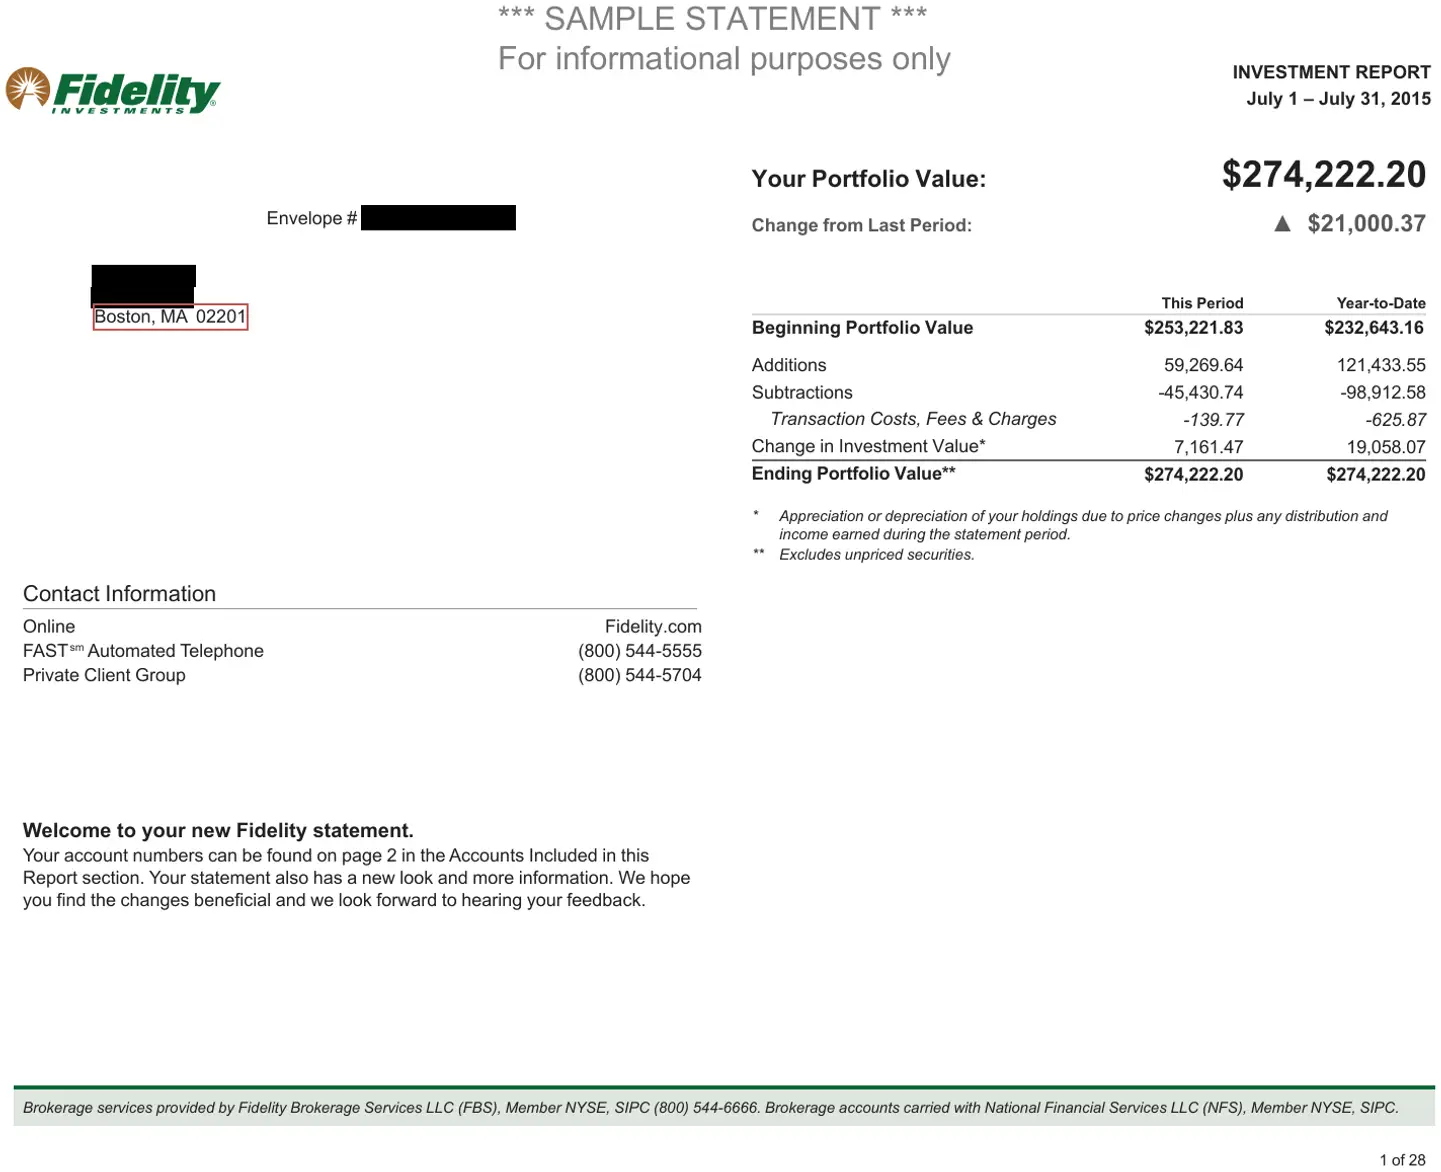
Fidelity-sample-statement.pdf
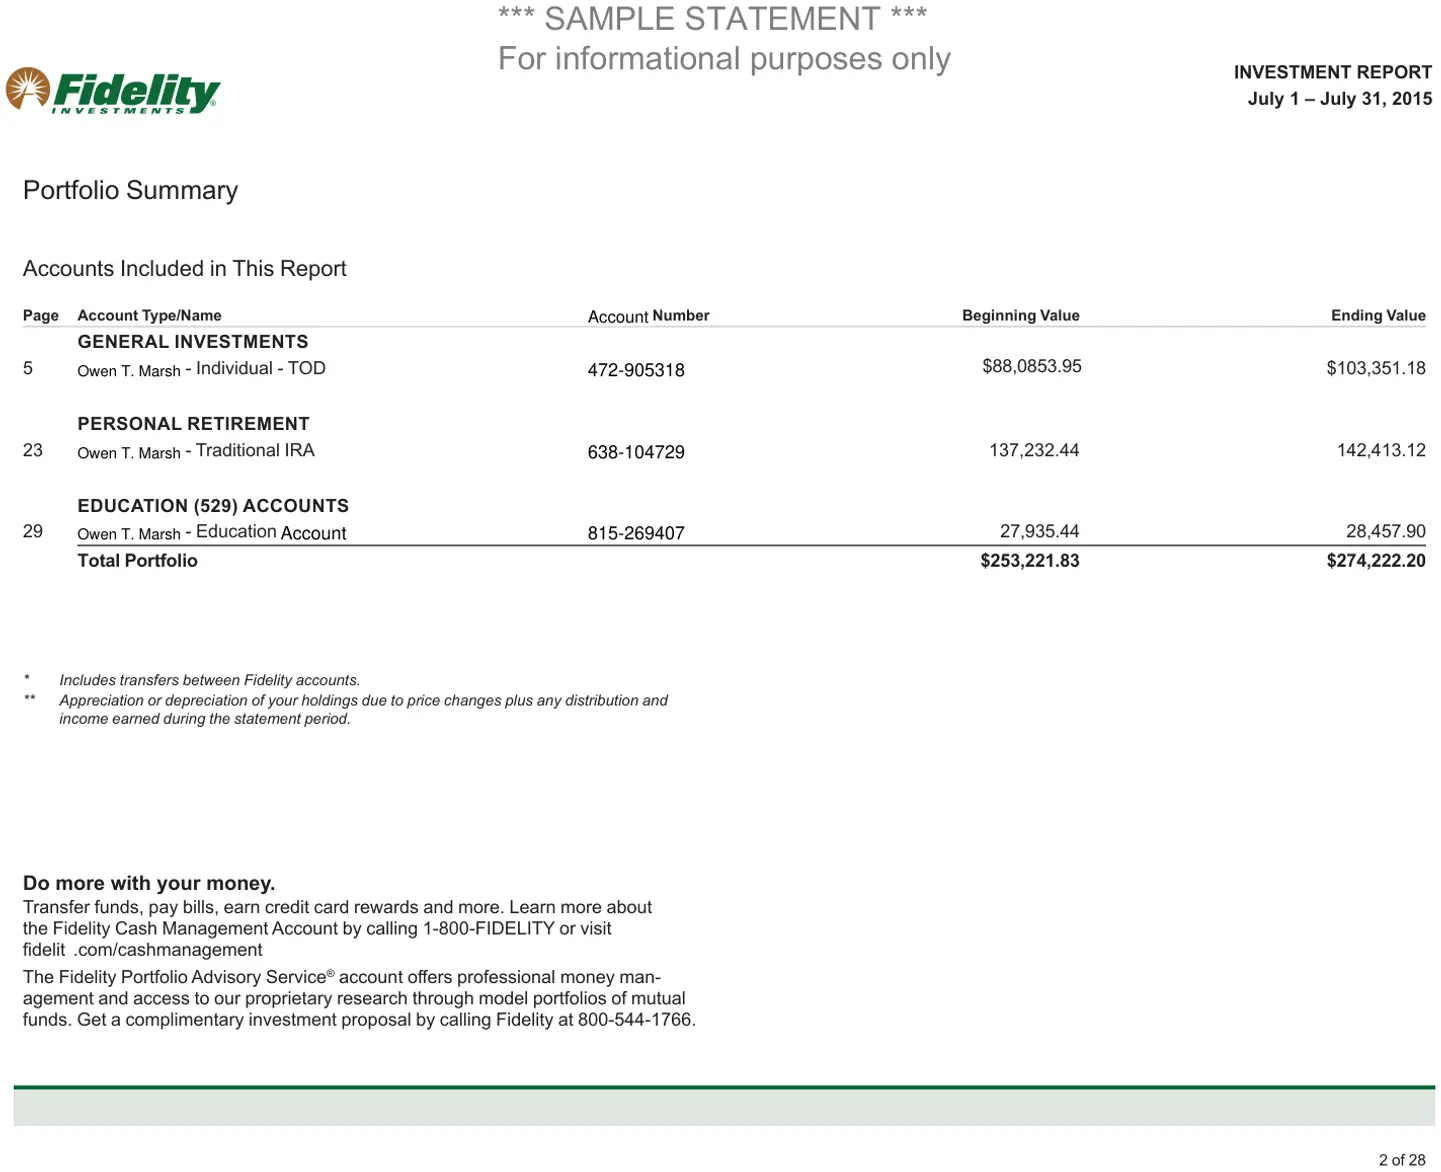
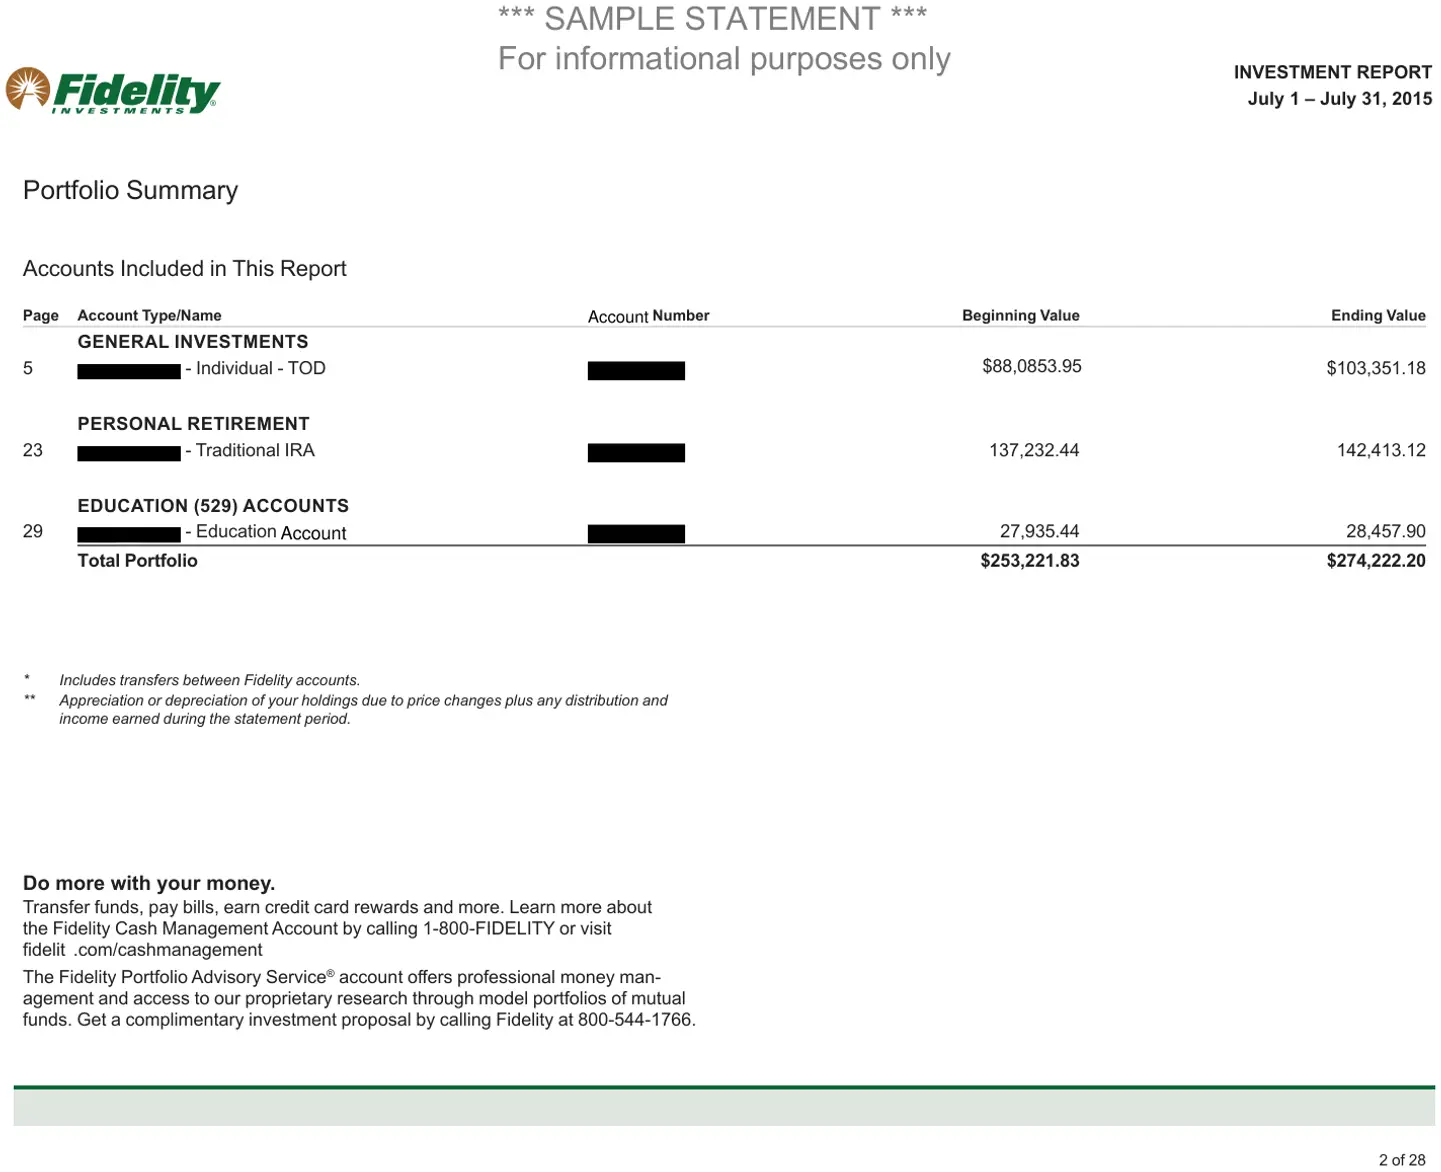
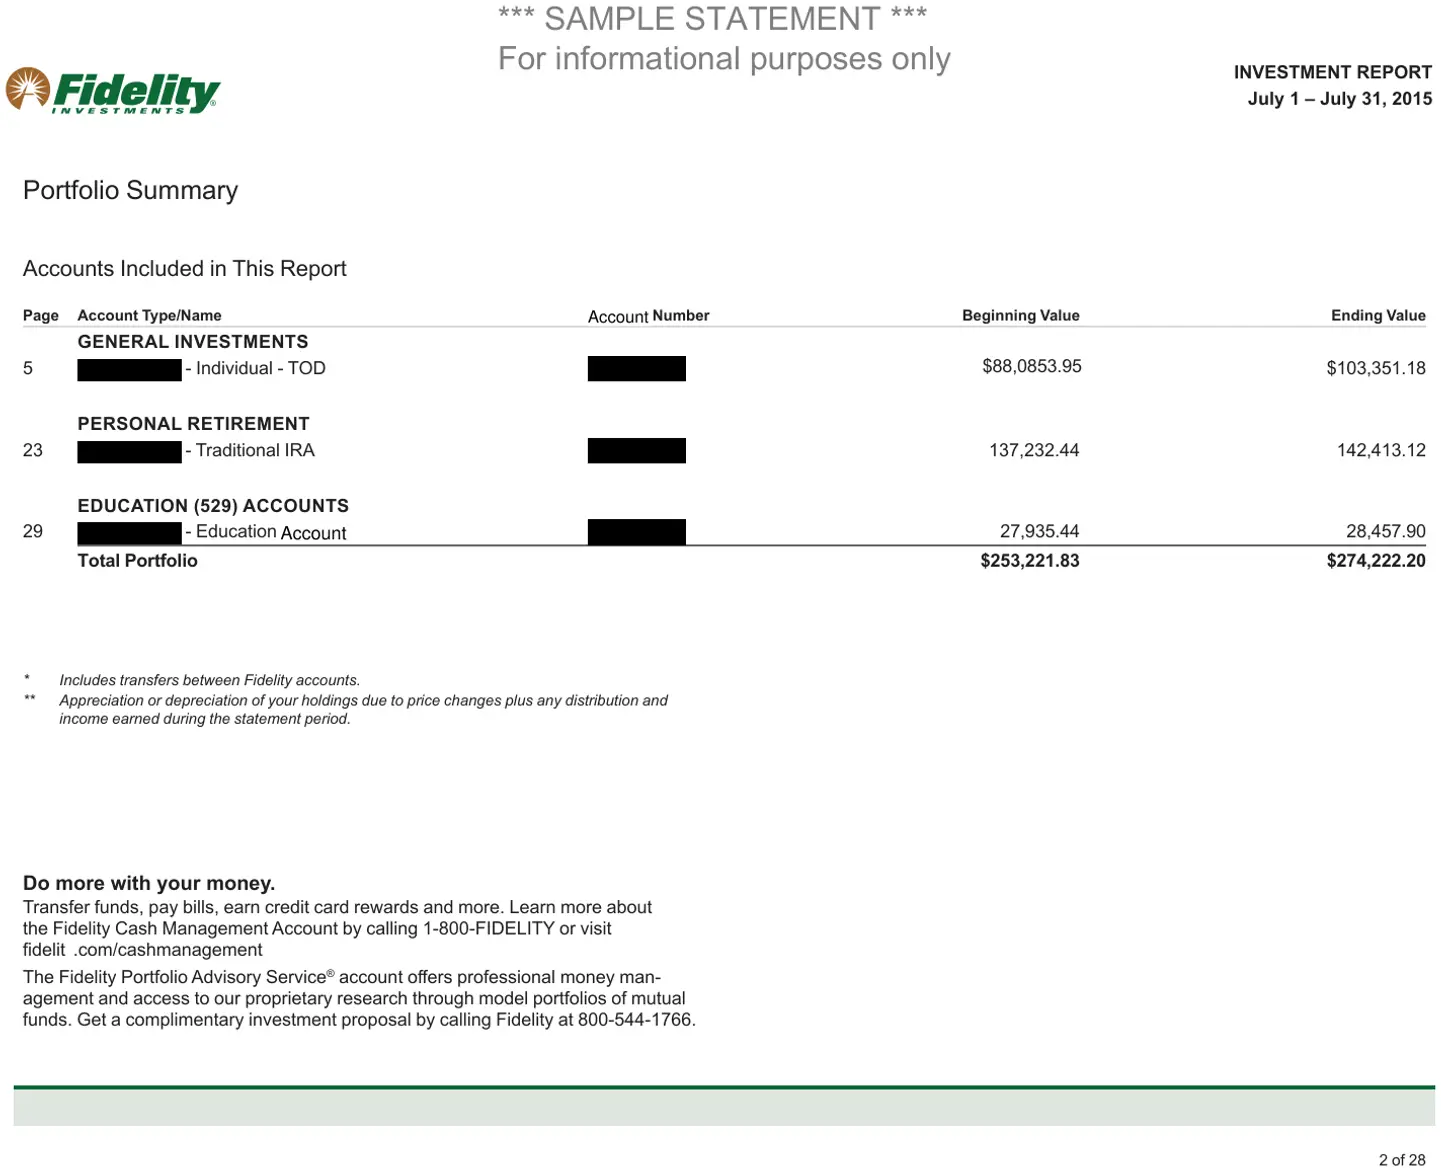
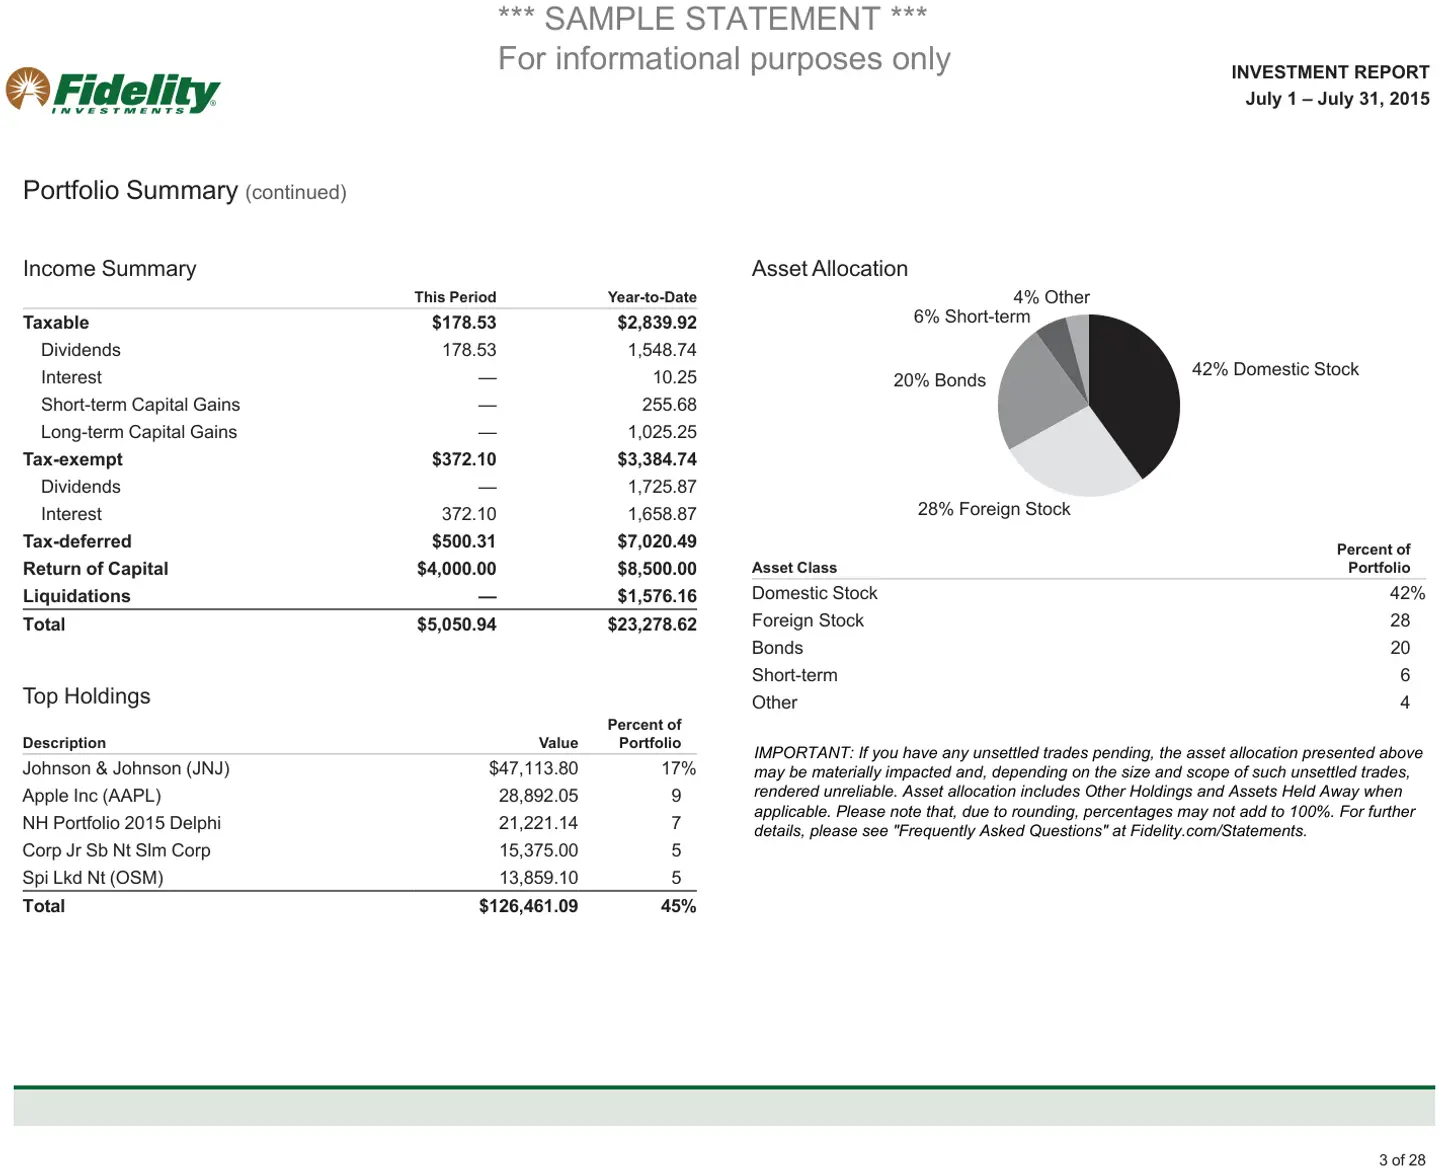
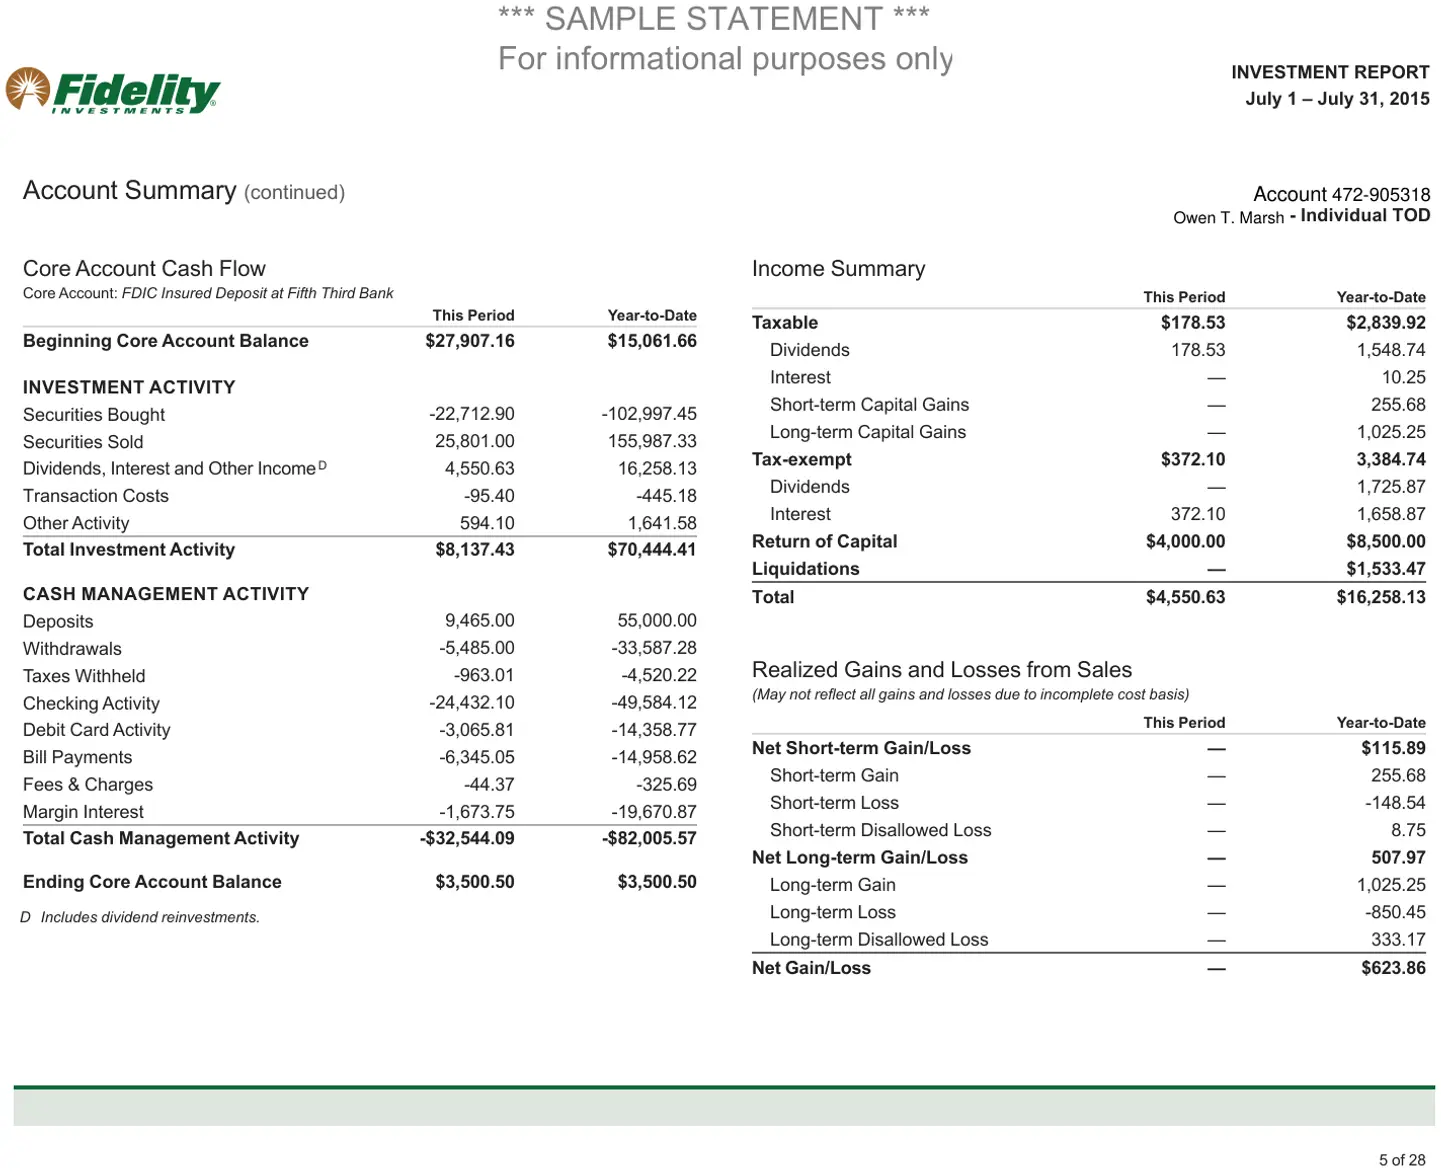
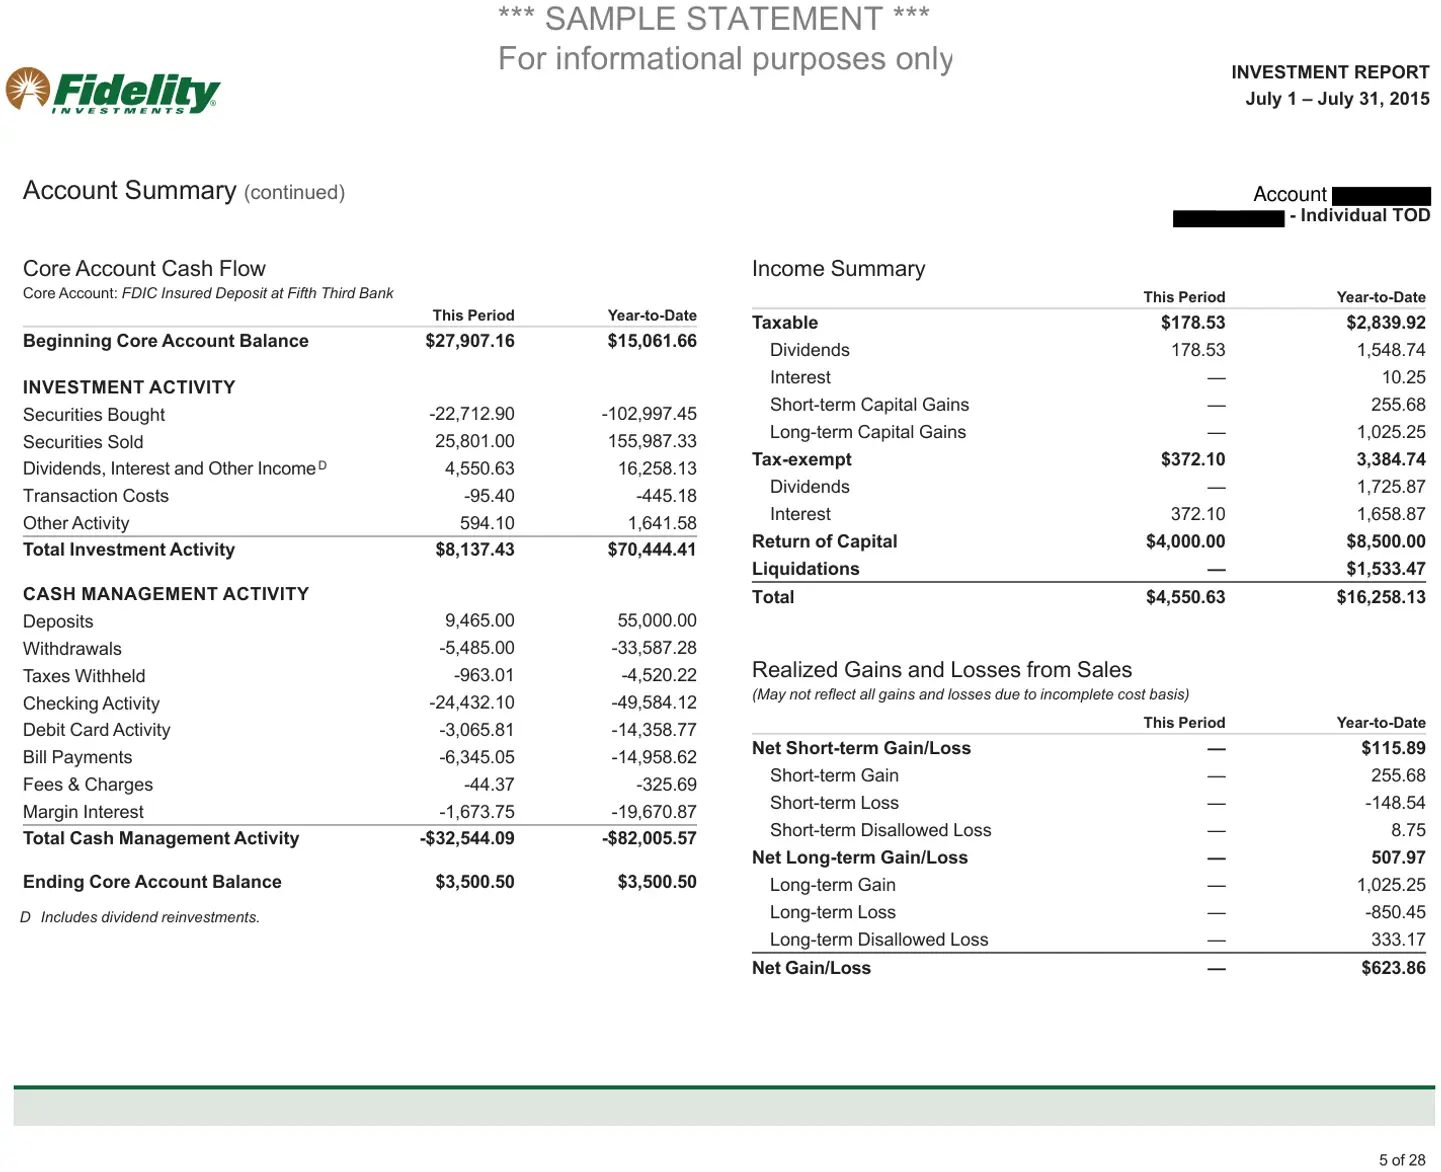
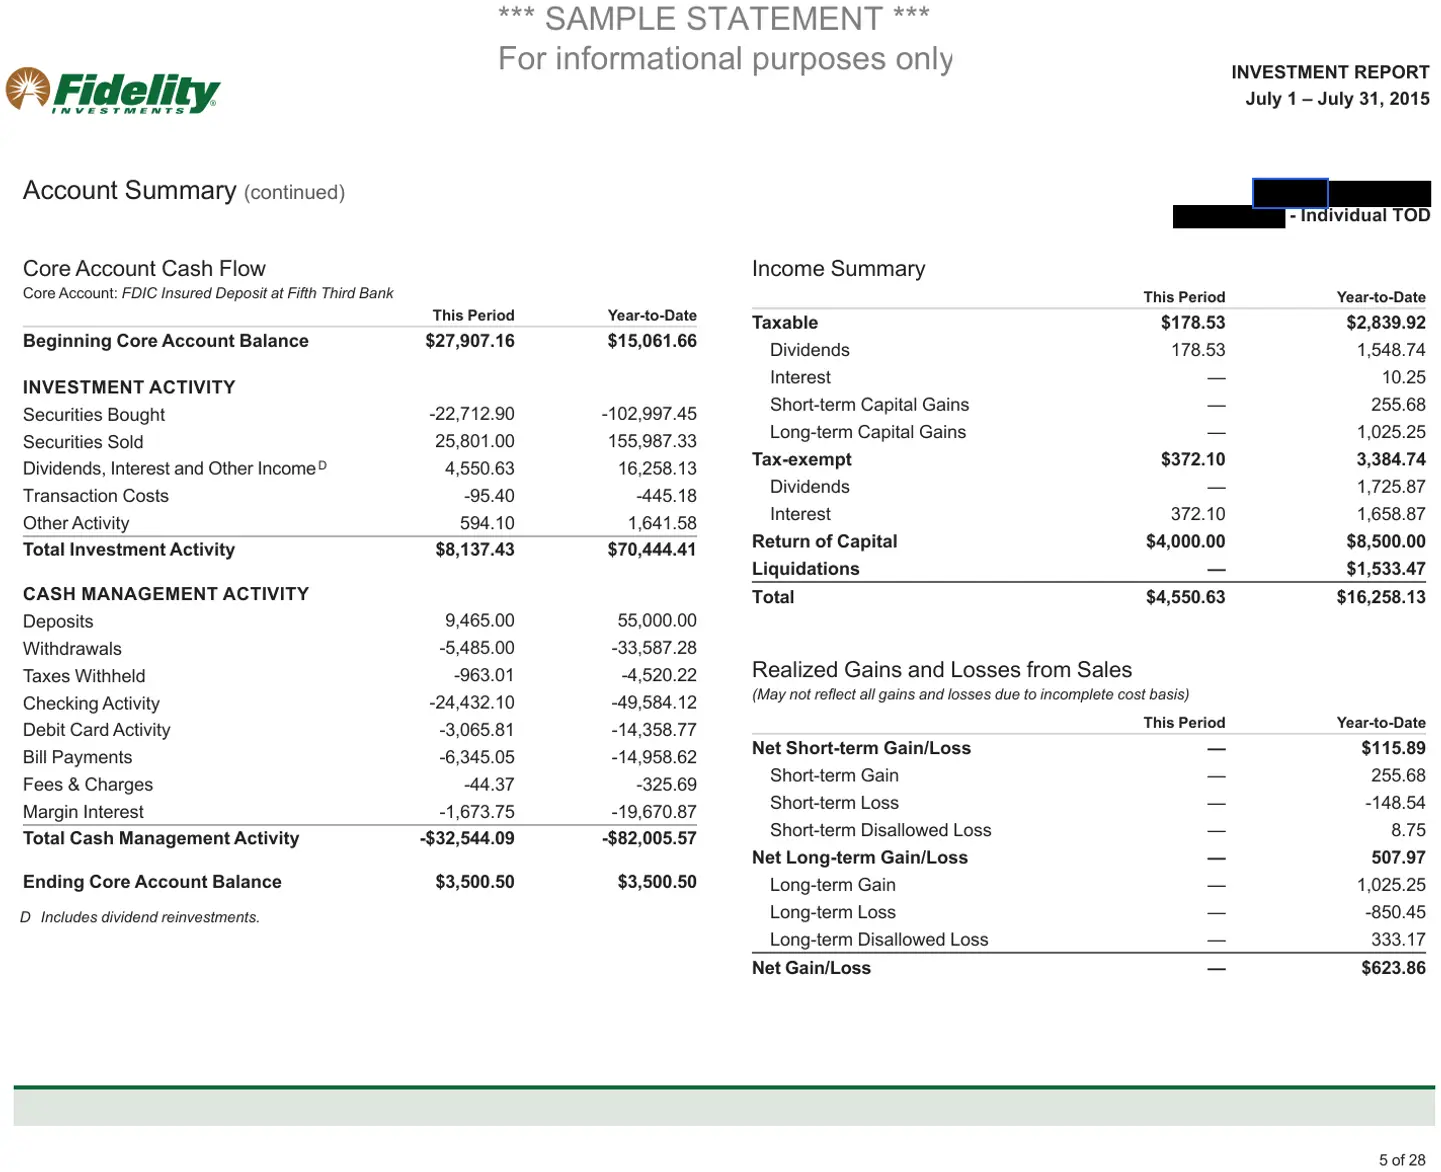
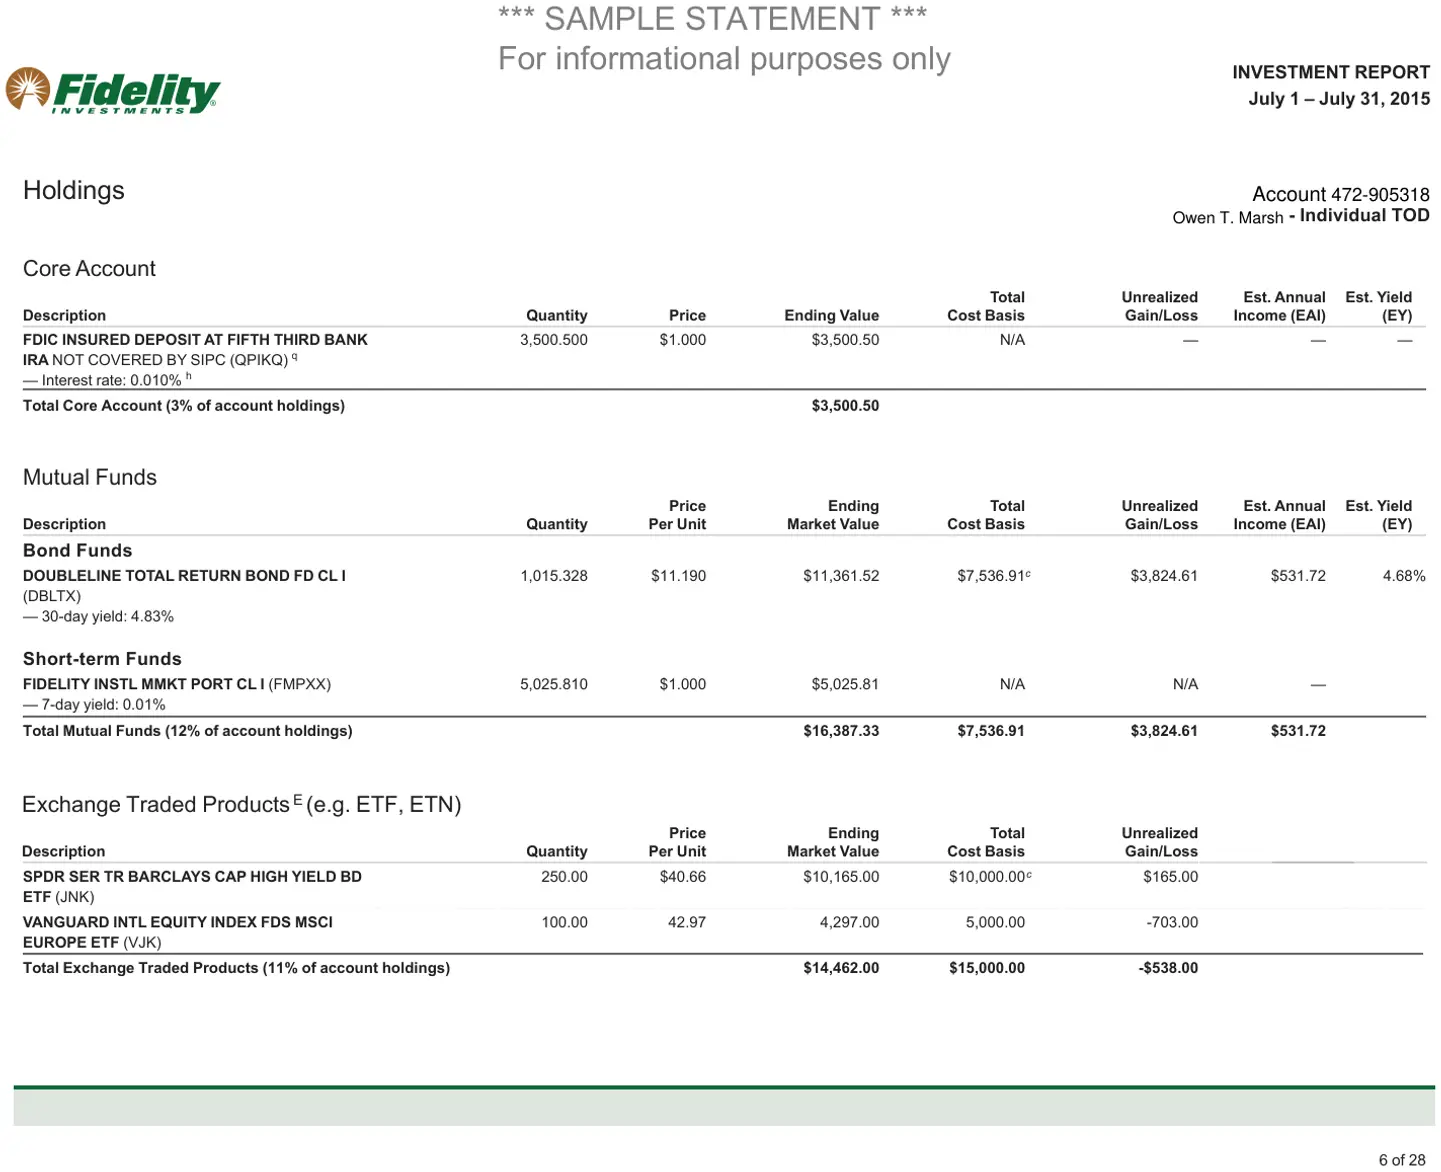
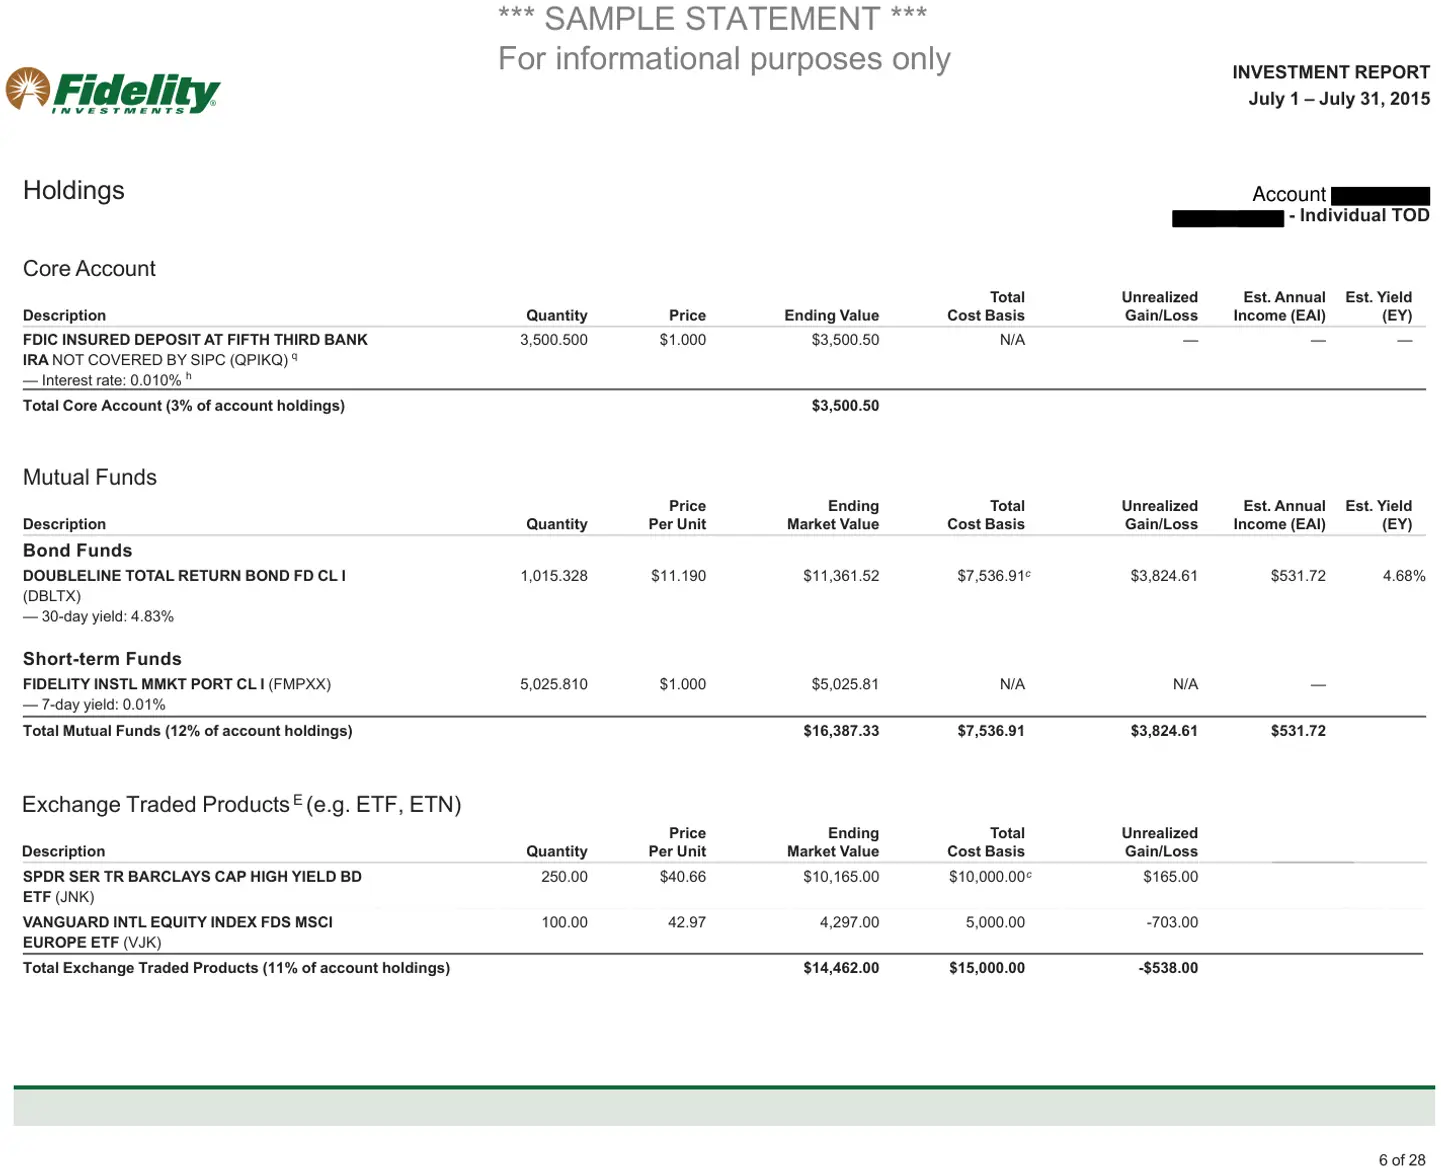
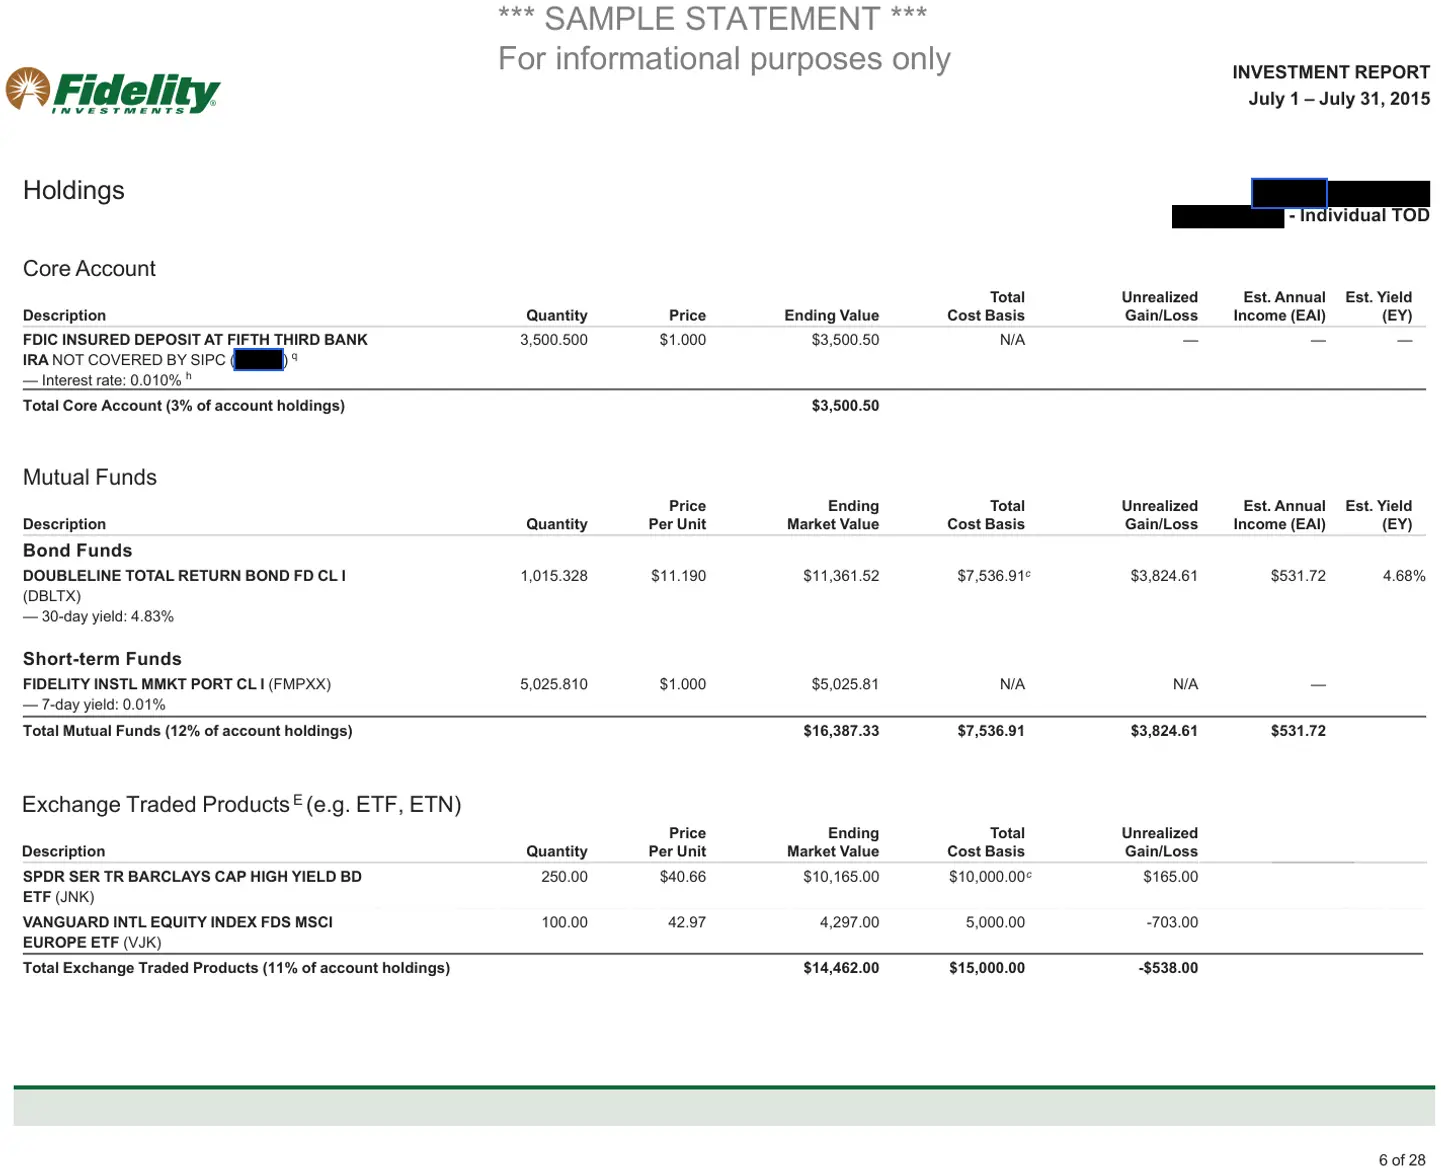
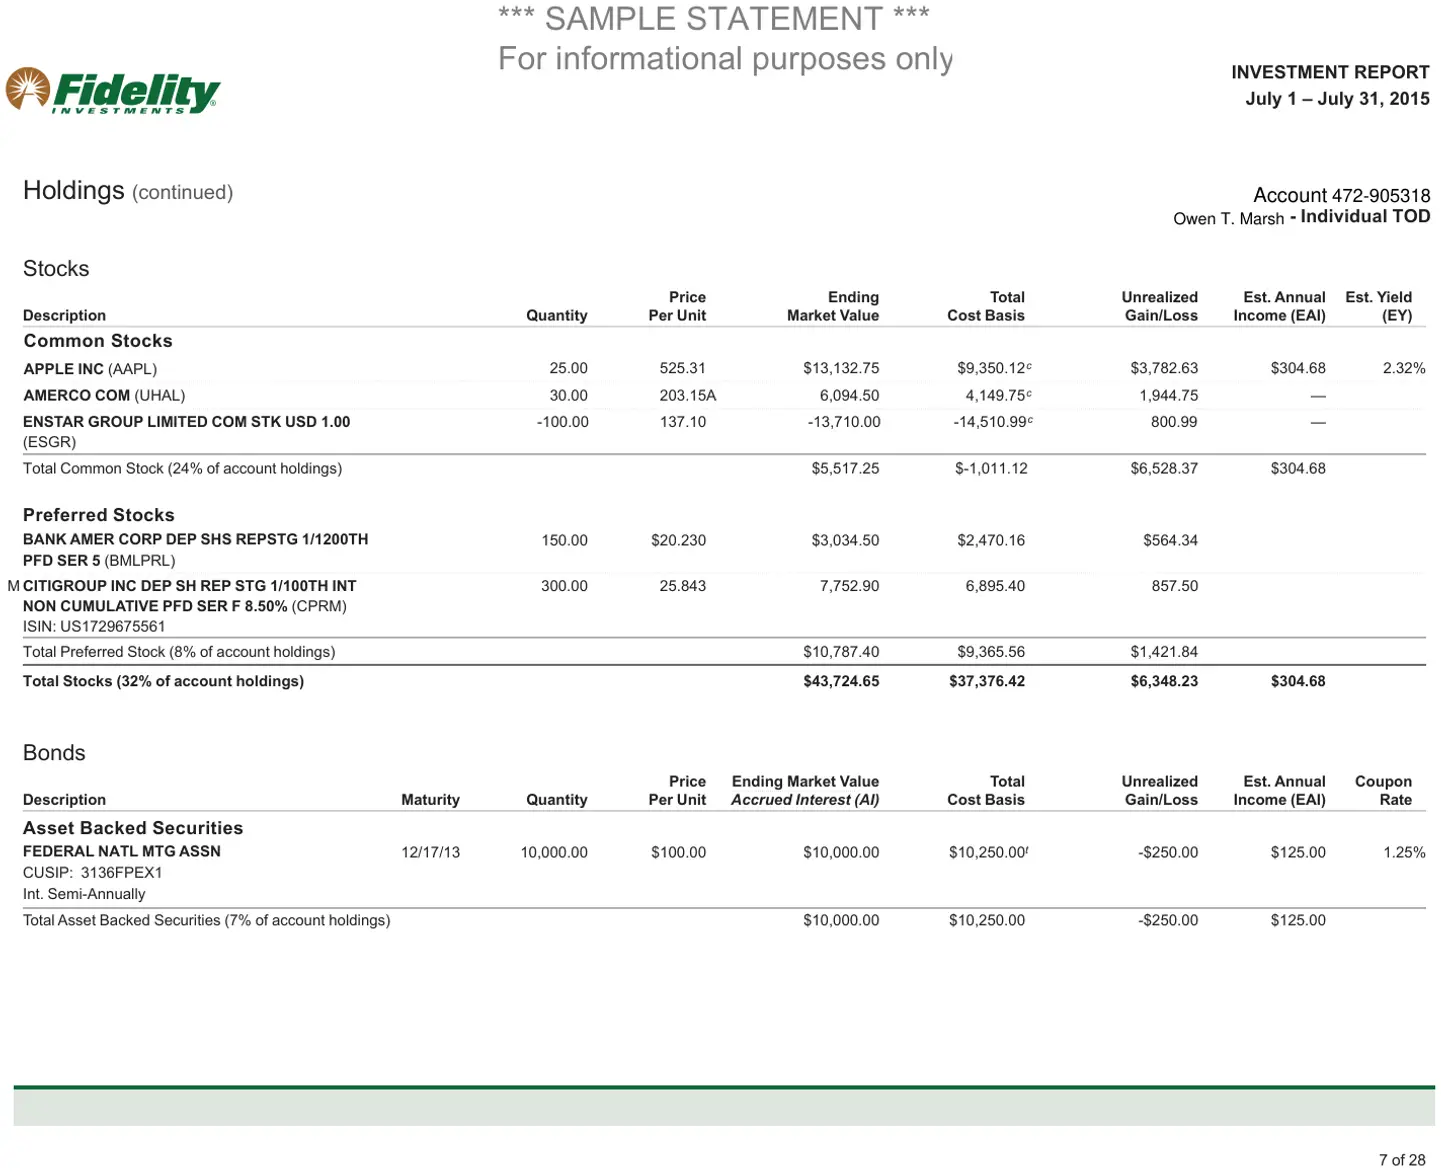
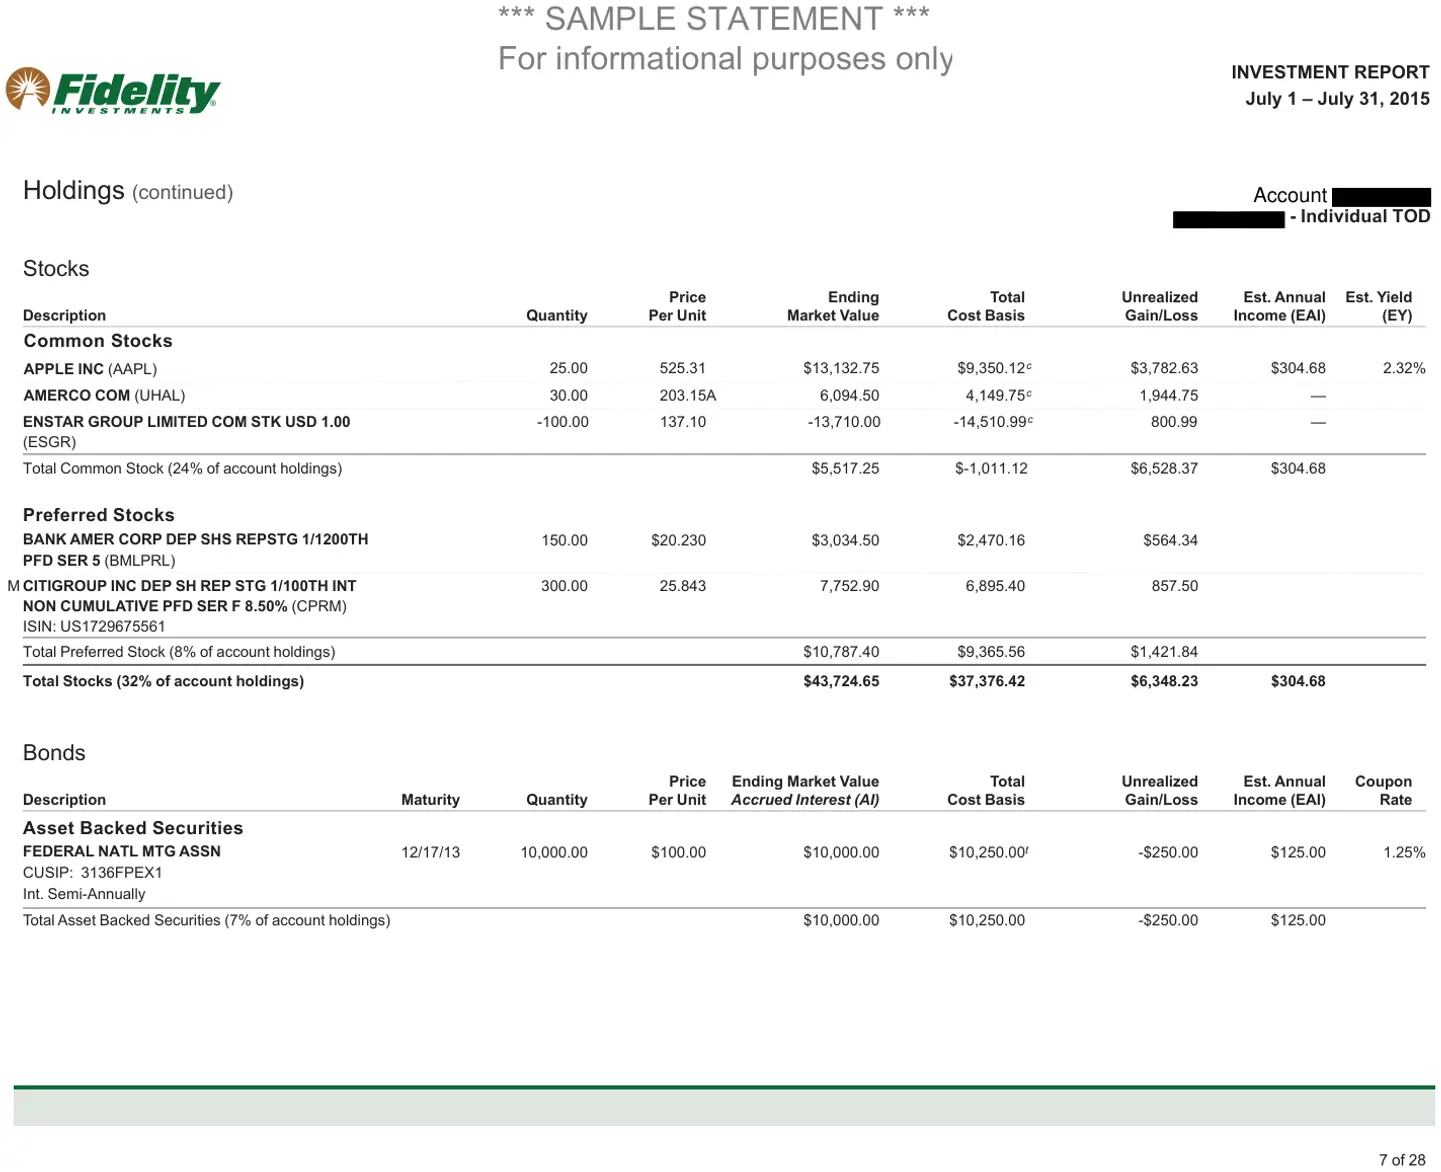
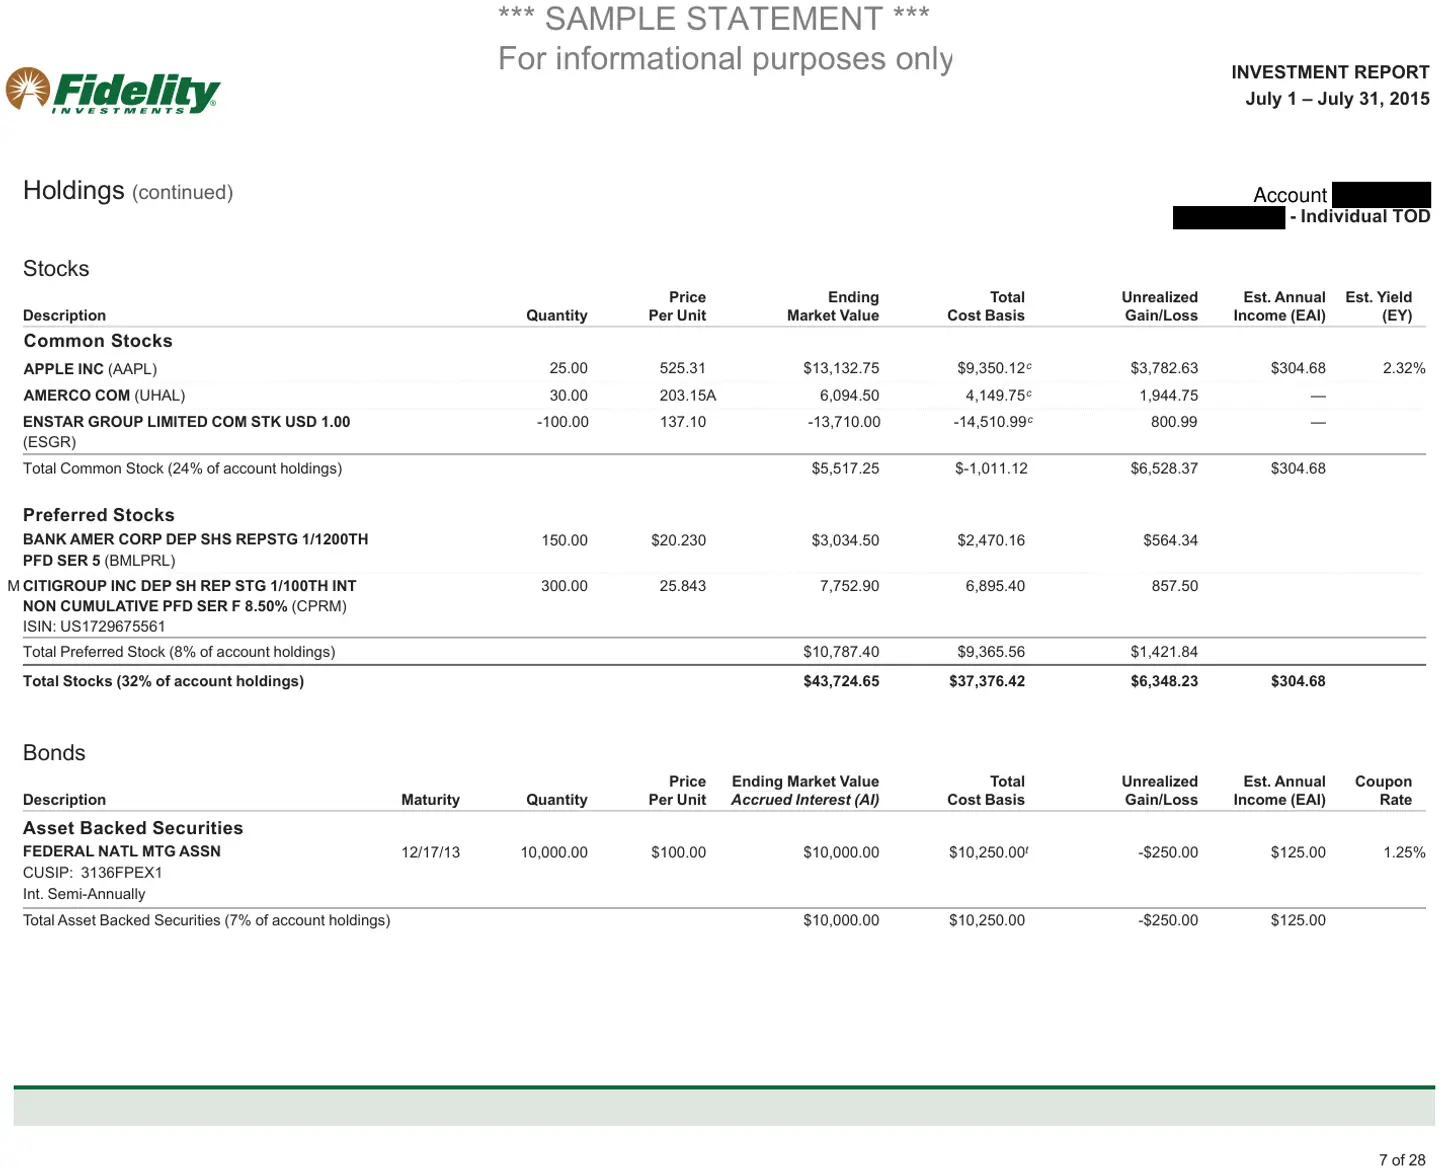
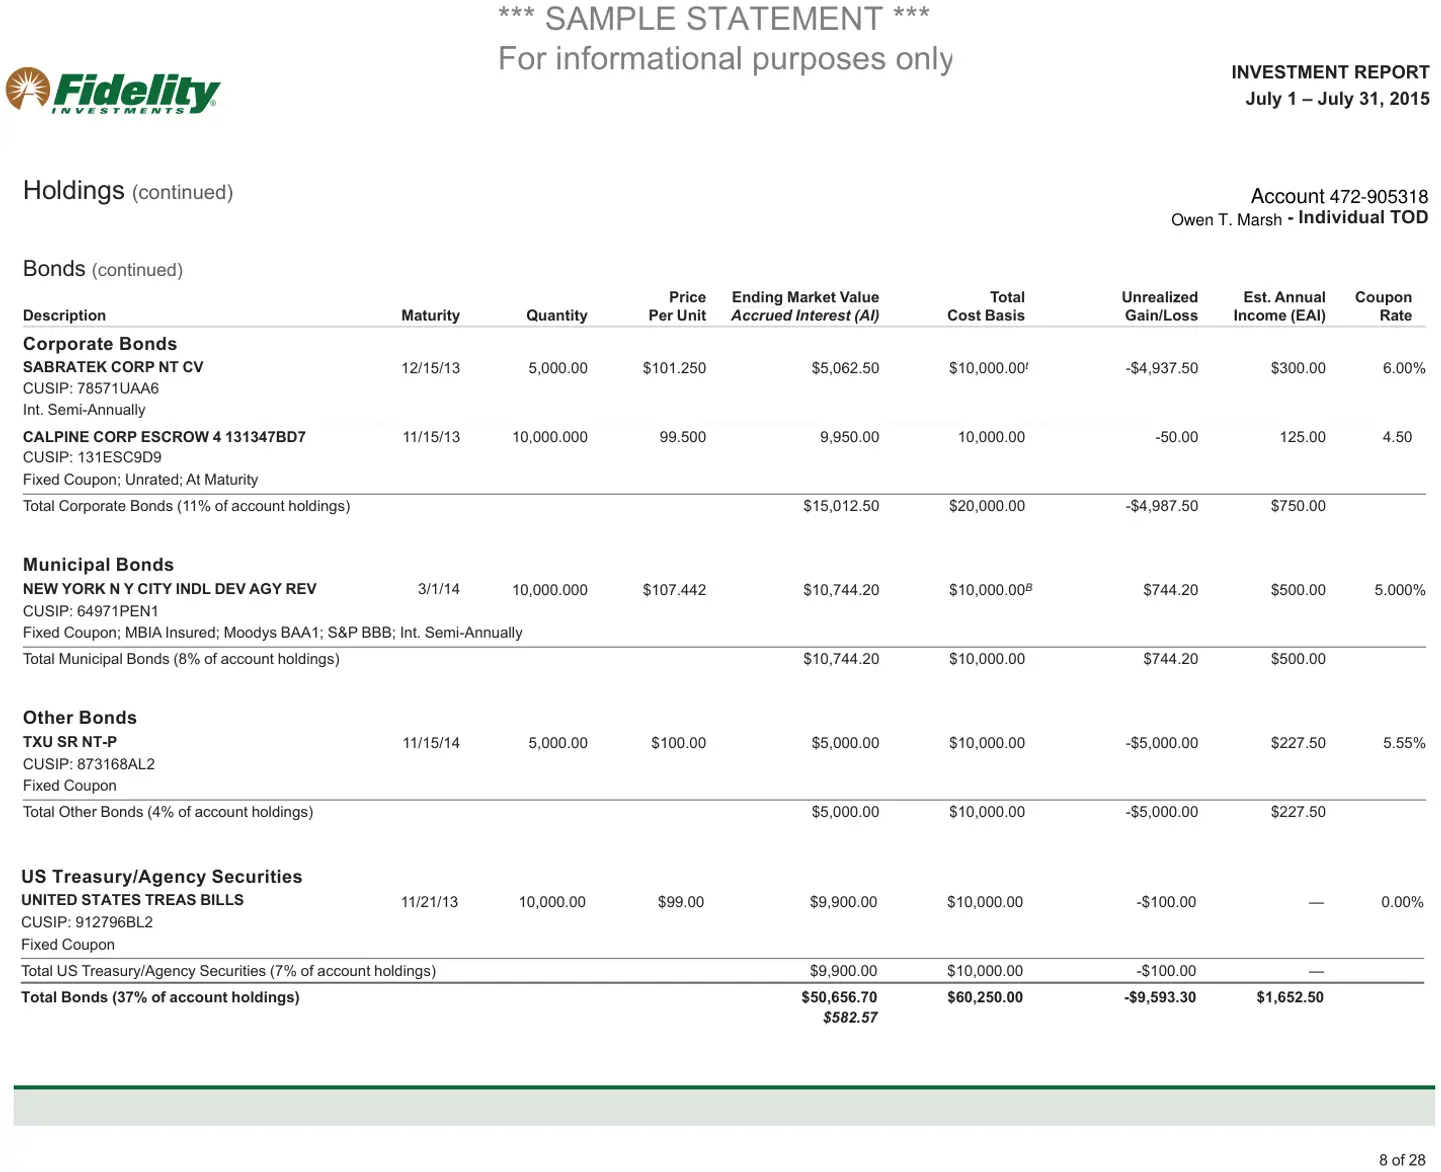
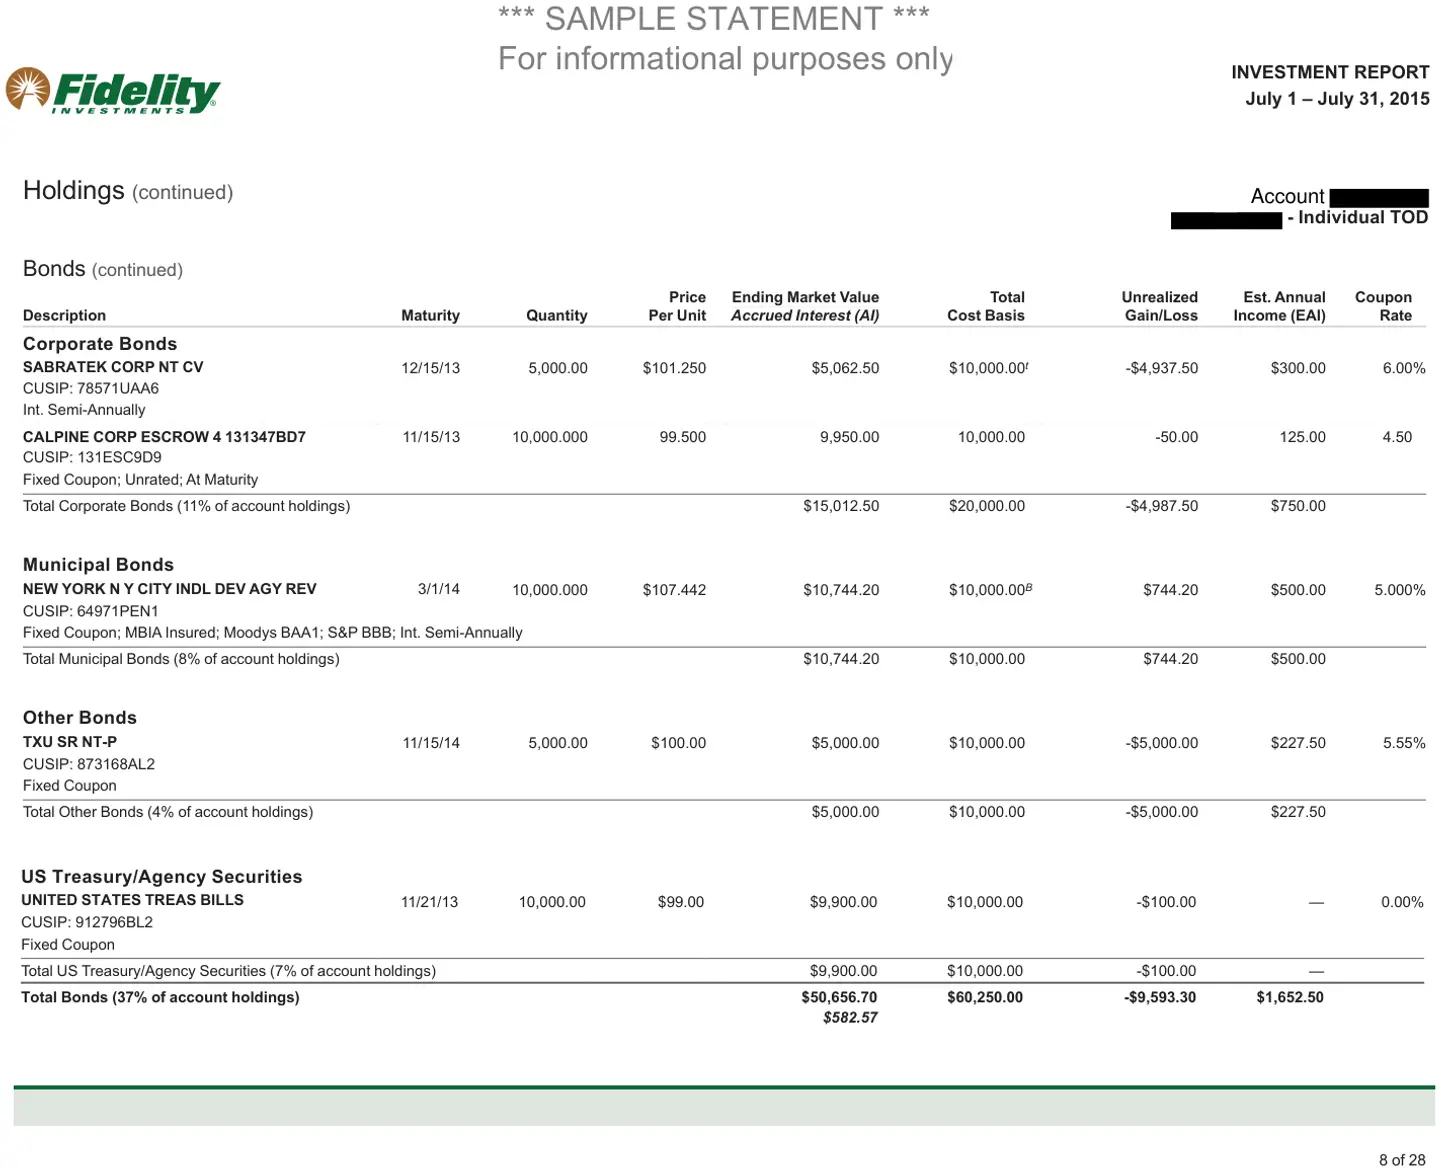
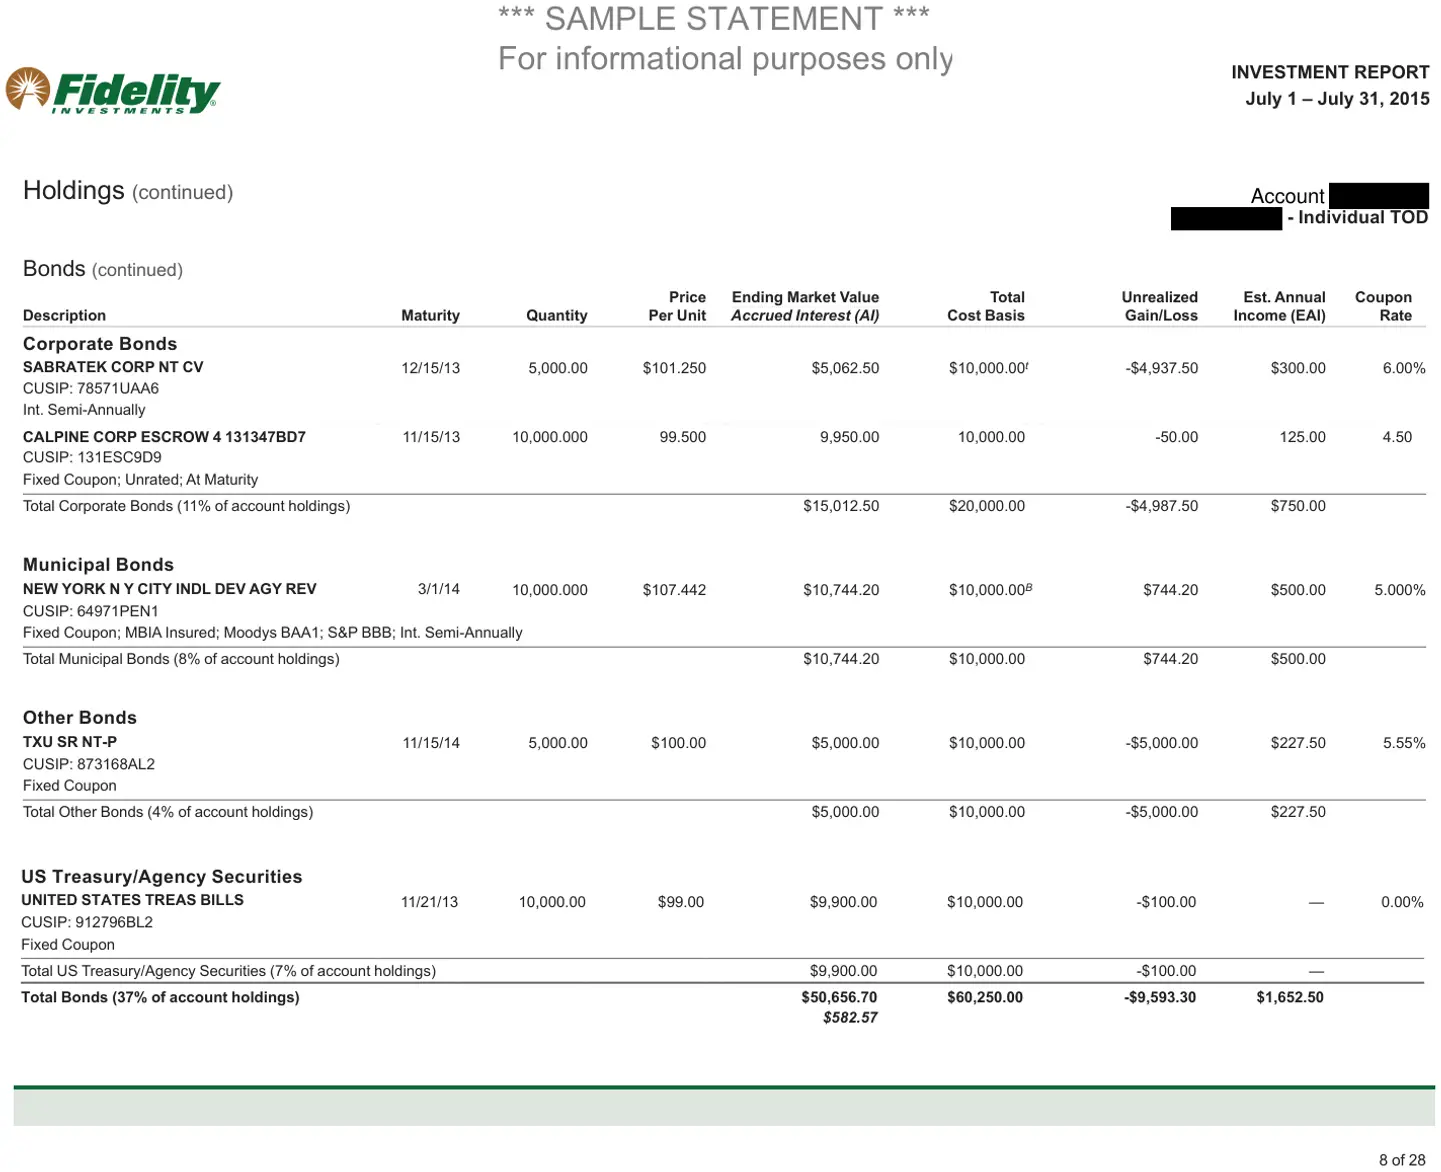
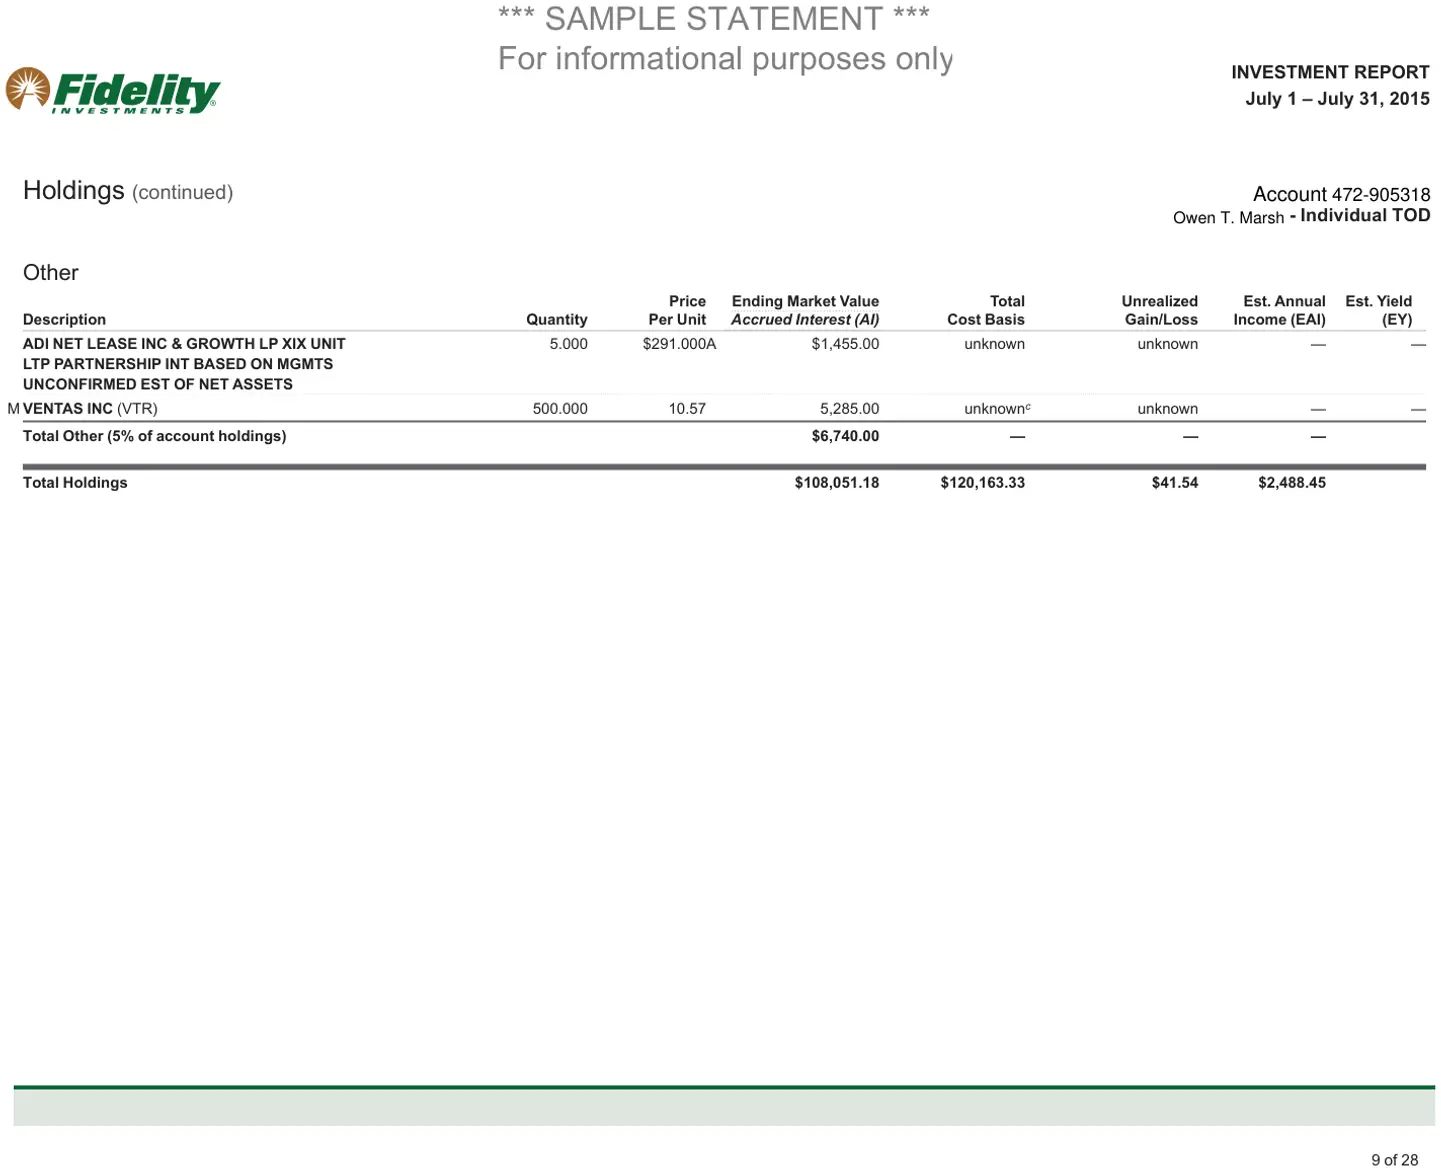
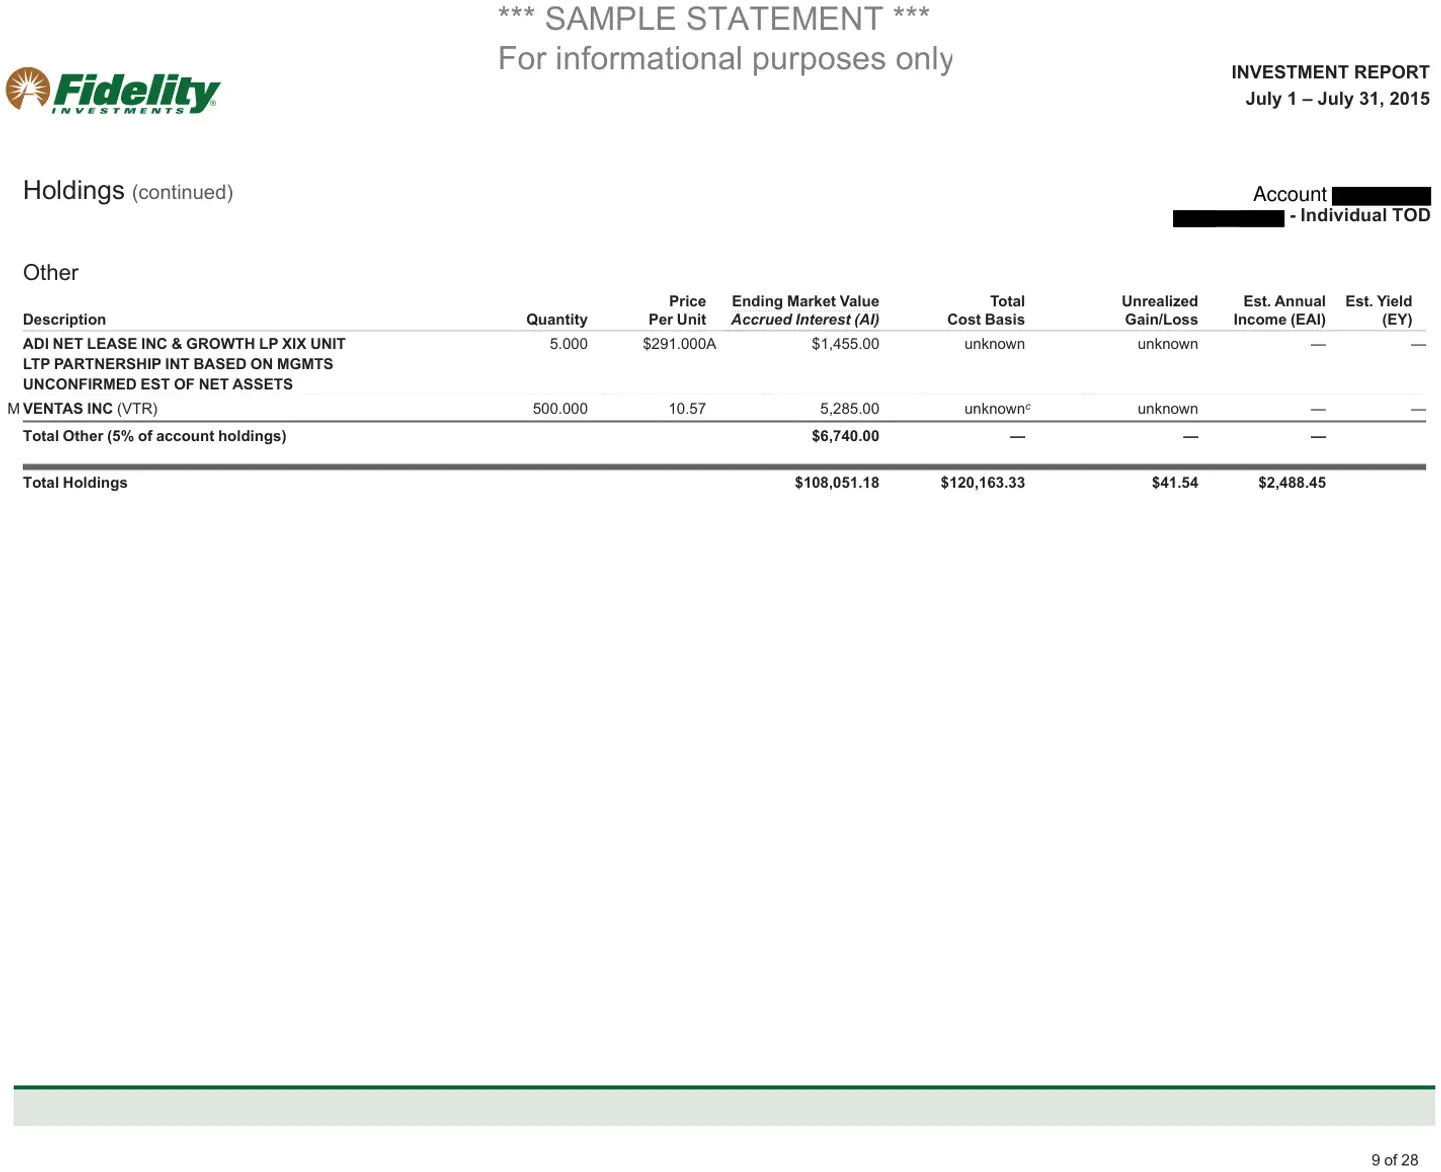
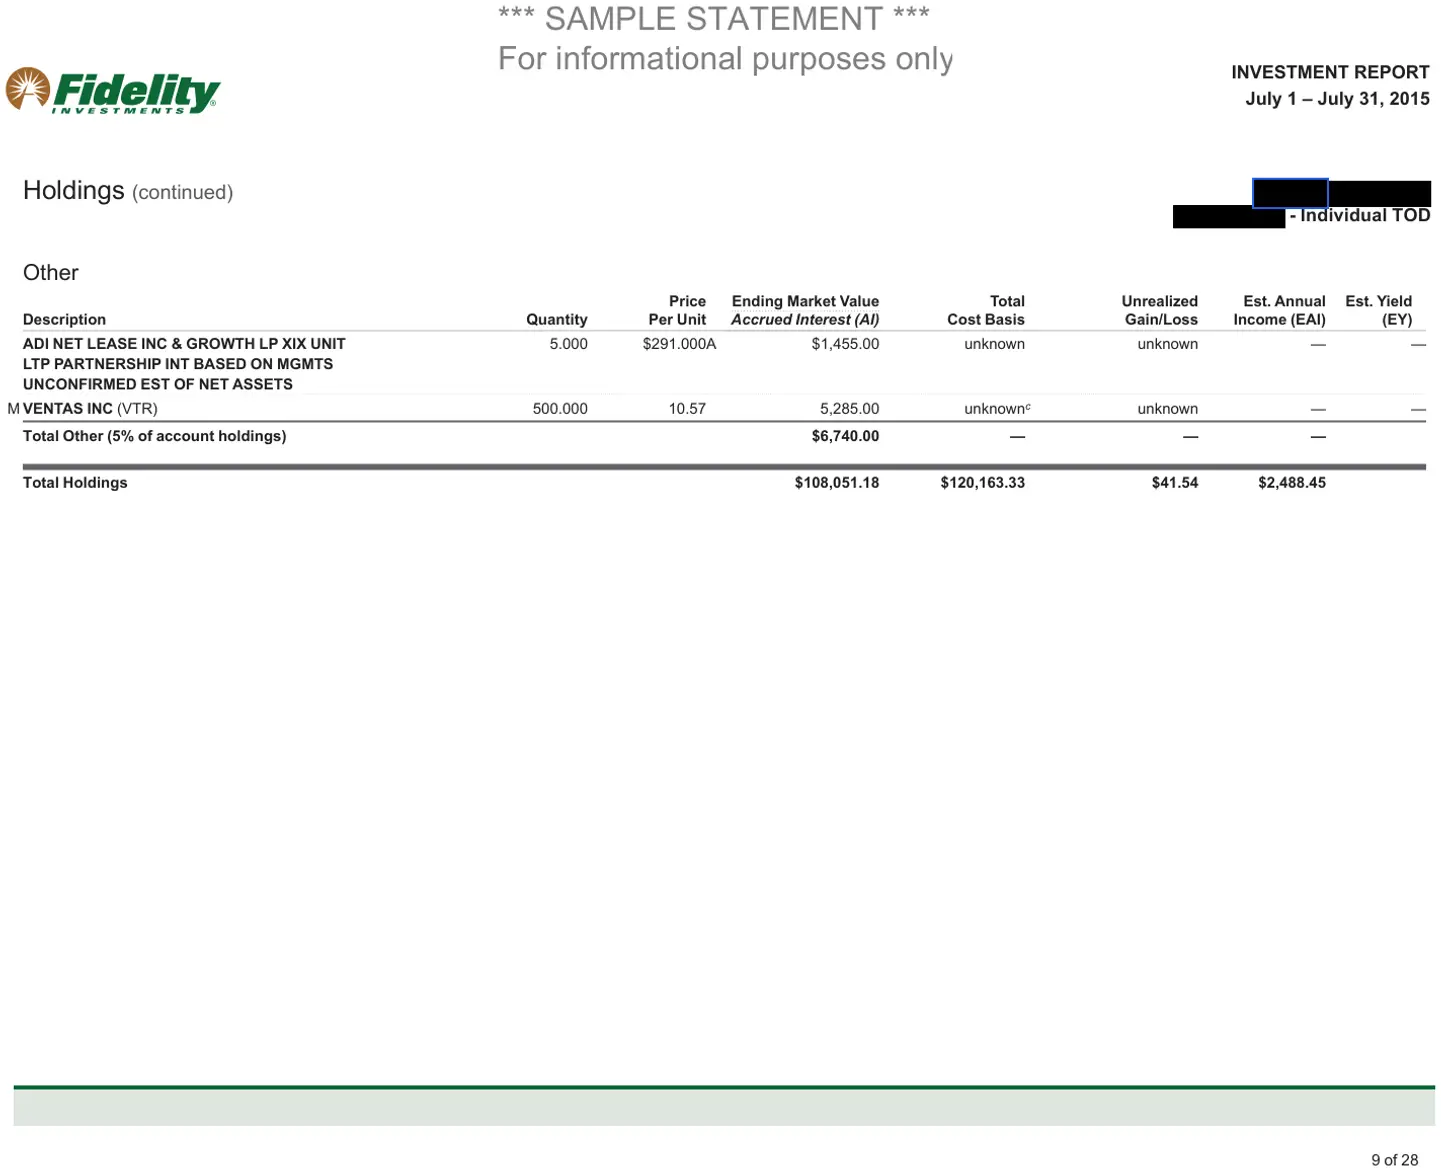
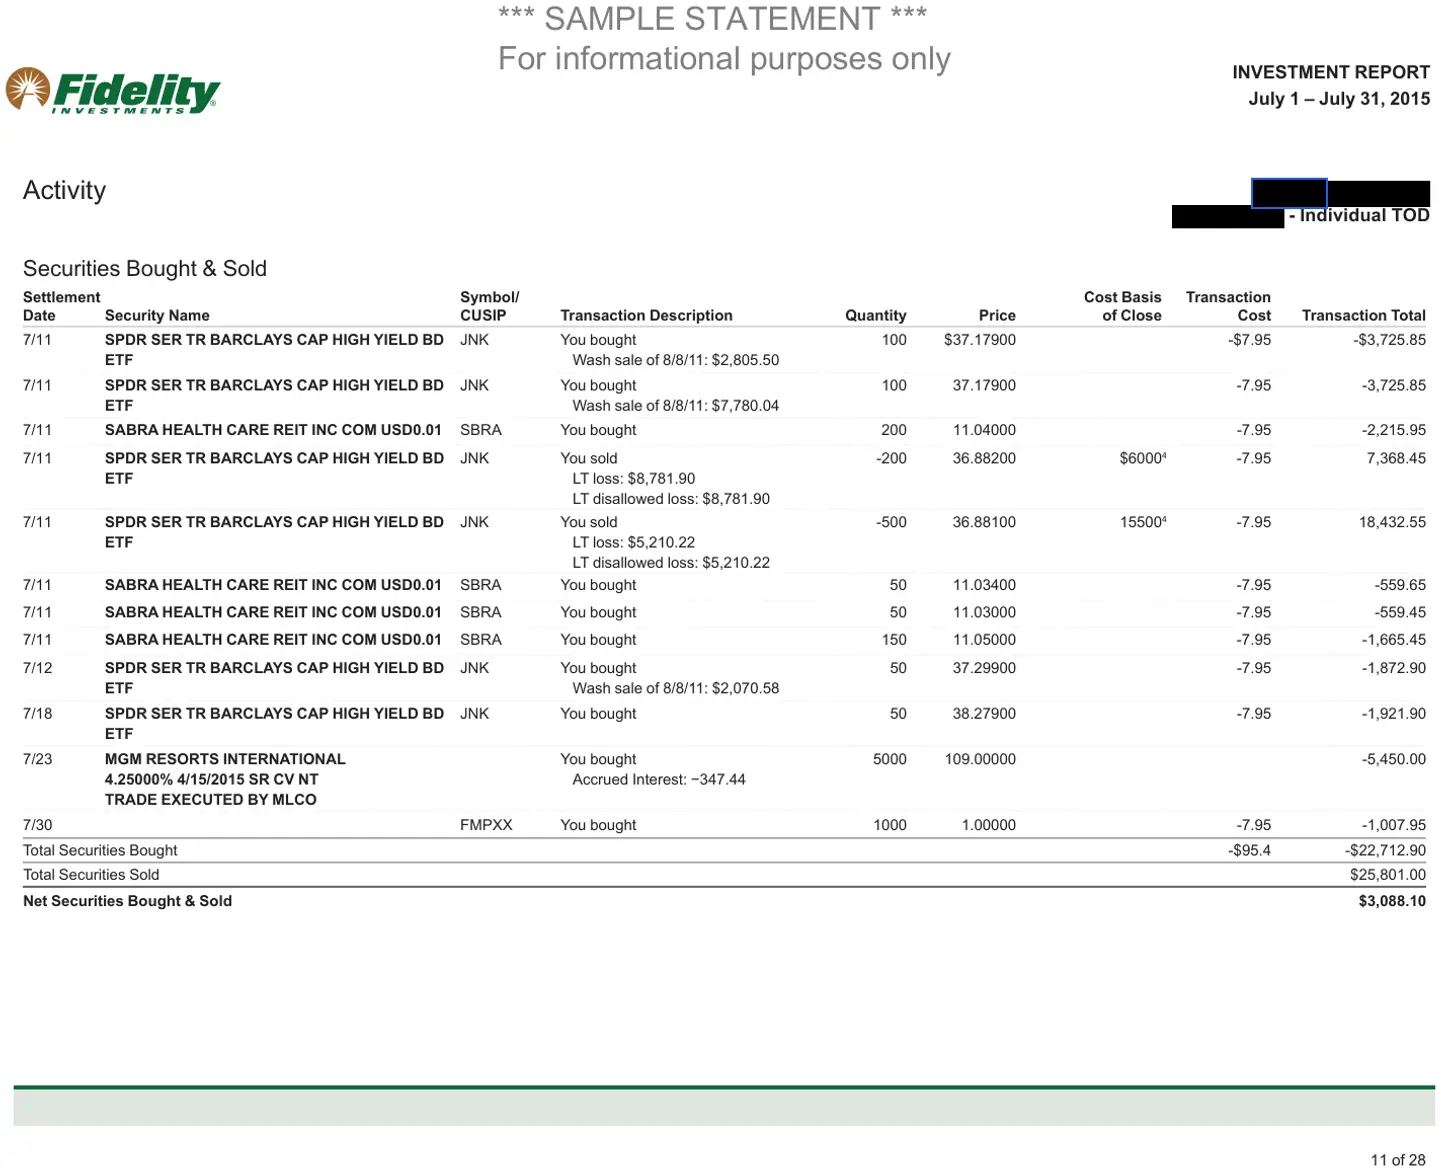
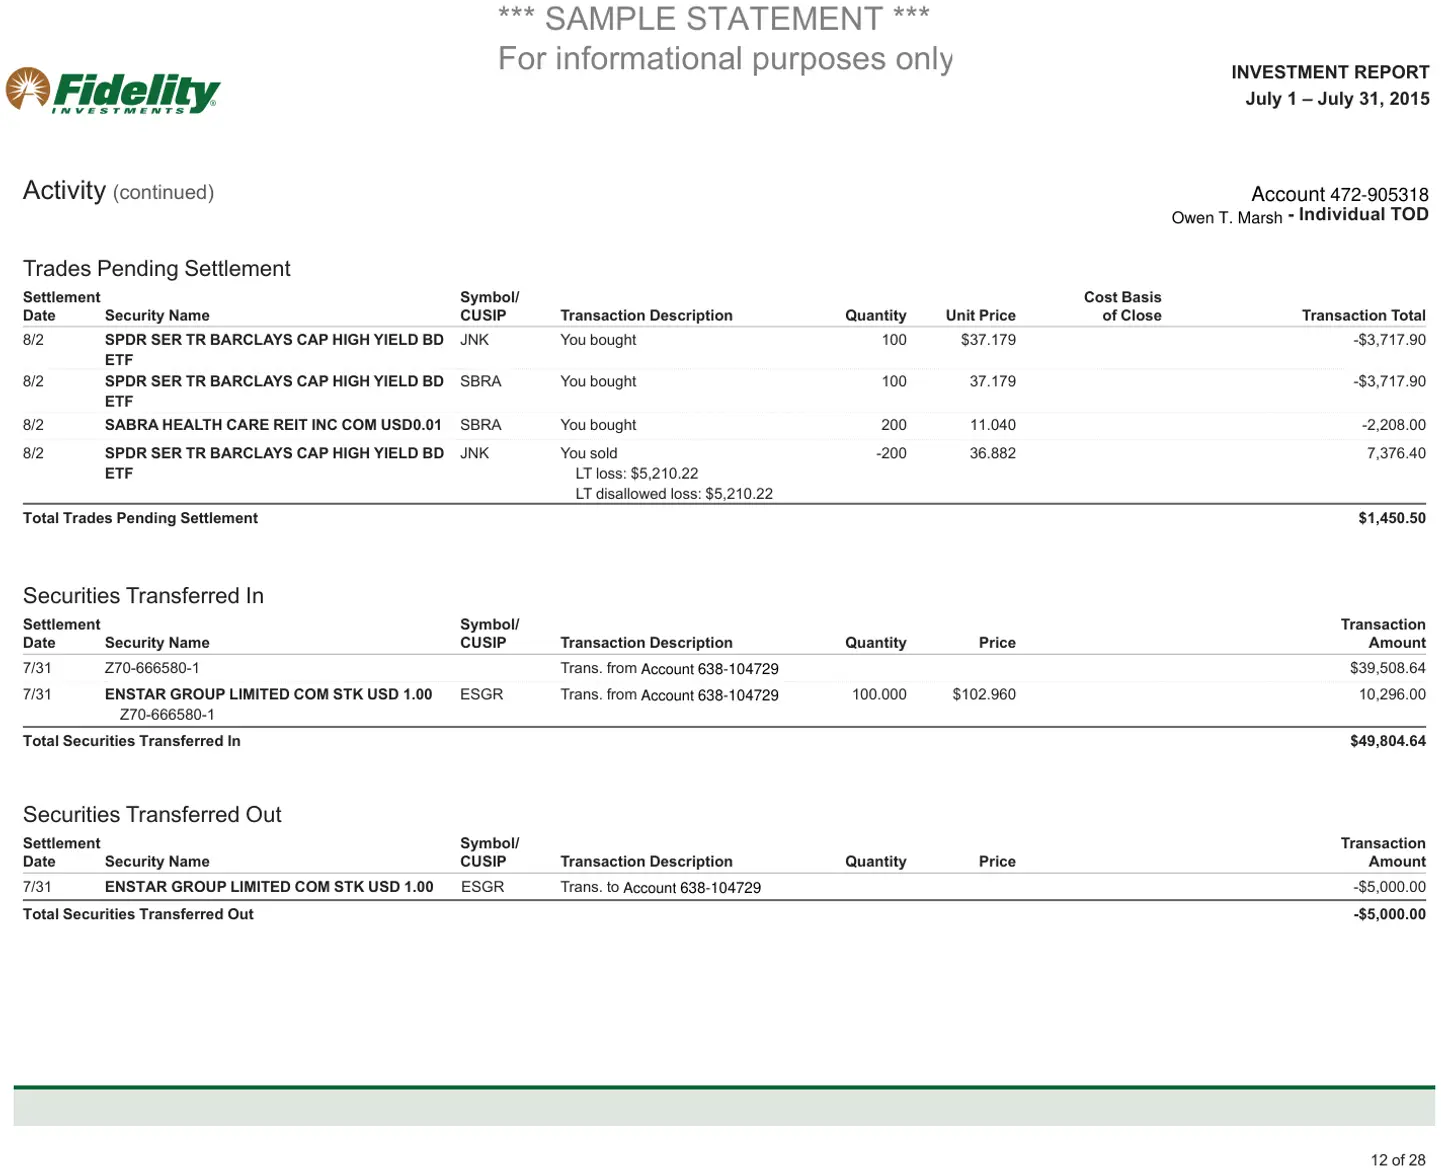
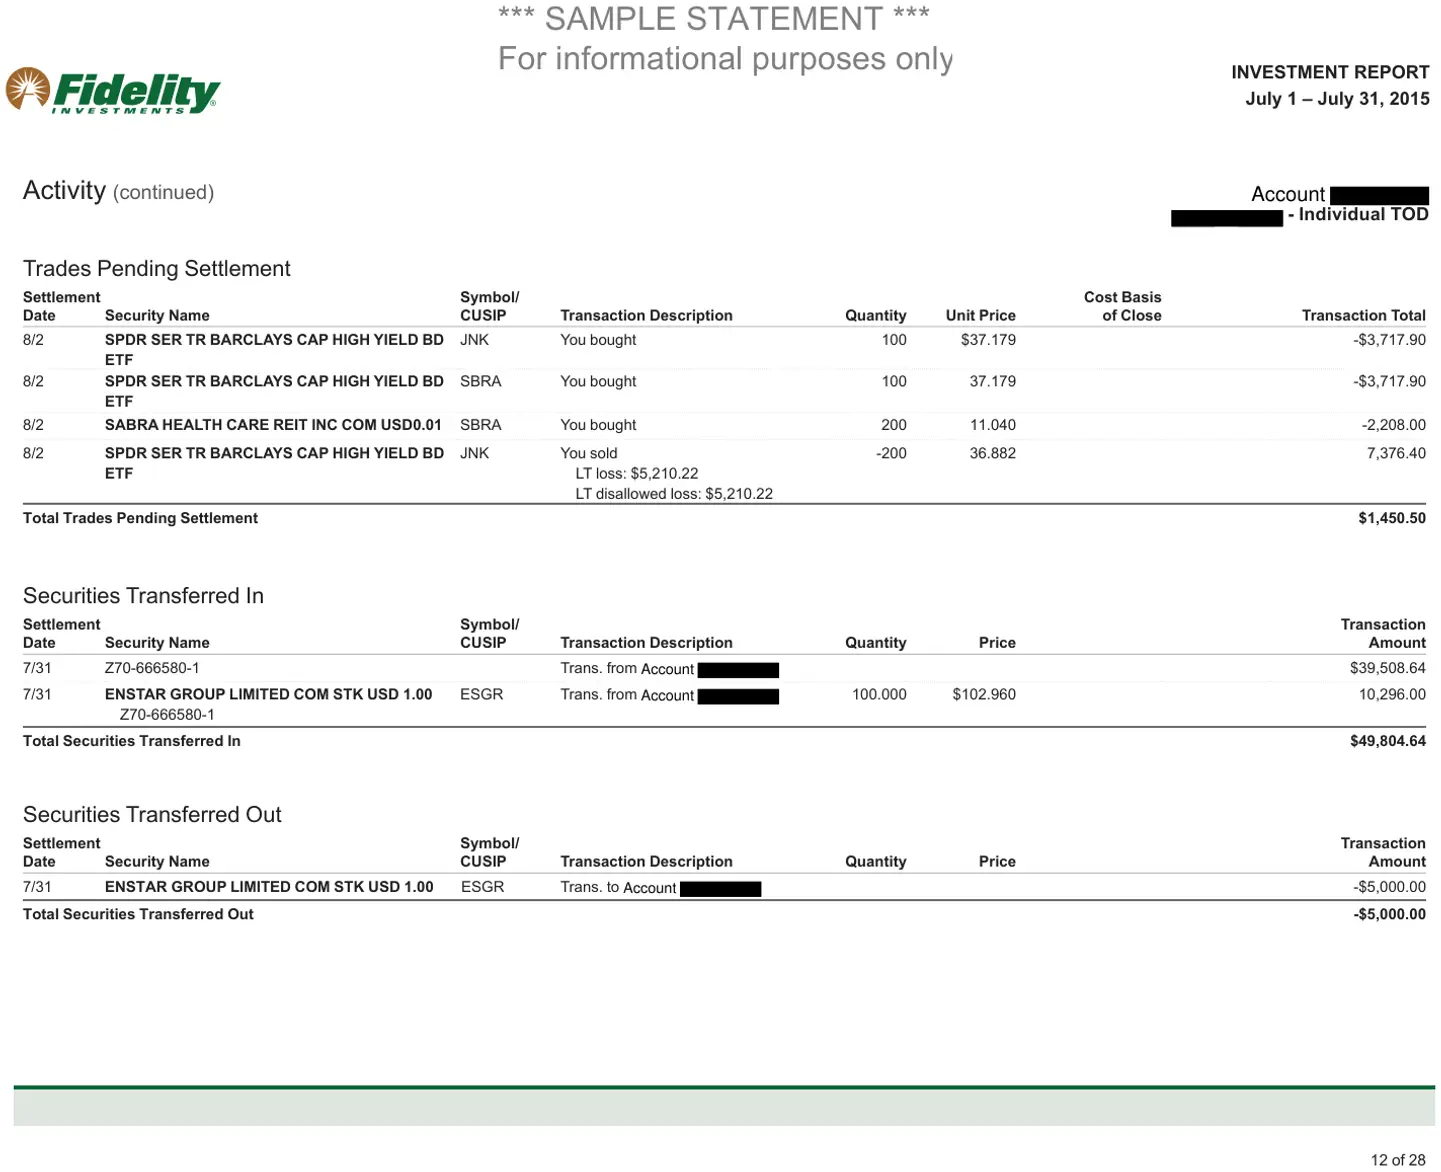
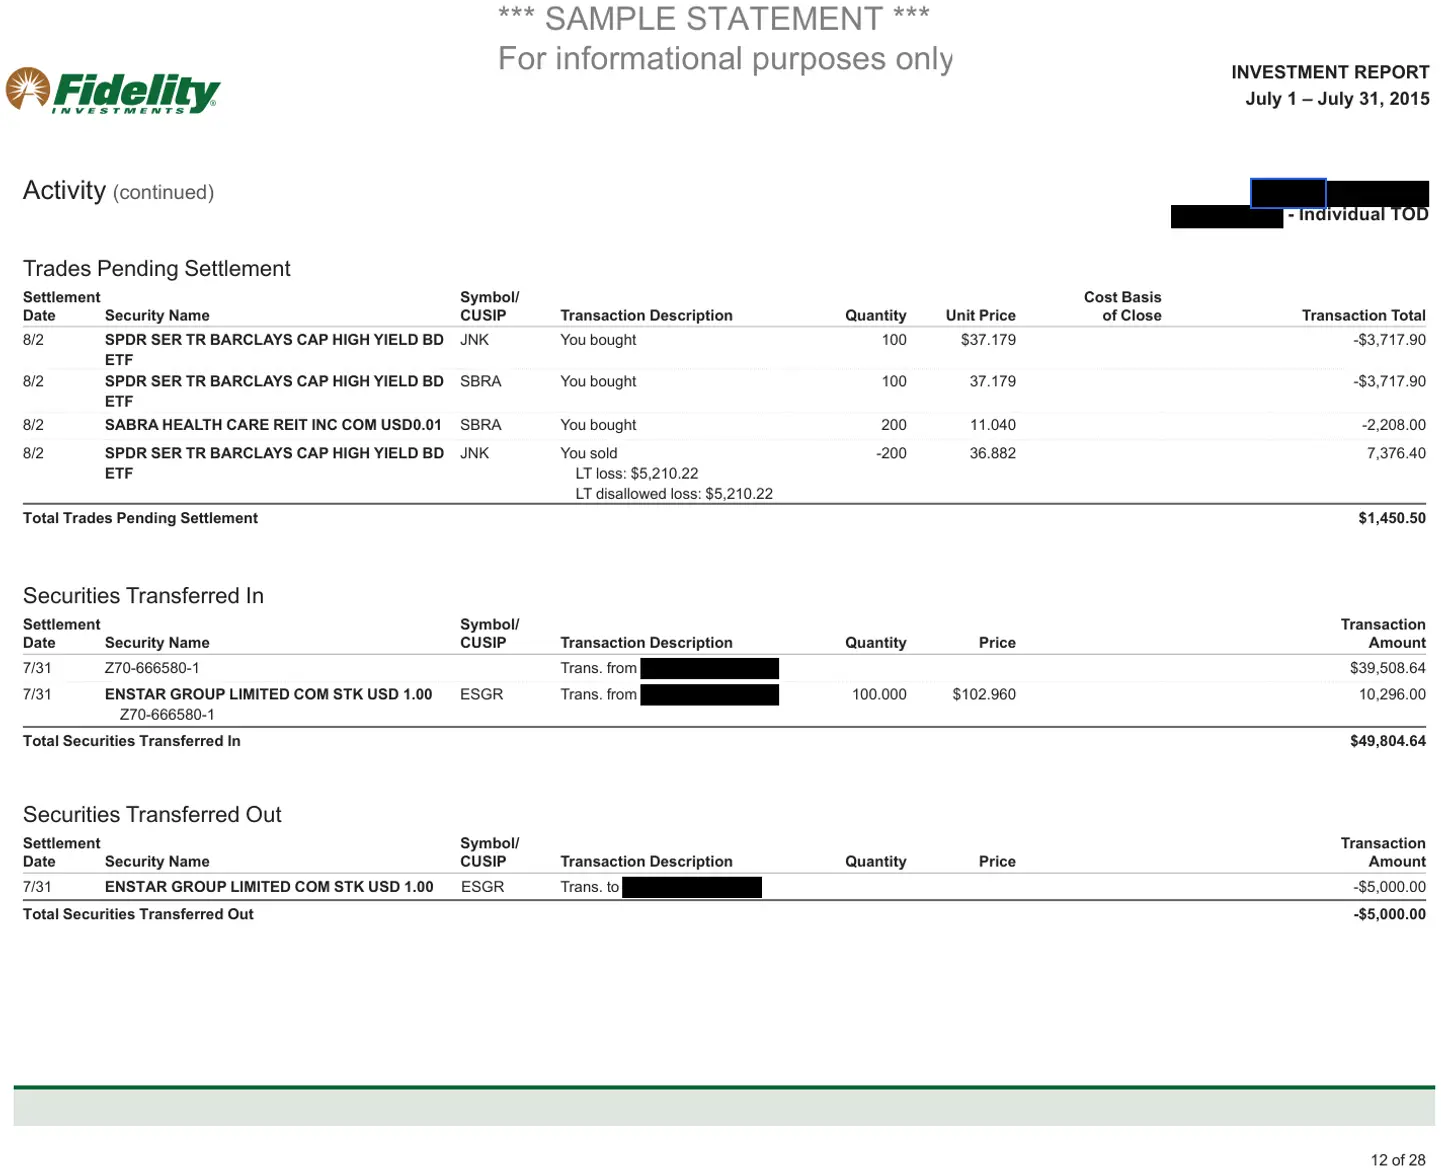
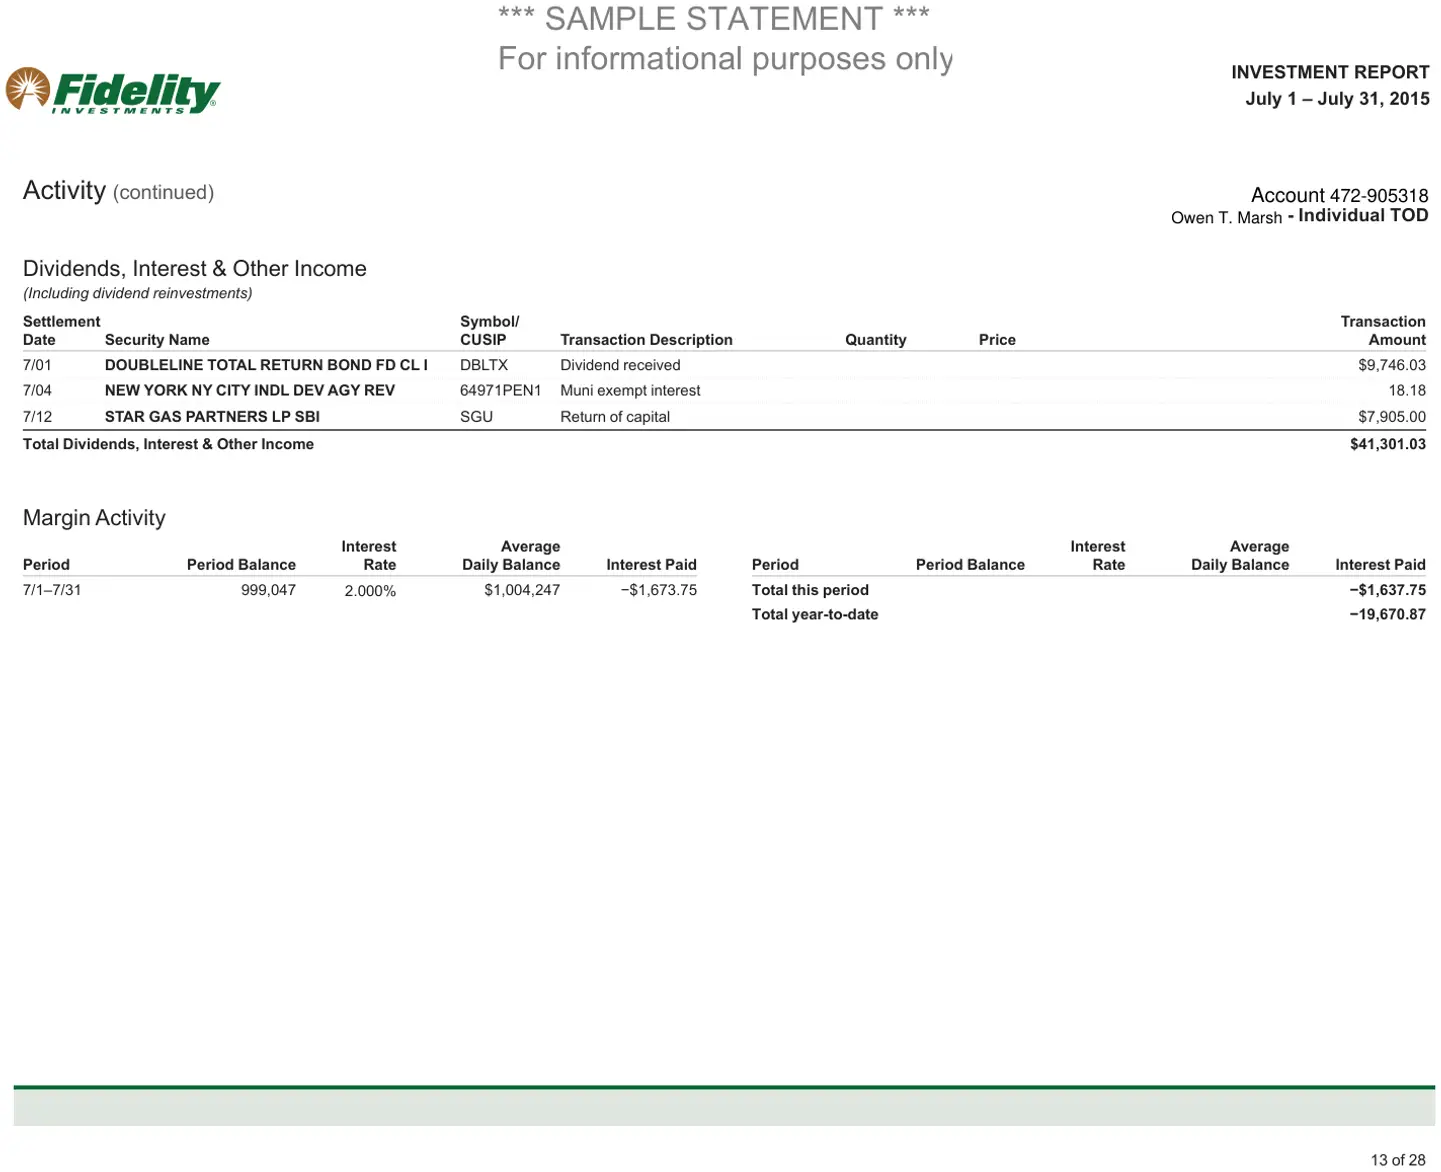
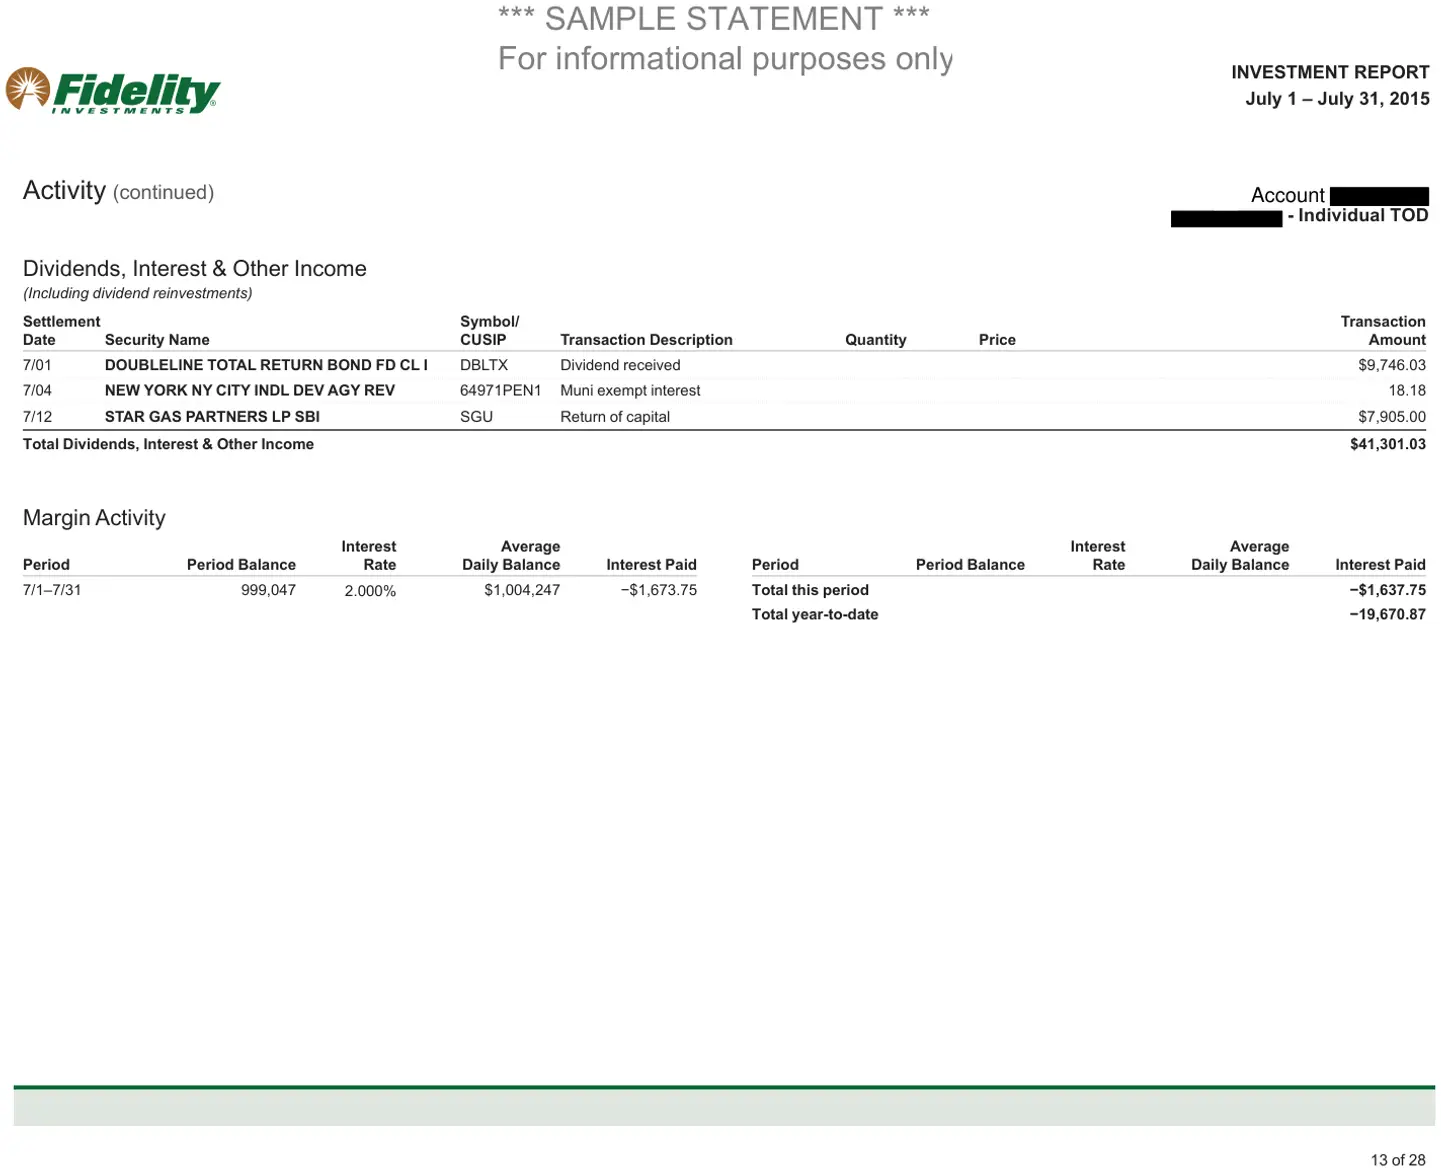
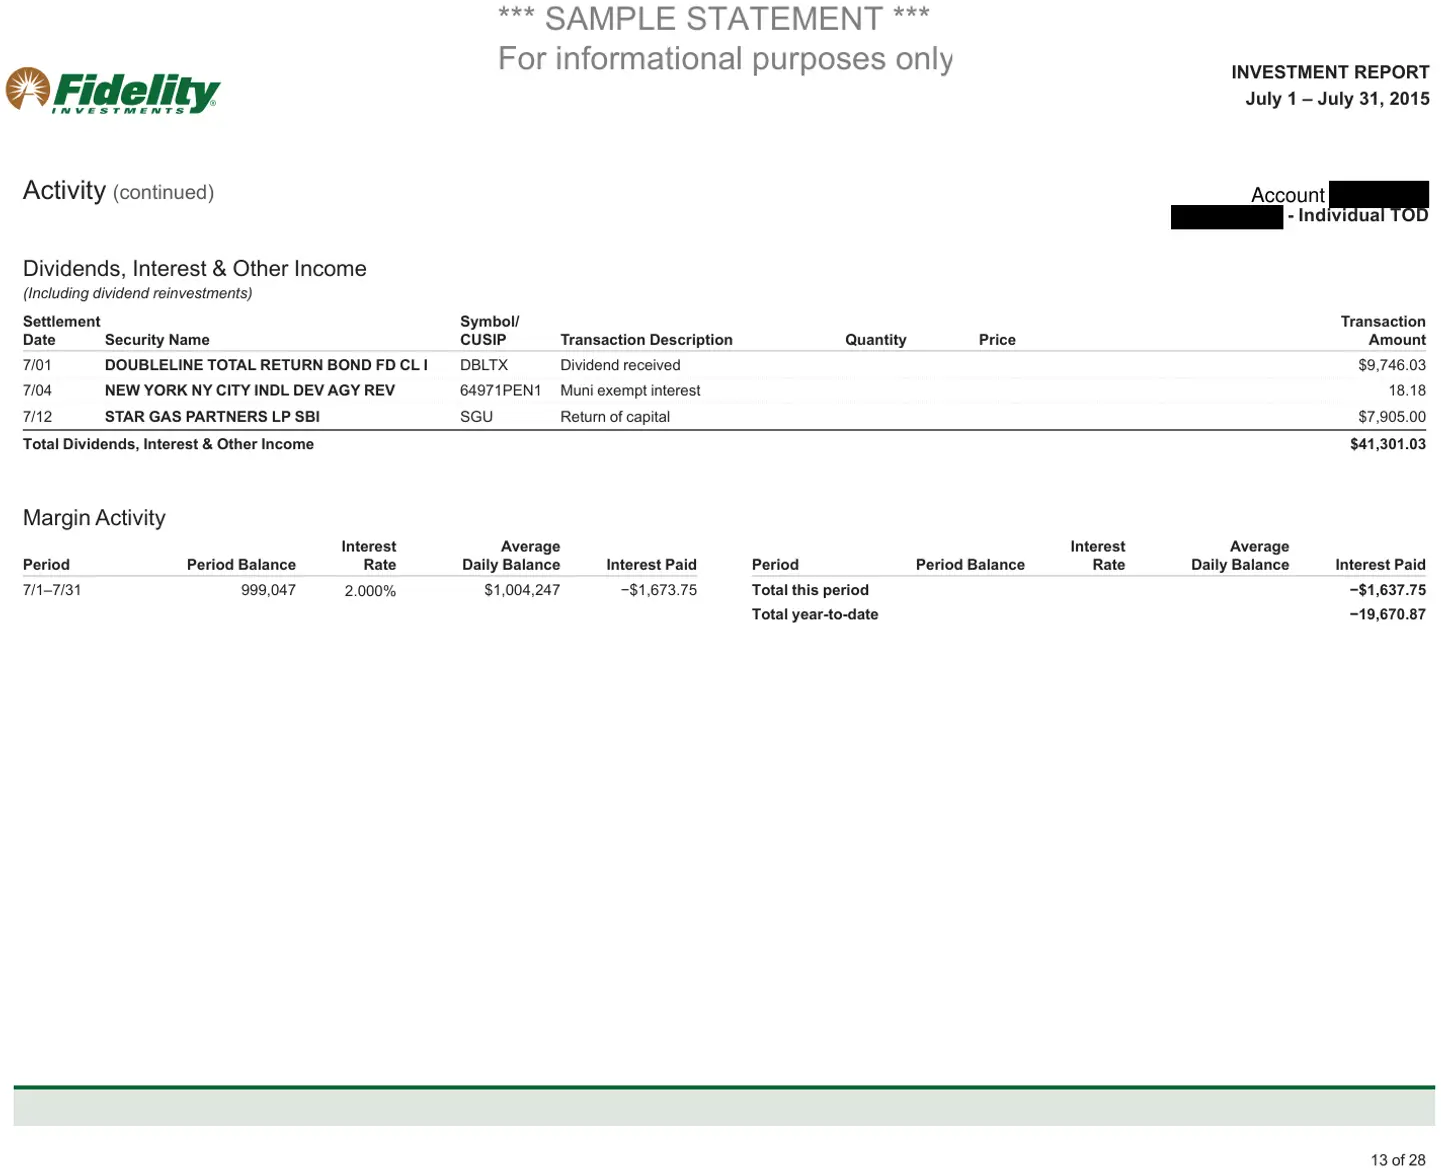
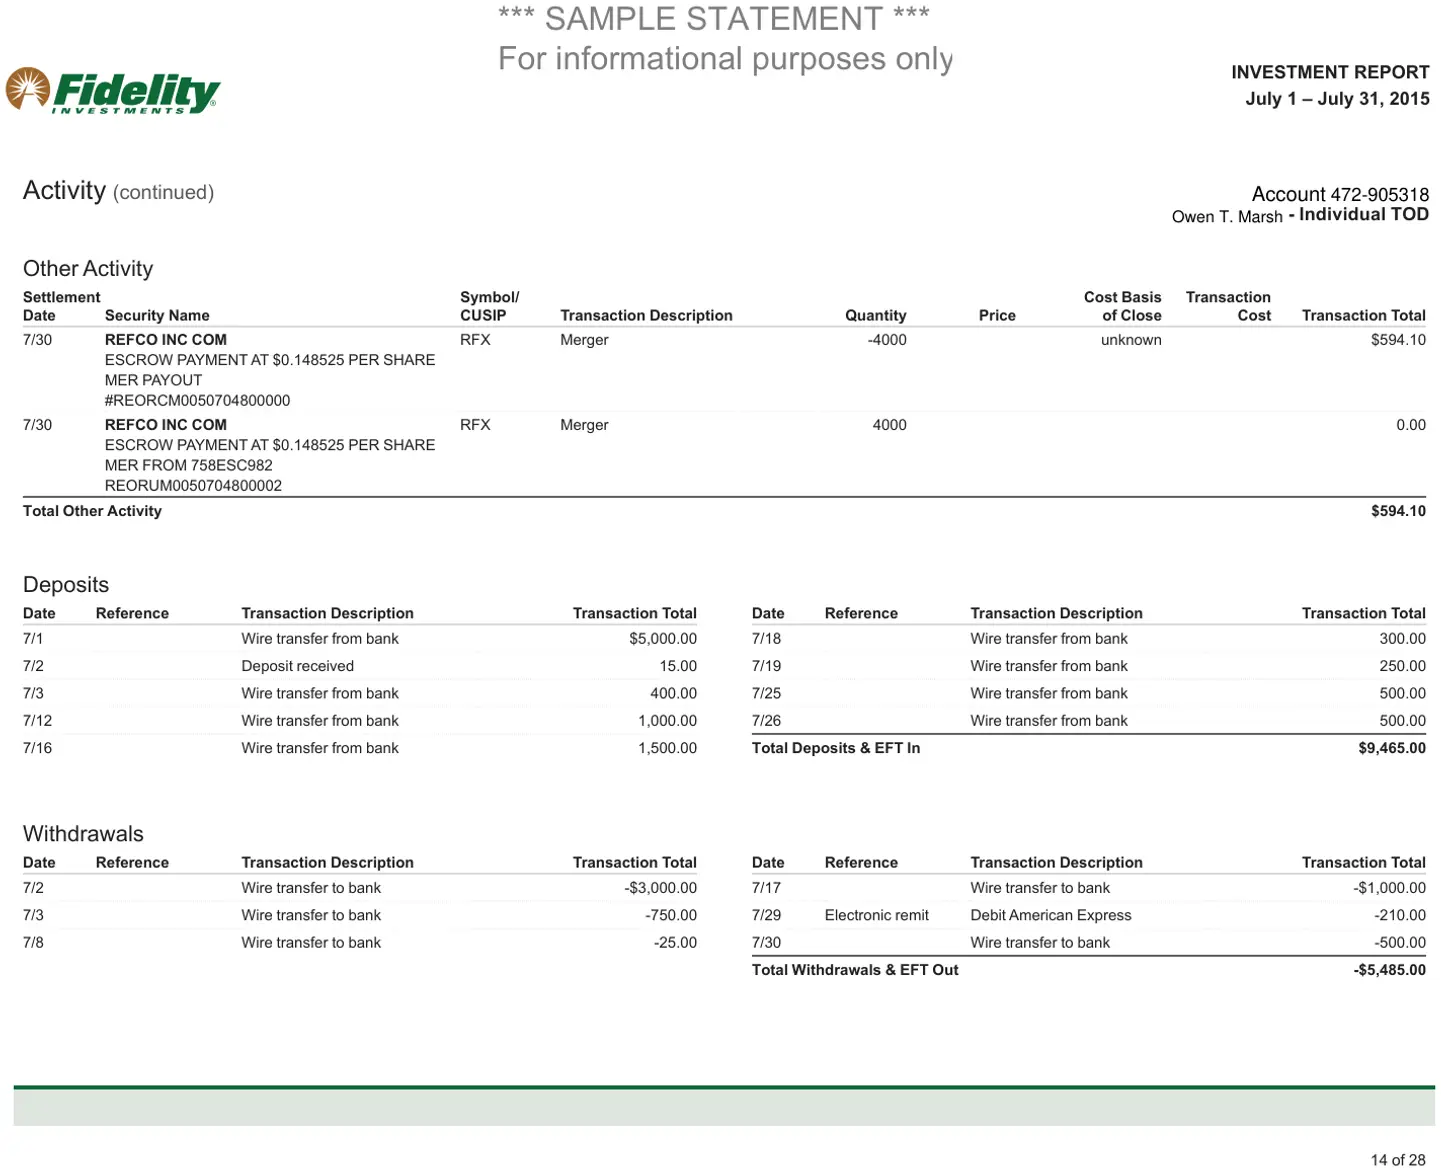
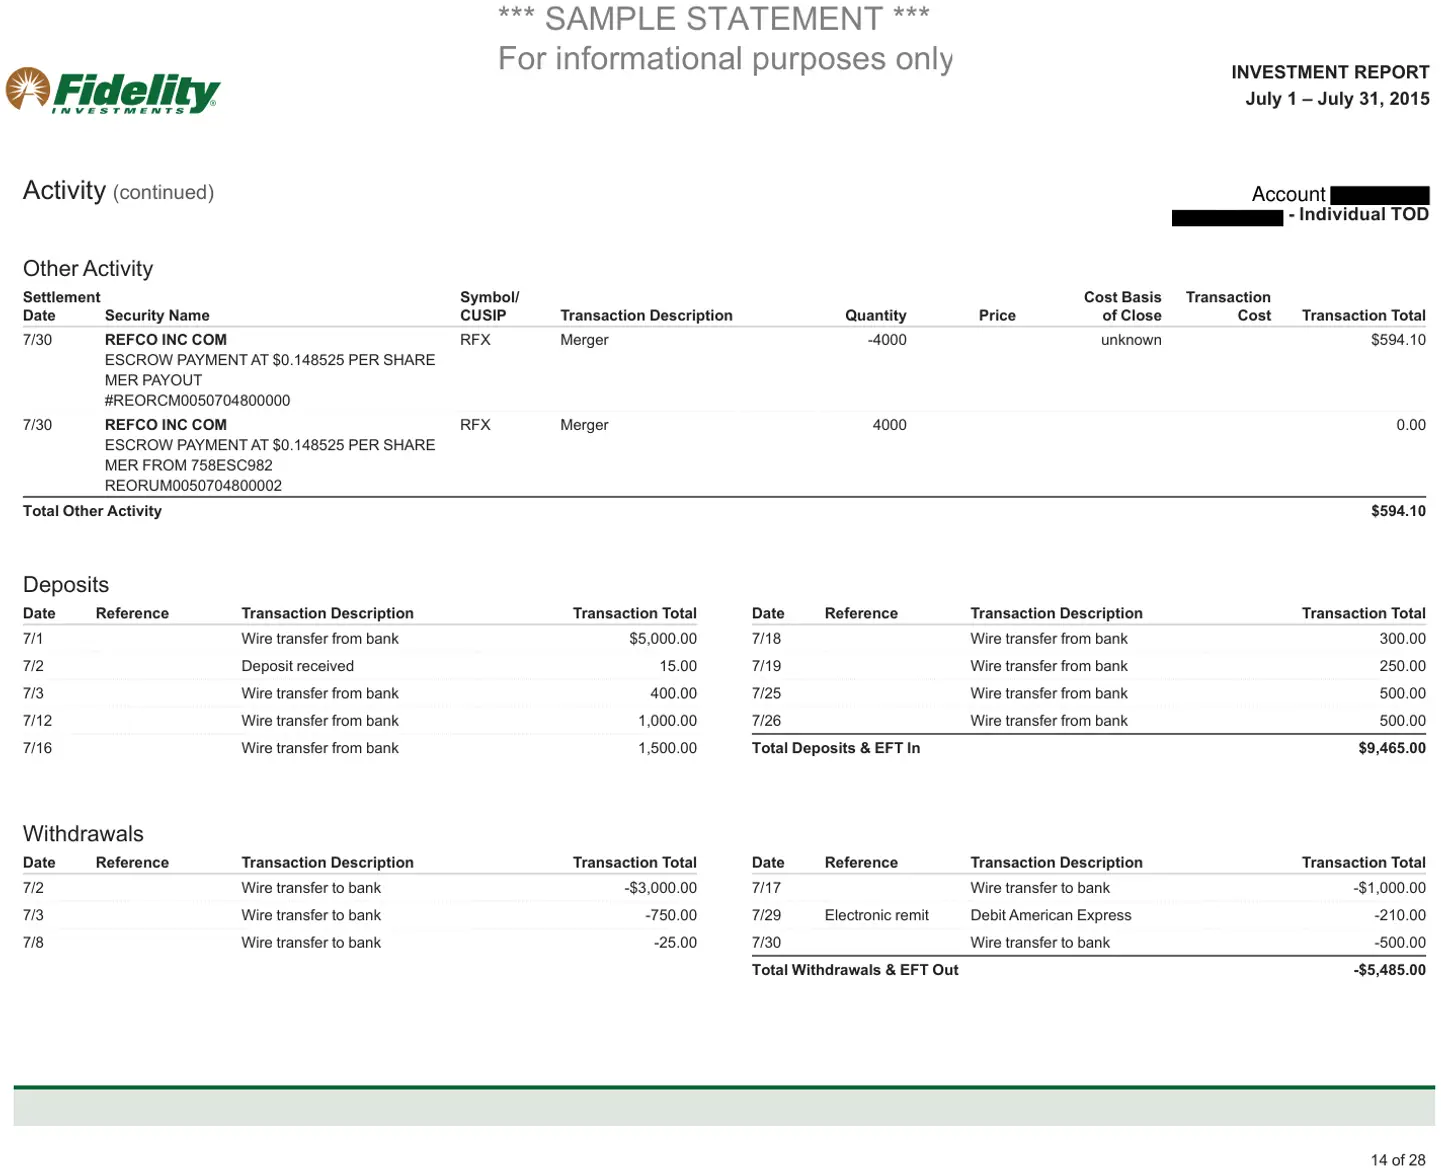
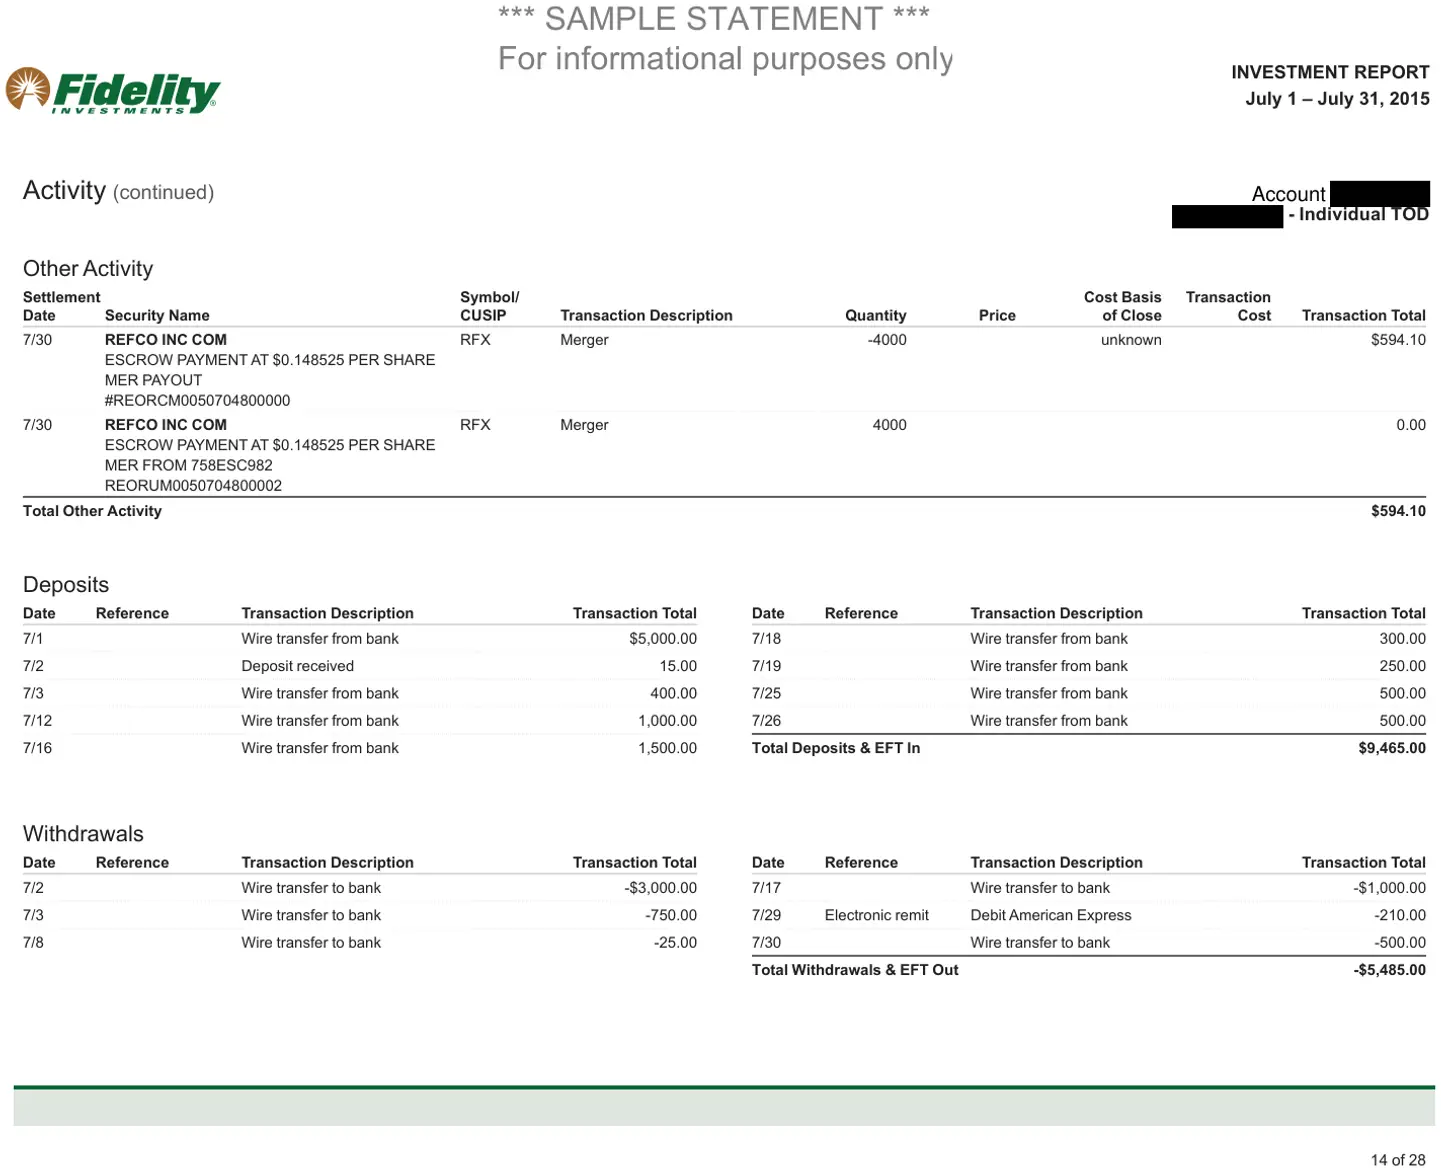
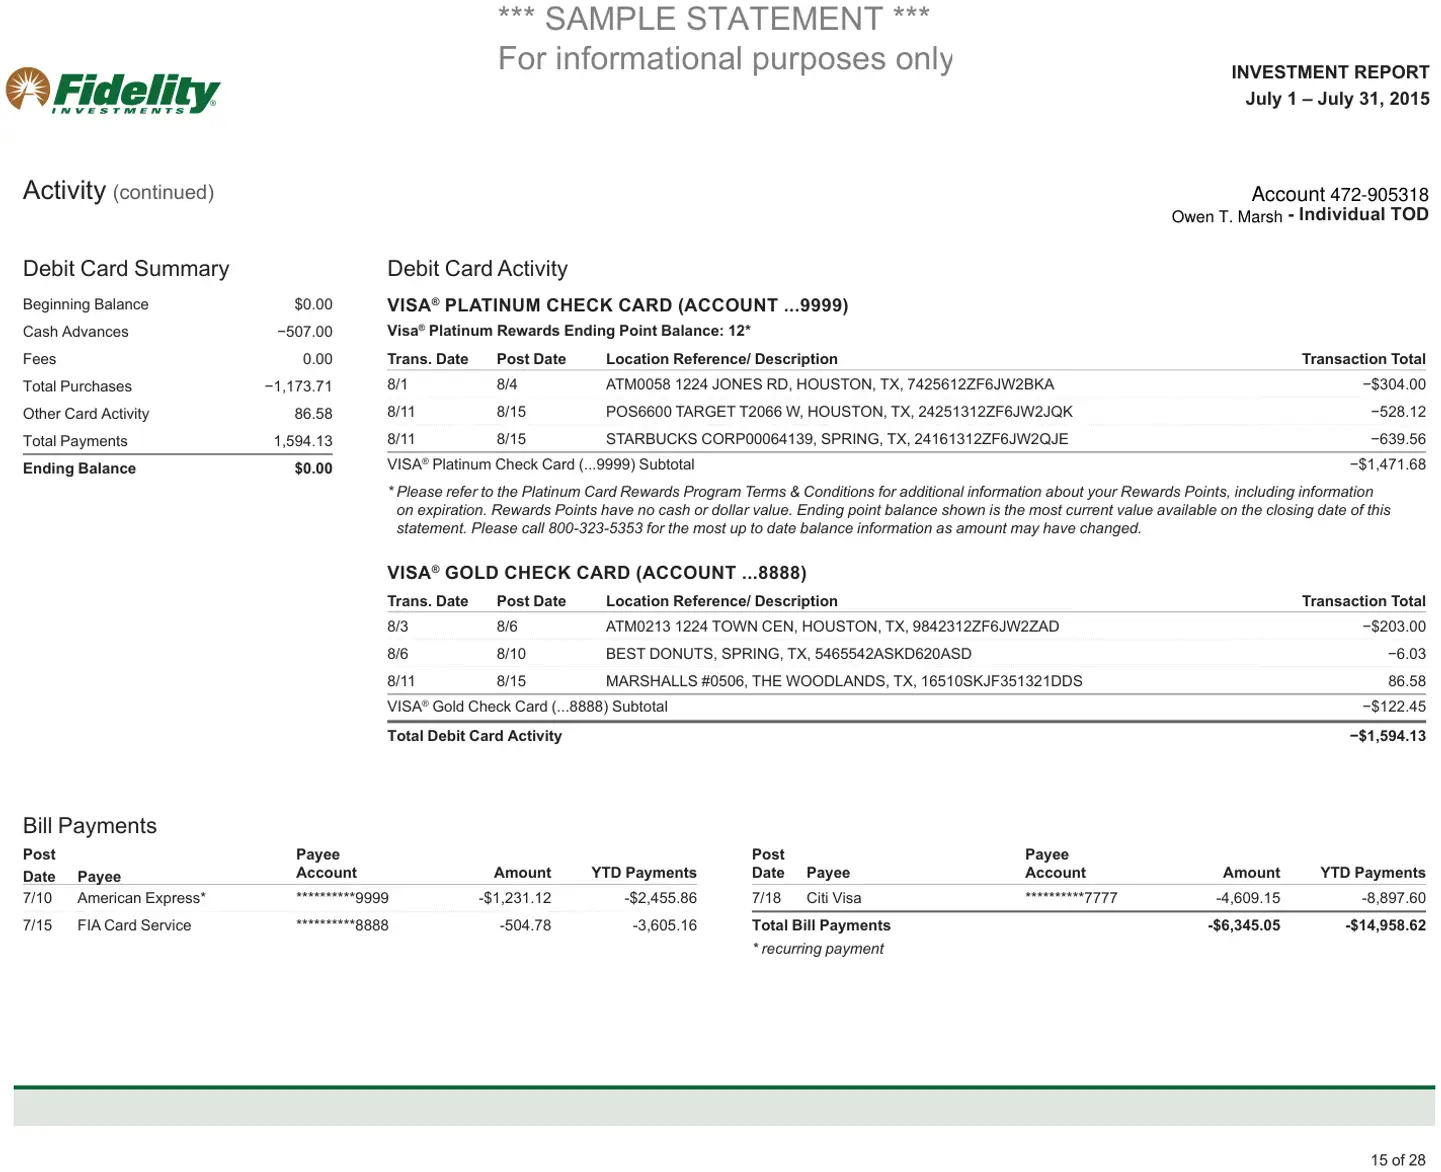
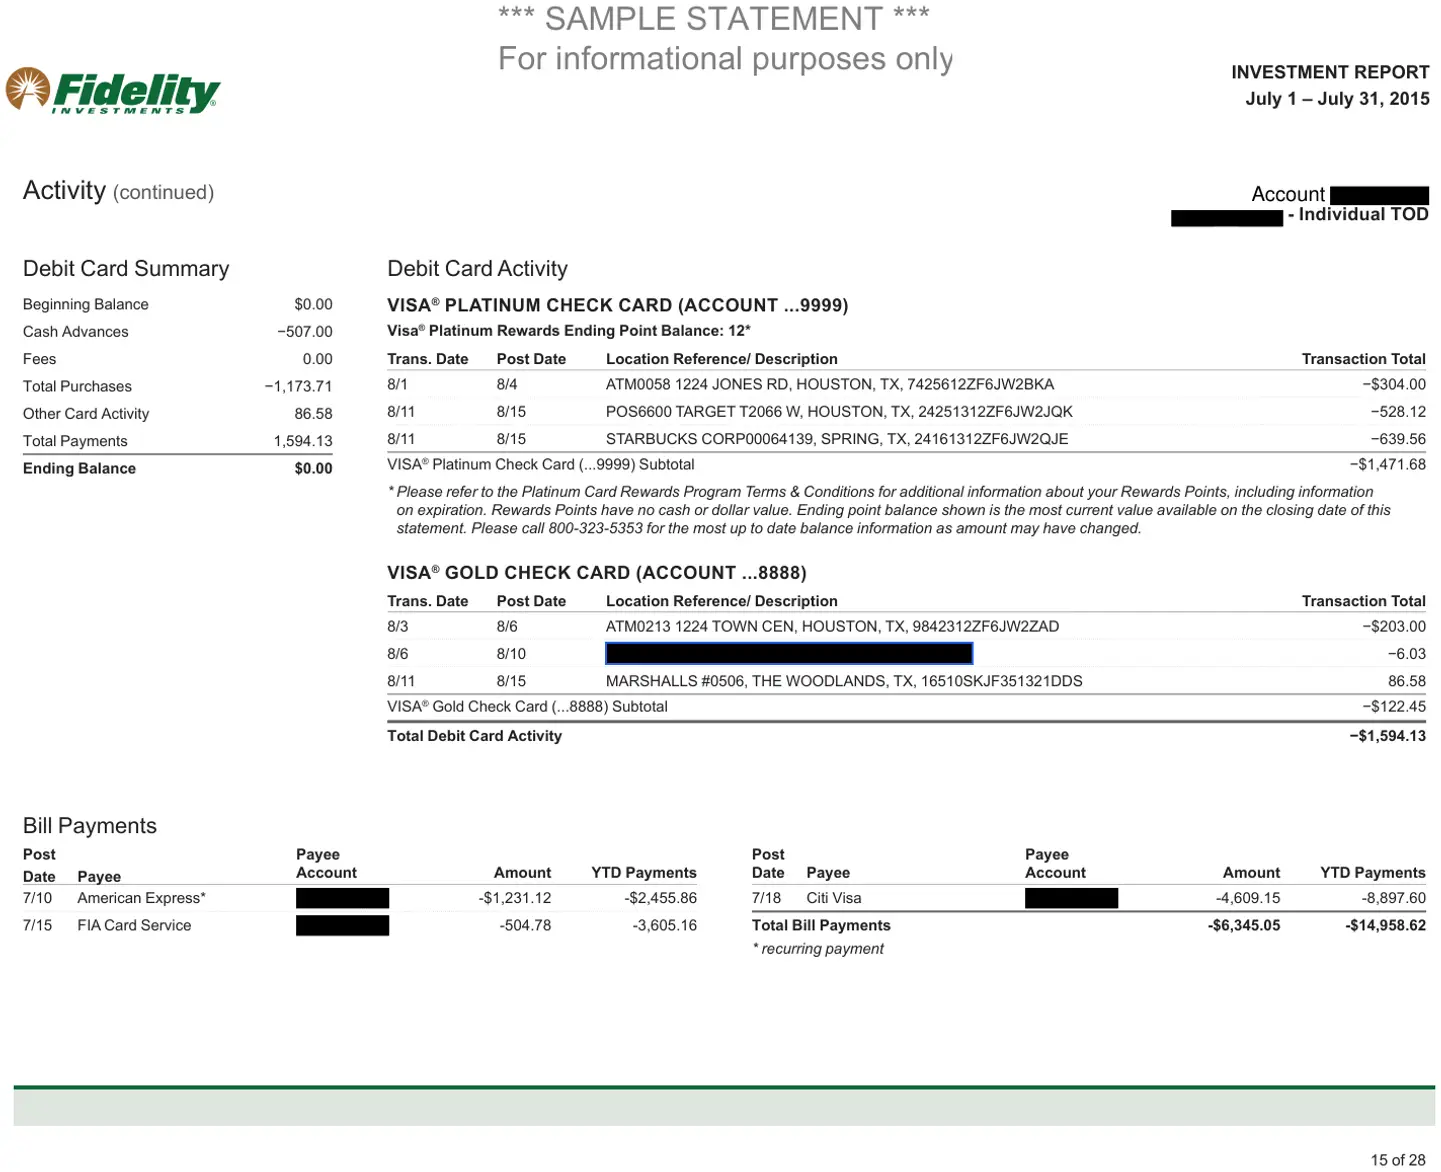
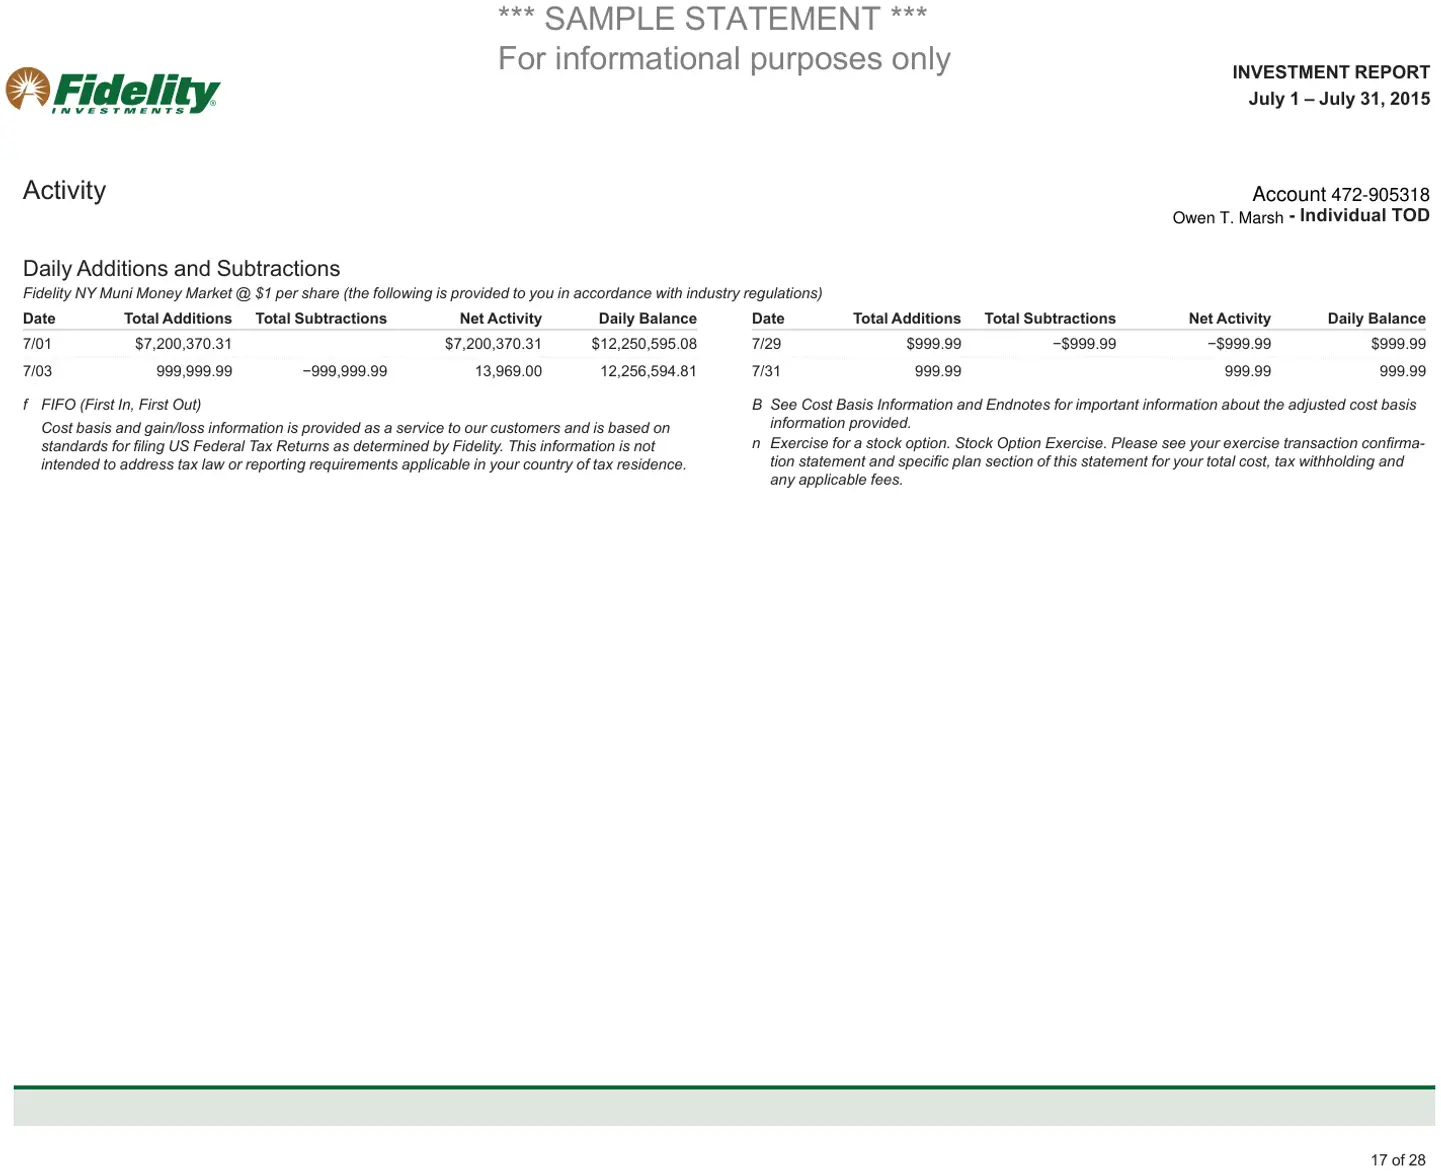
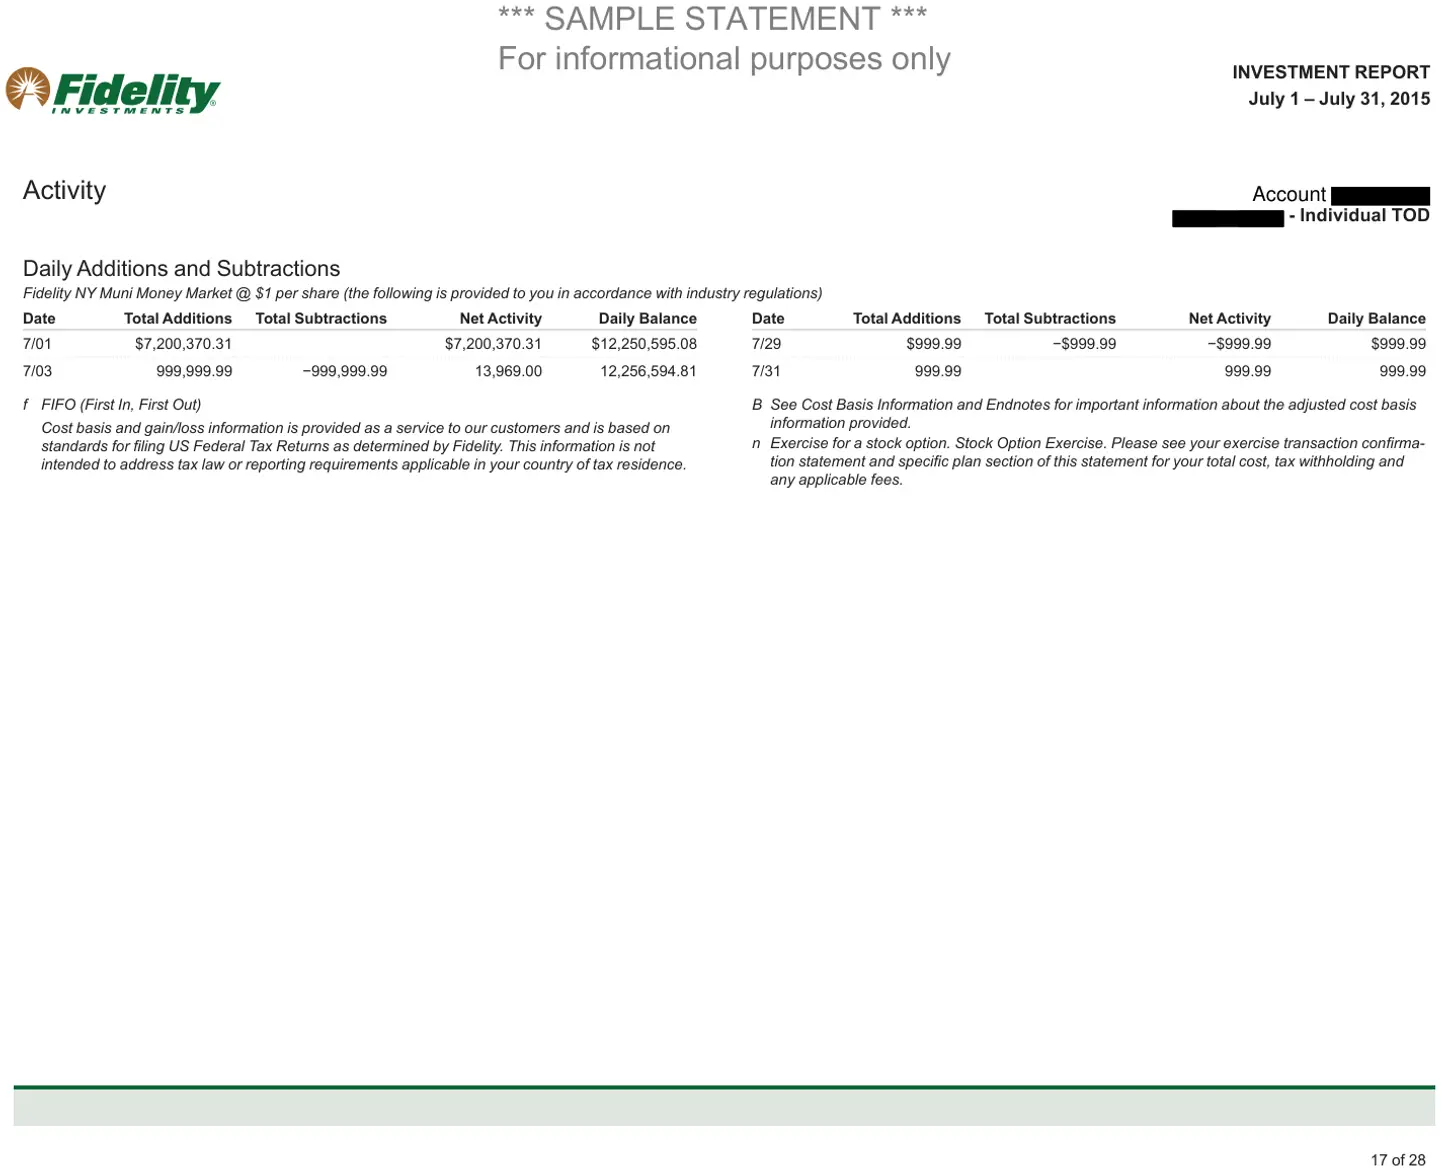
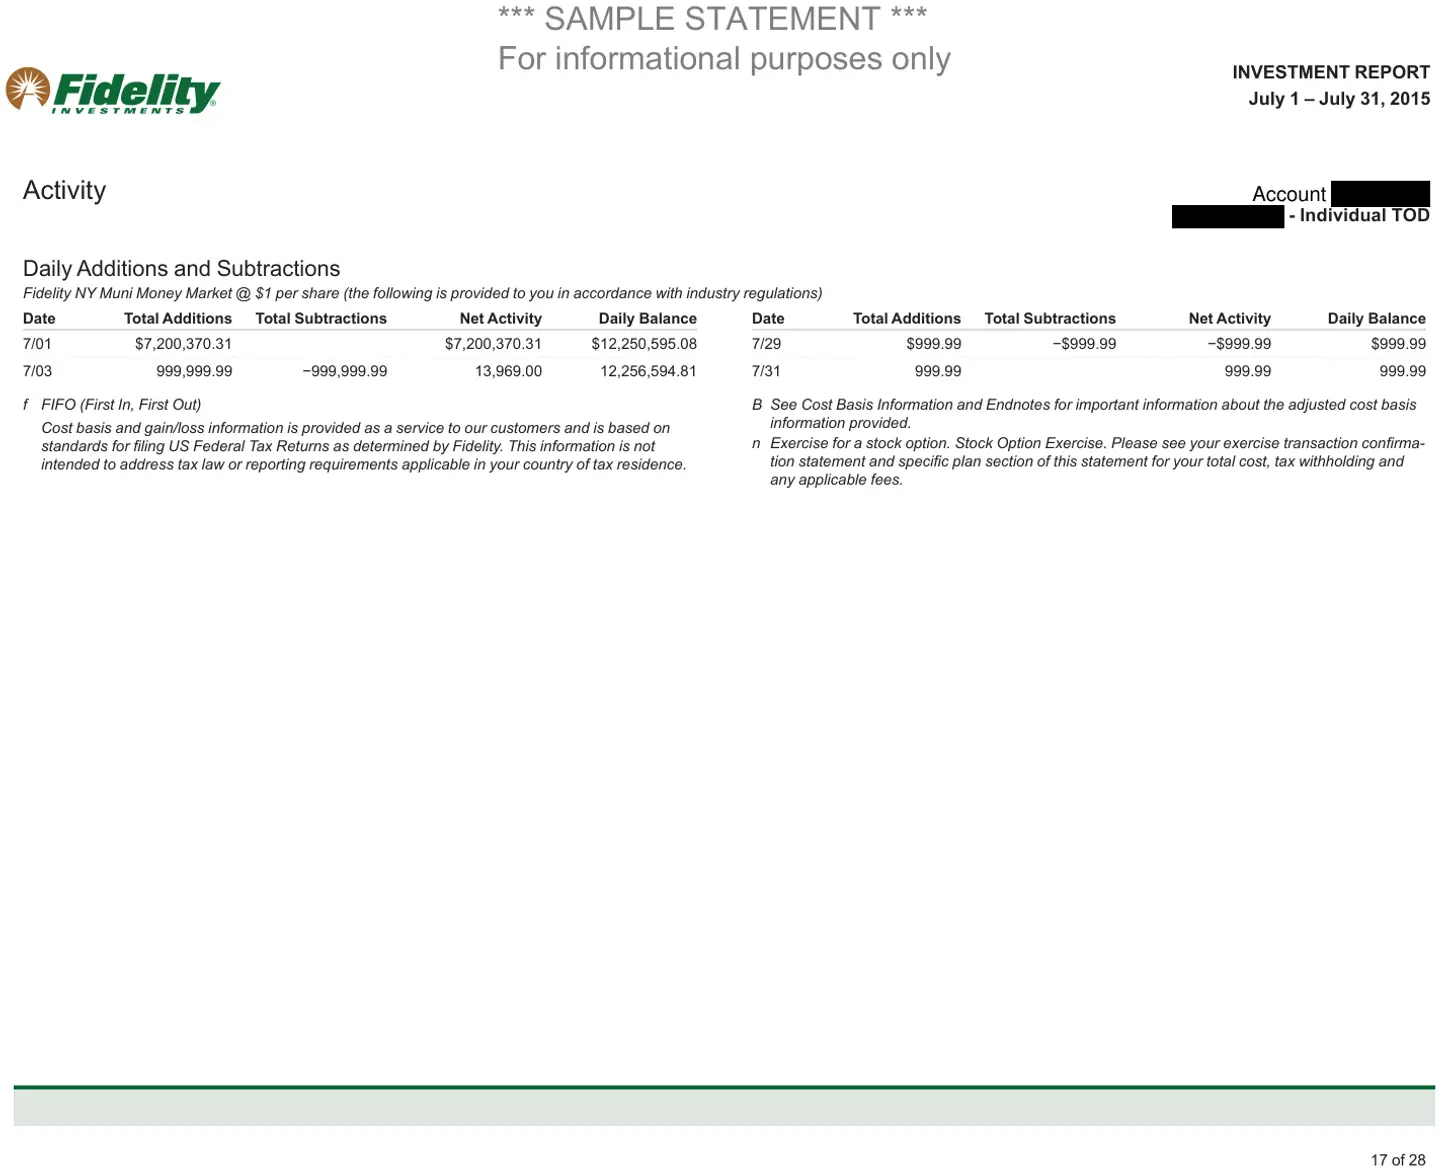
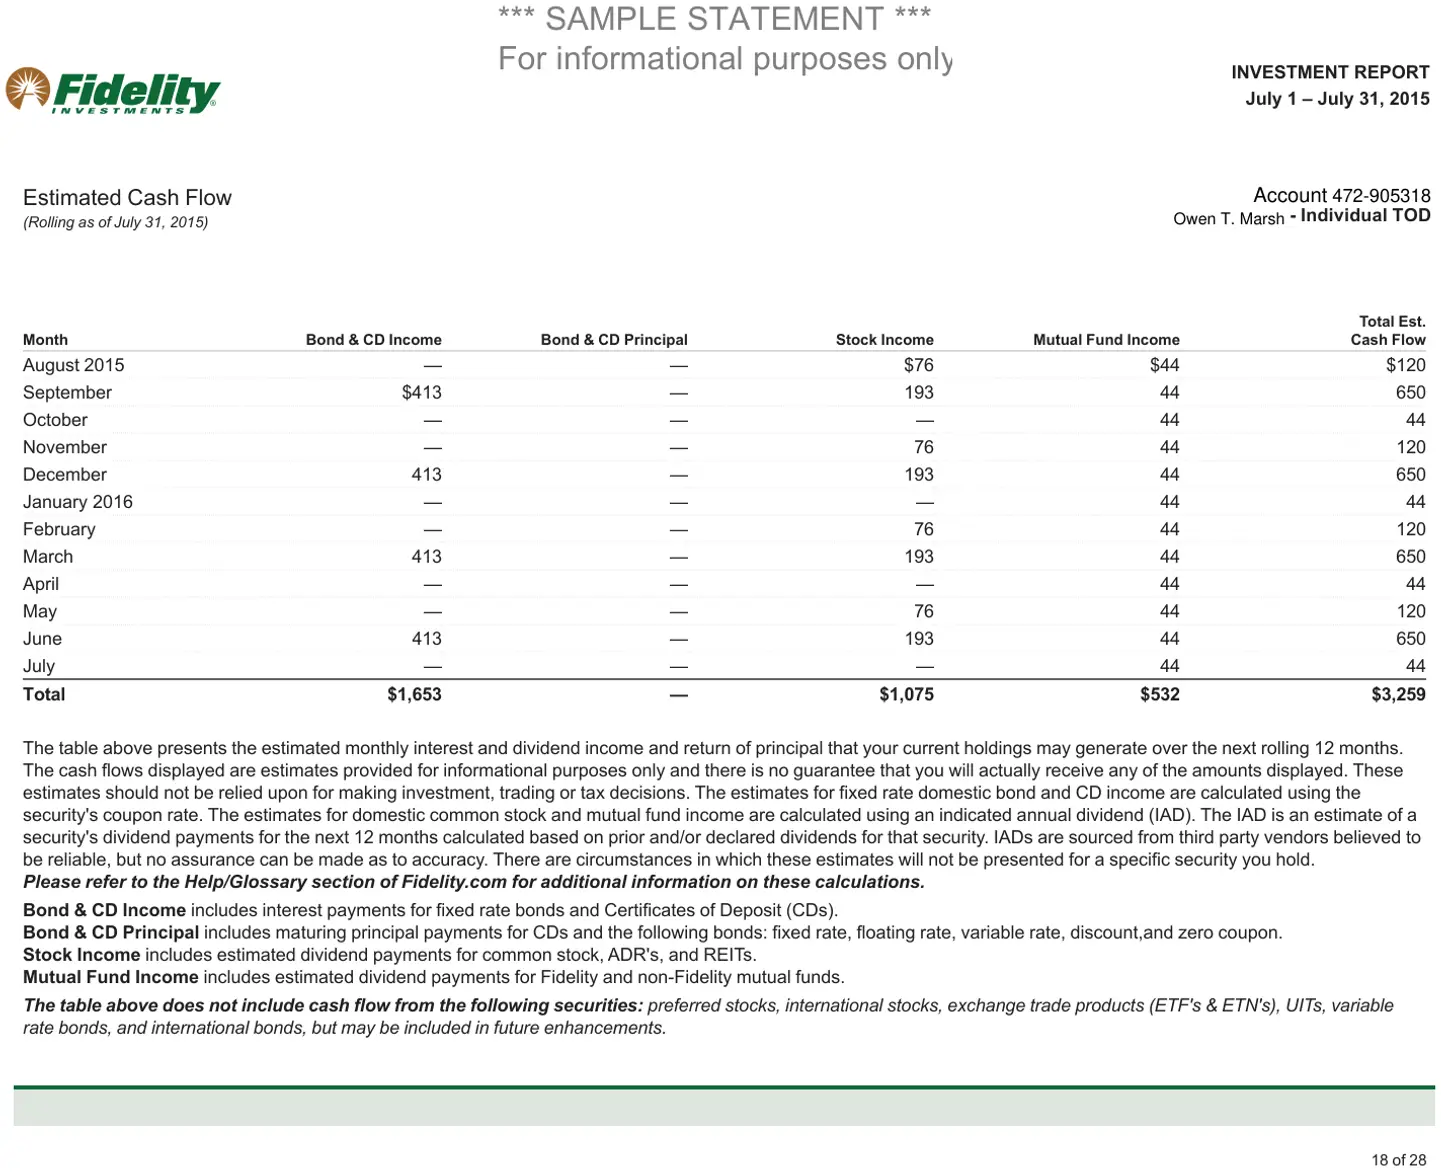
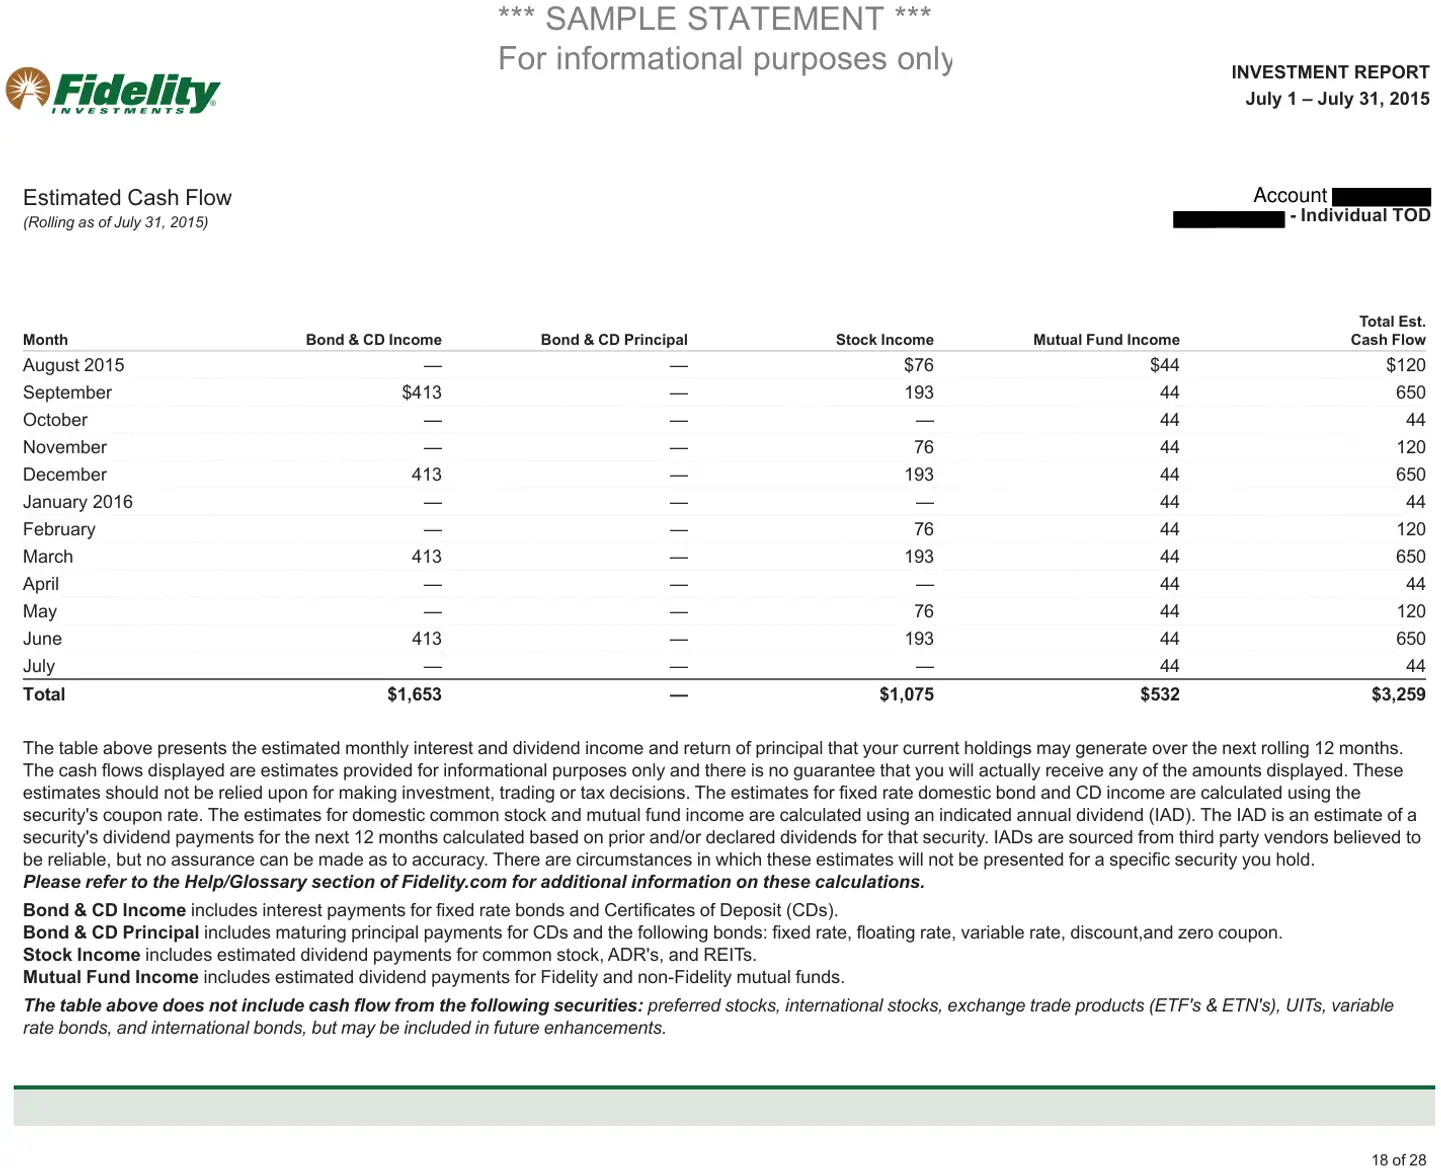
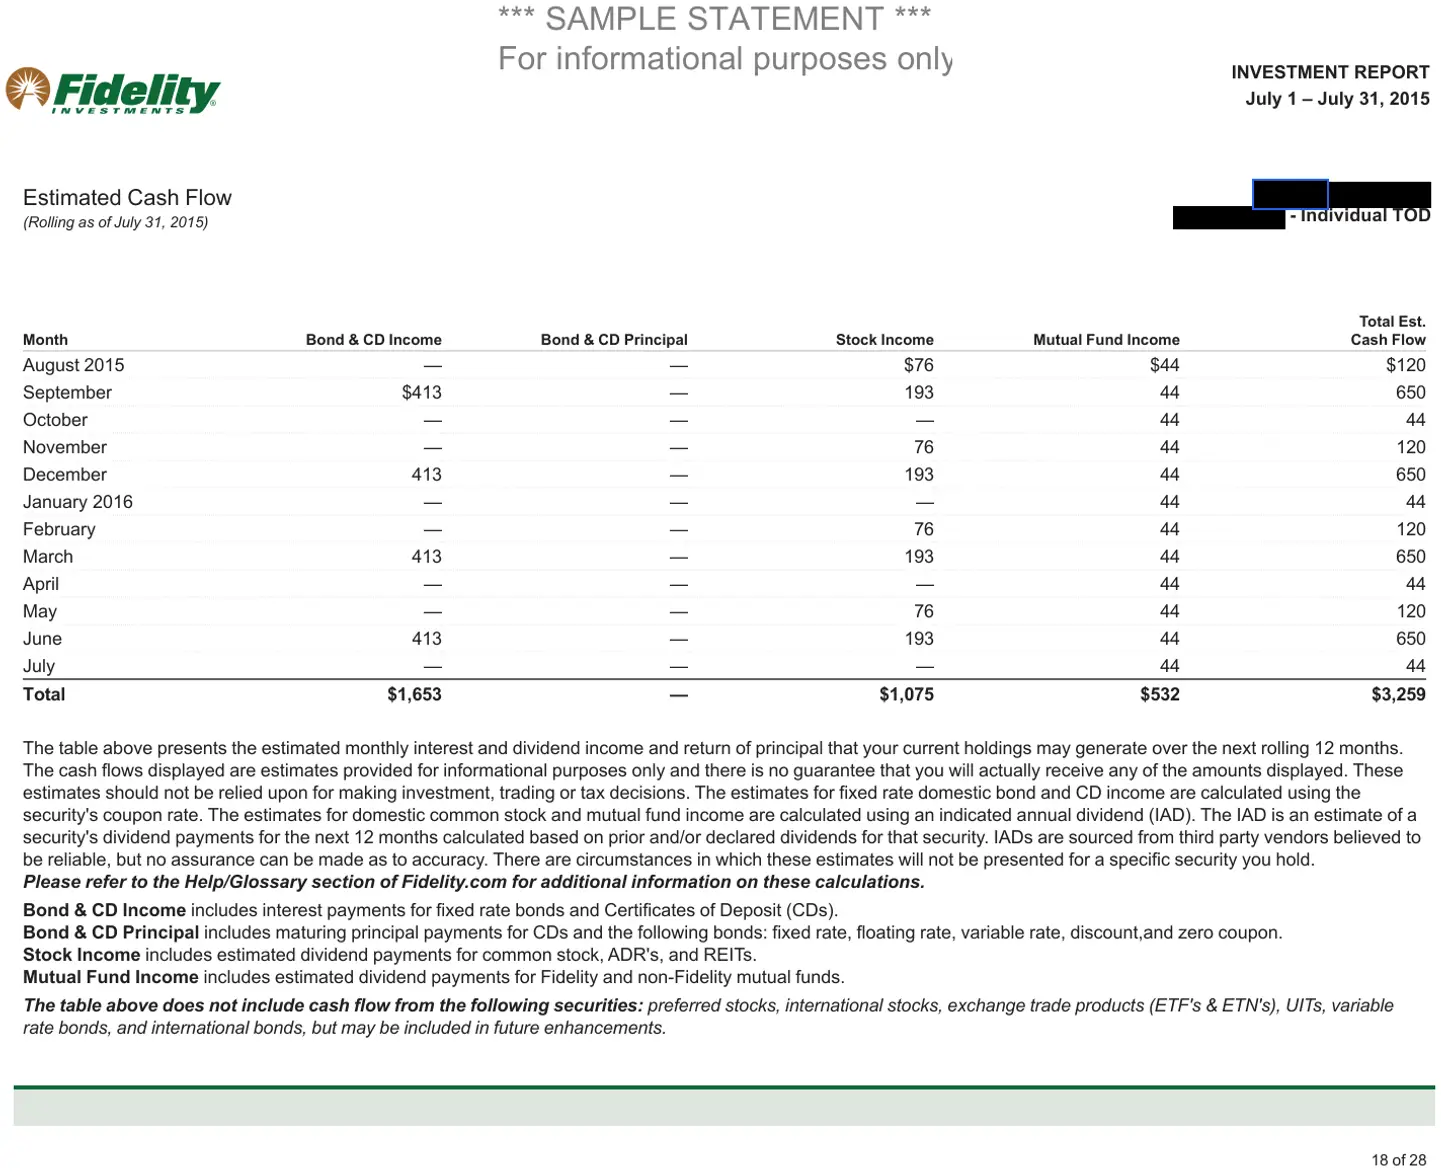
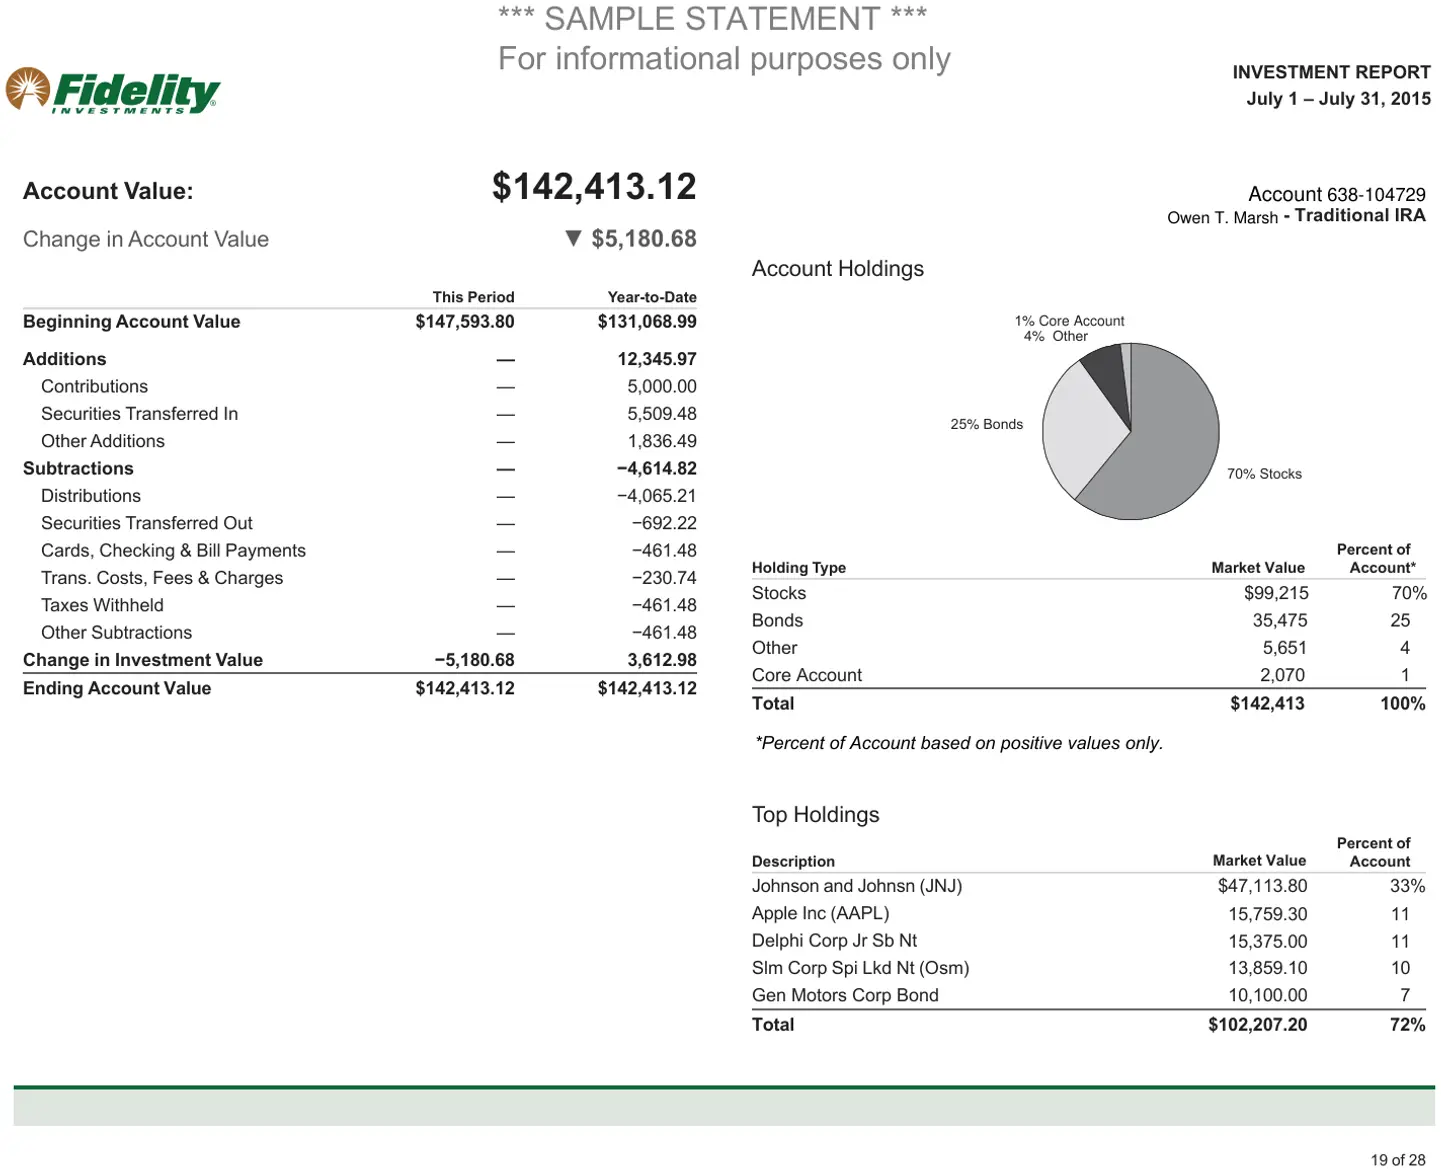
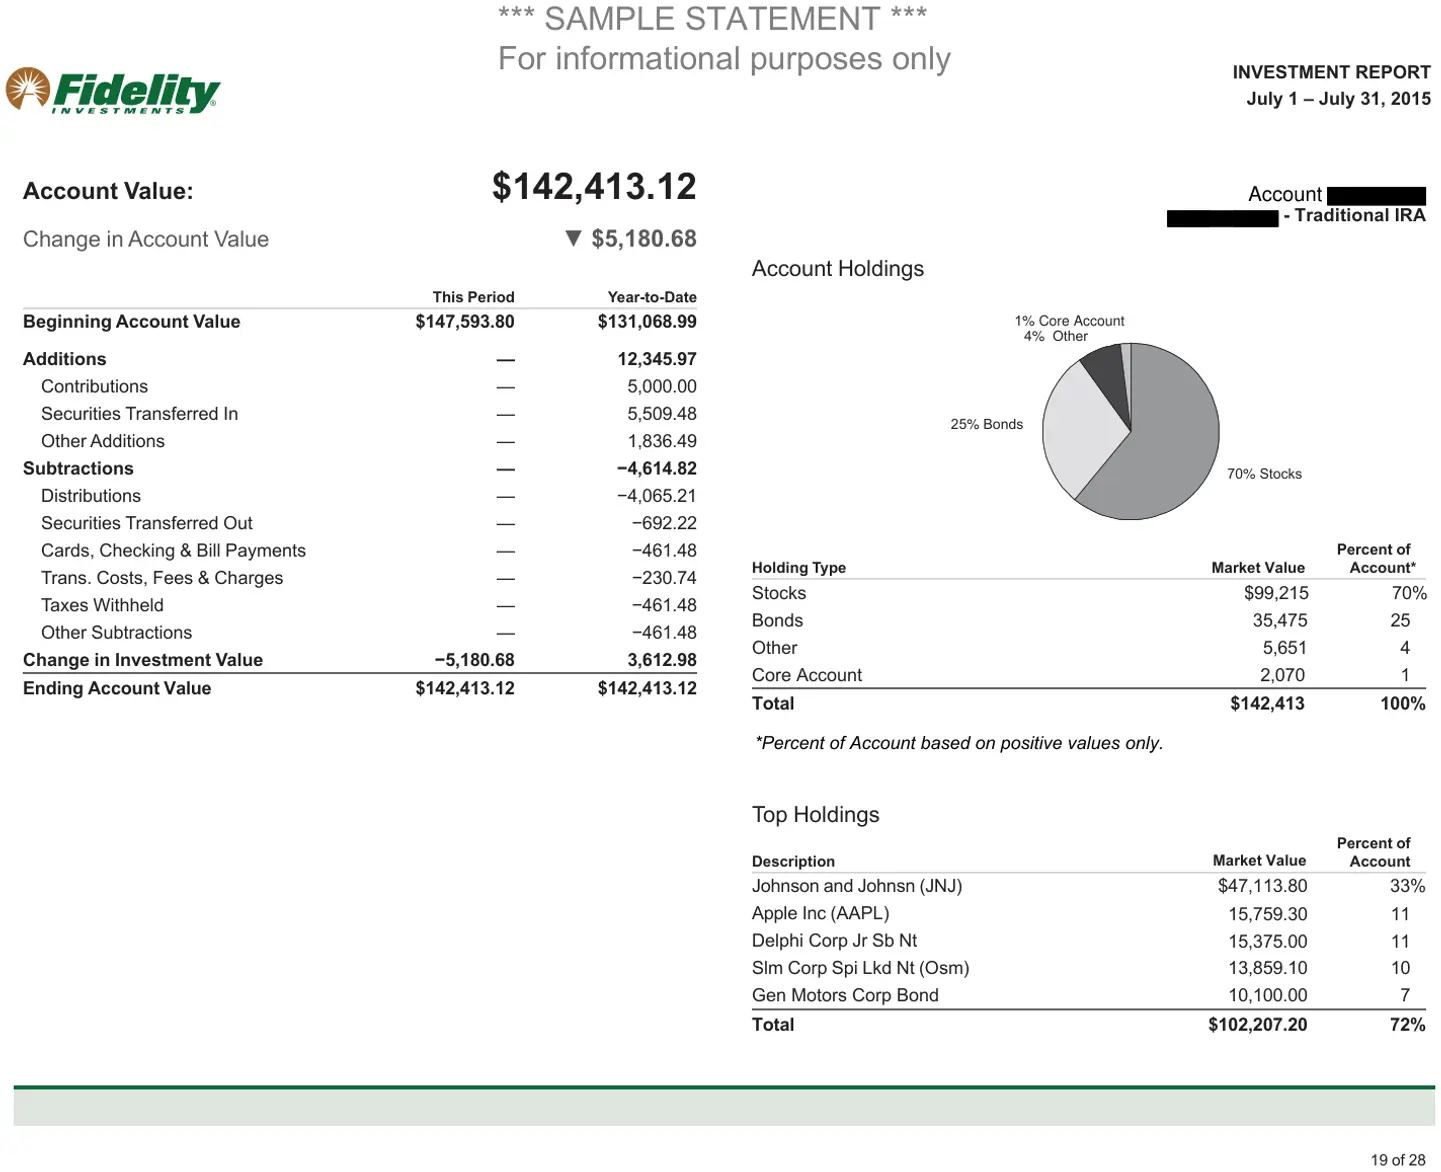
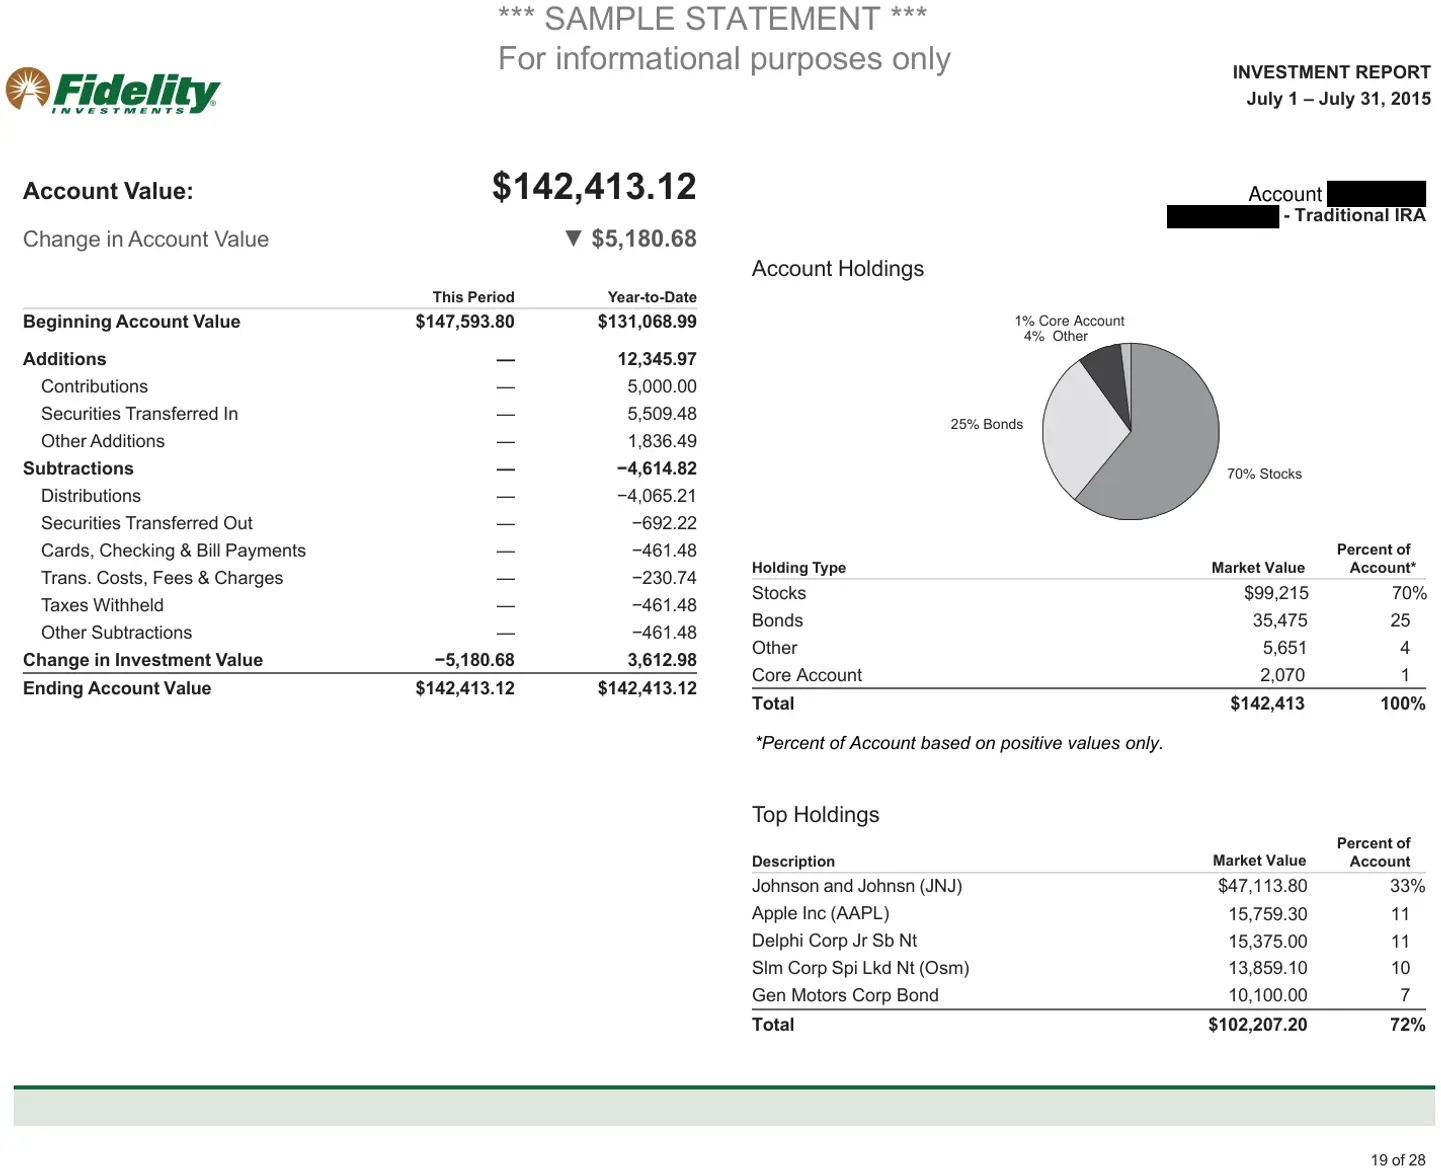
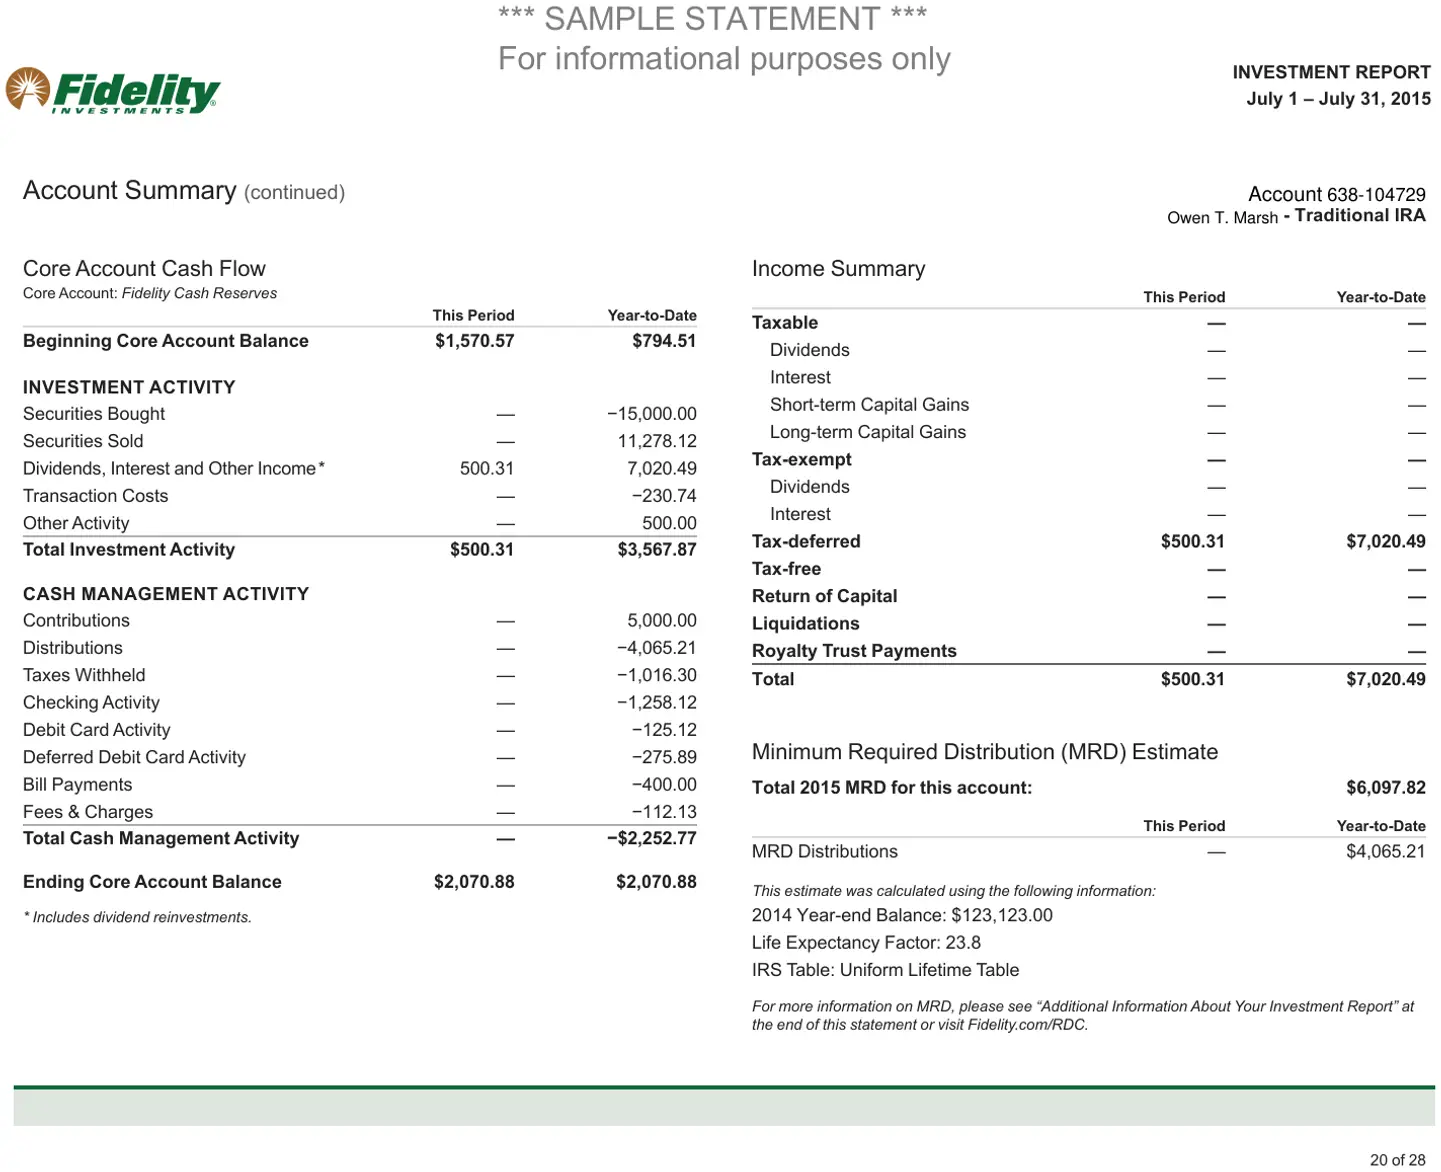
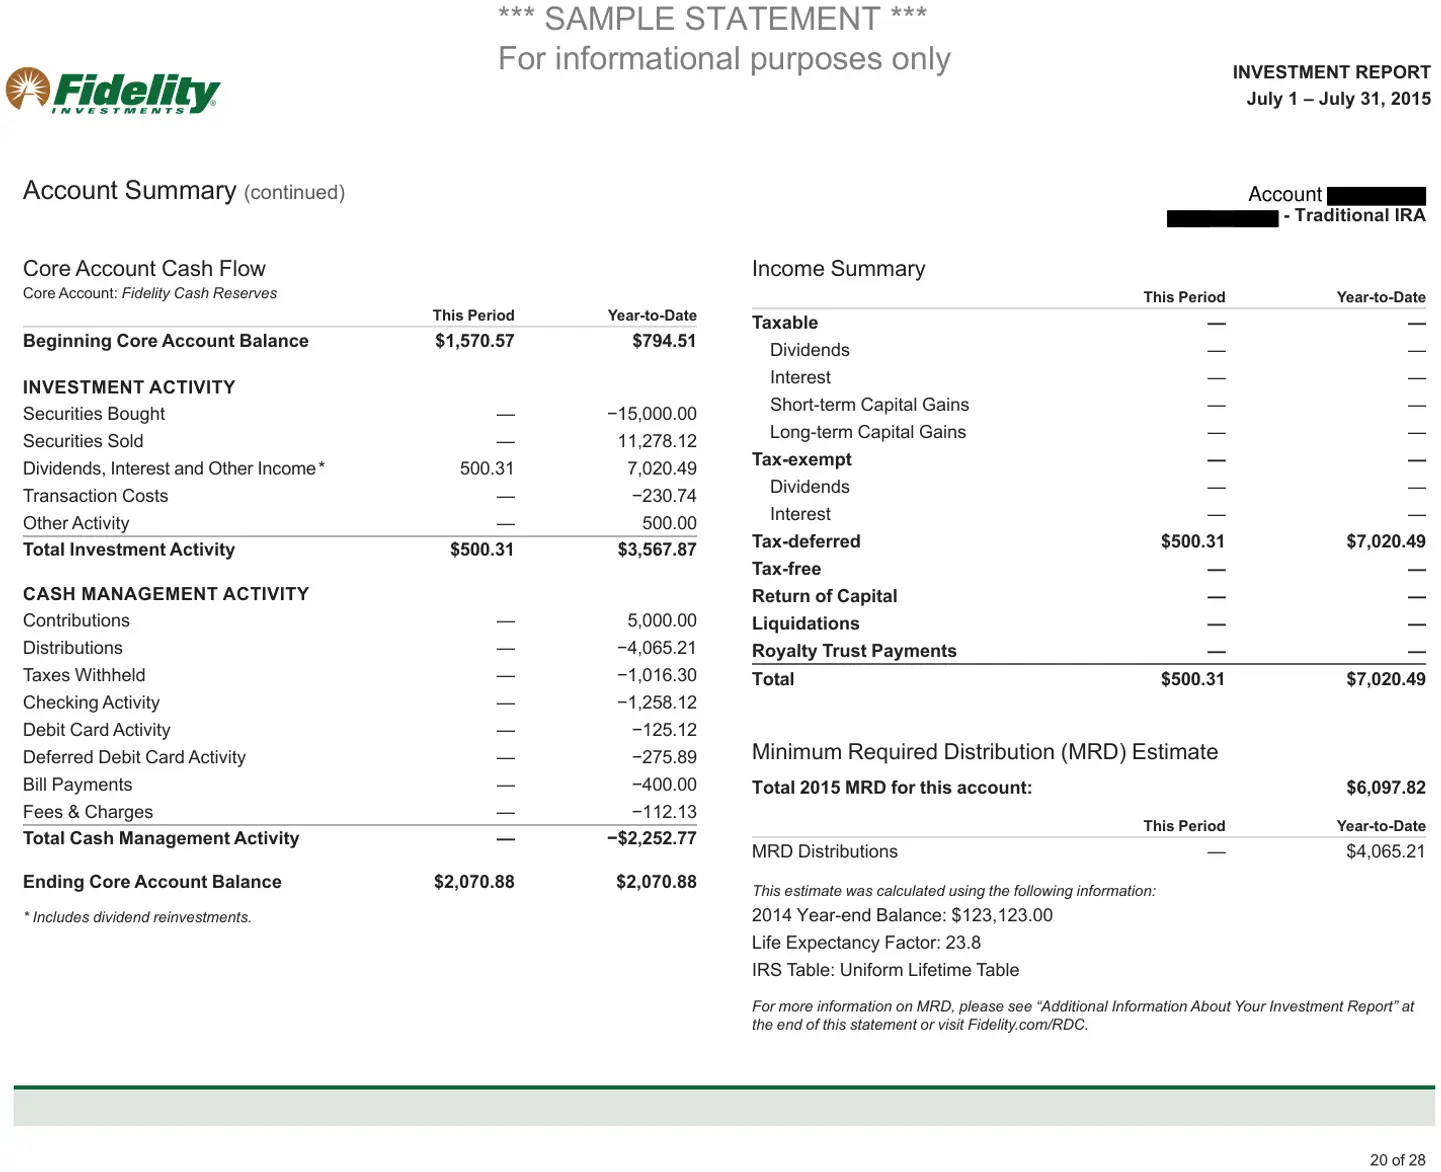
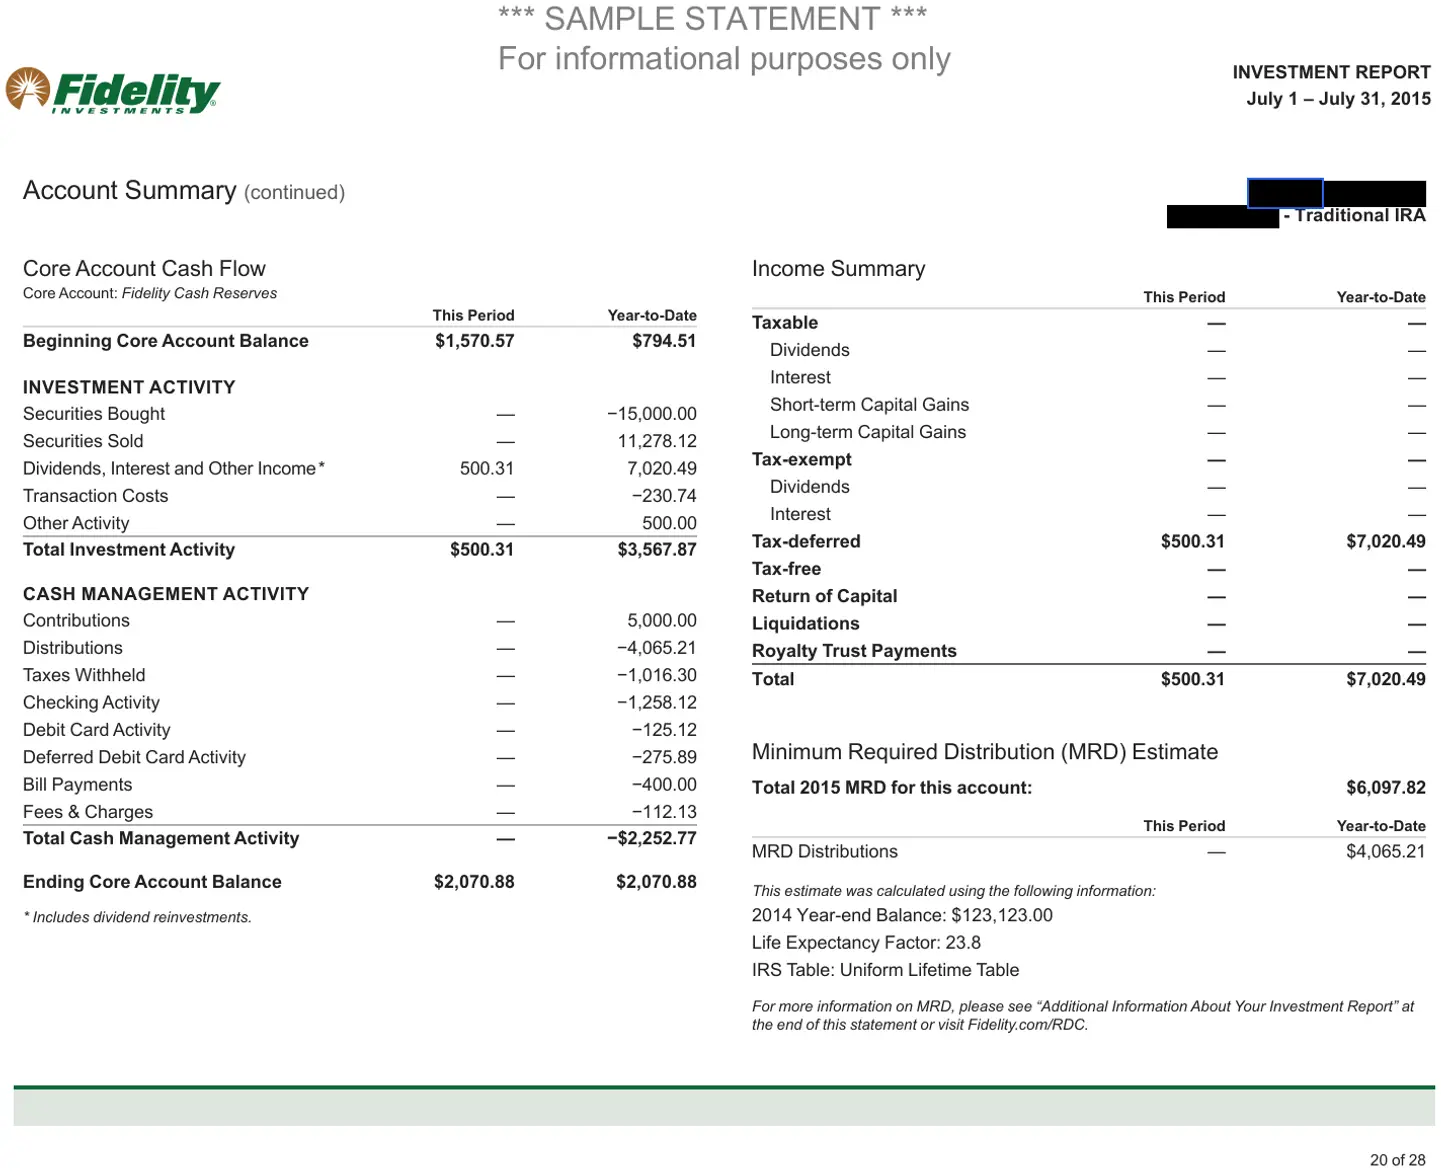
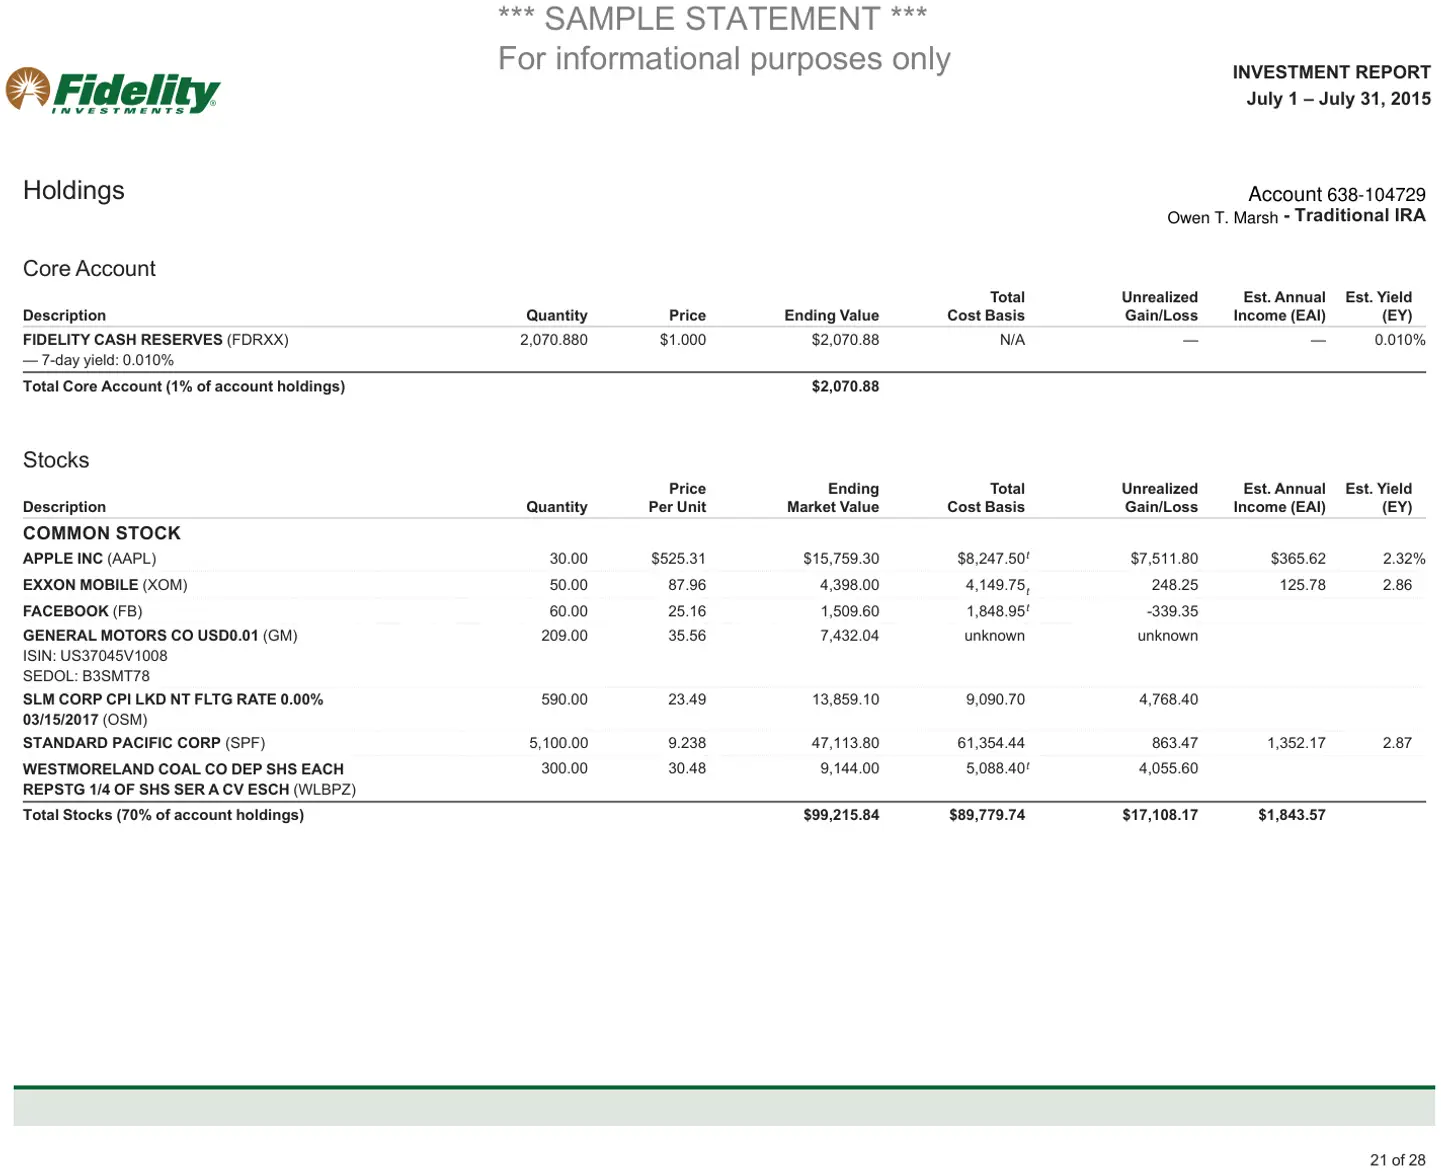
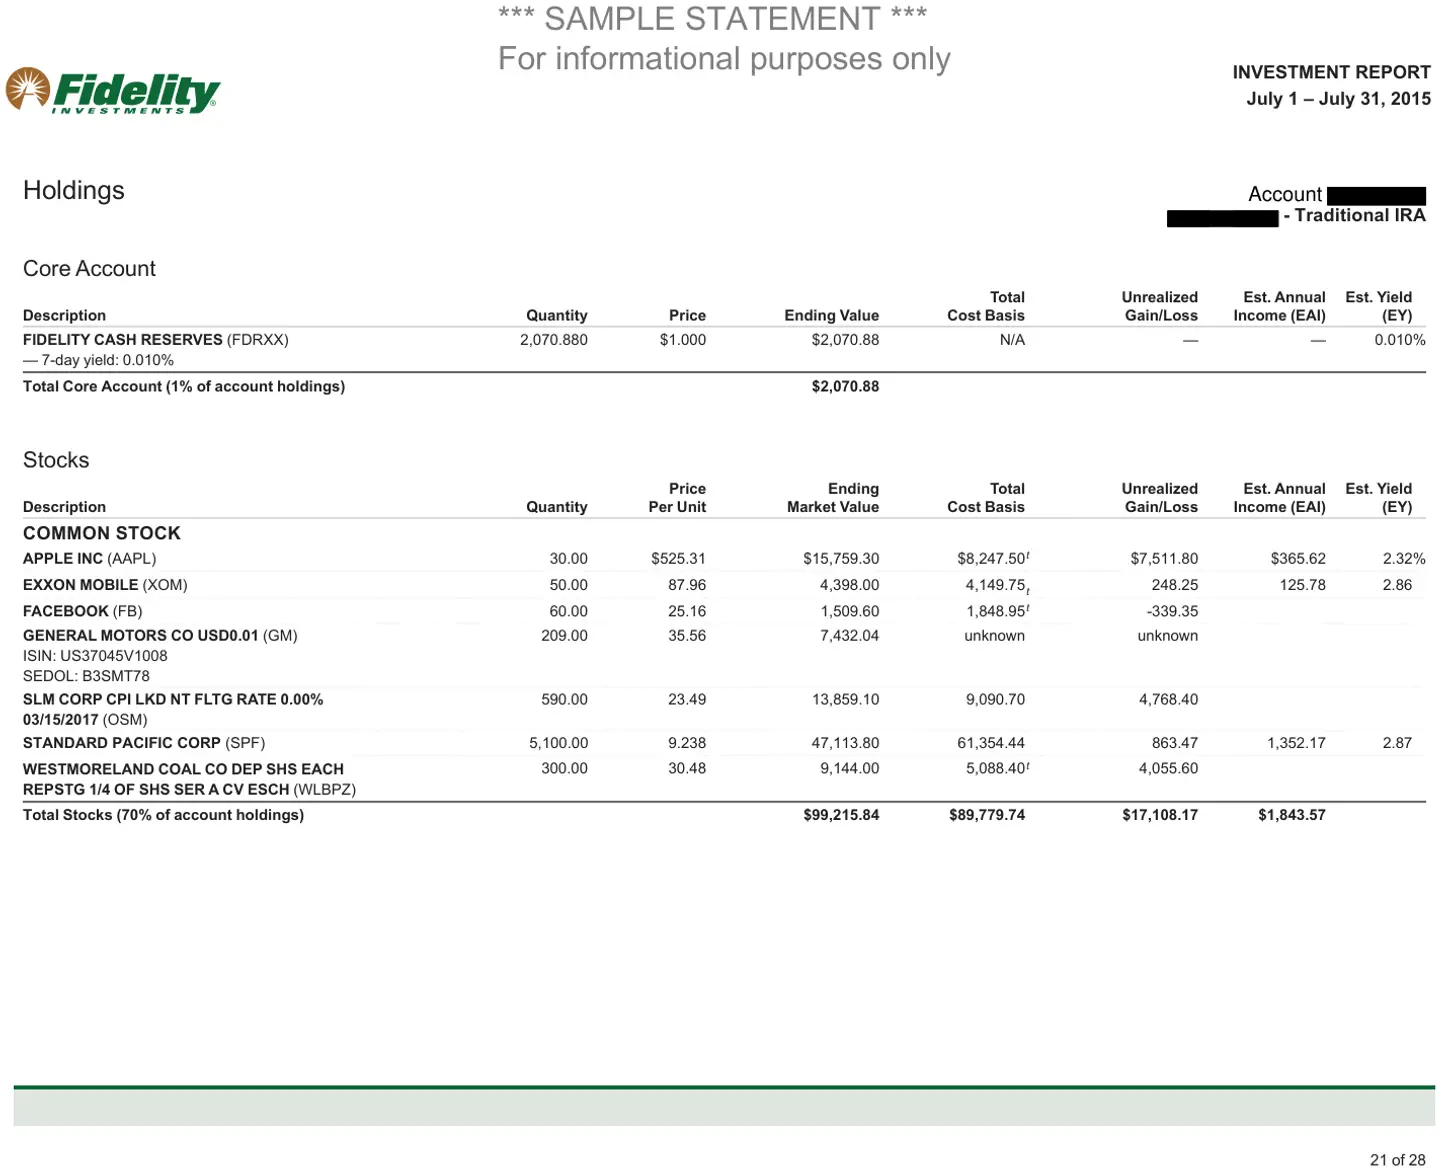
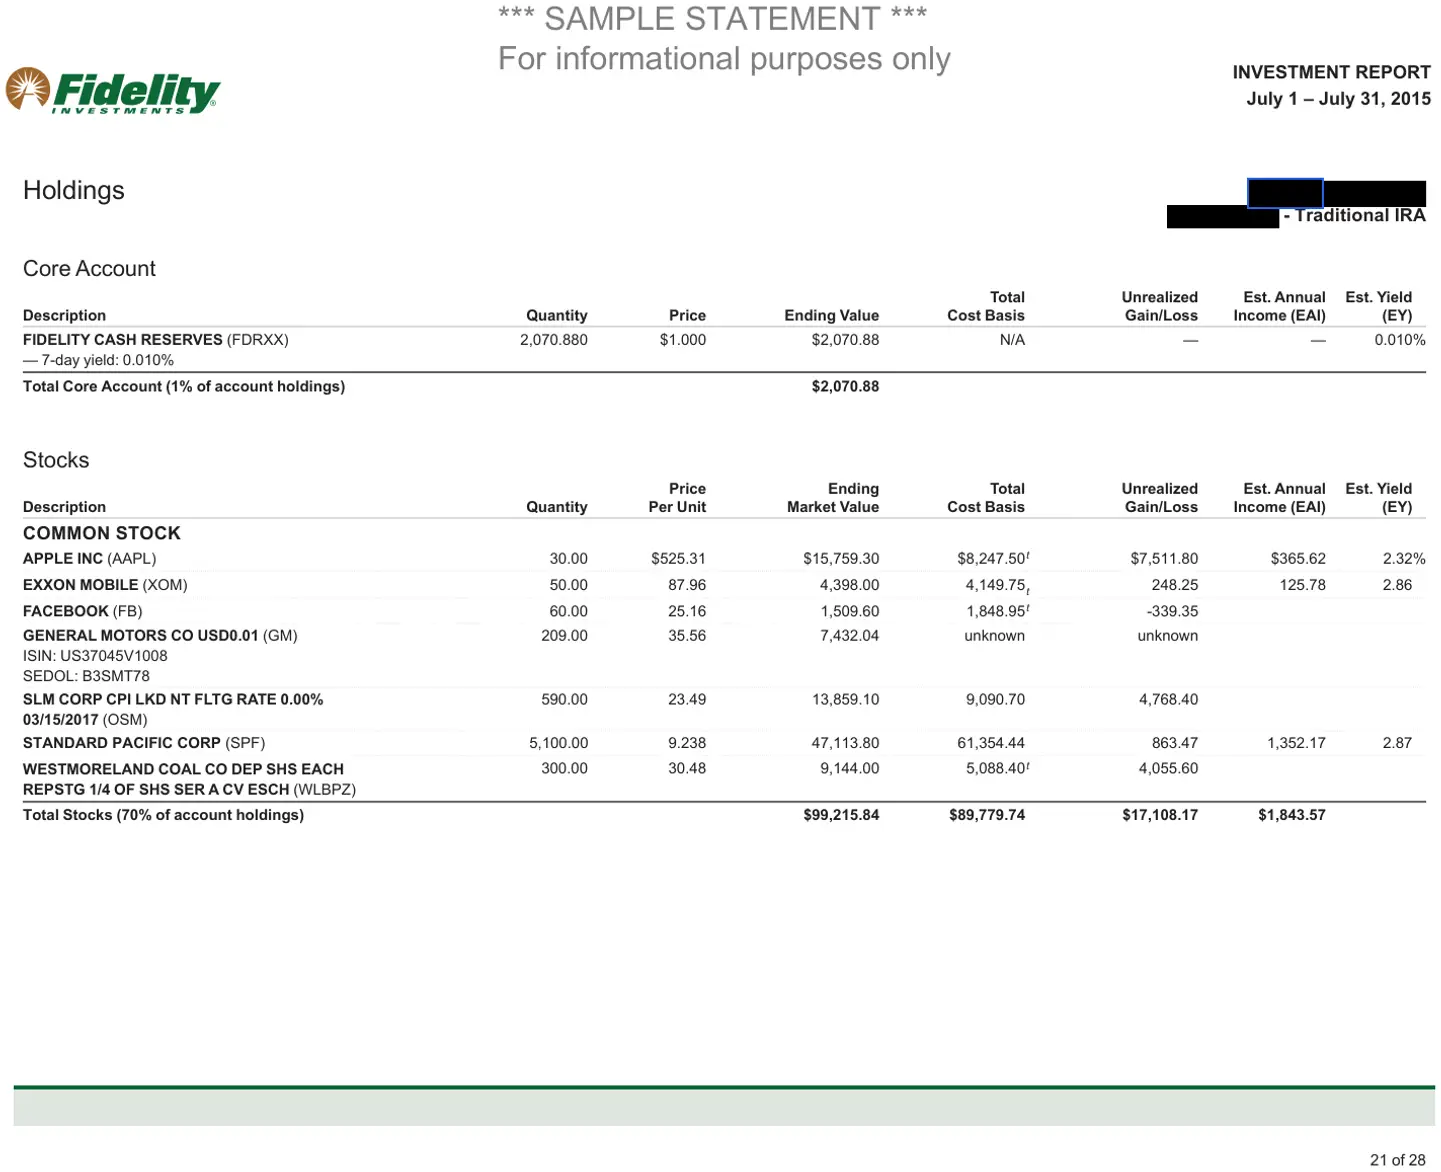
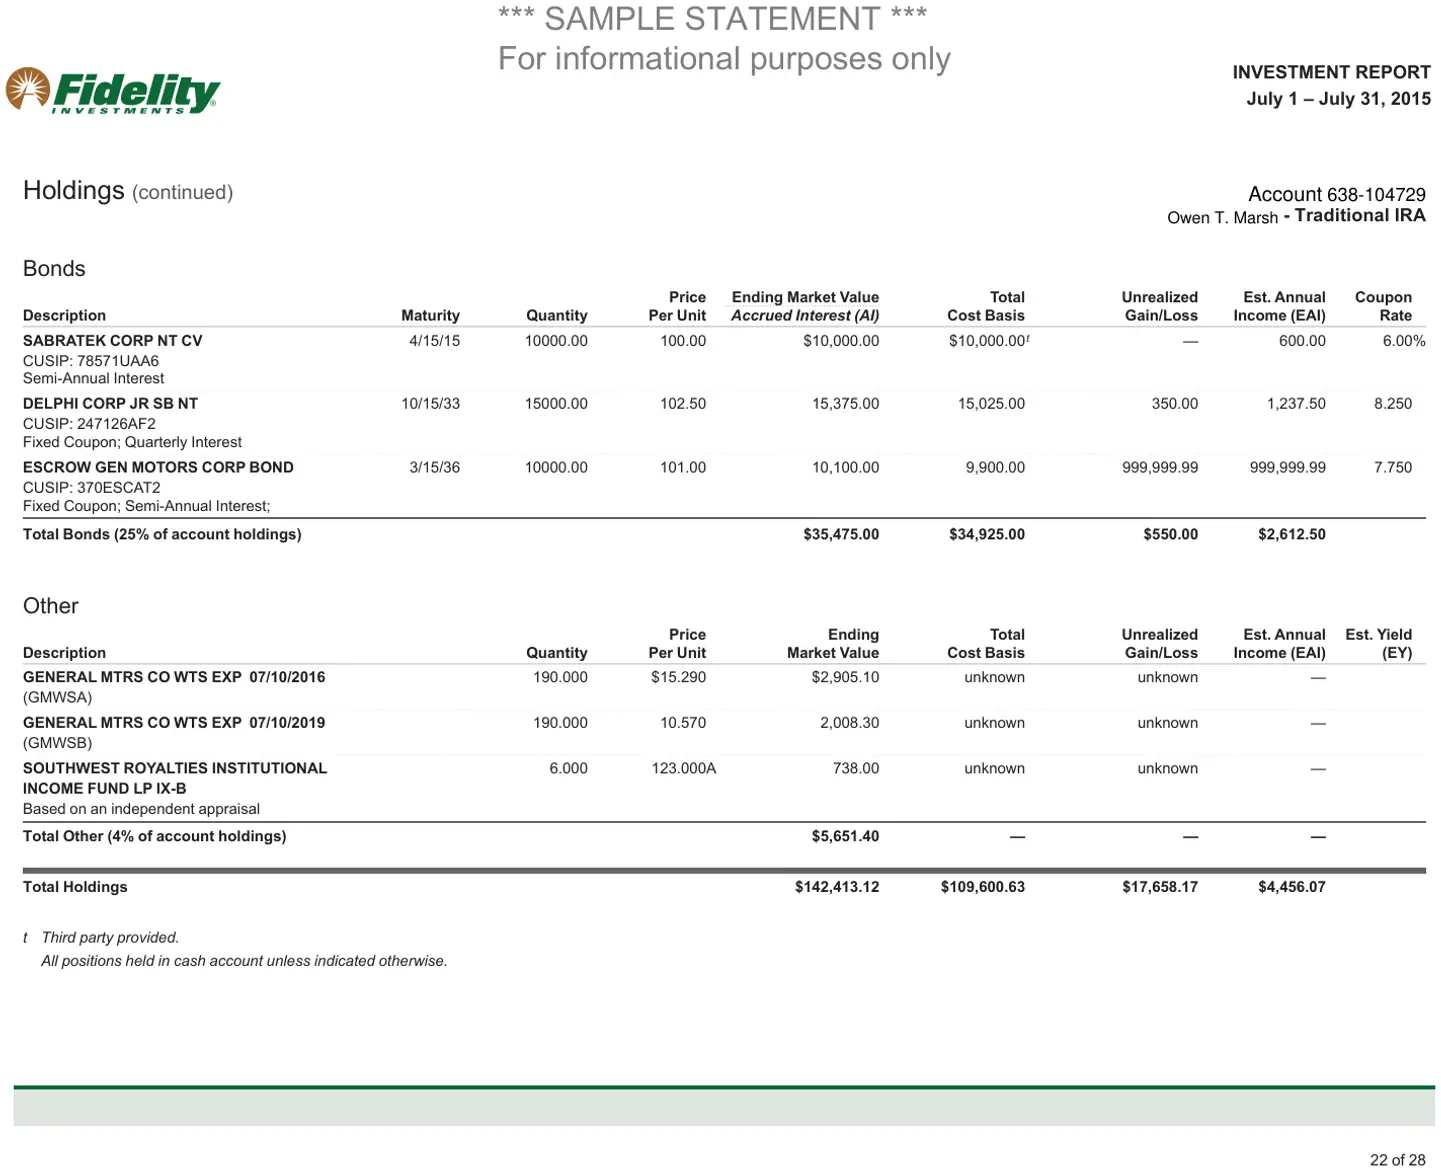
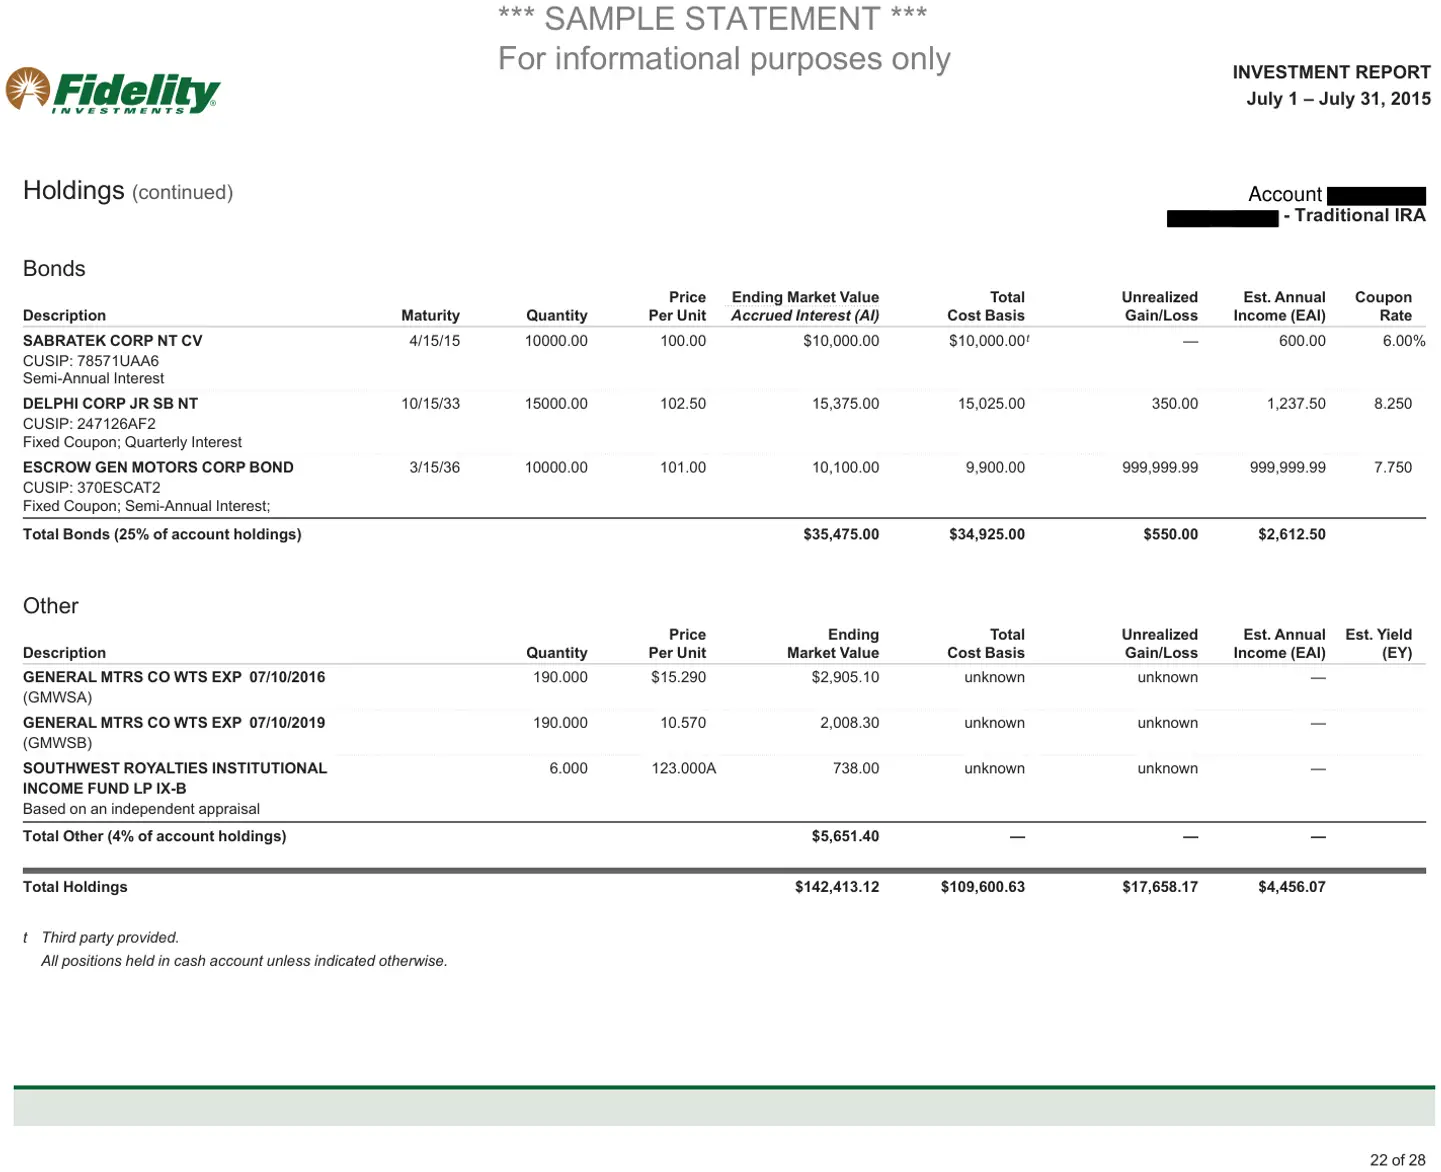
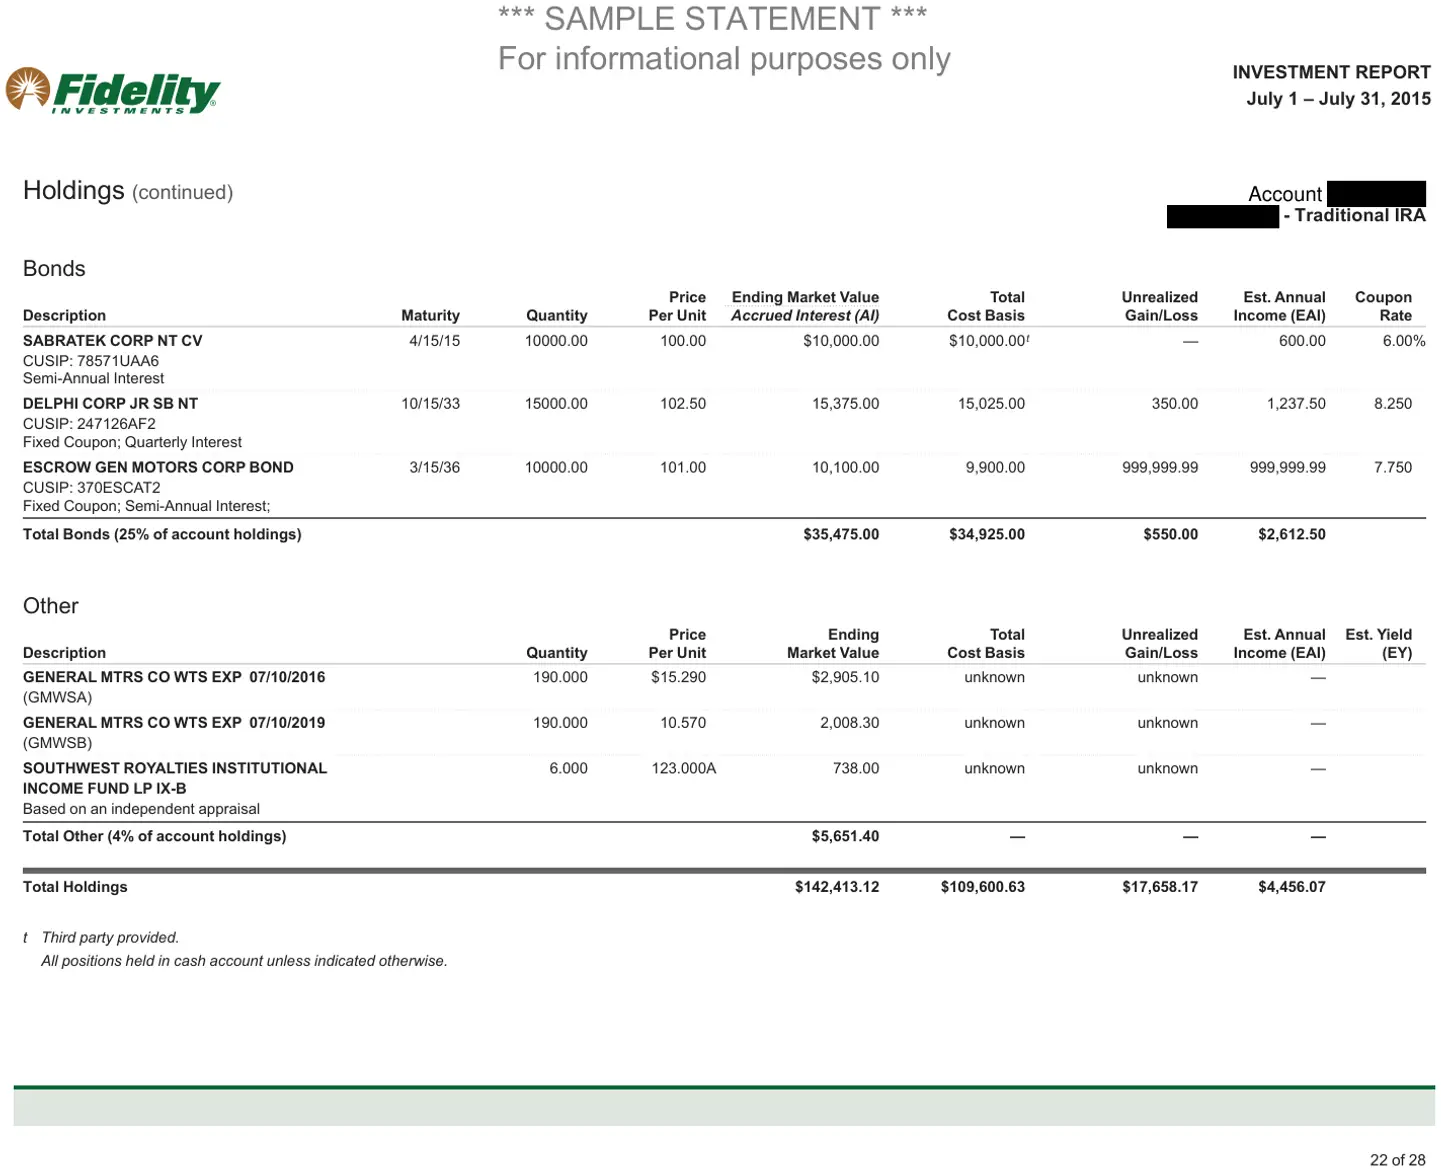
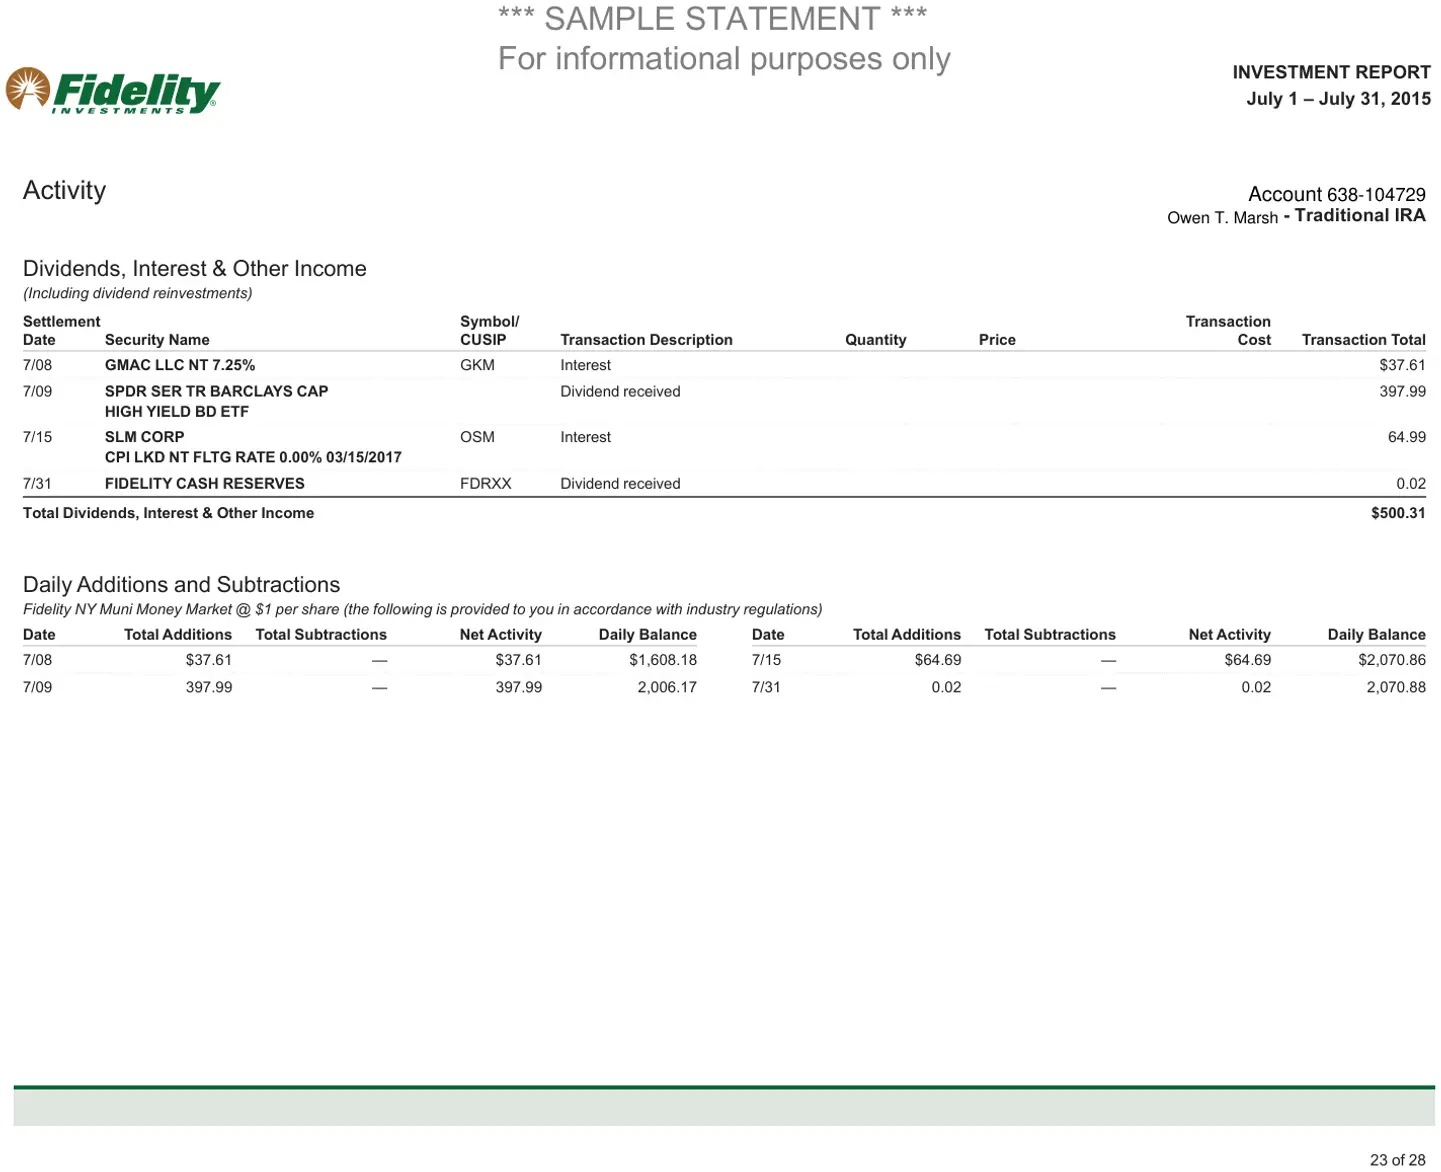
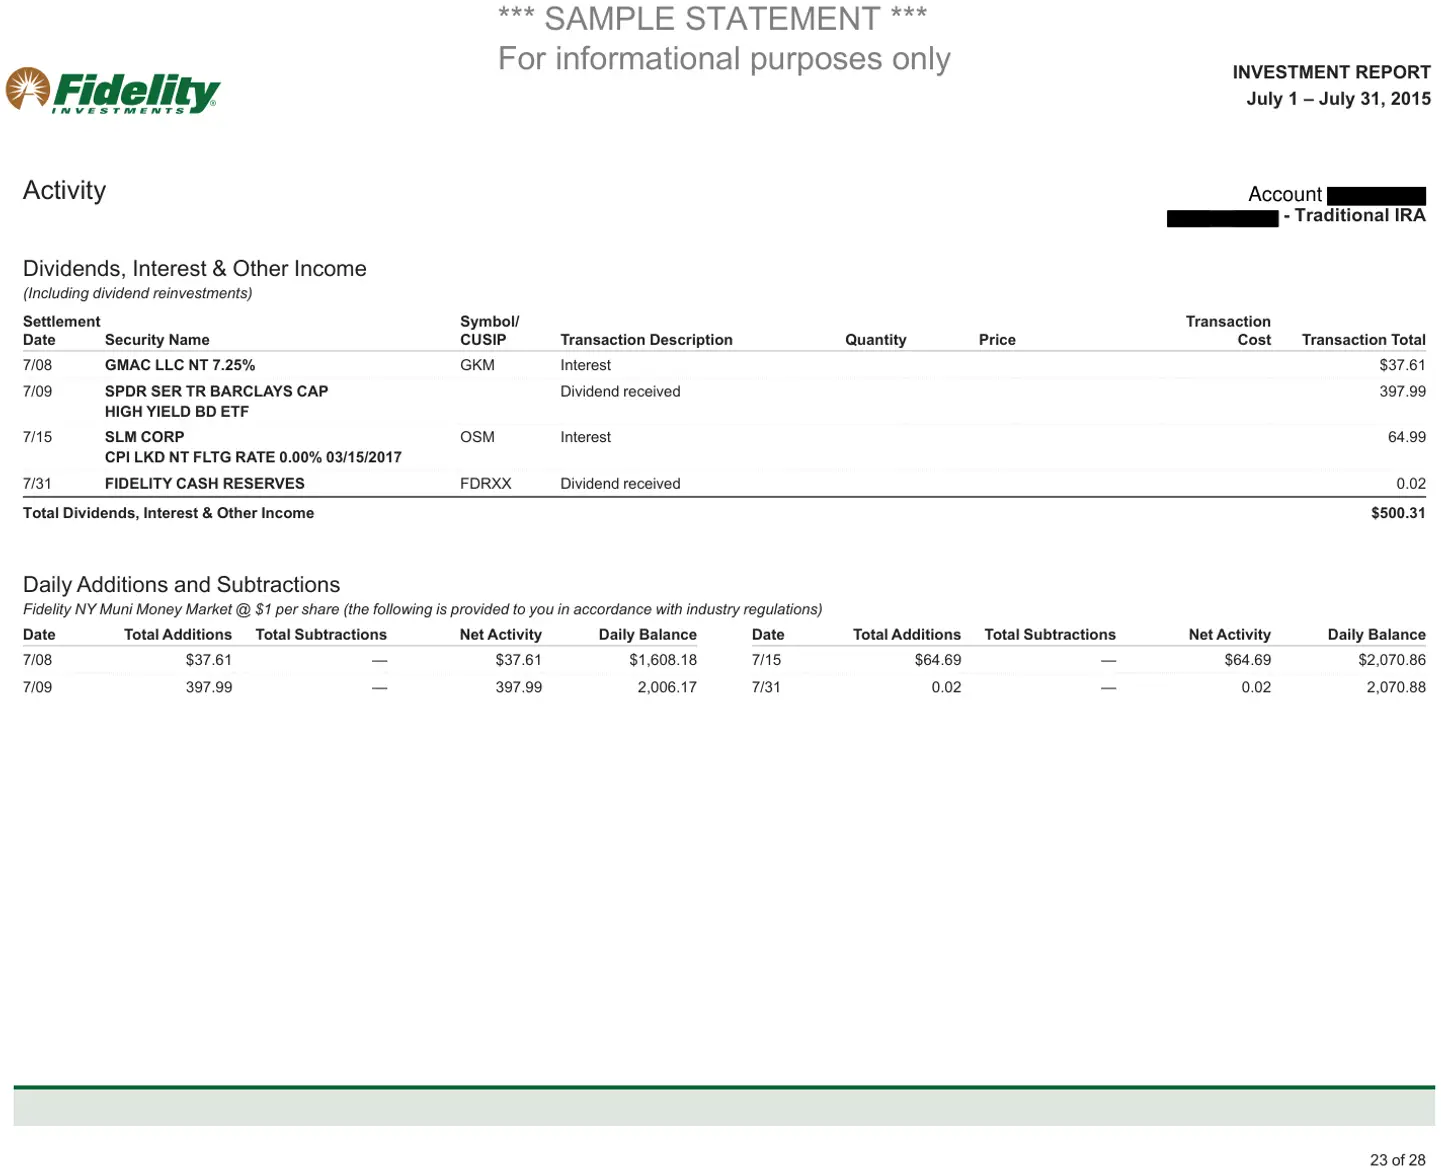
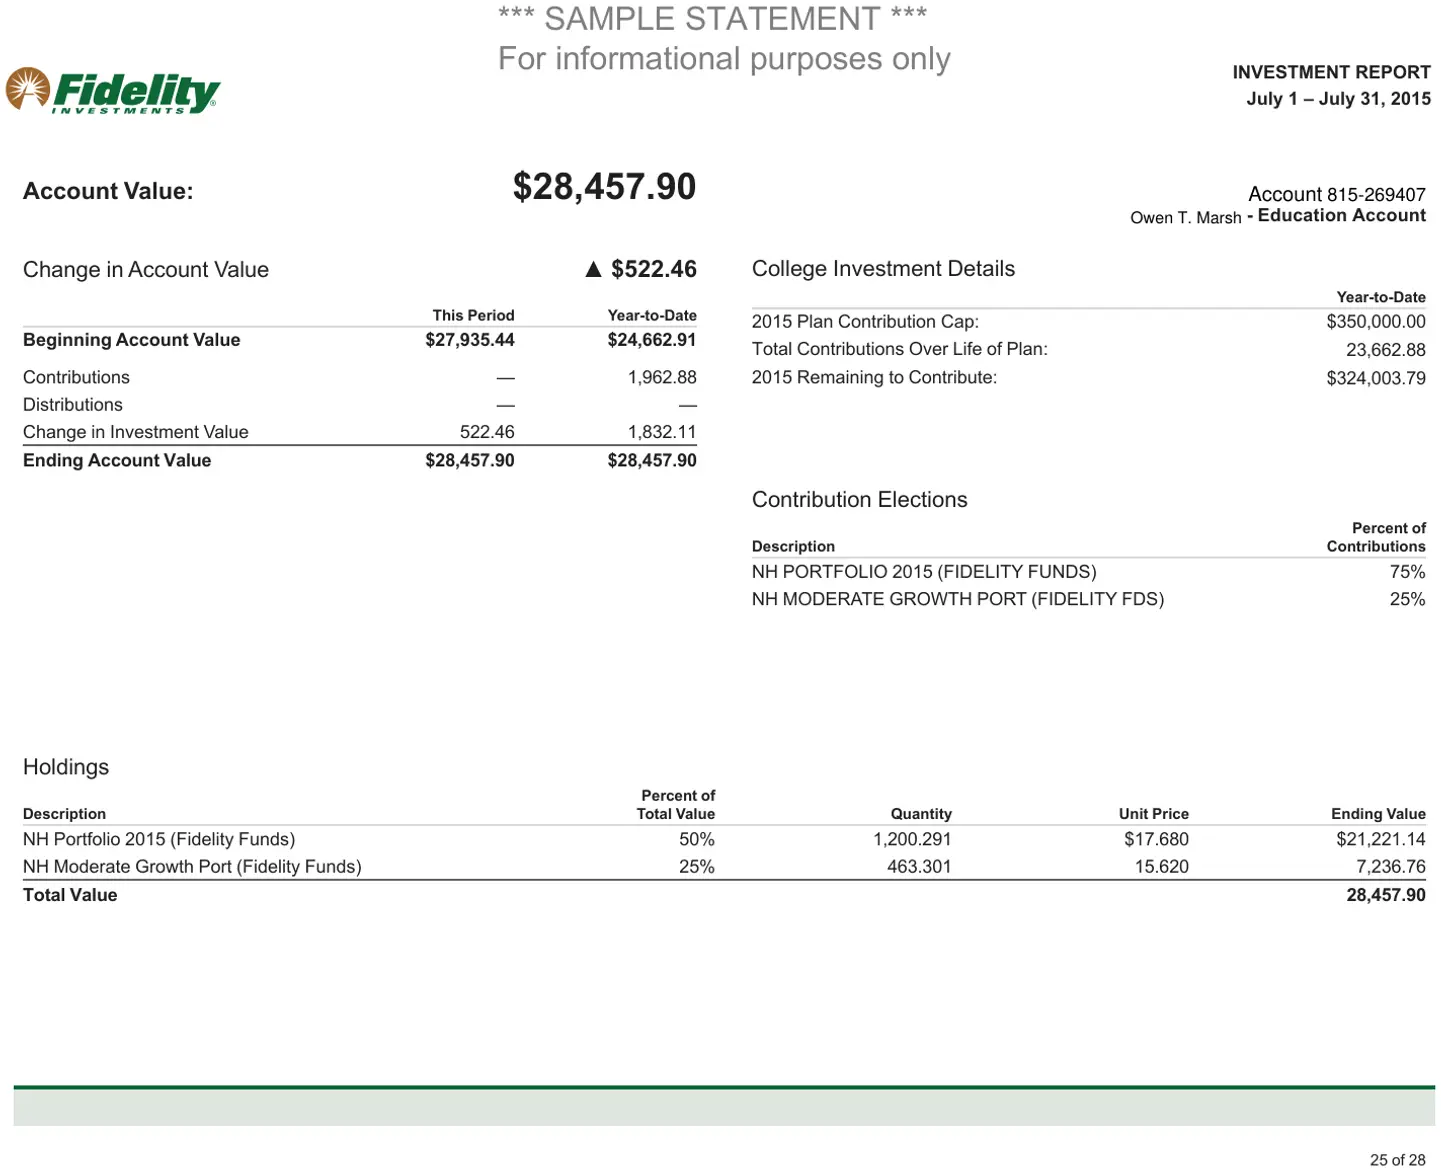
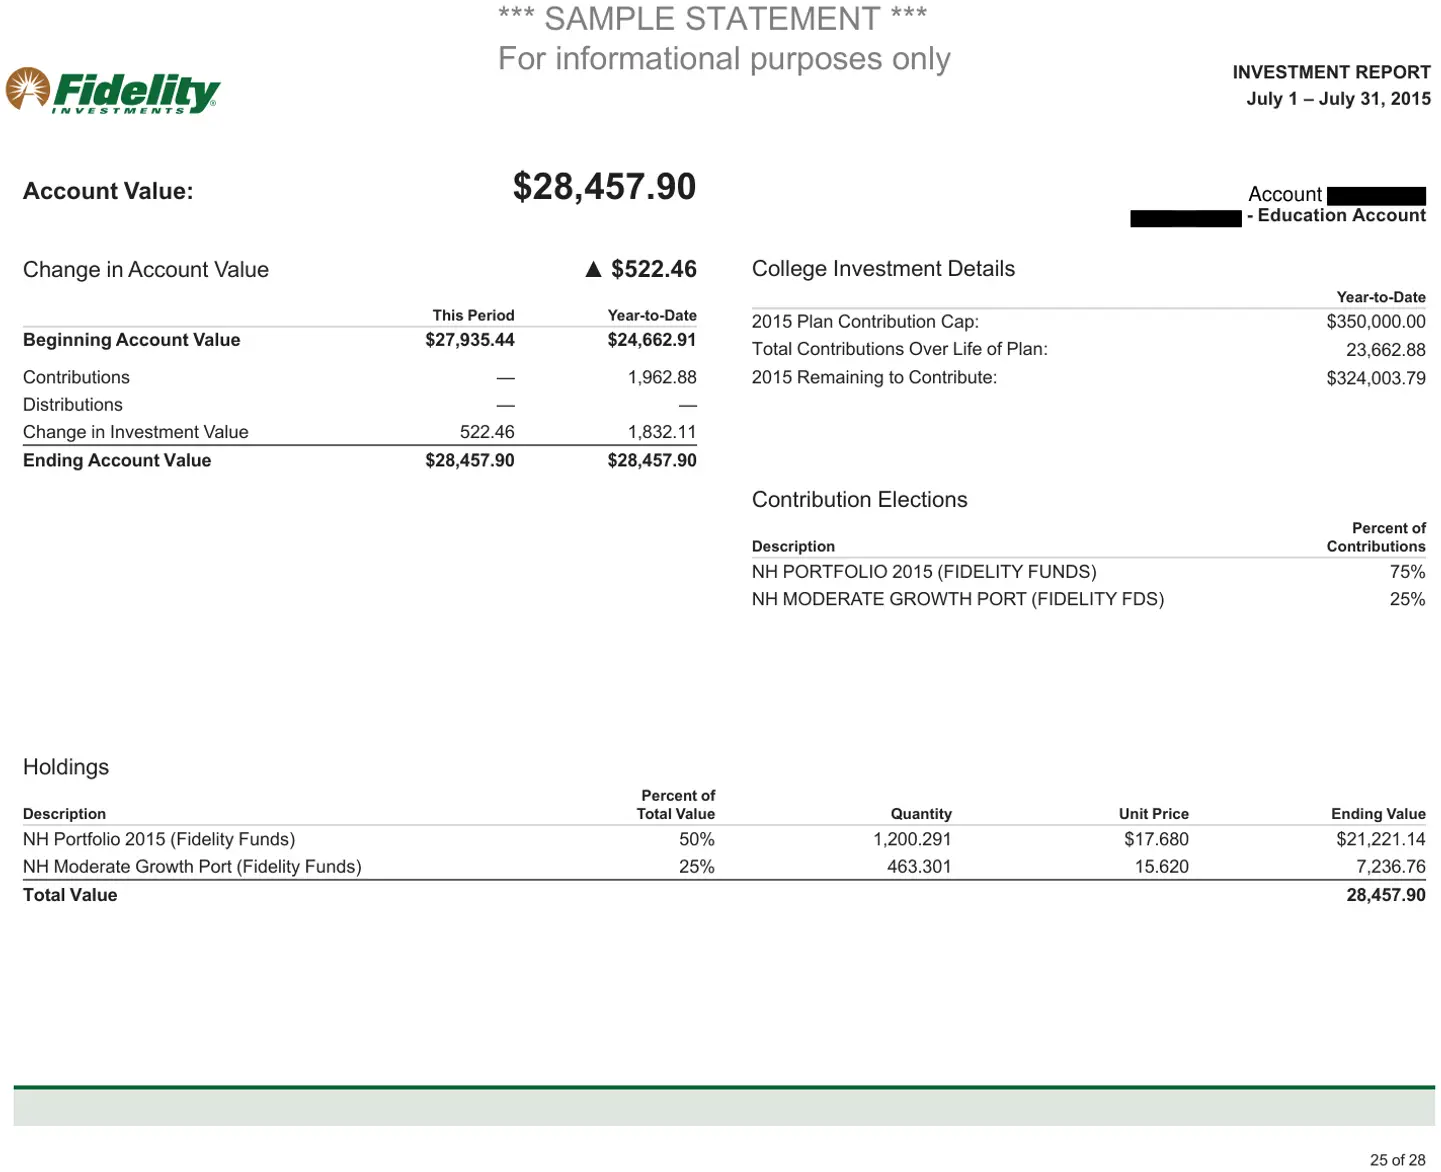
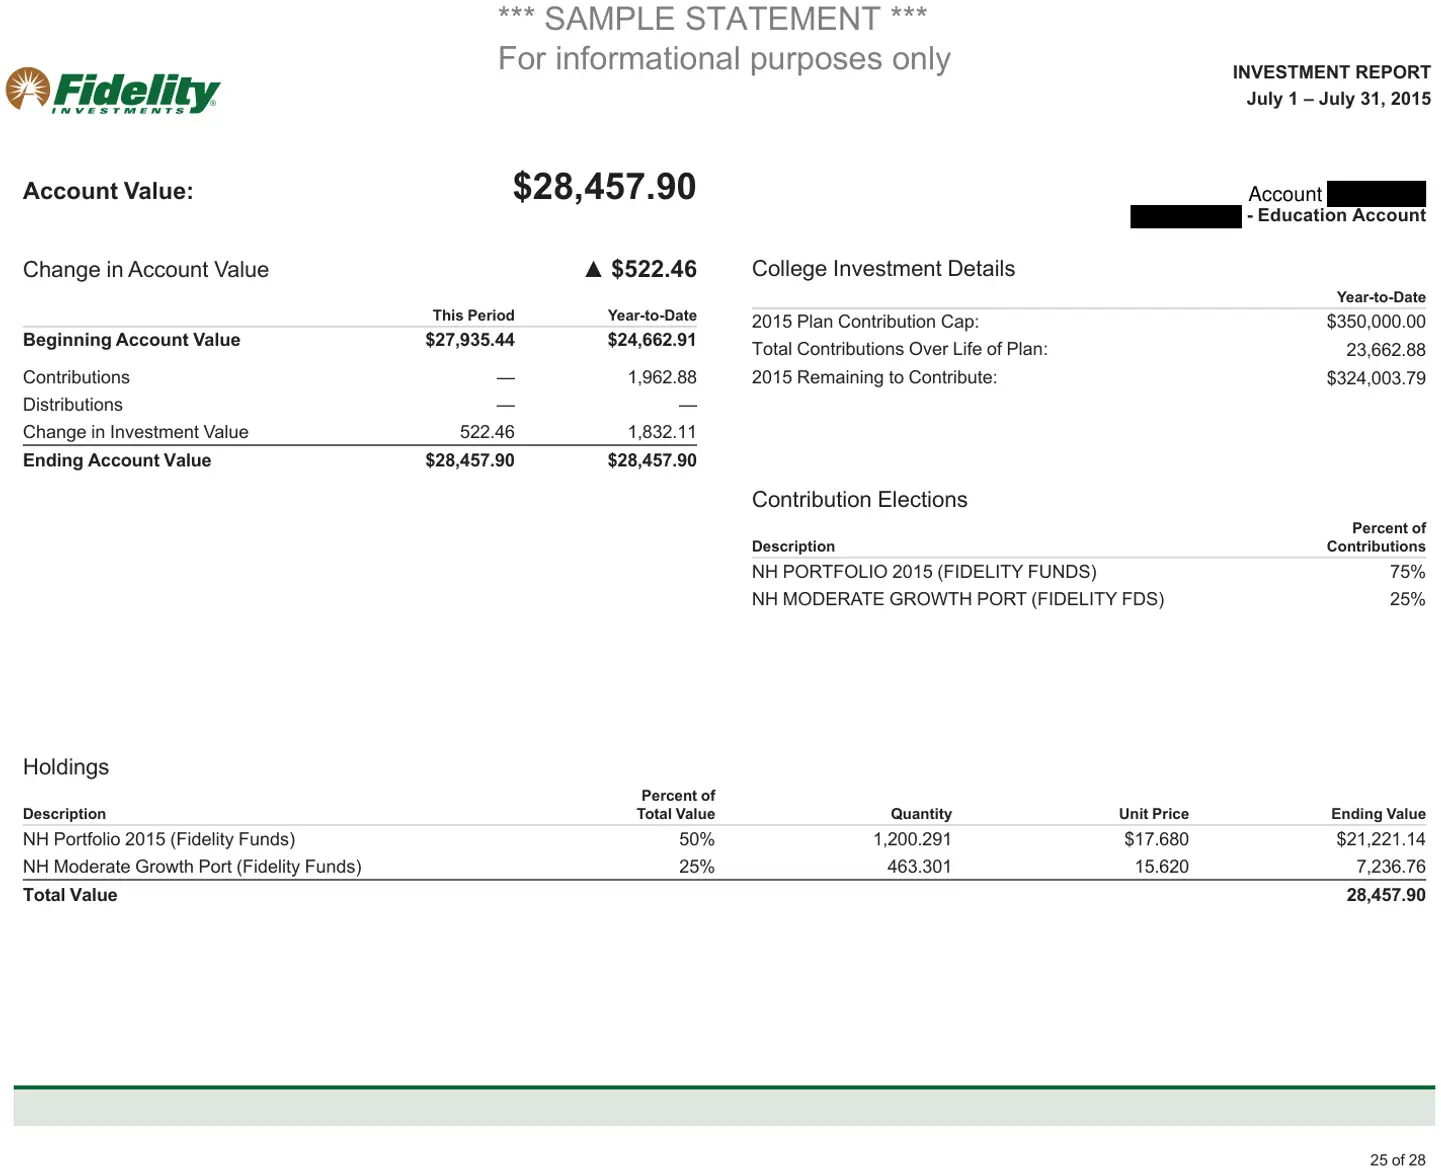
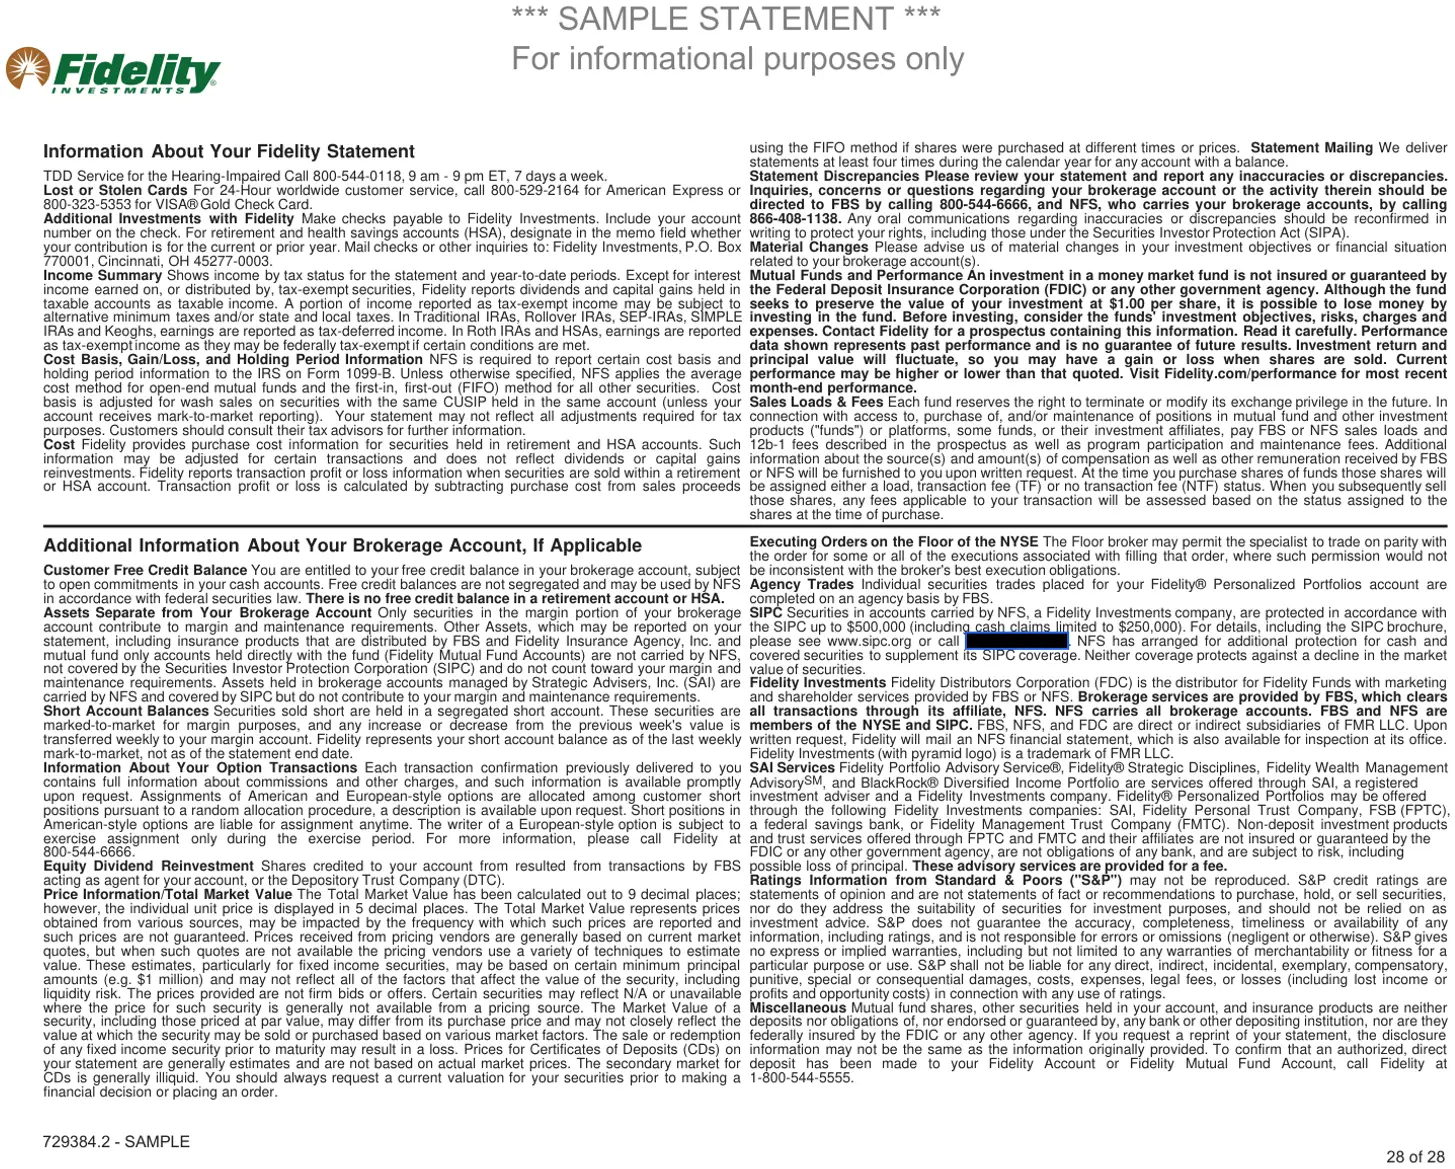
fidelity-large-print-sample-statement.pdf
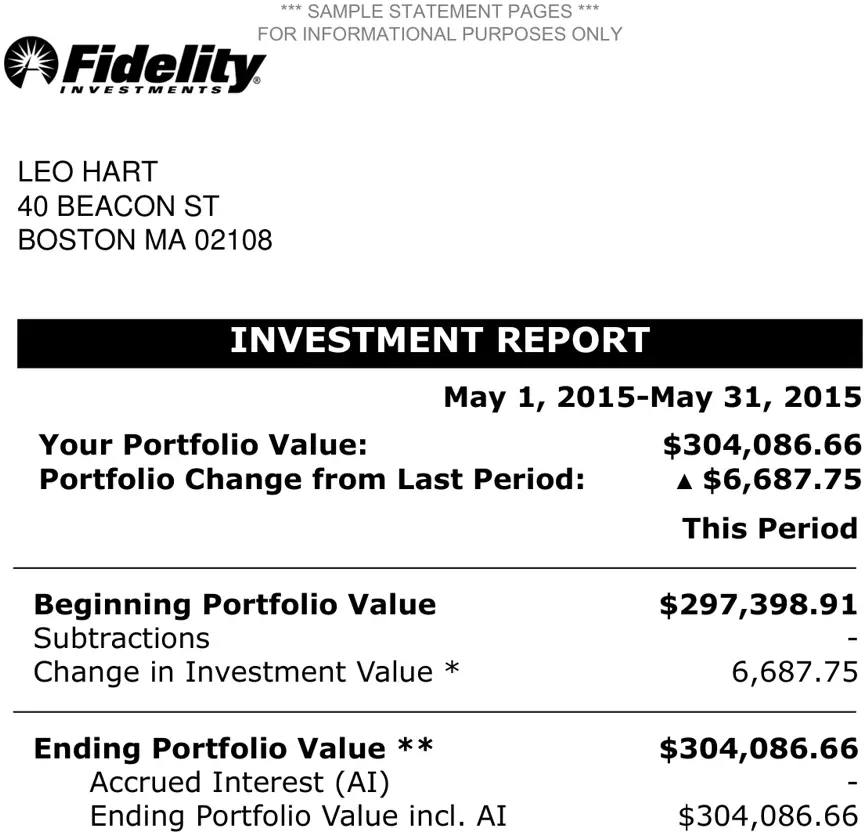
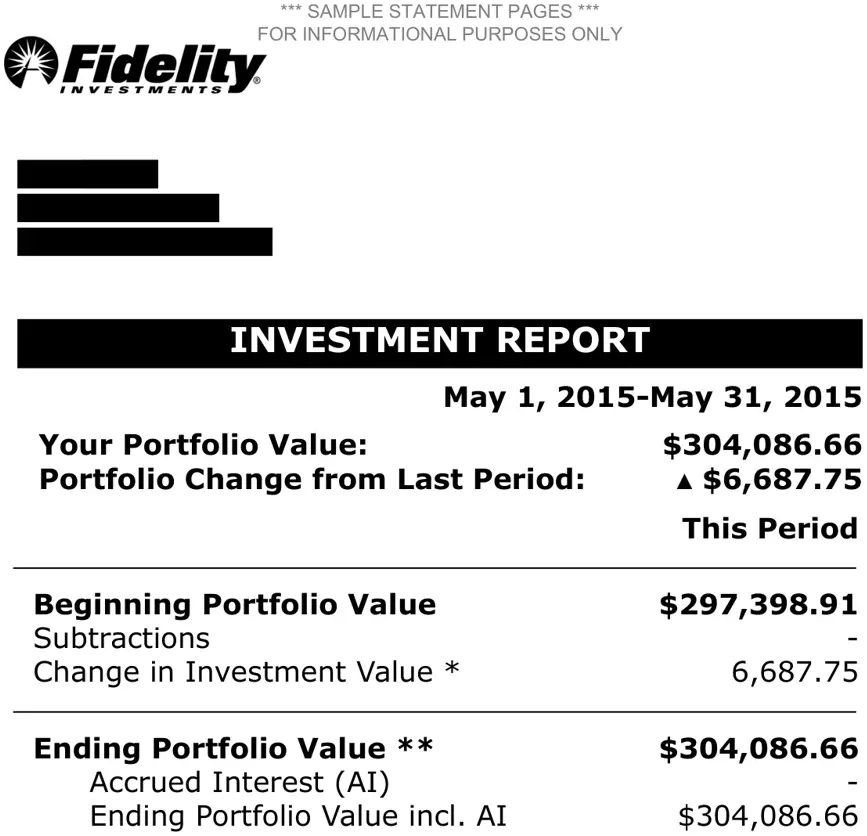
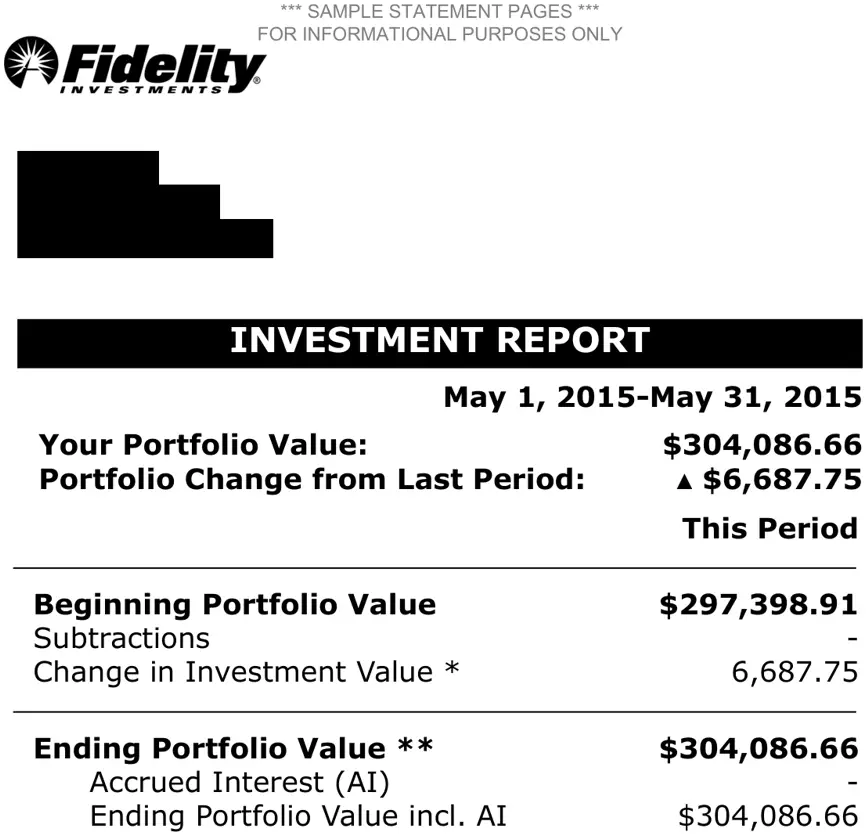
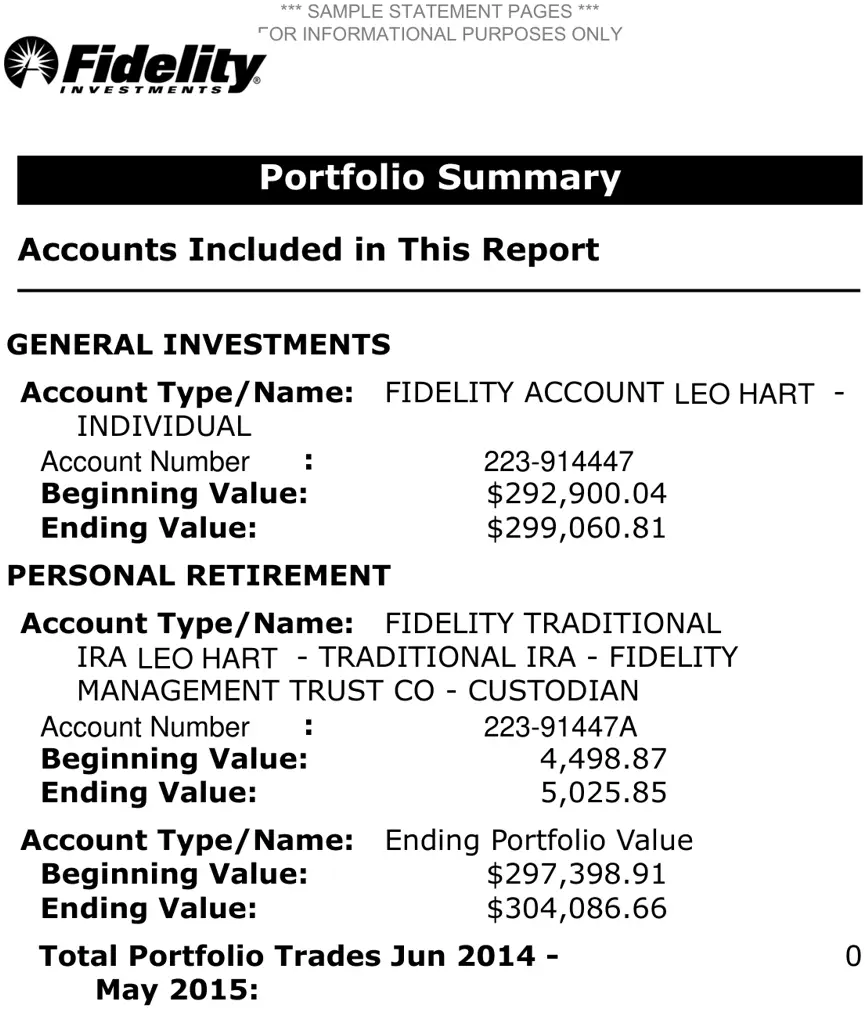
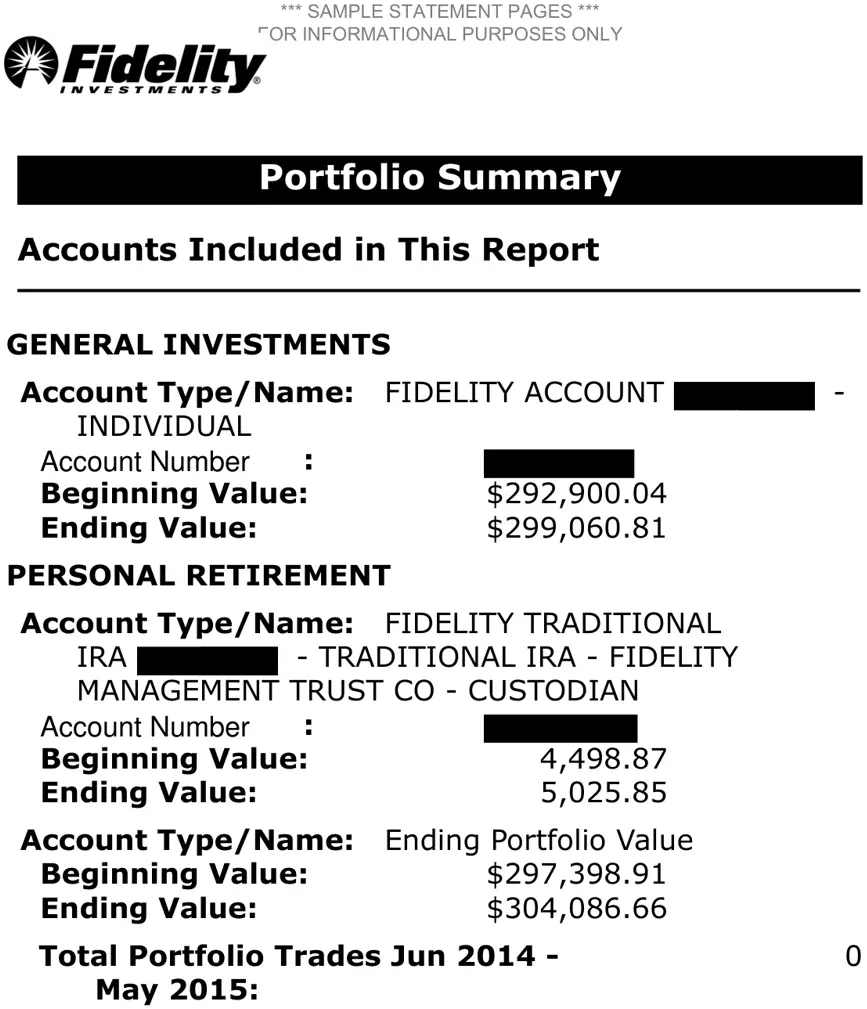
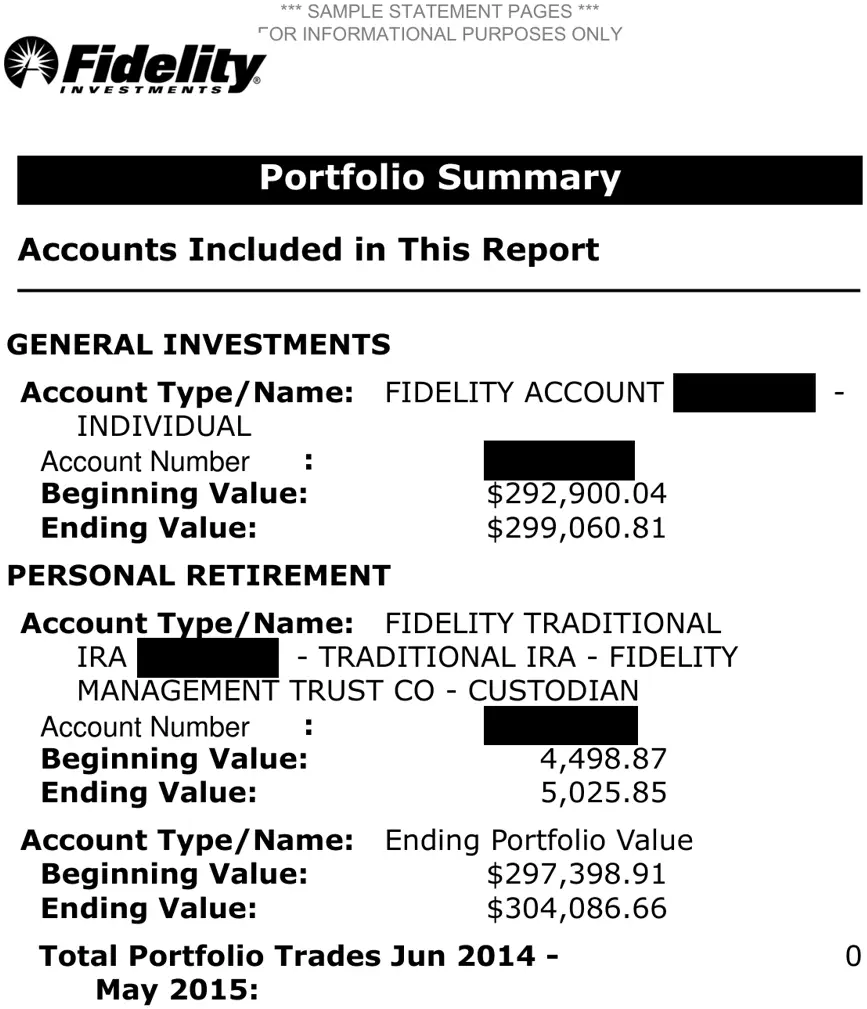
pershing-2024-sample-tax-yearend.pdf
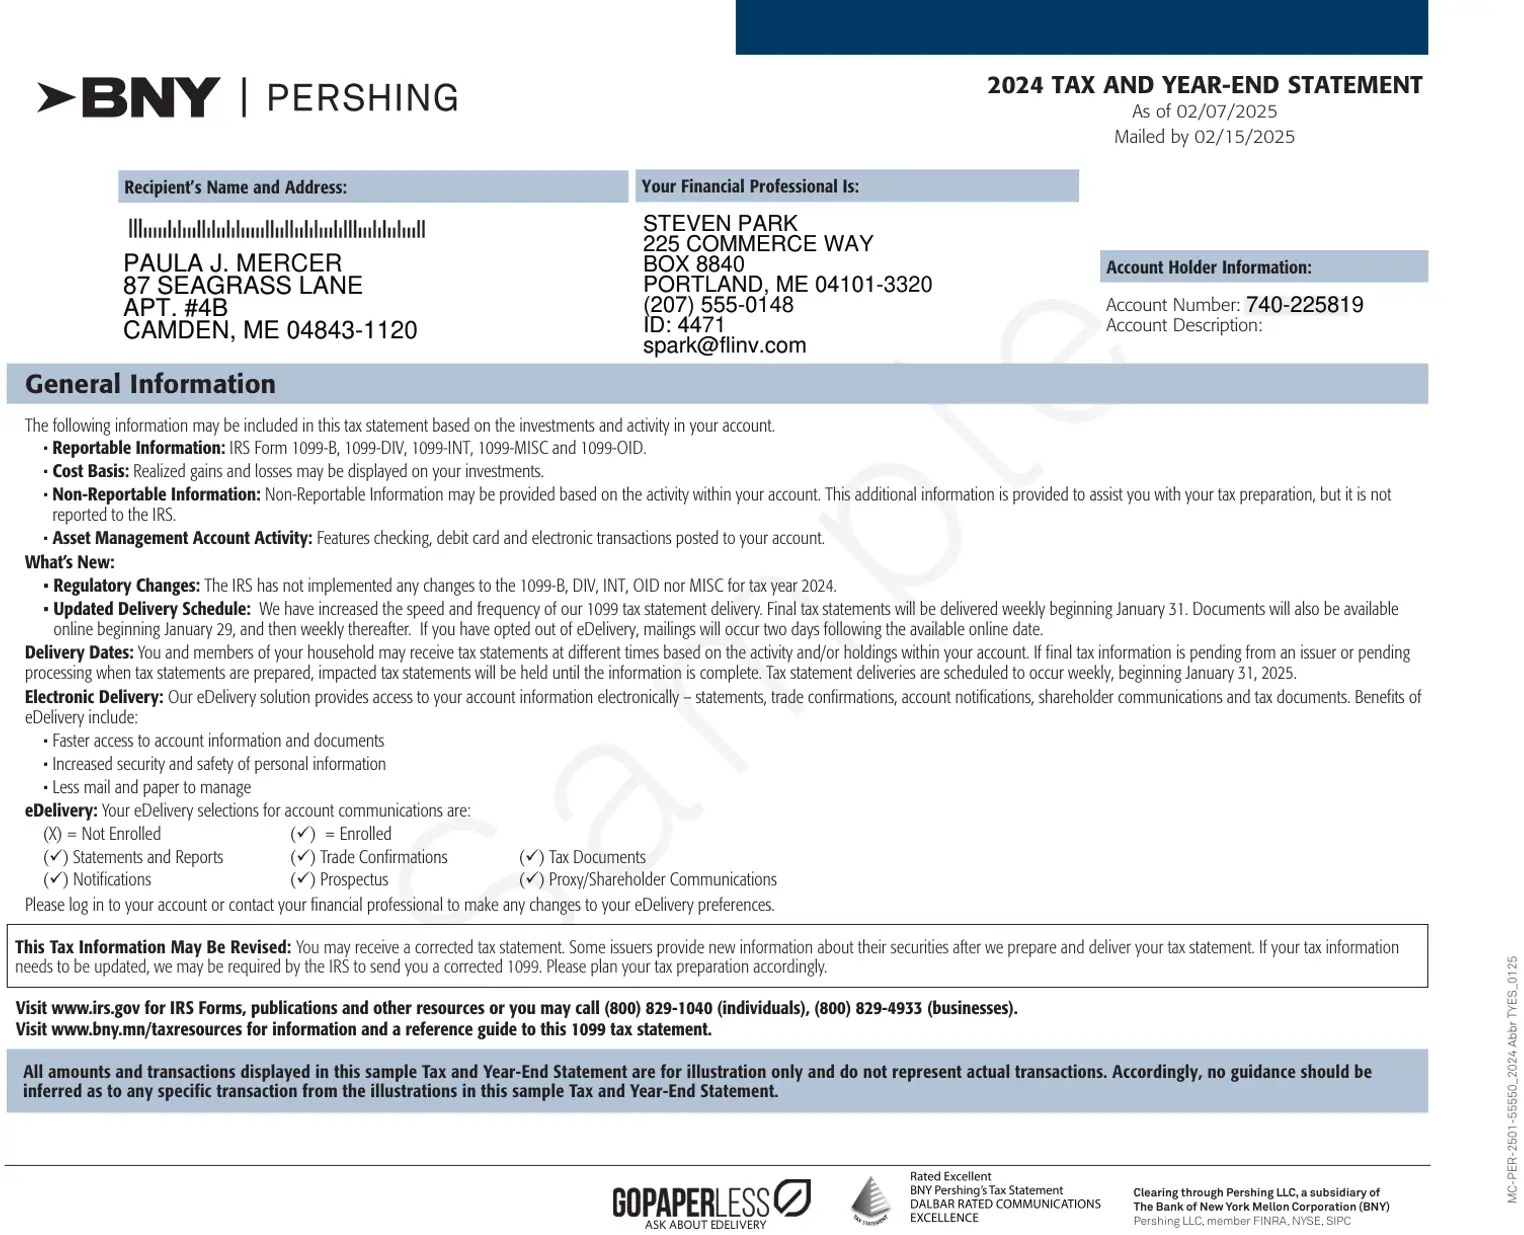
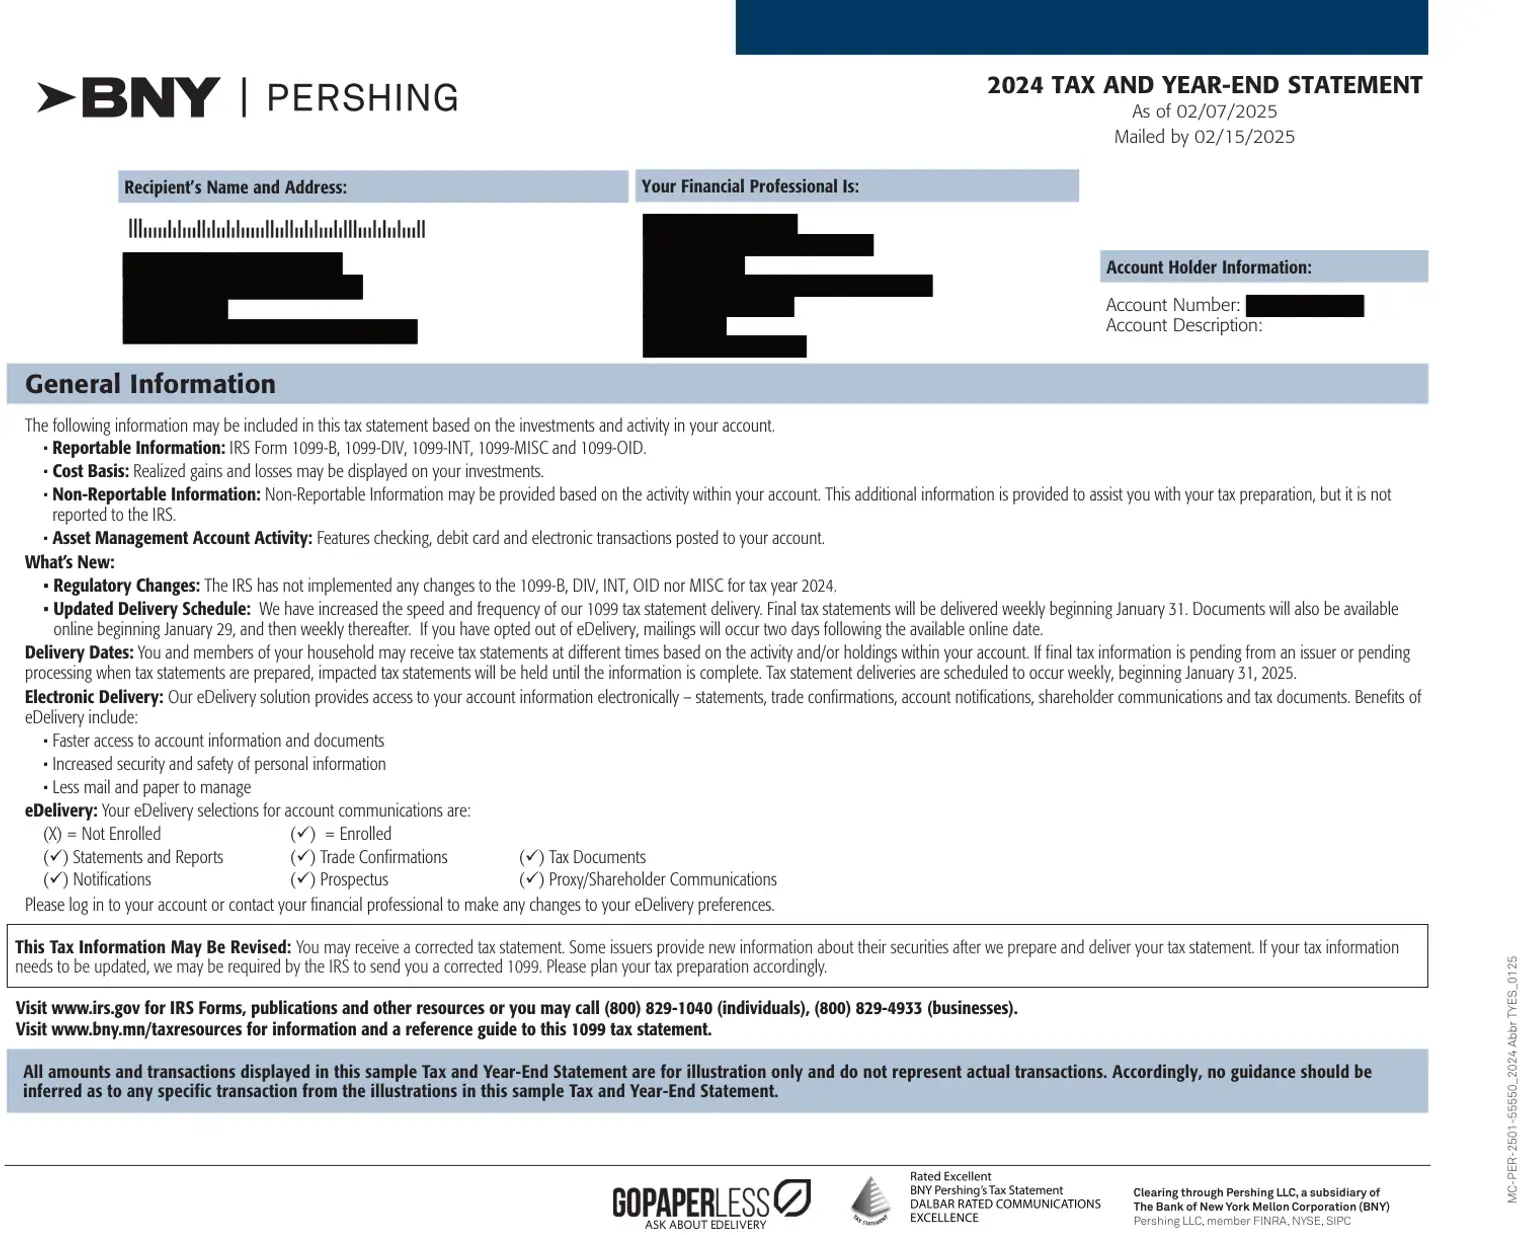
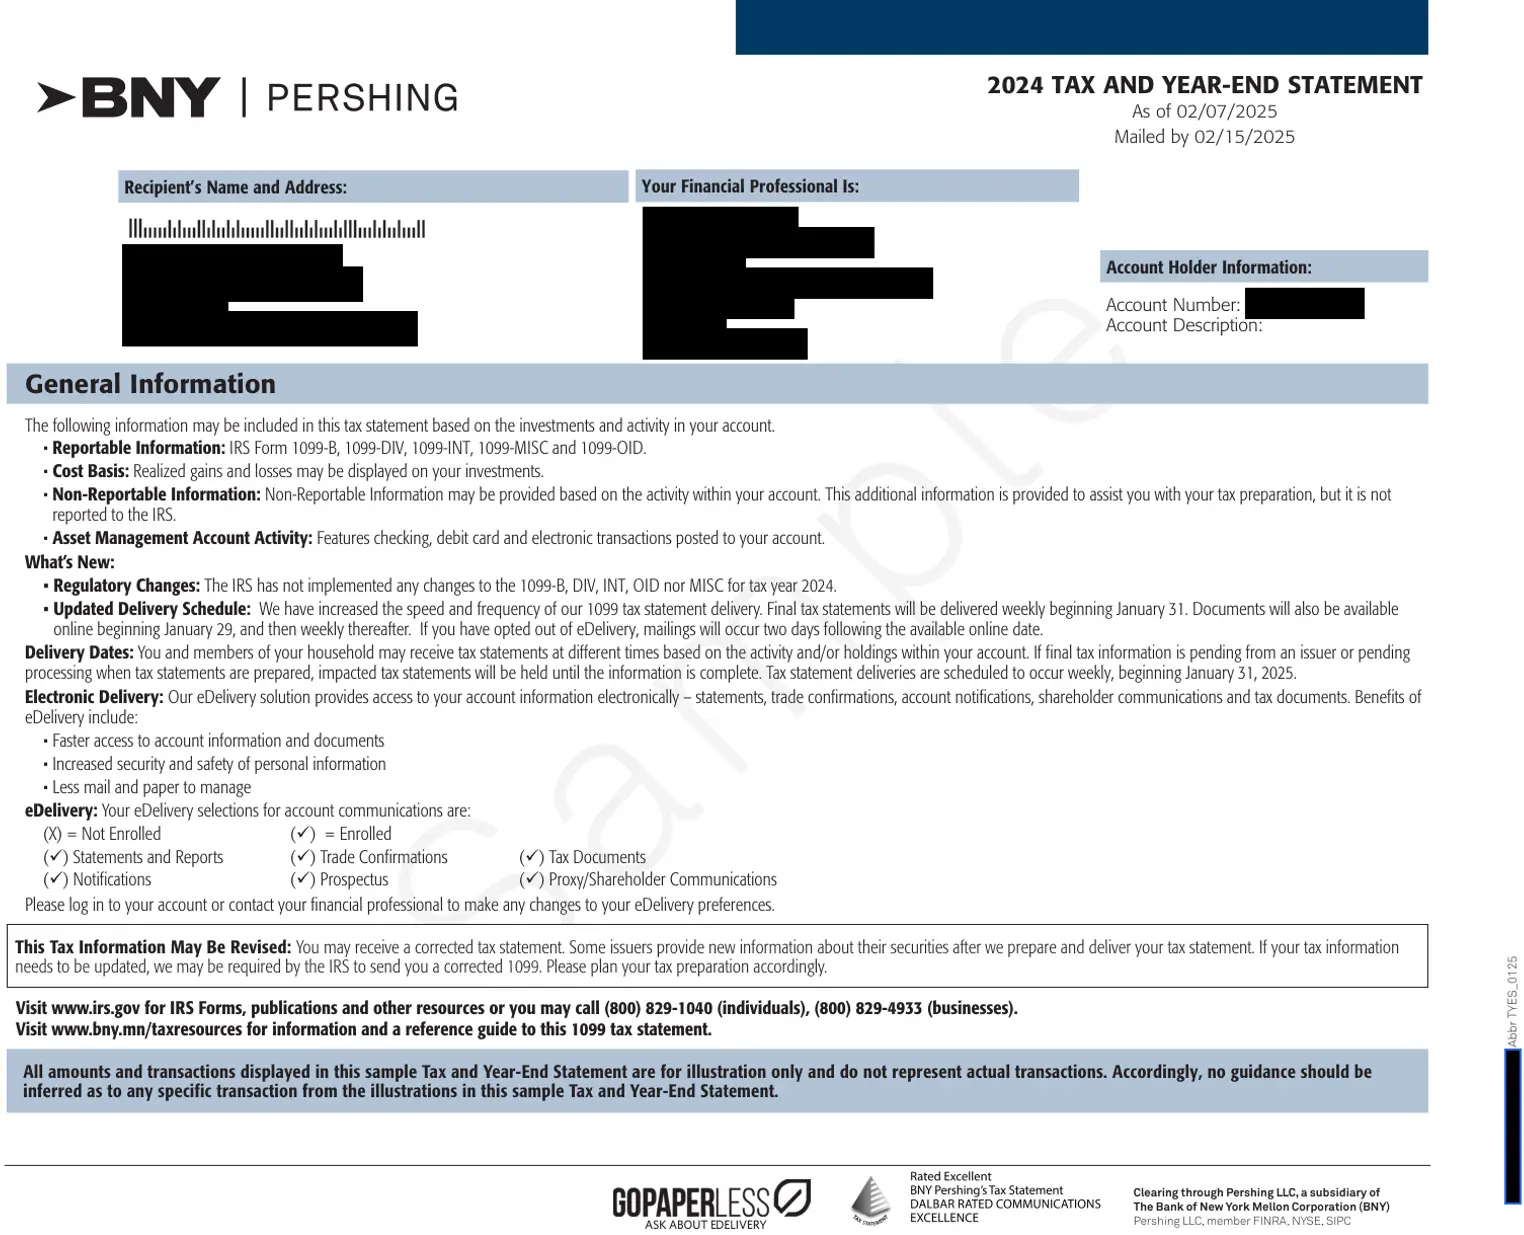
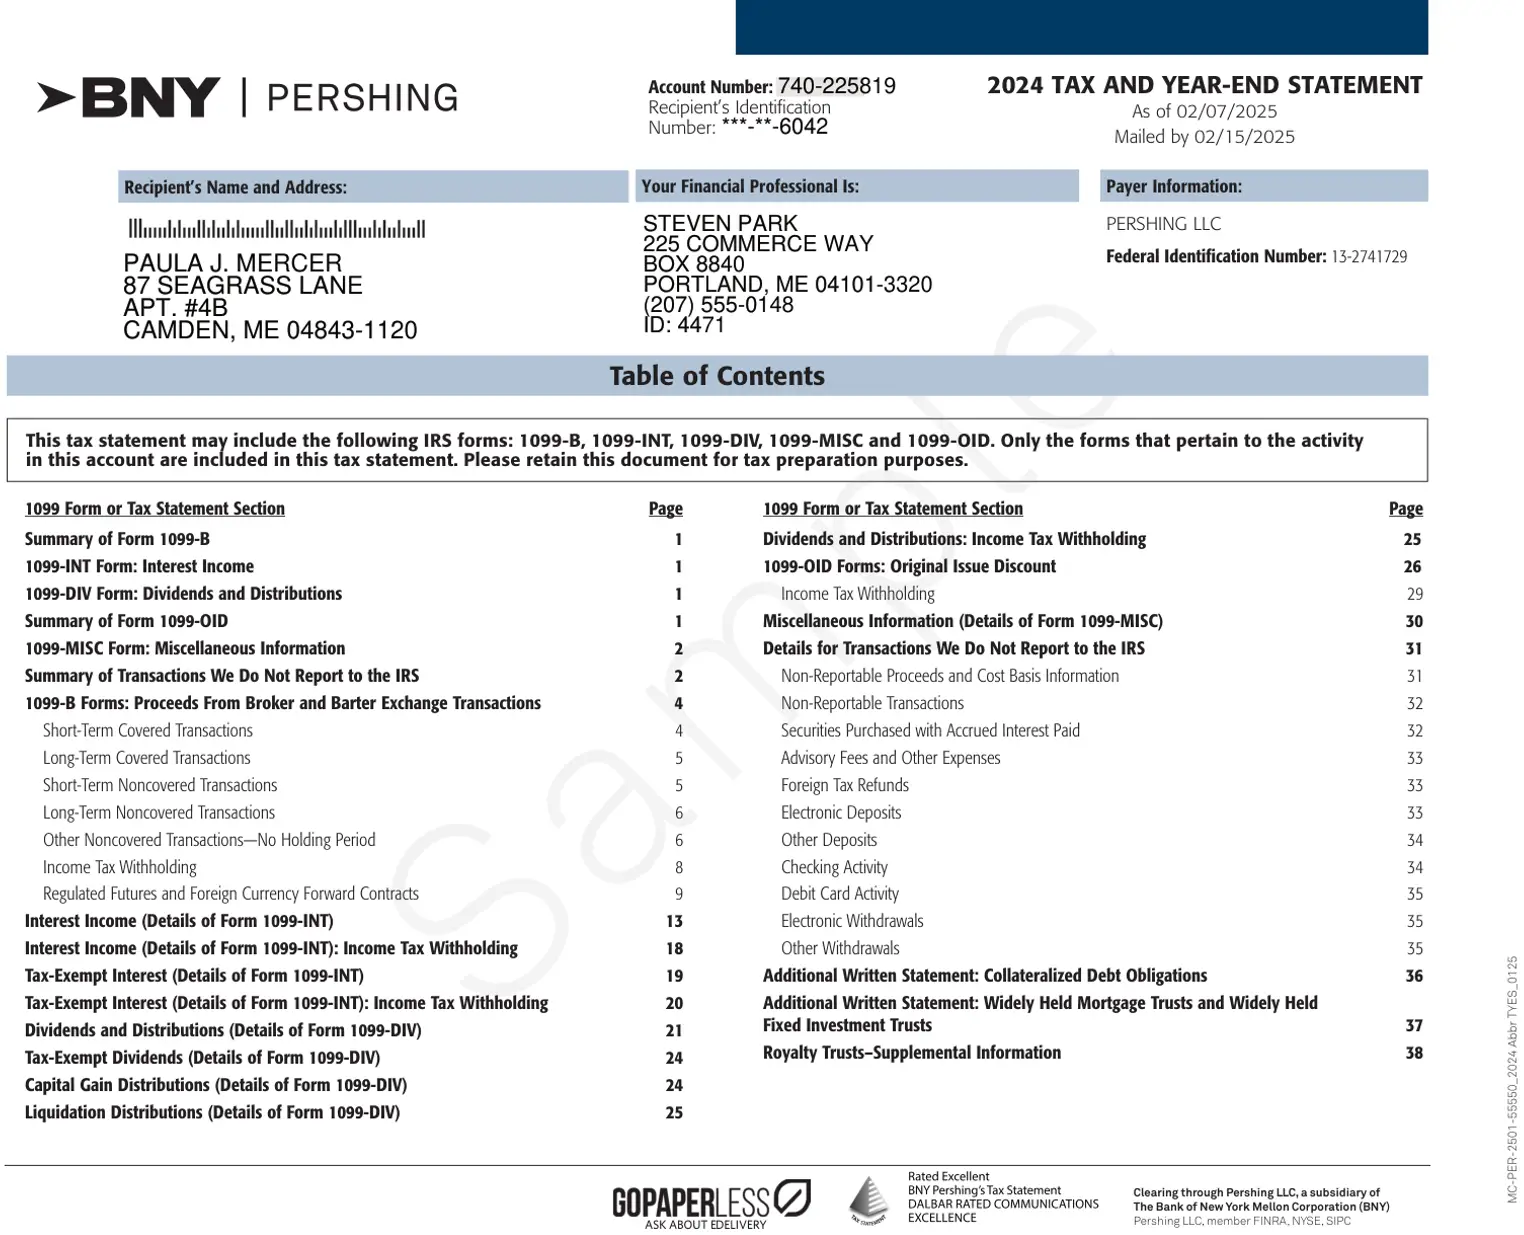
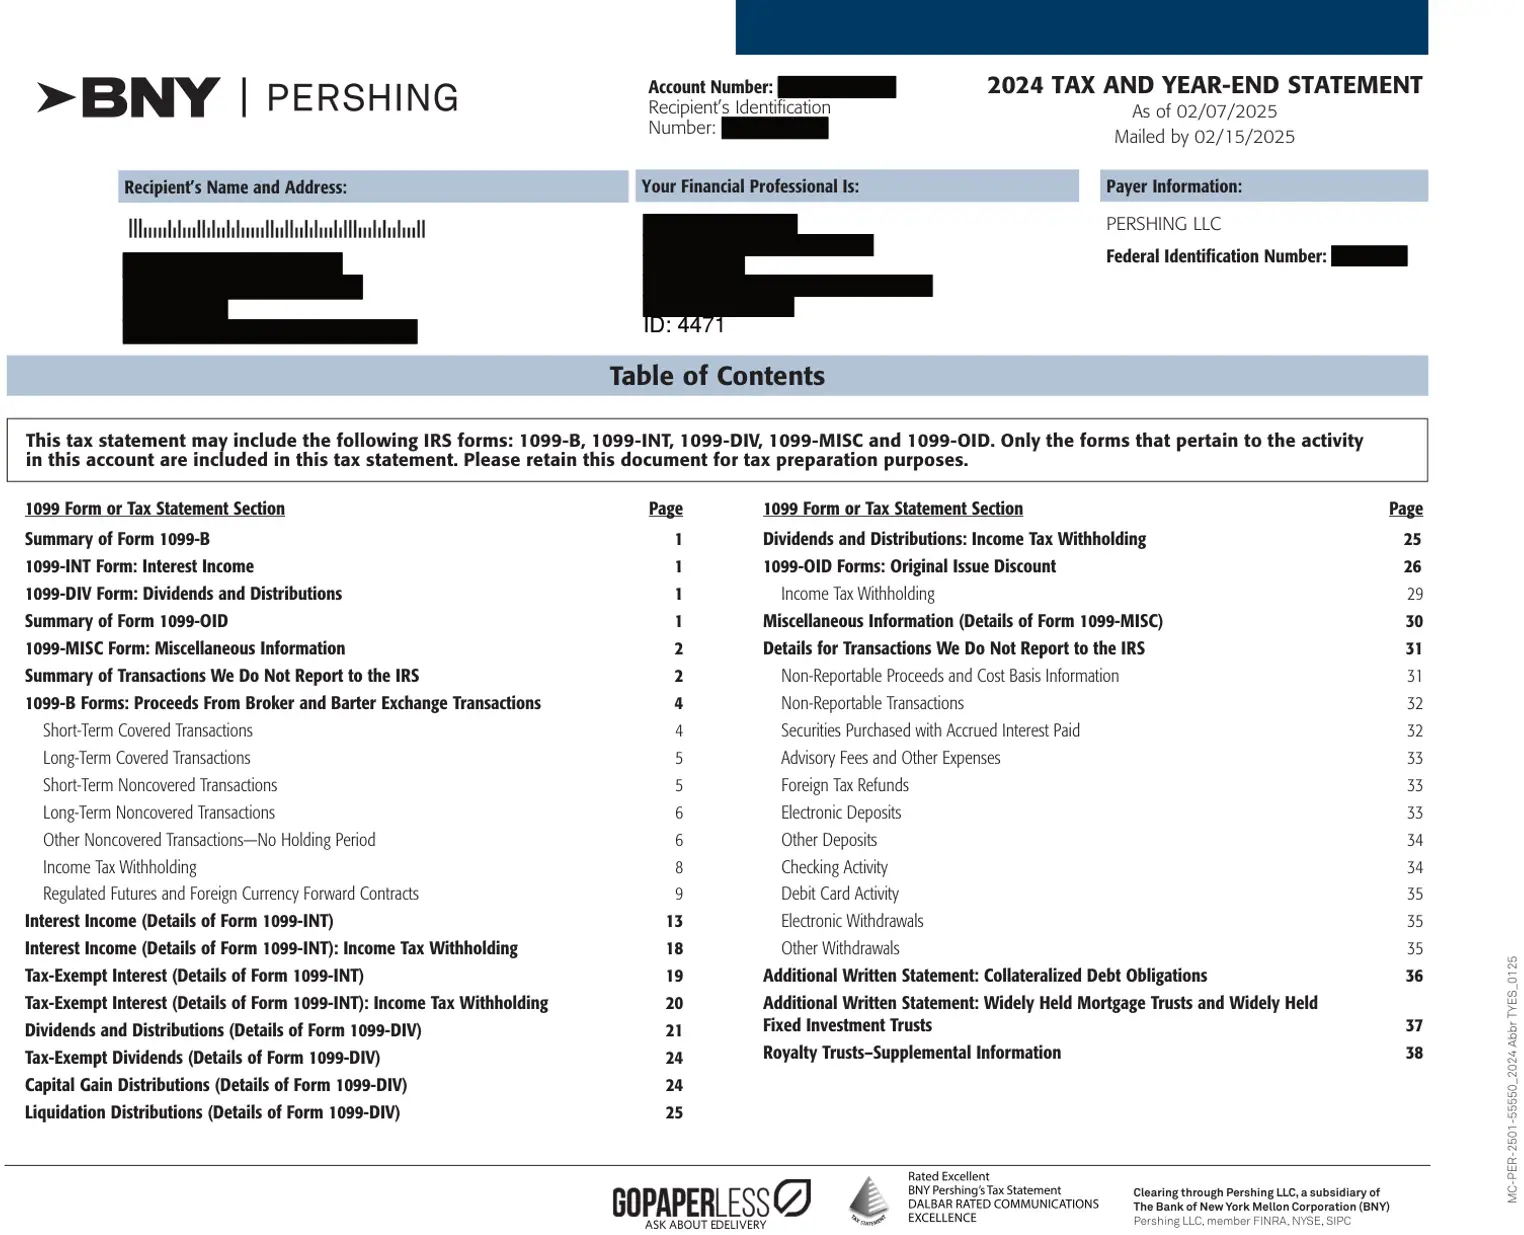
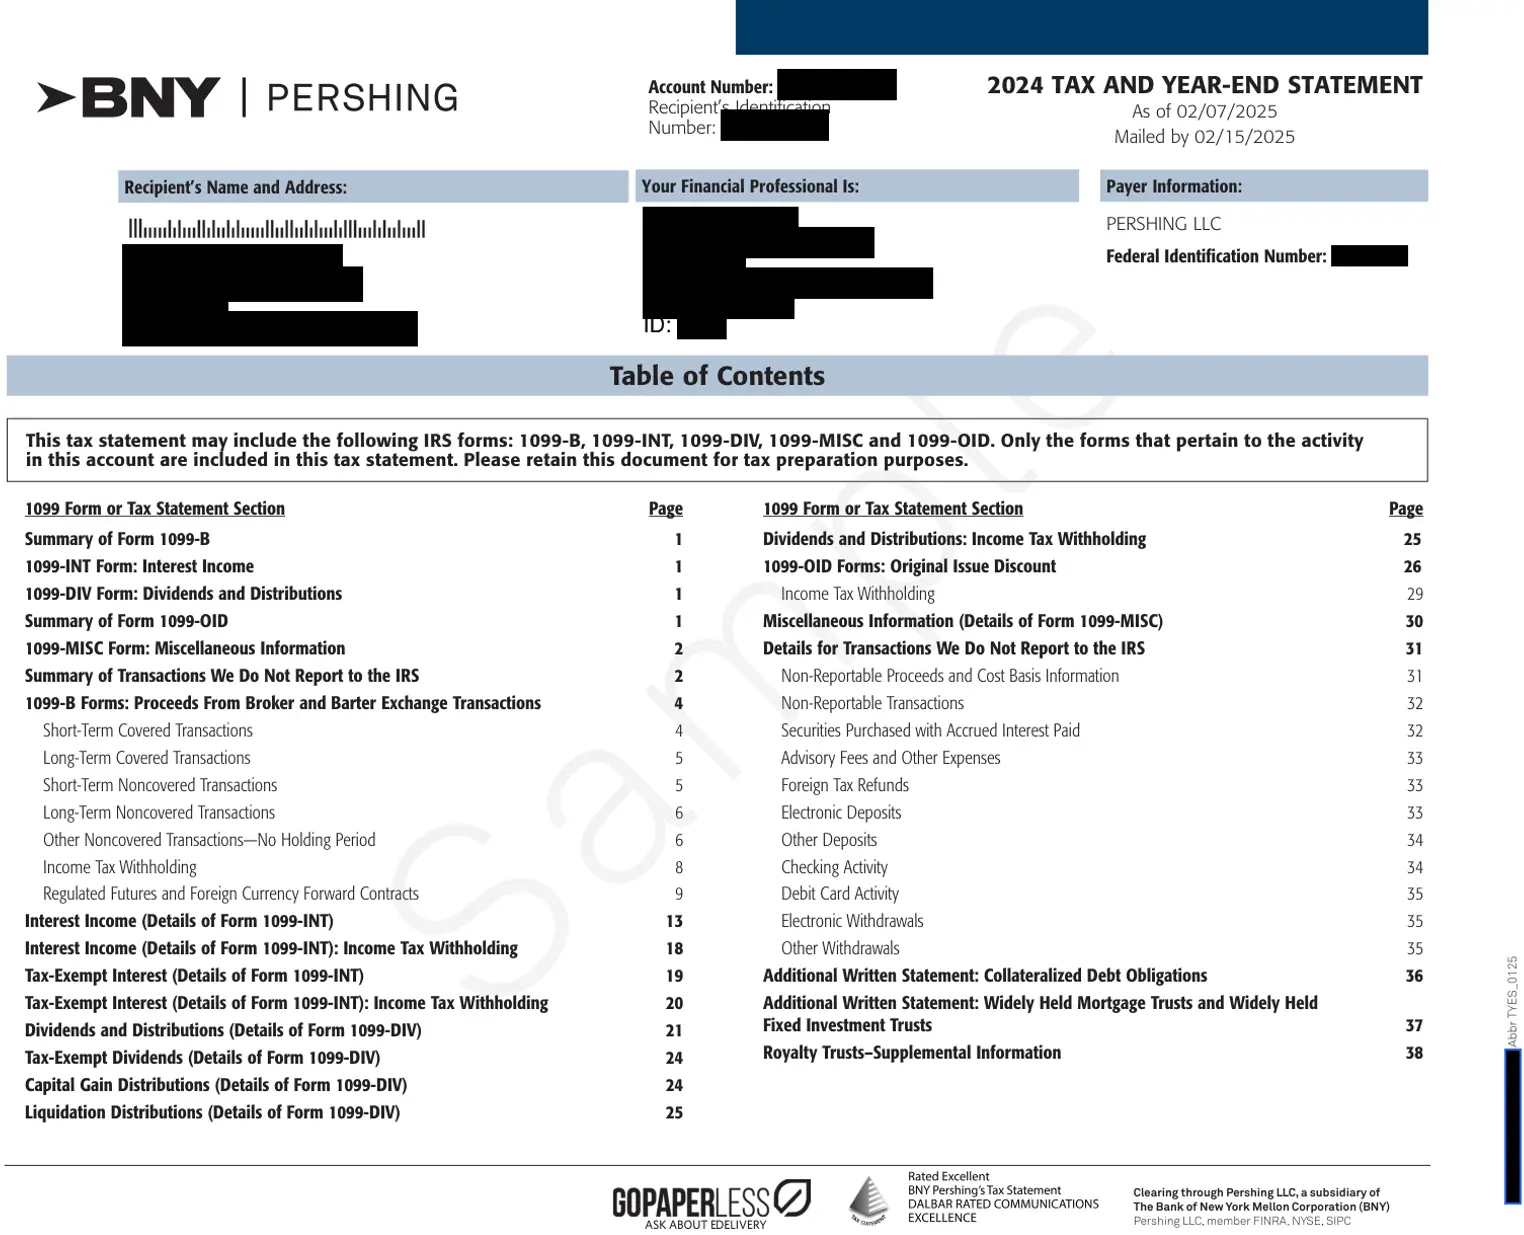
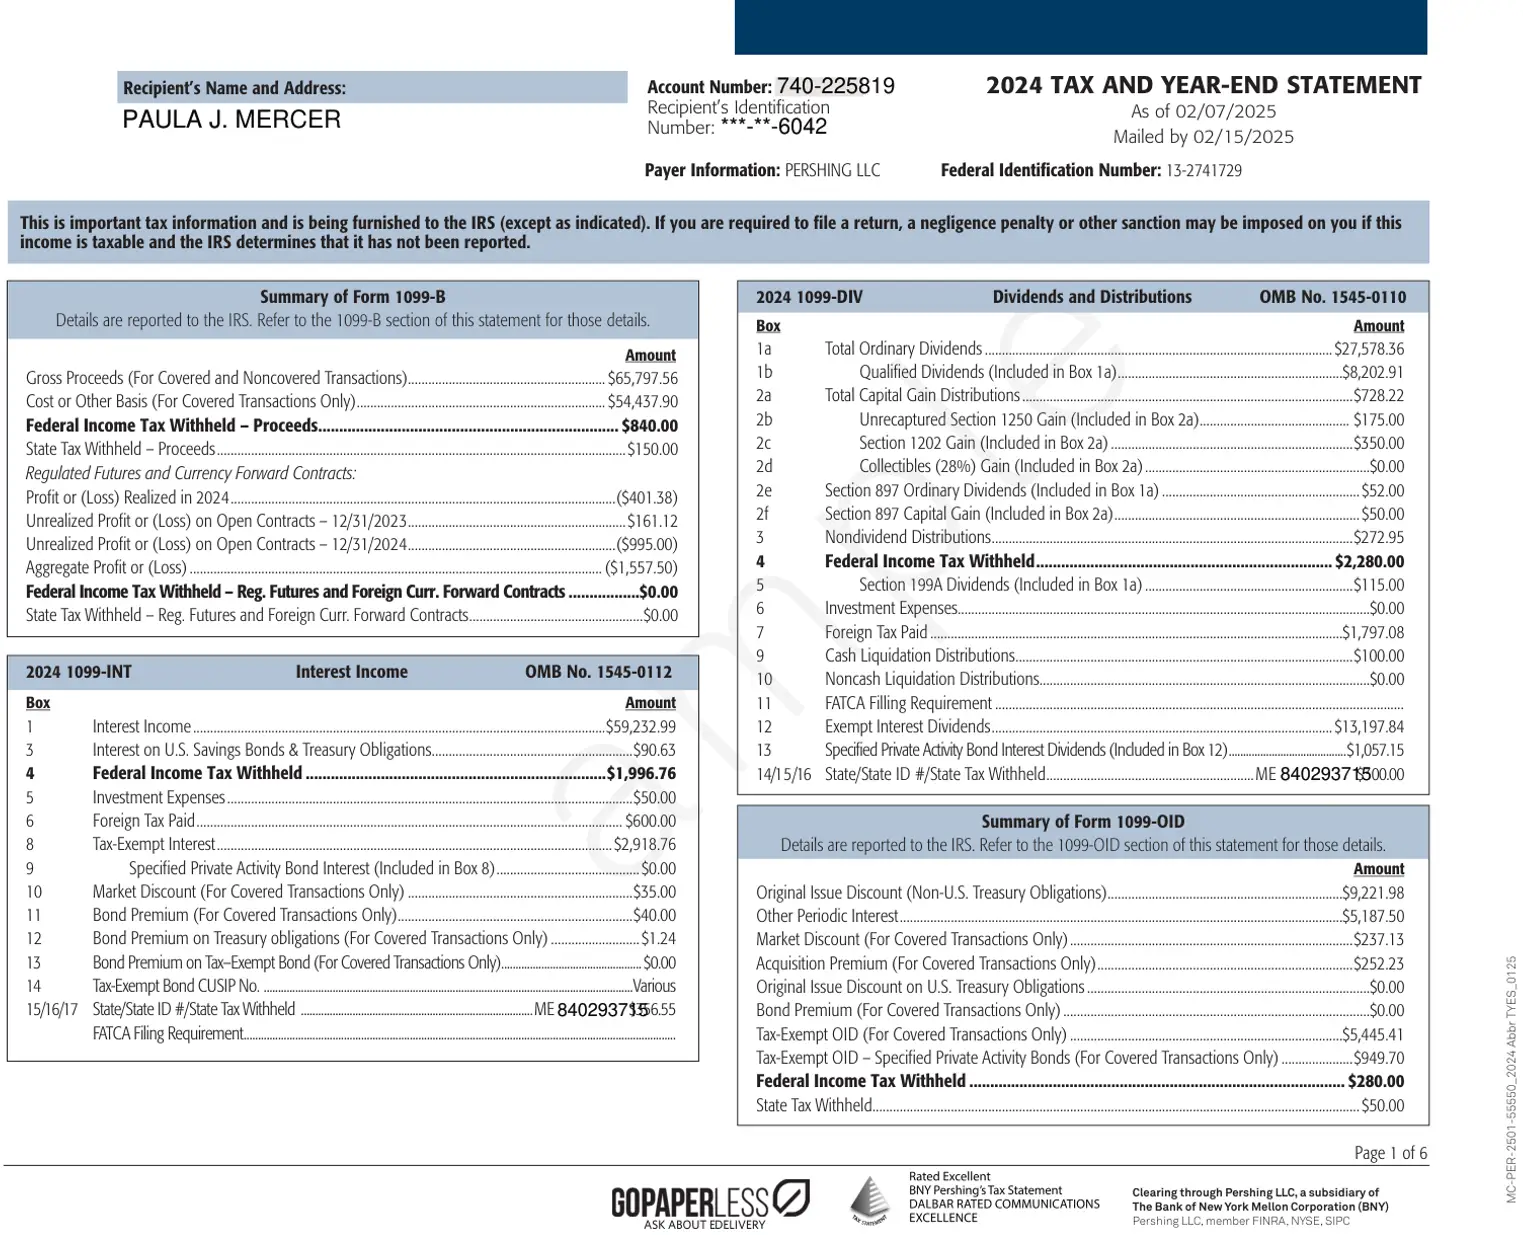
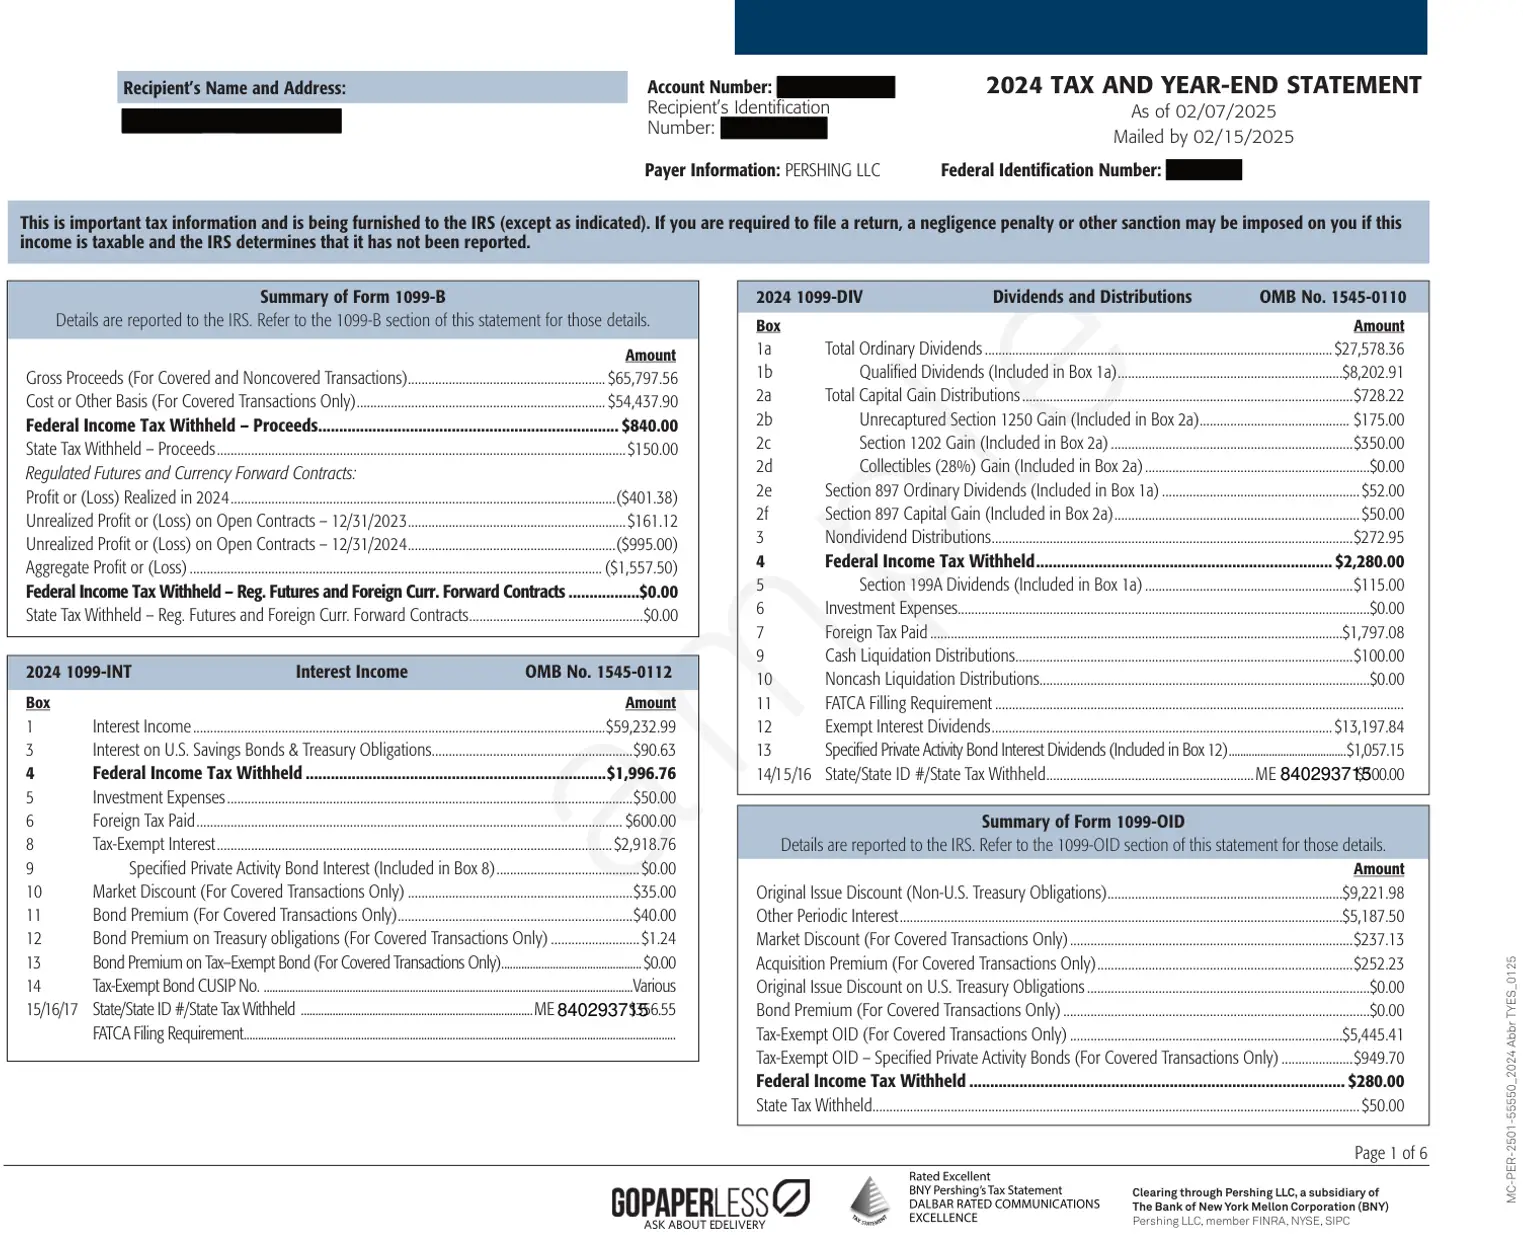
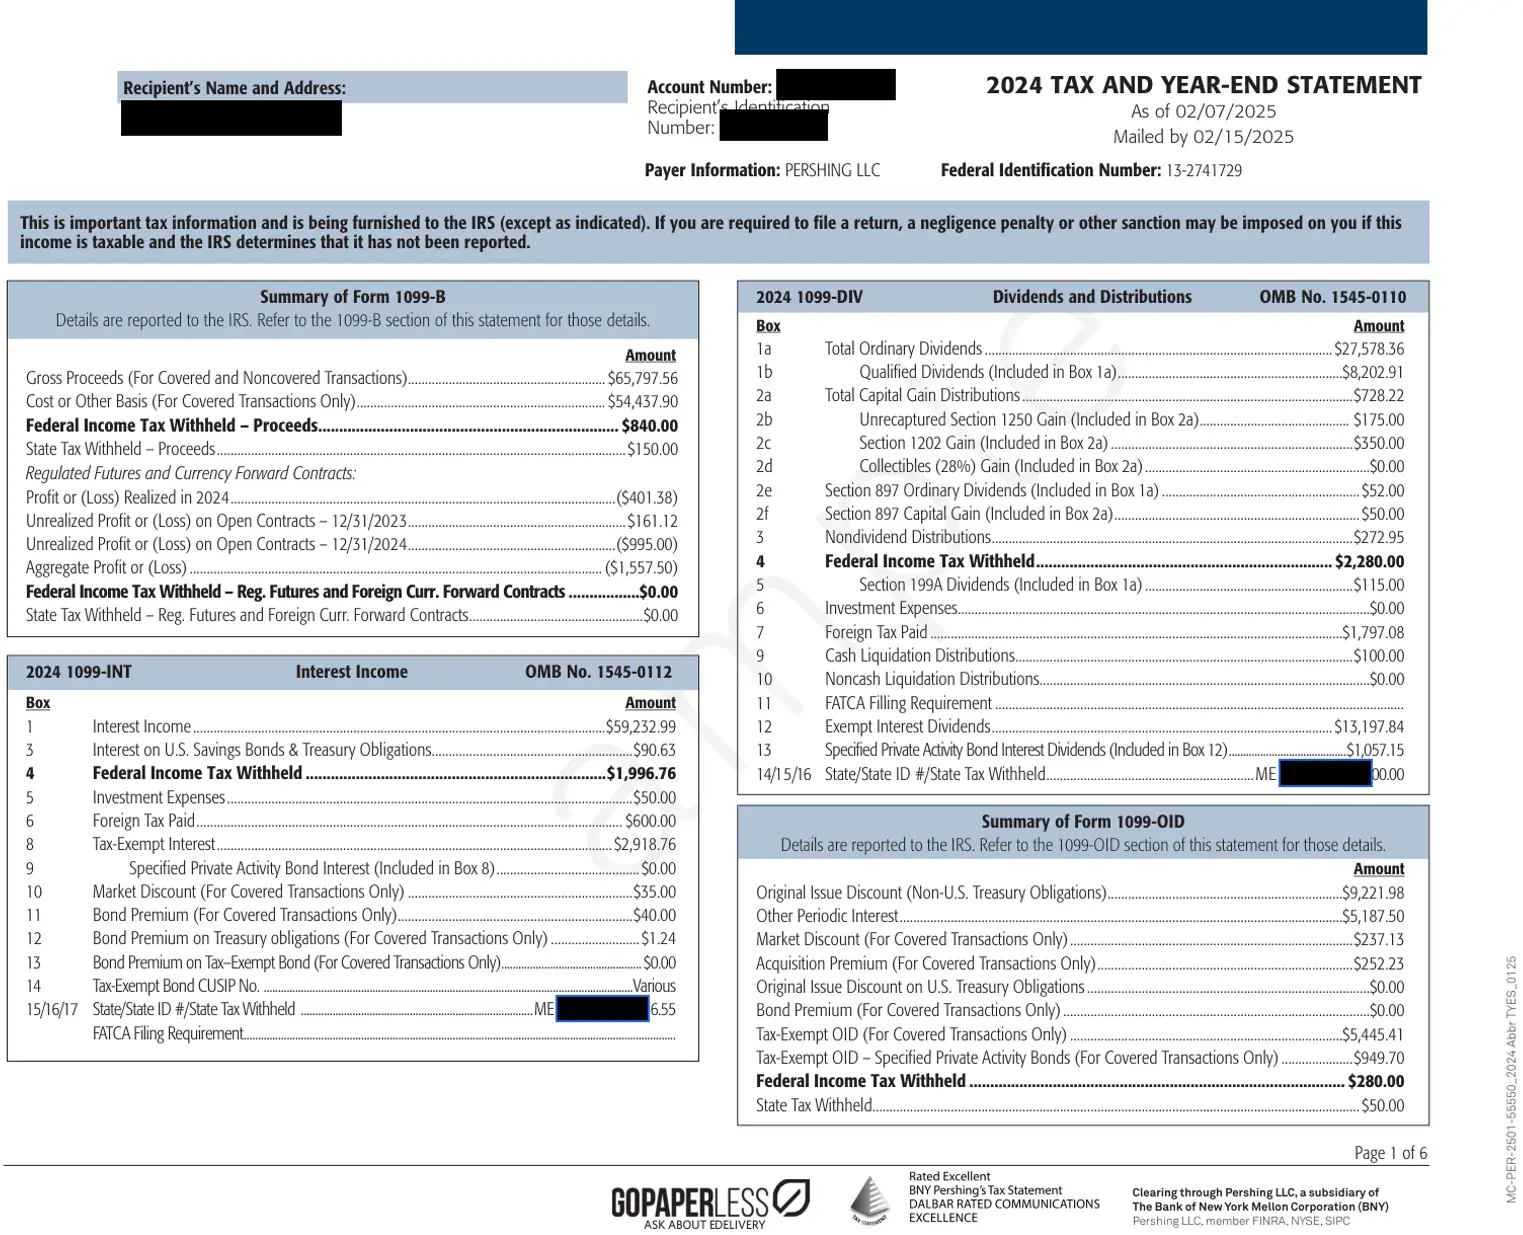
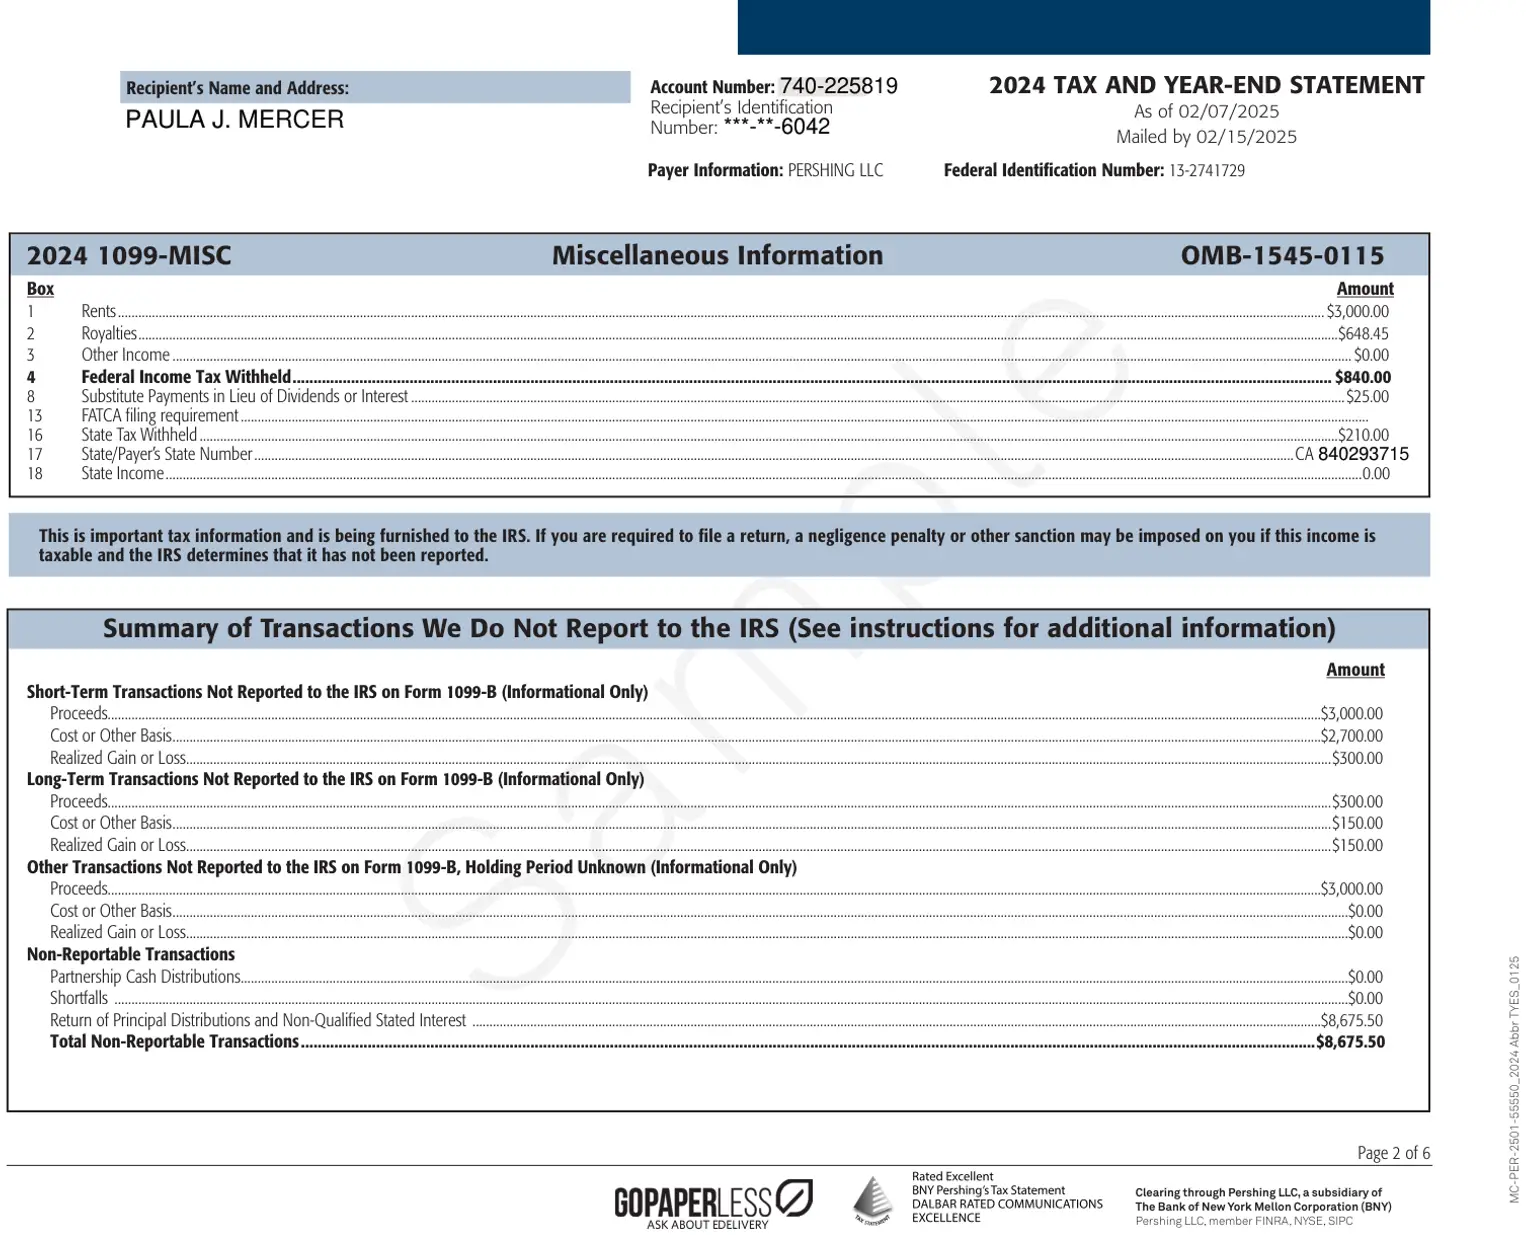
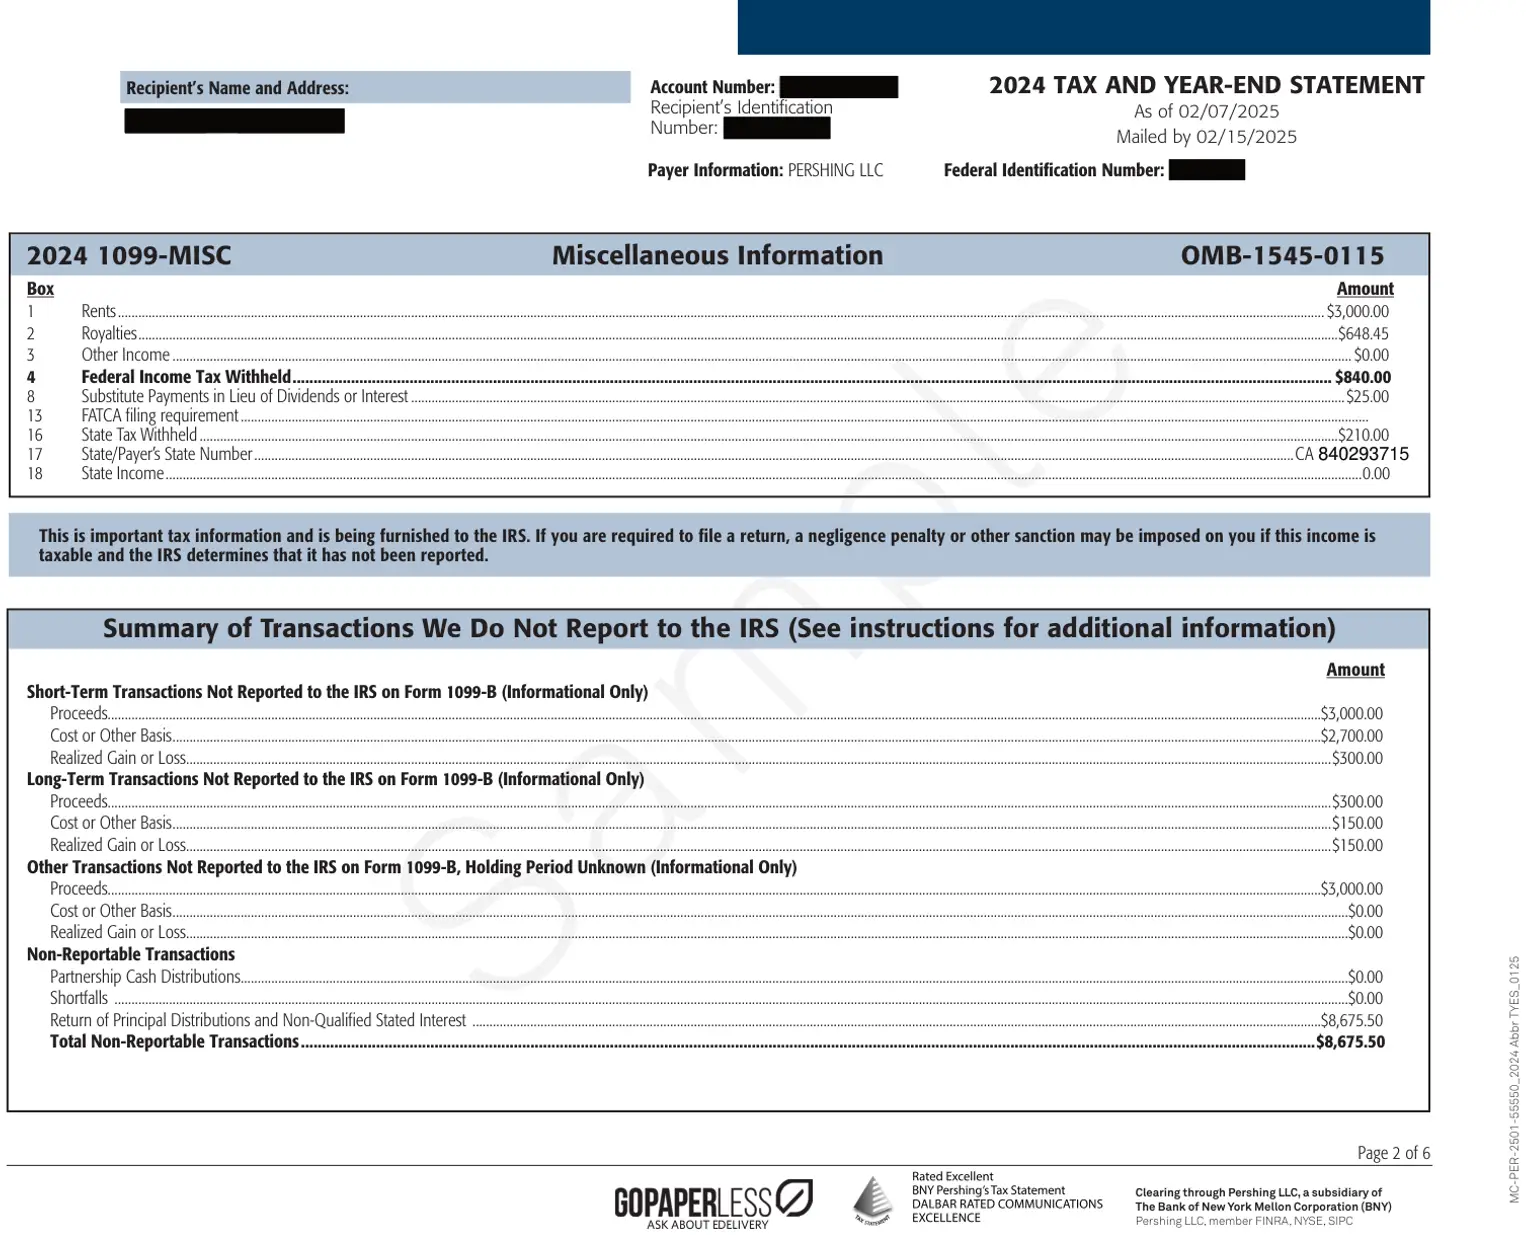
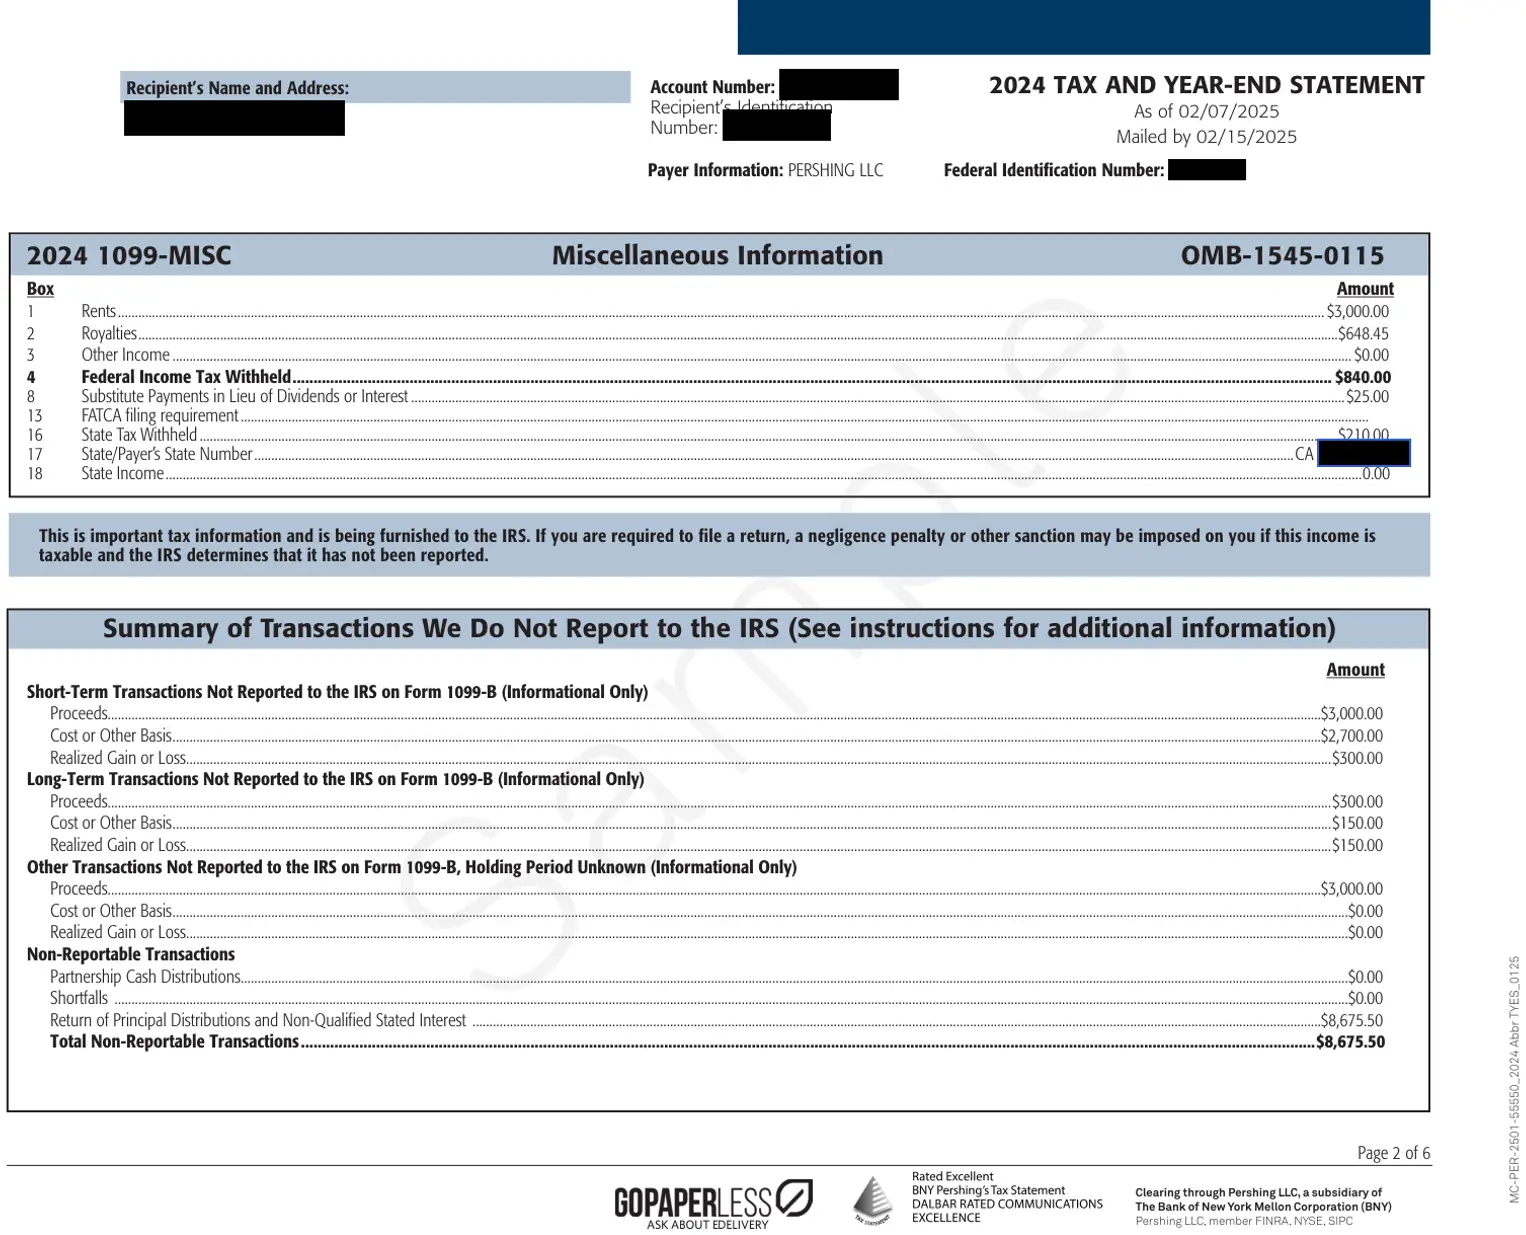
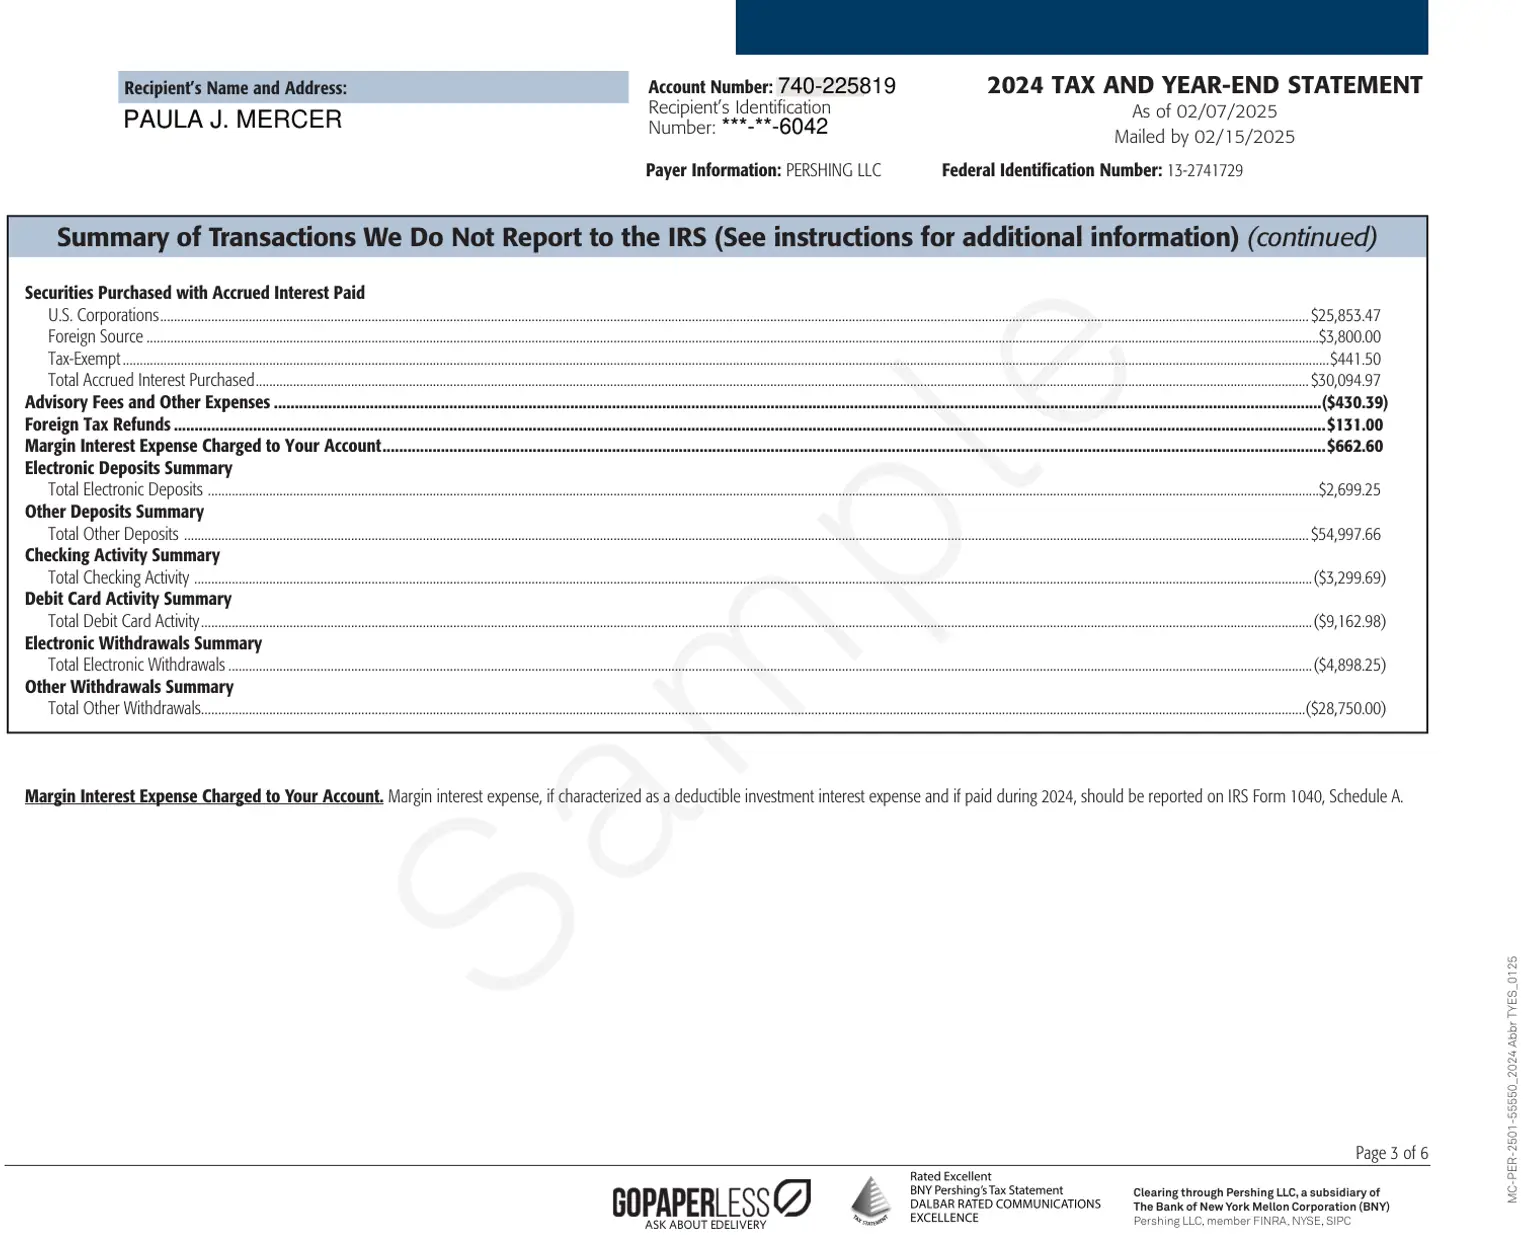
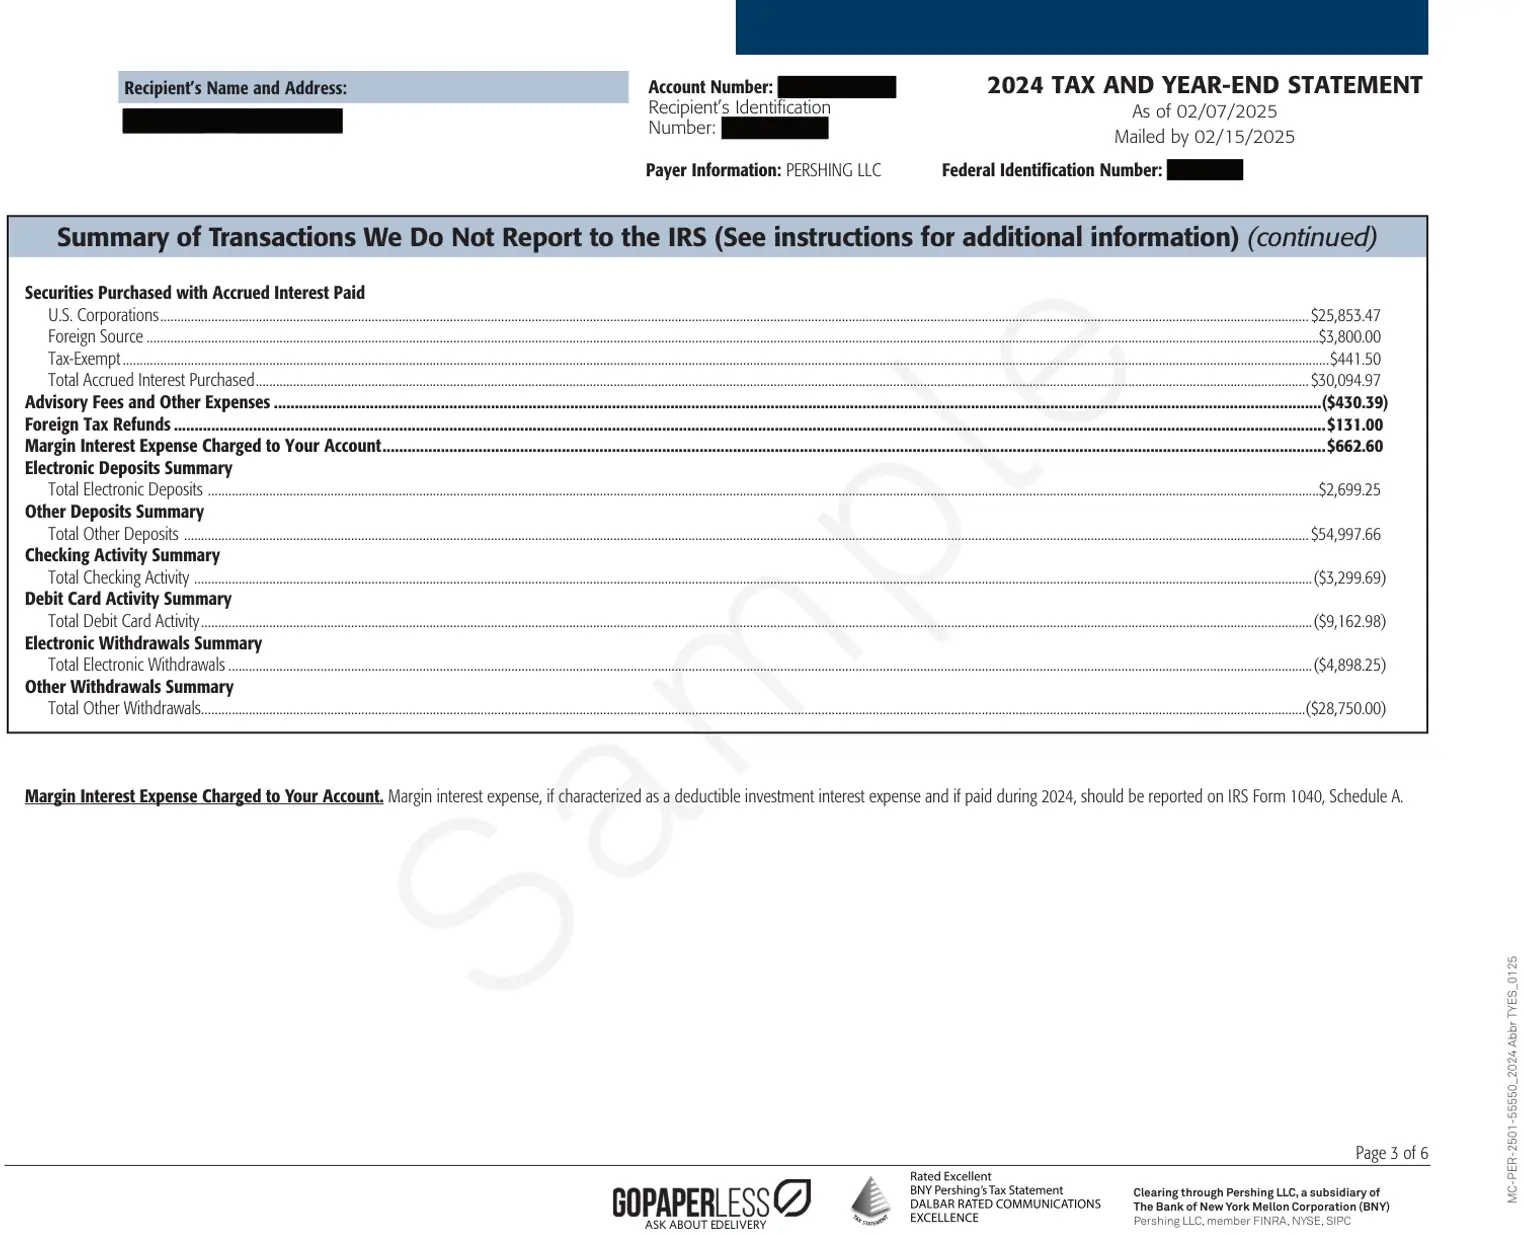
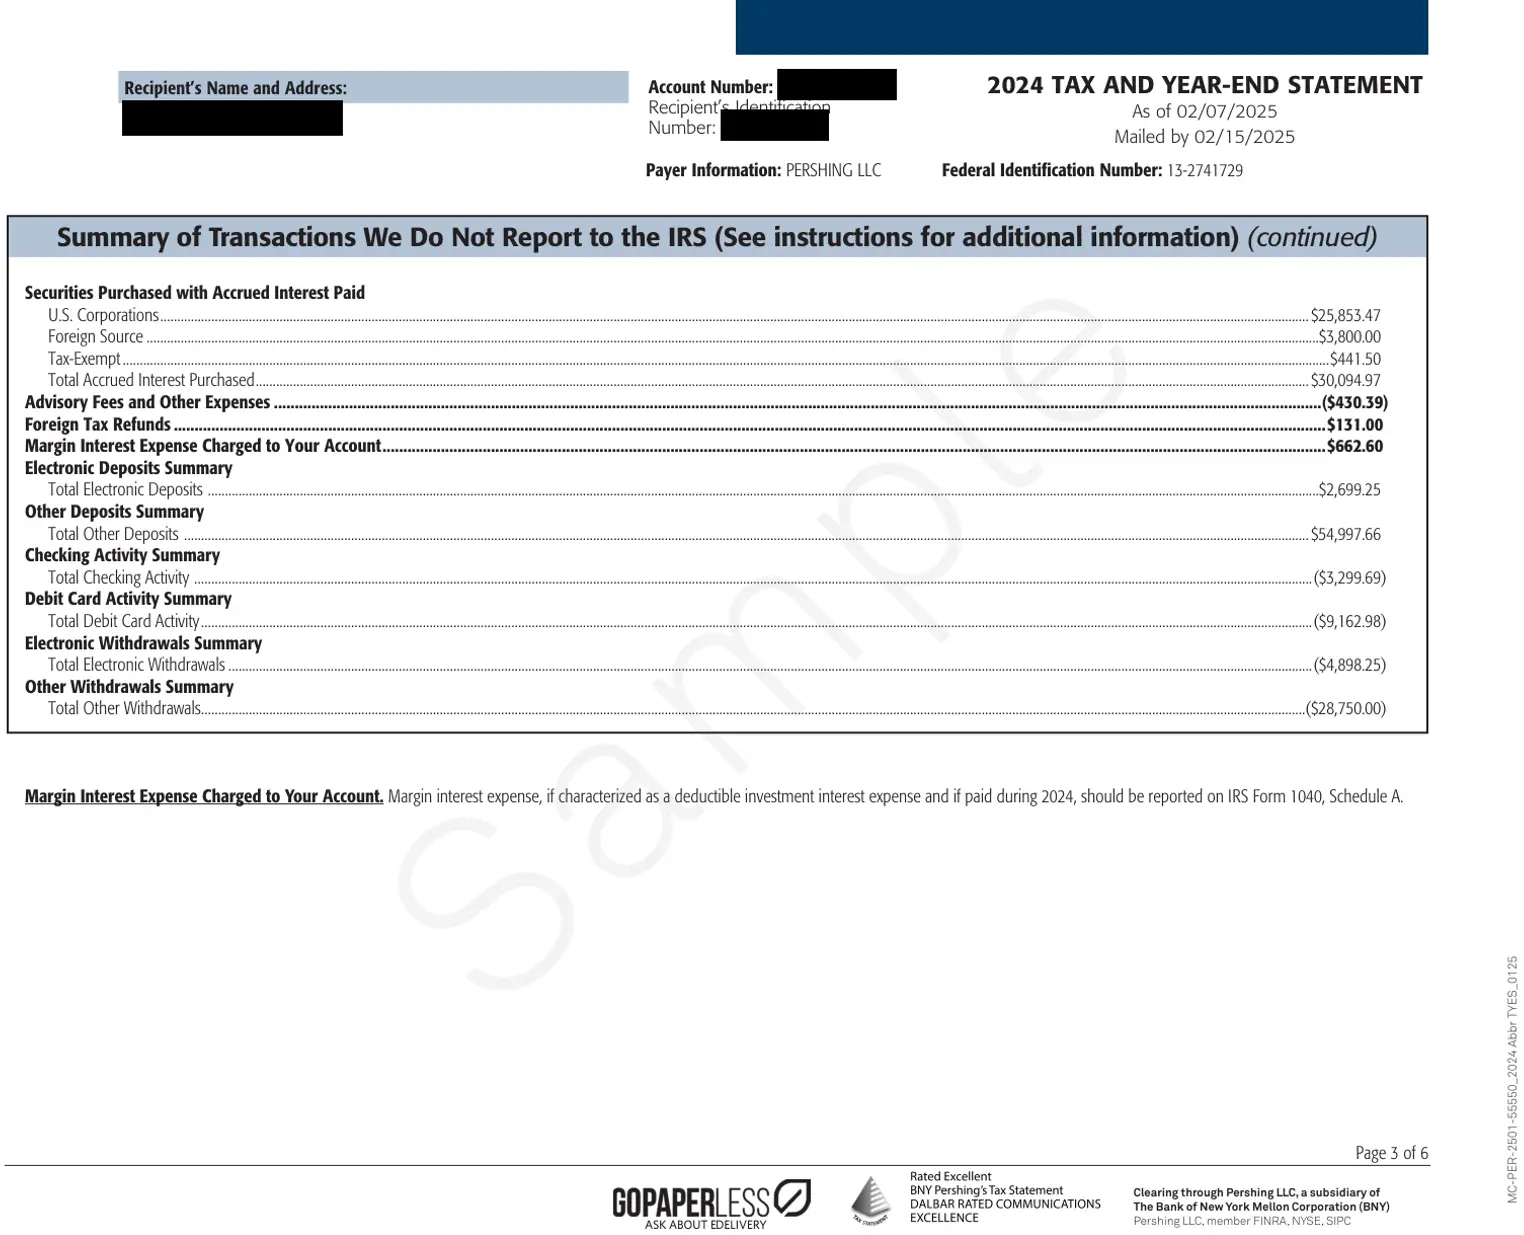
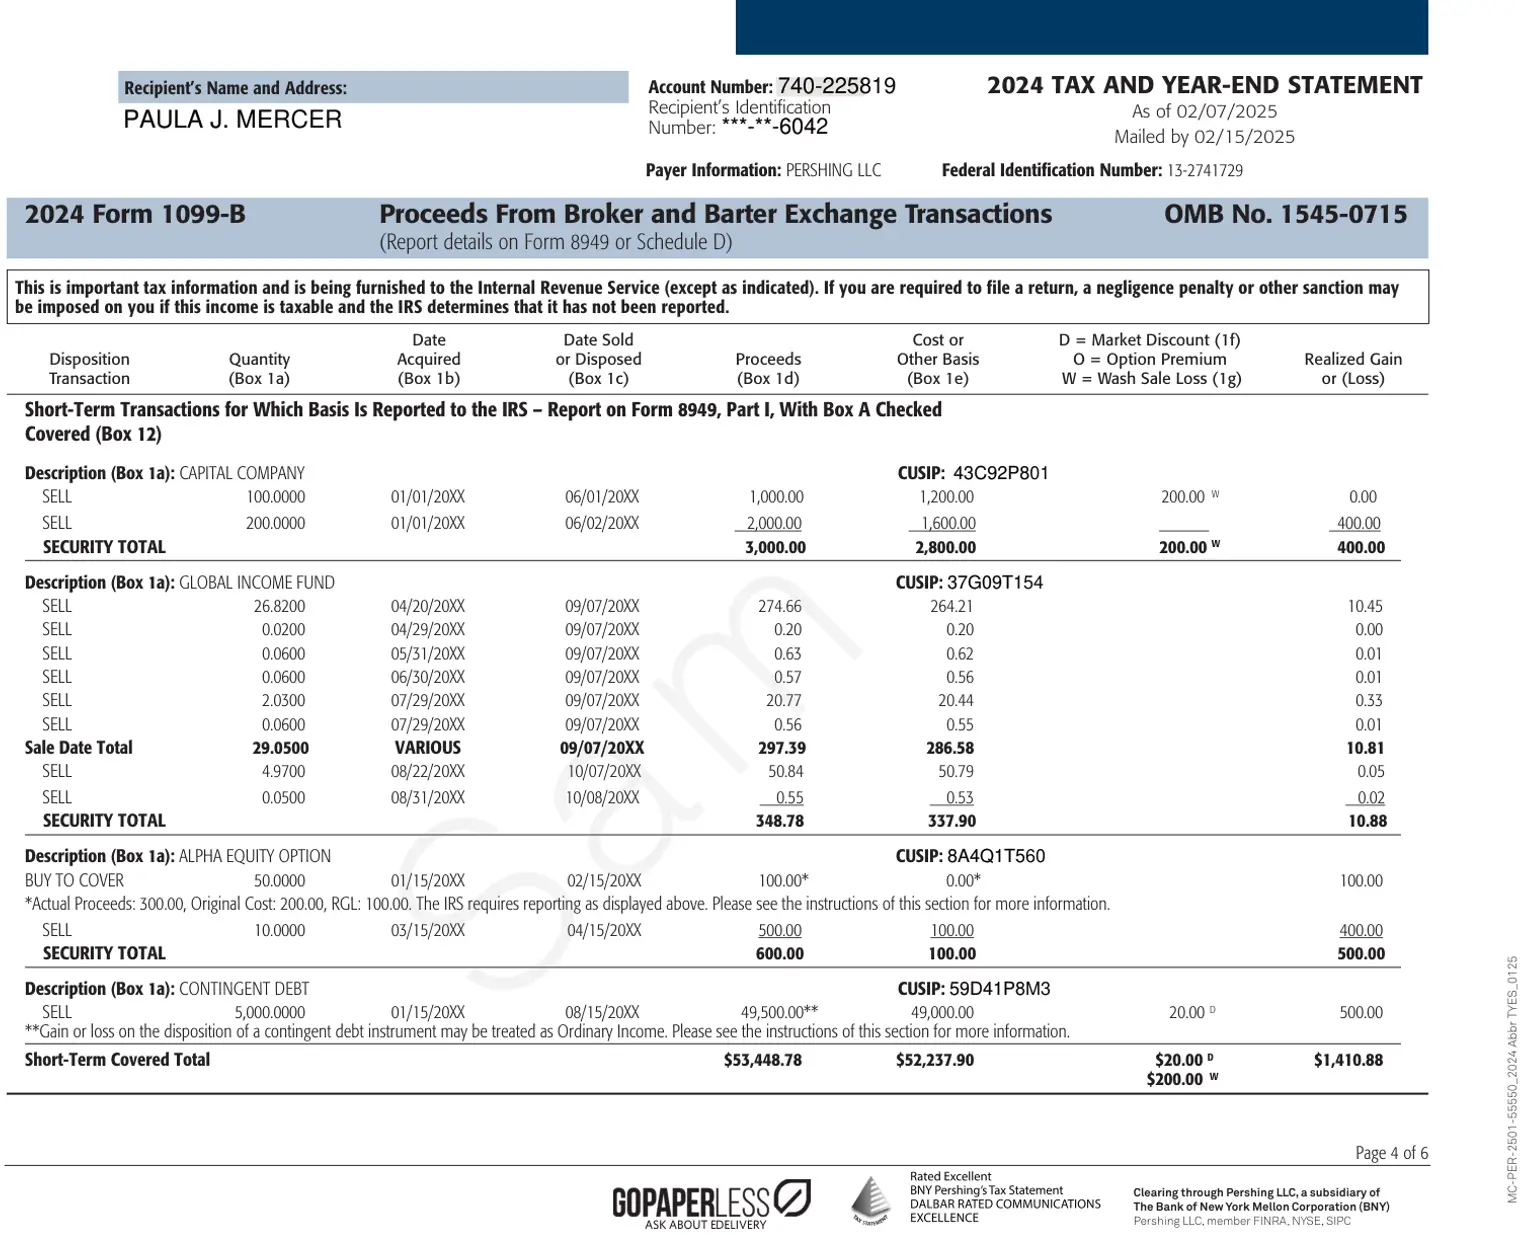
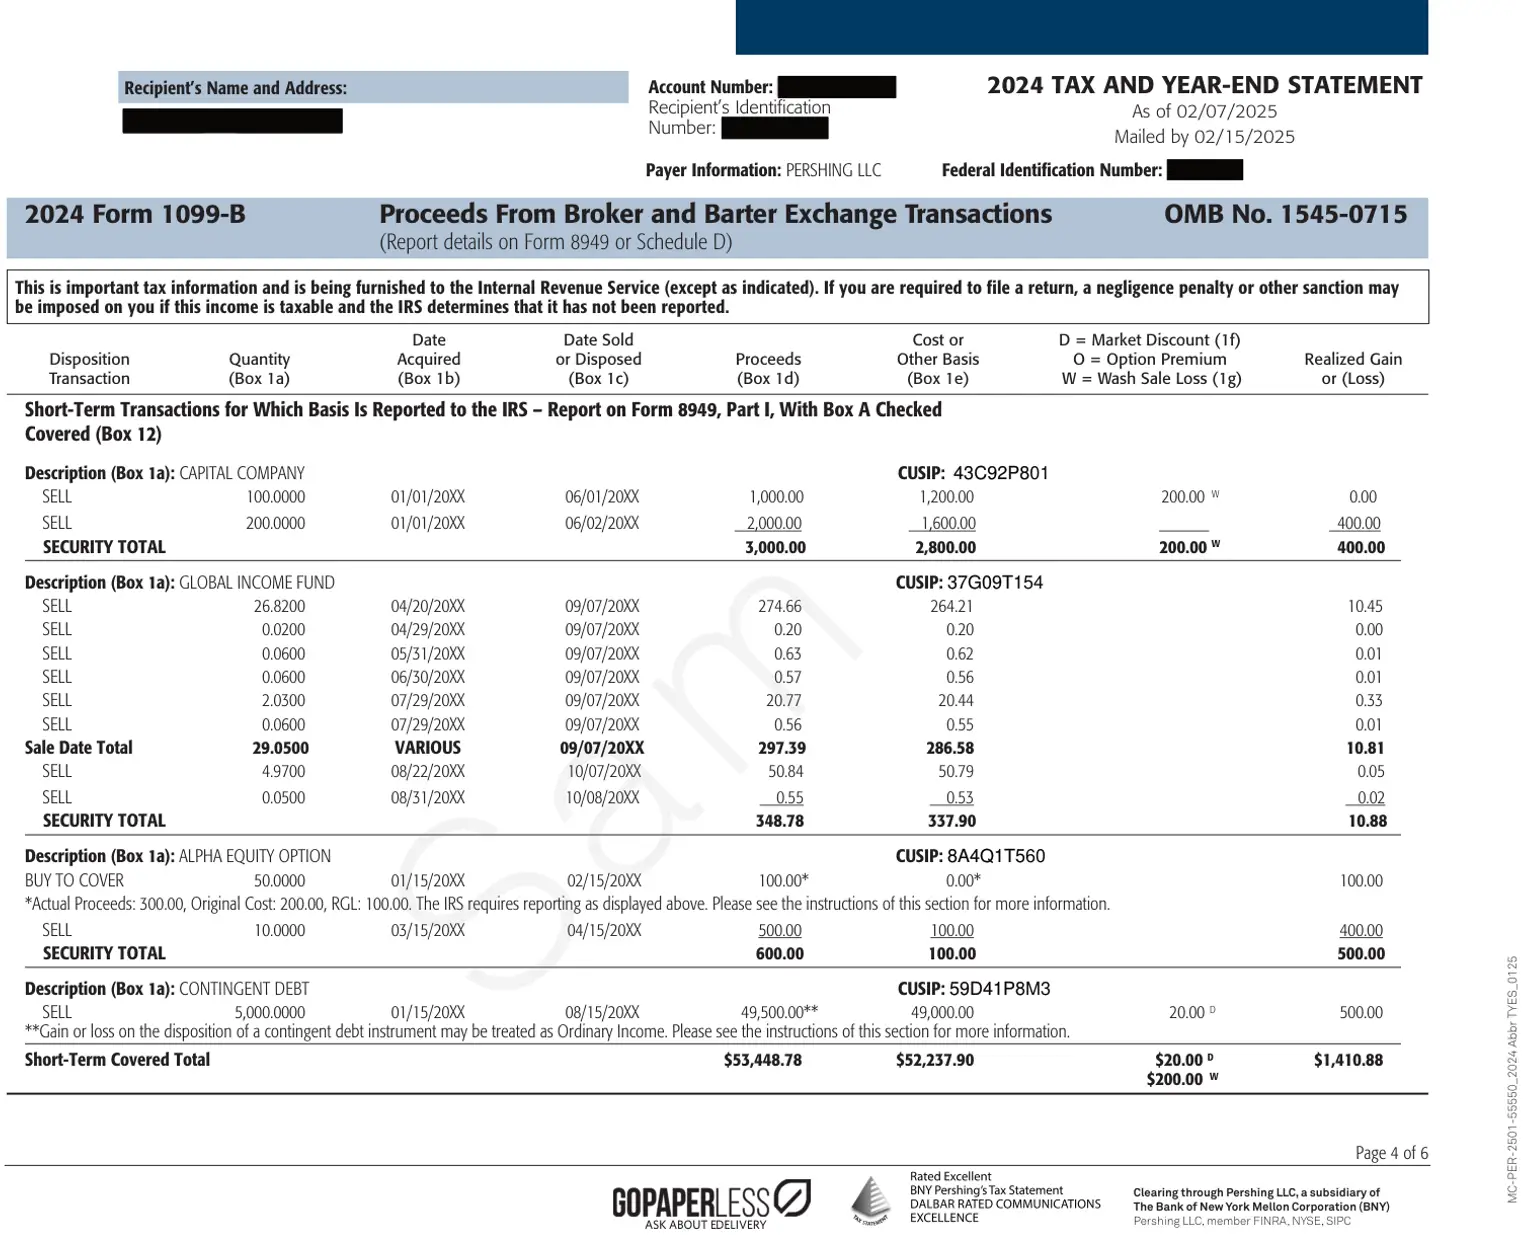
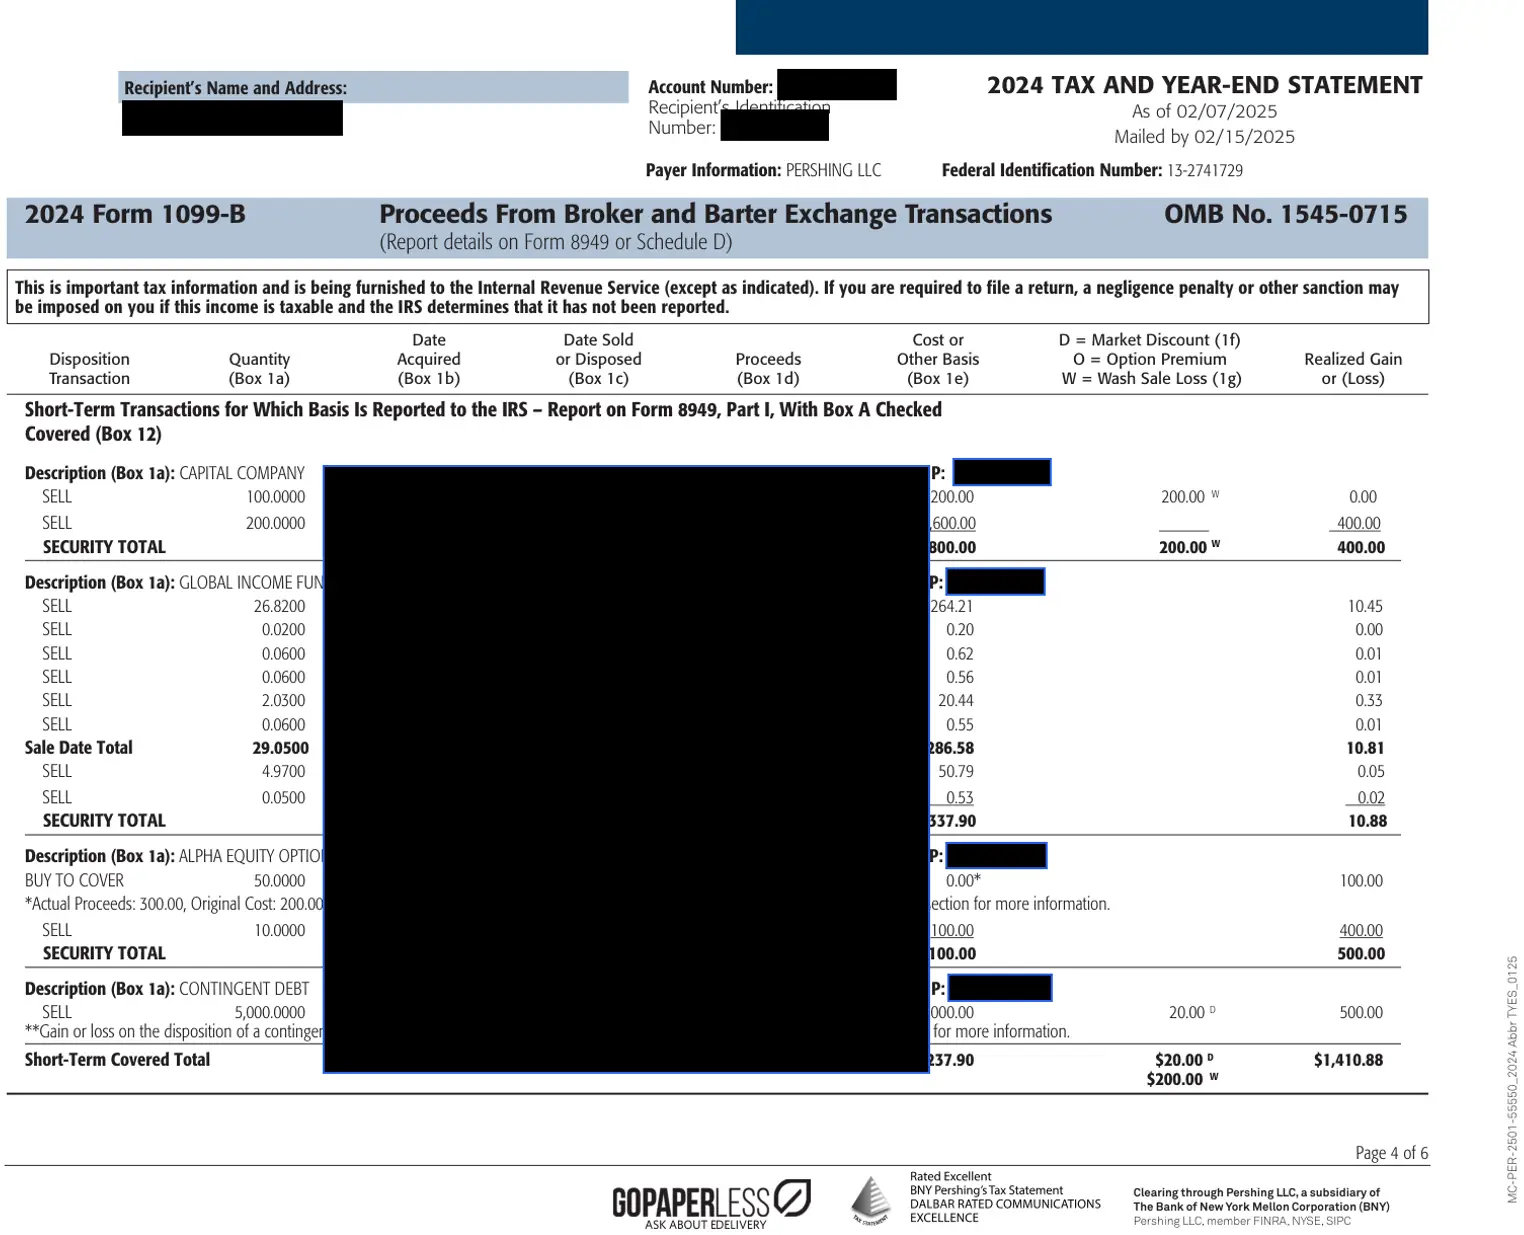
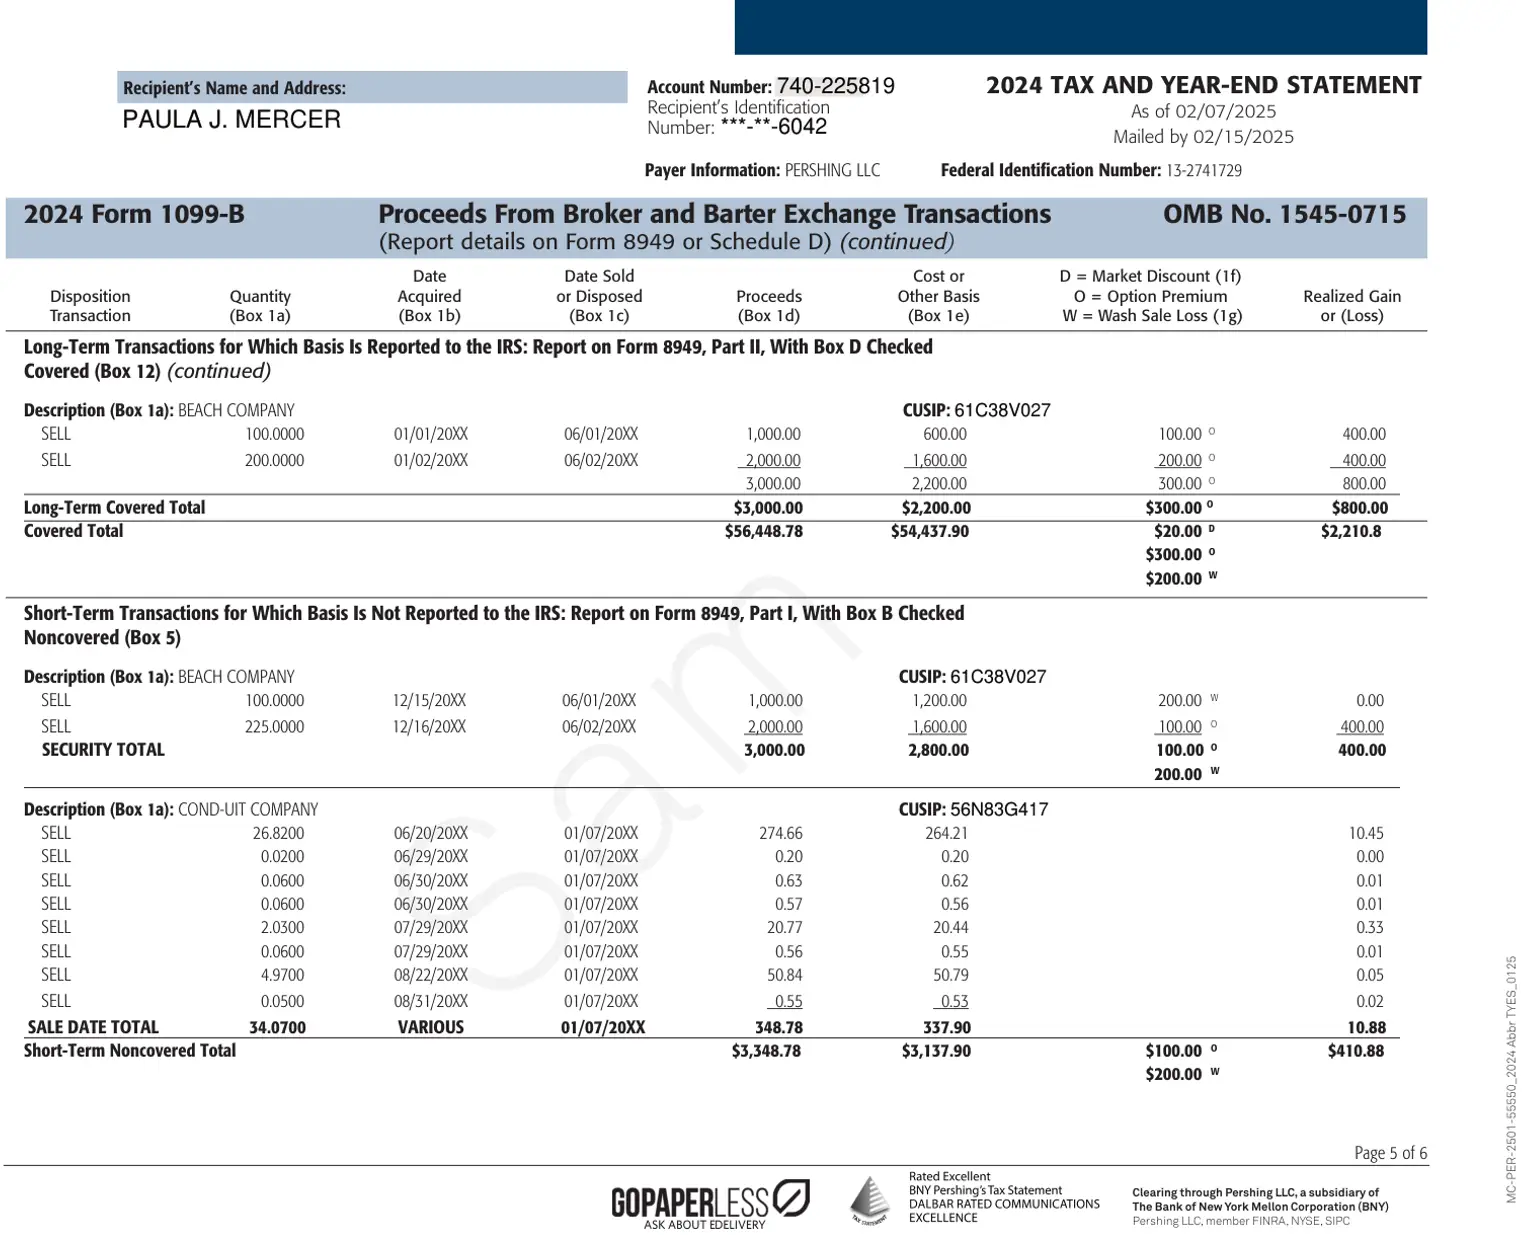
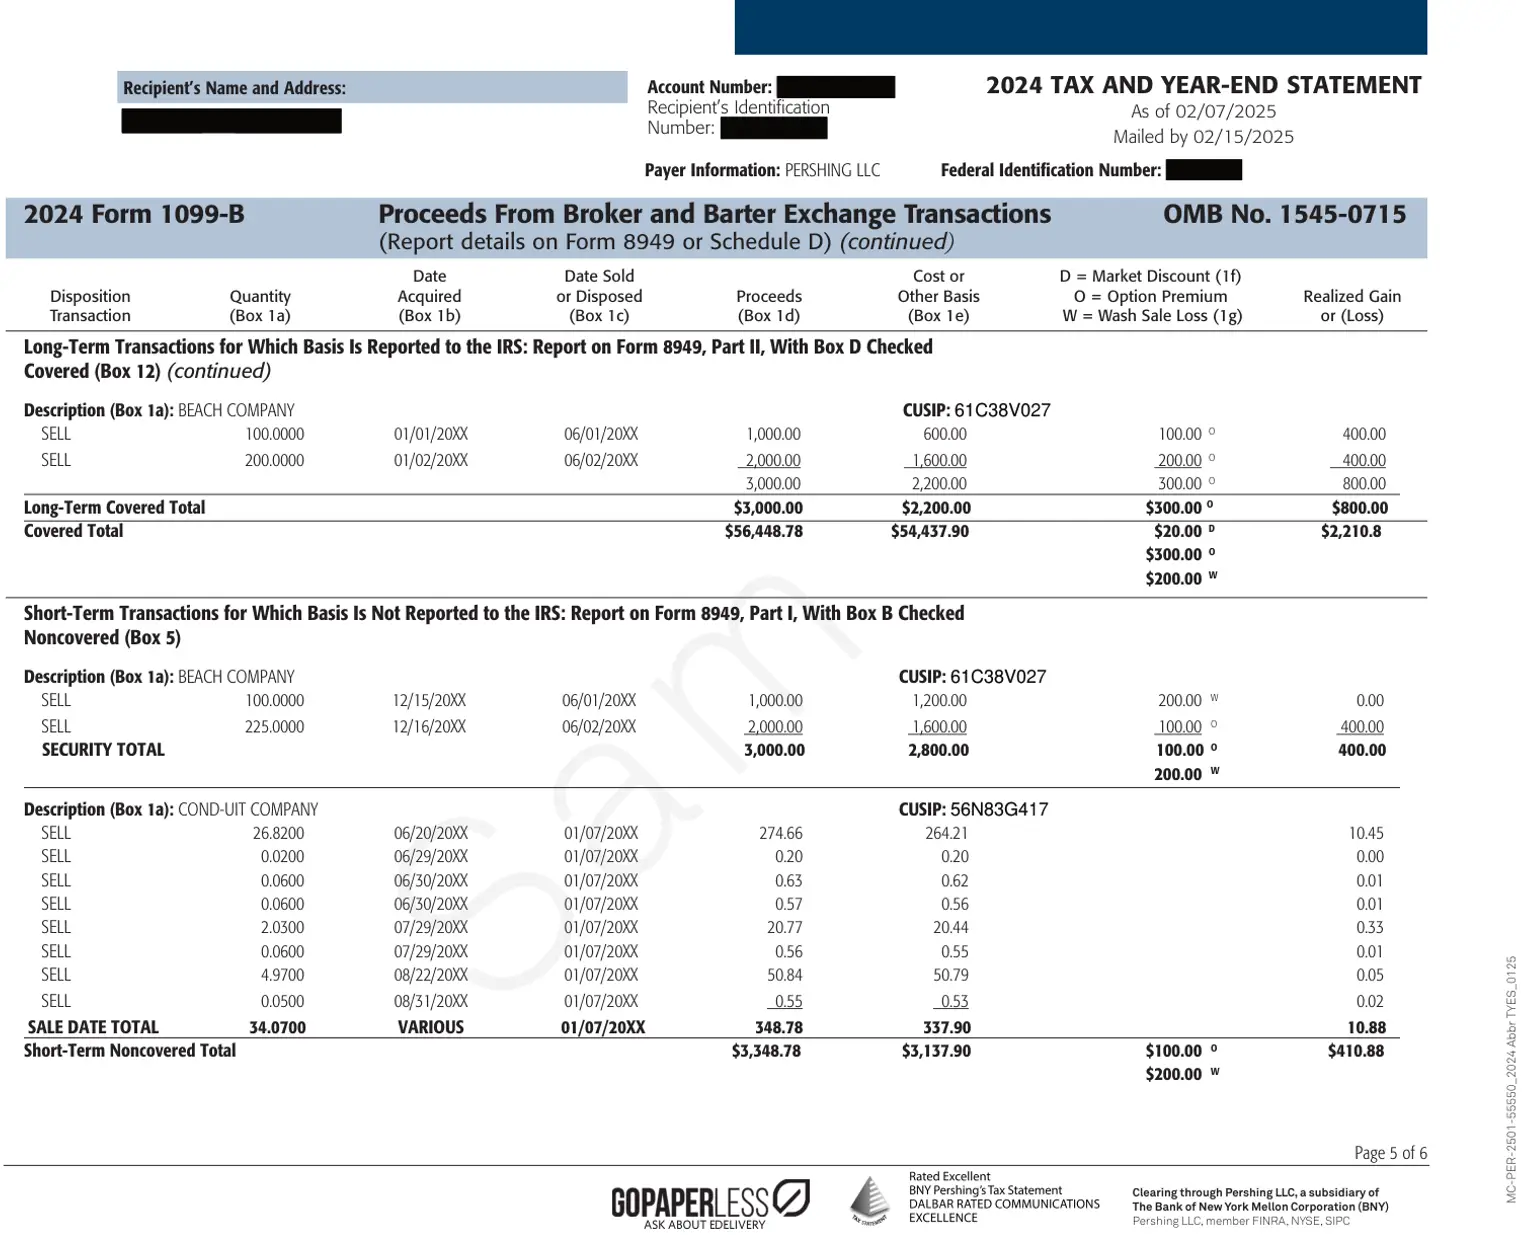
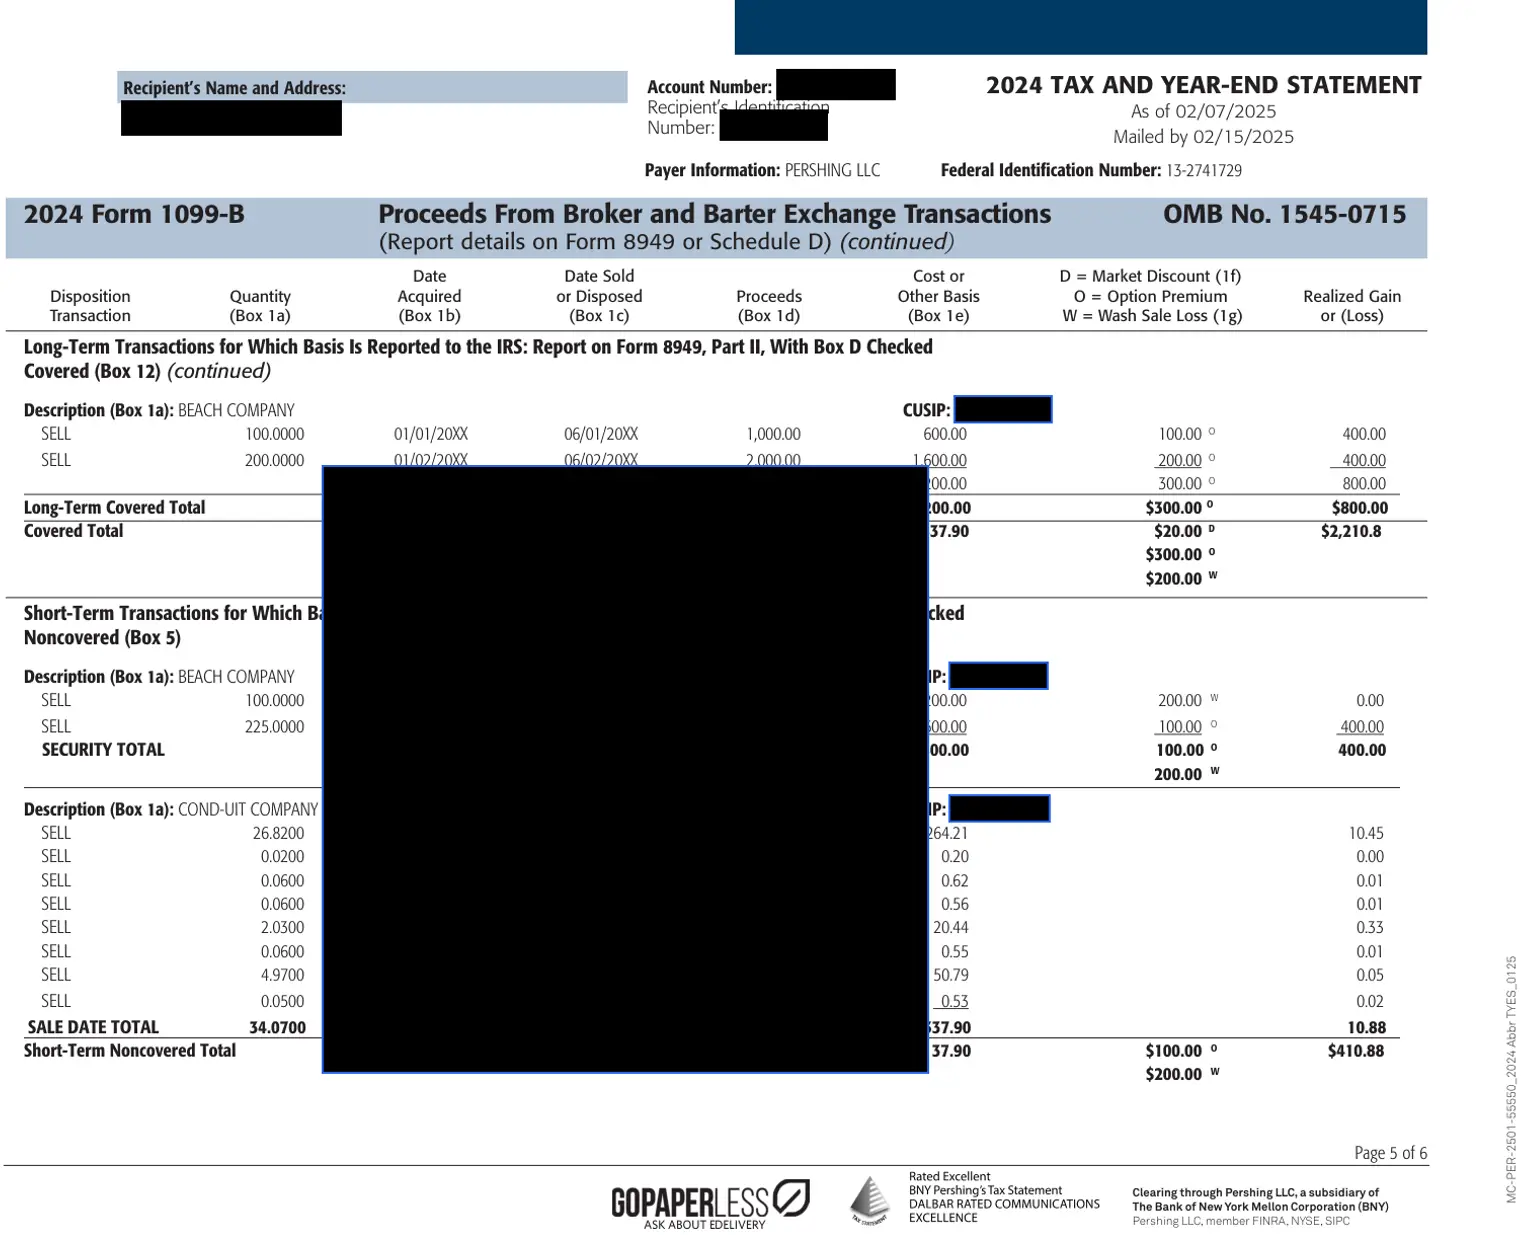
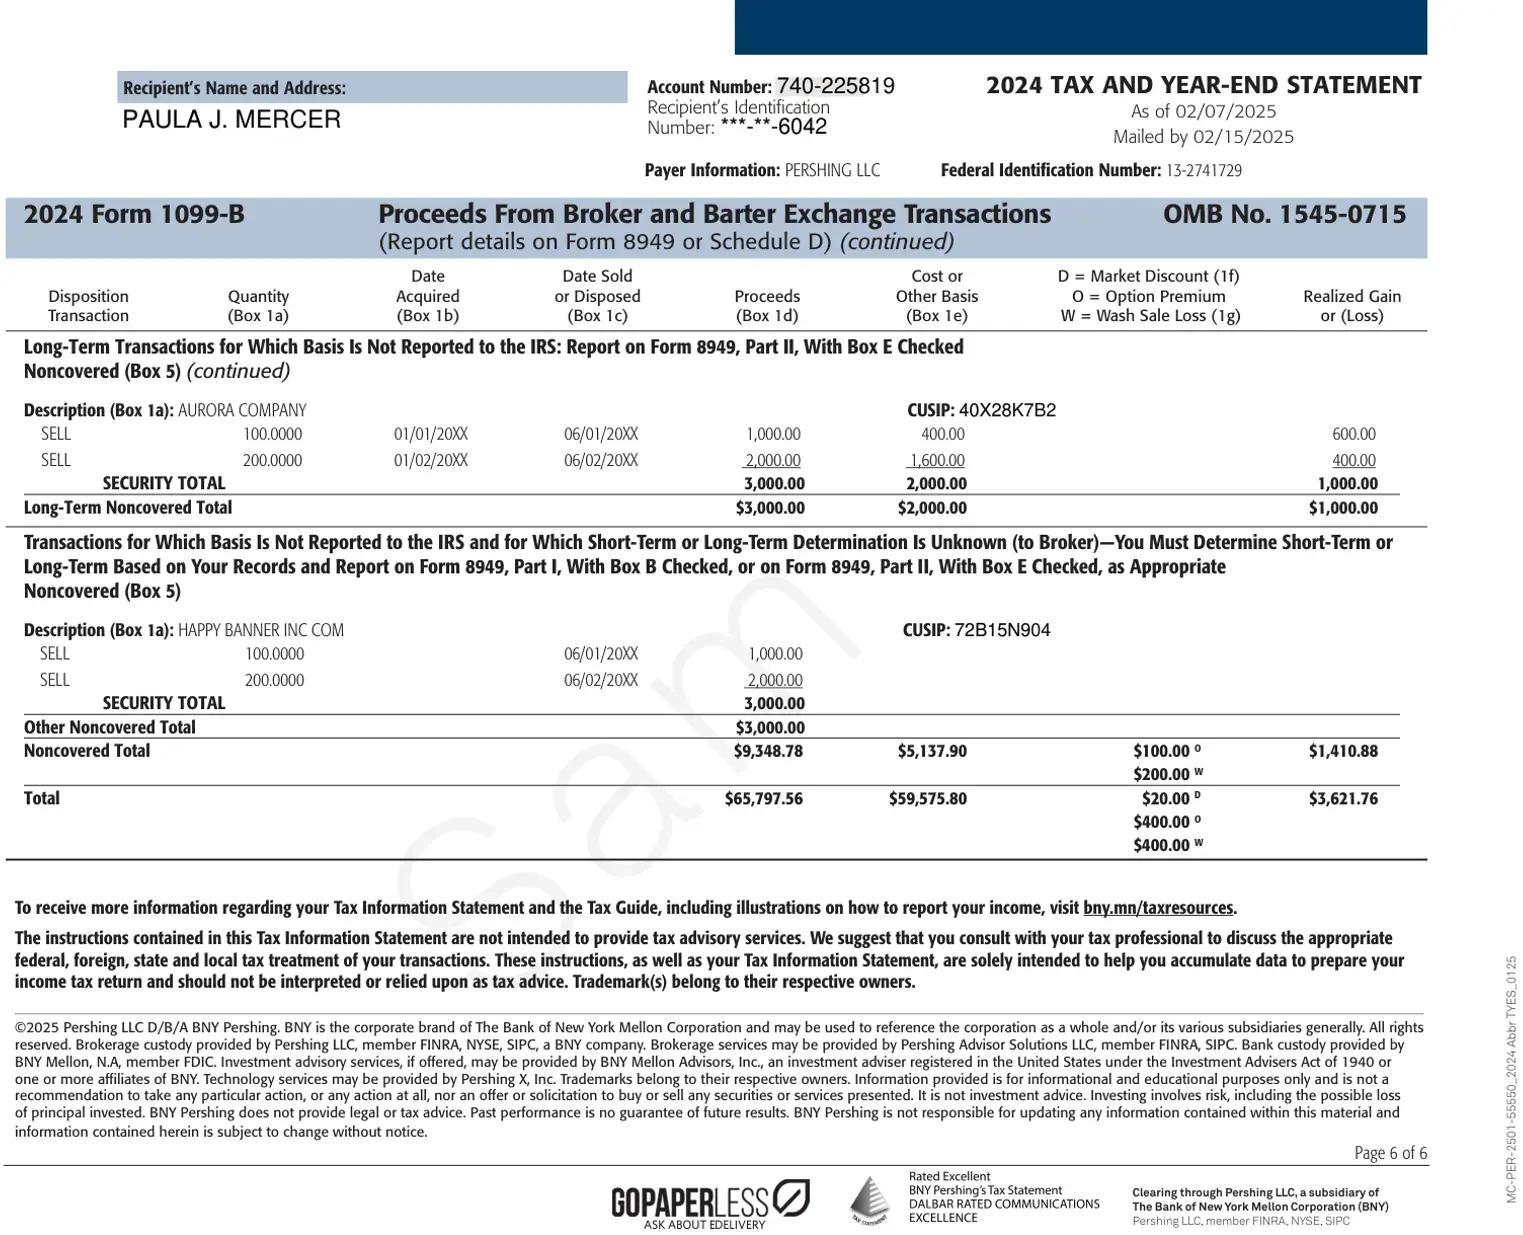
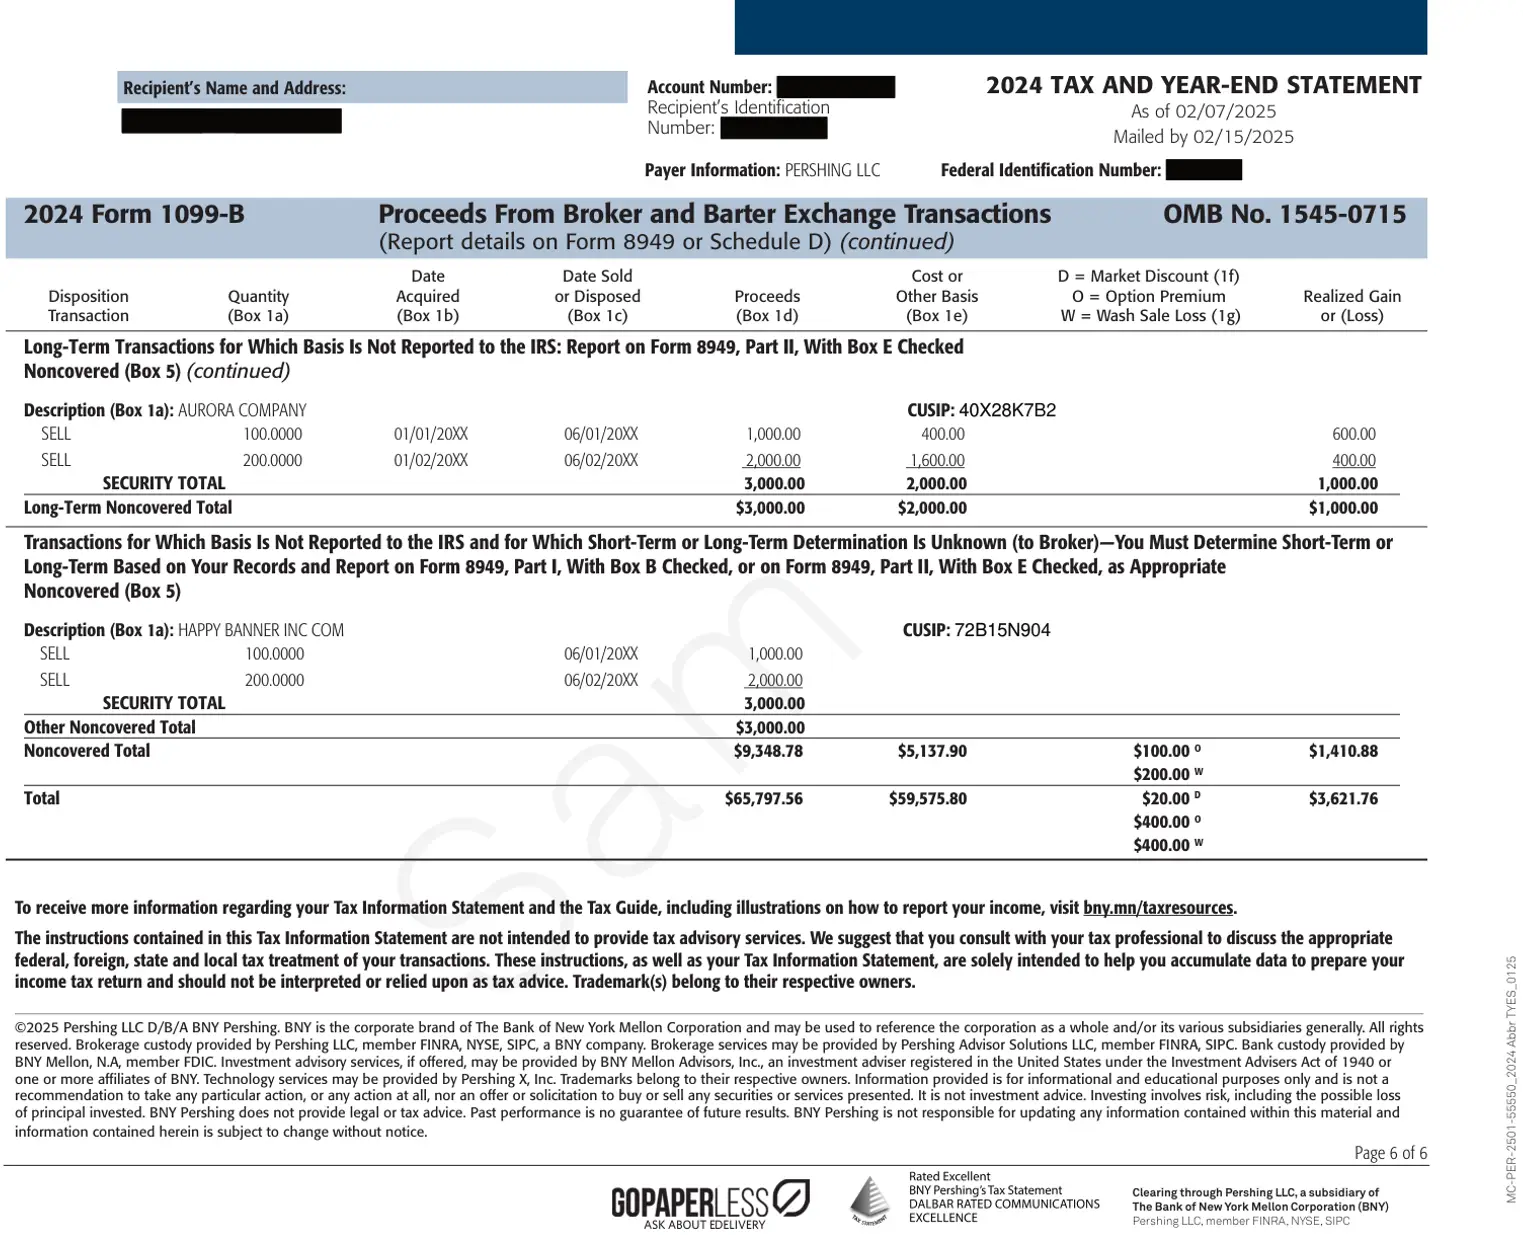
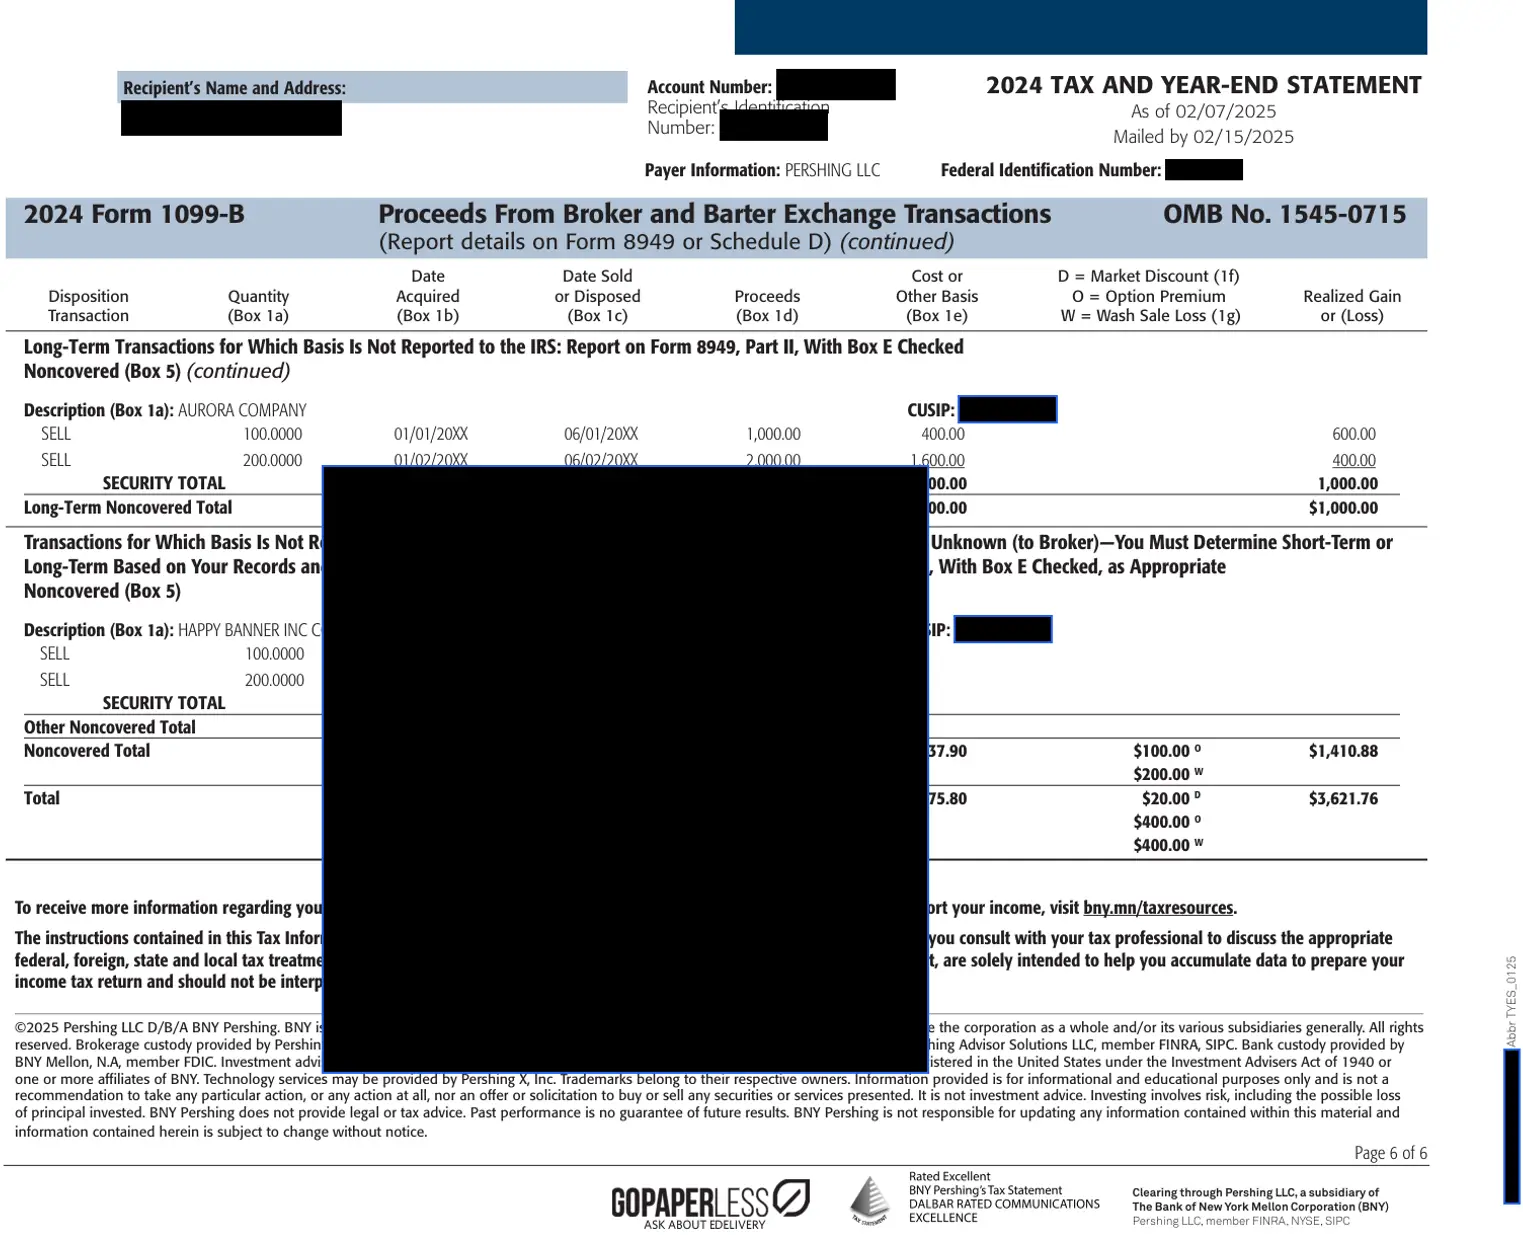
ubs-portfolio-summary-sample.pdf
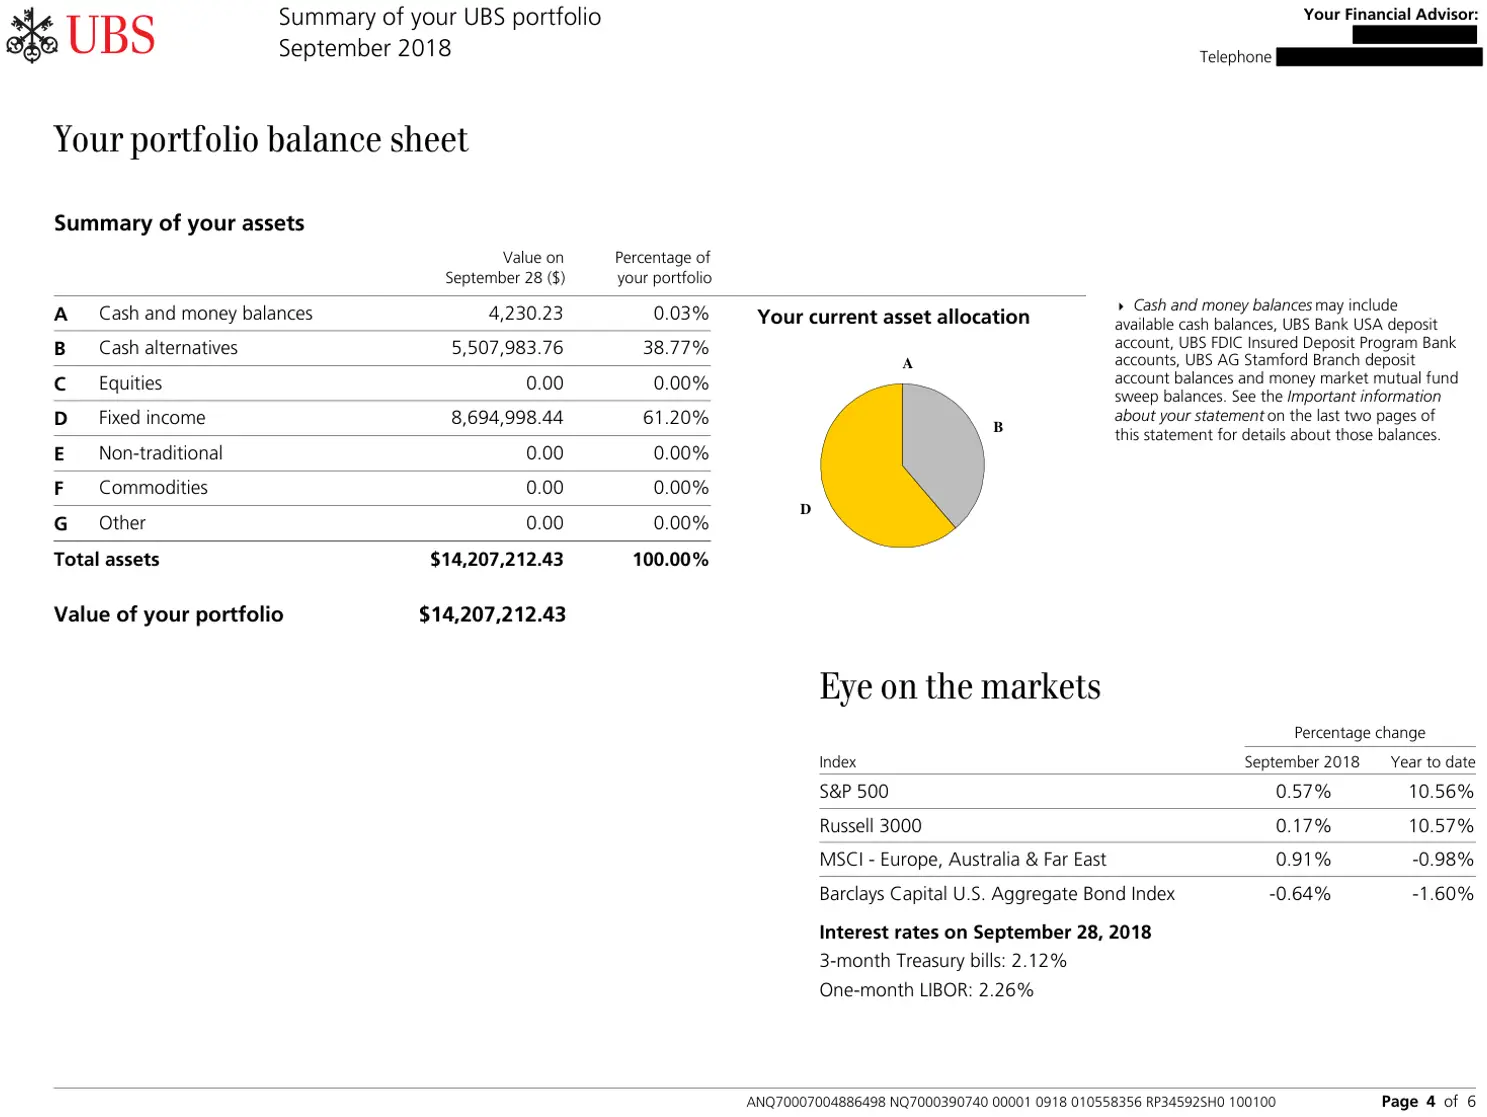
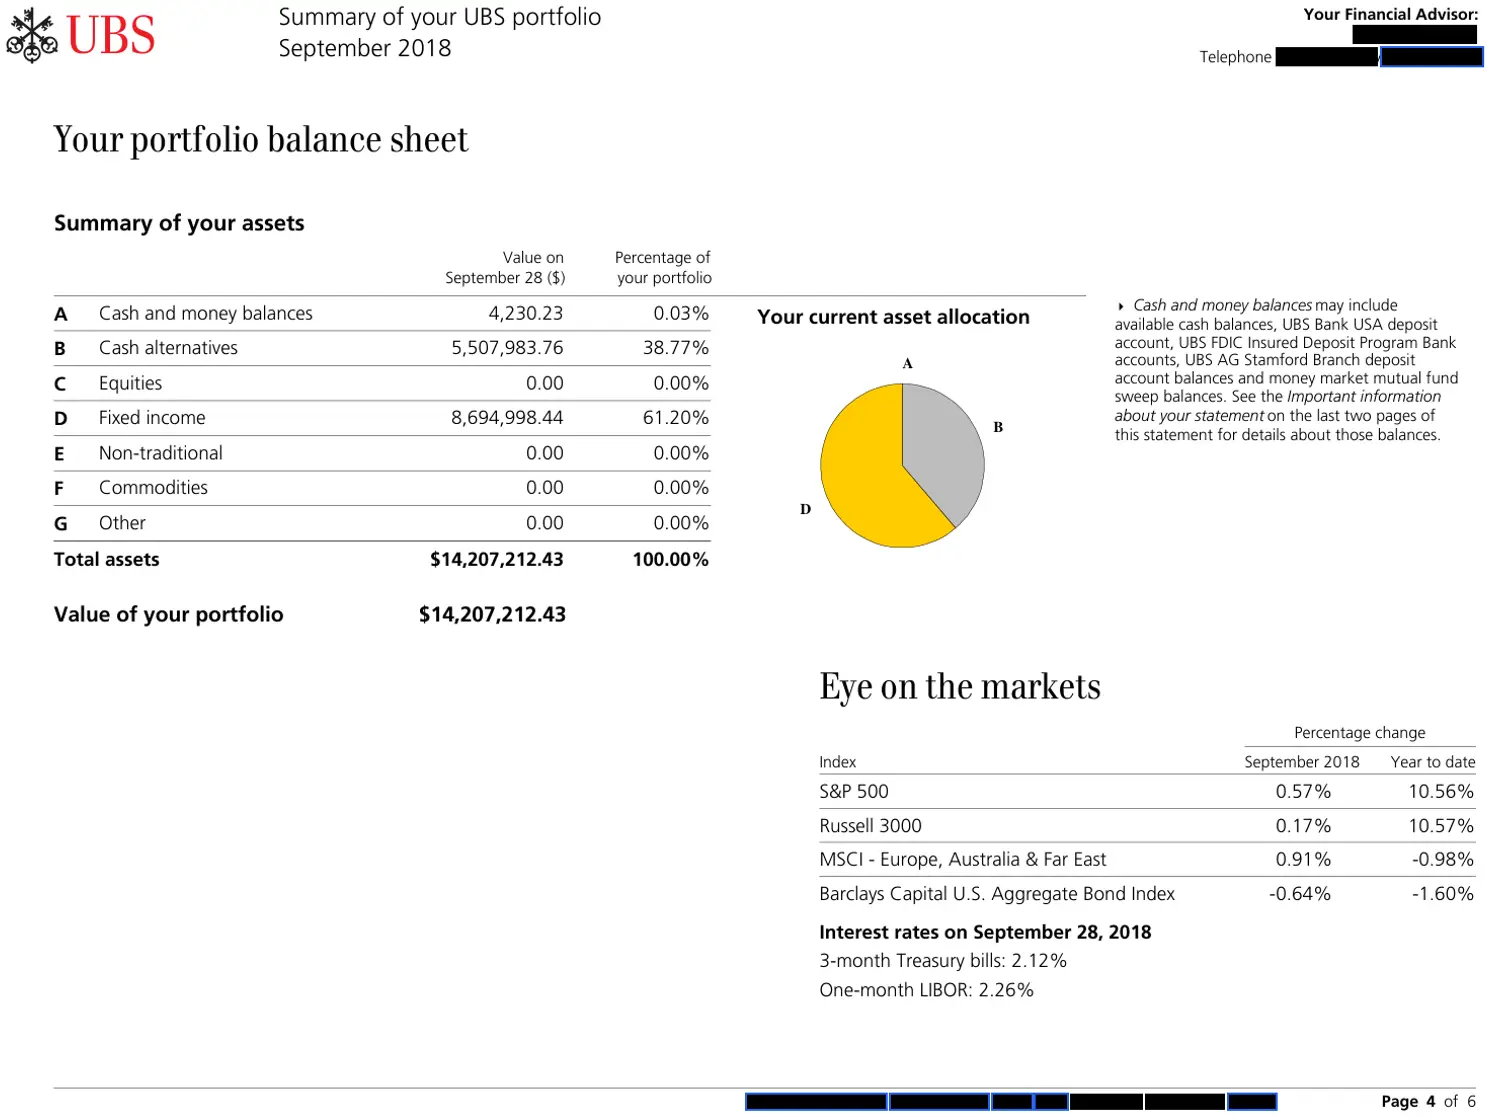
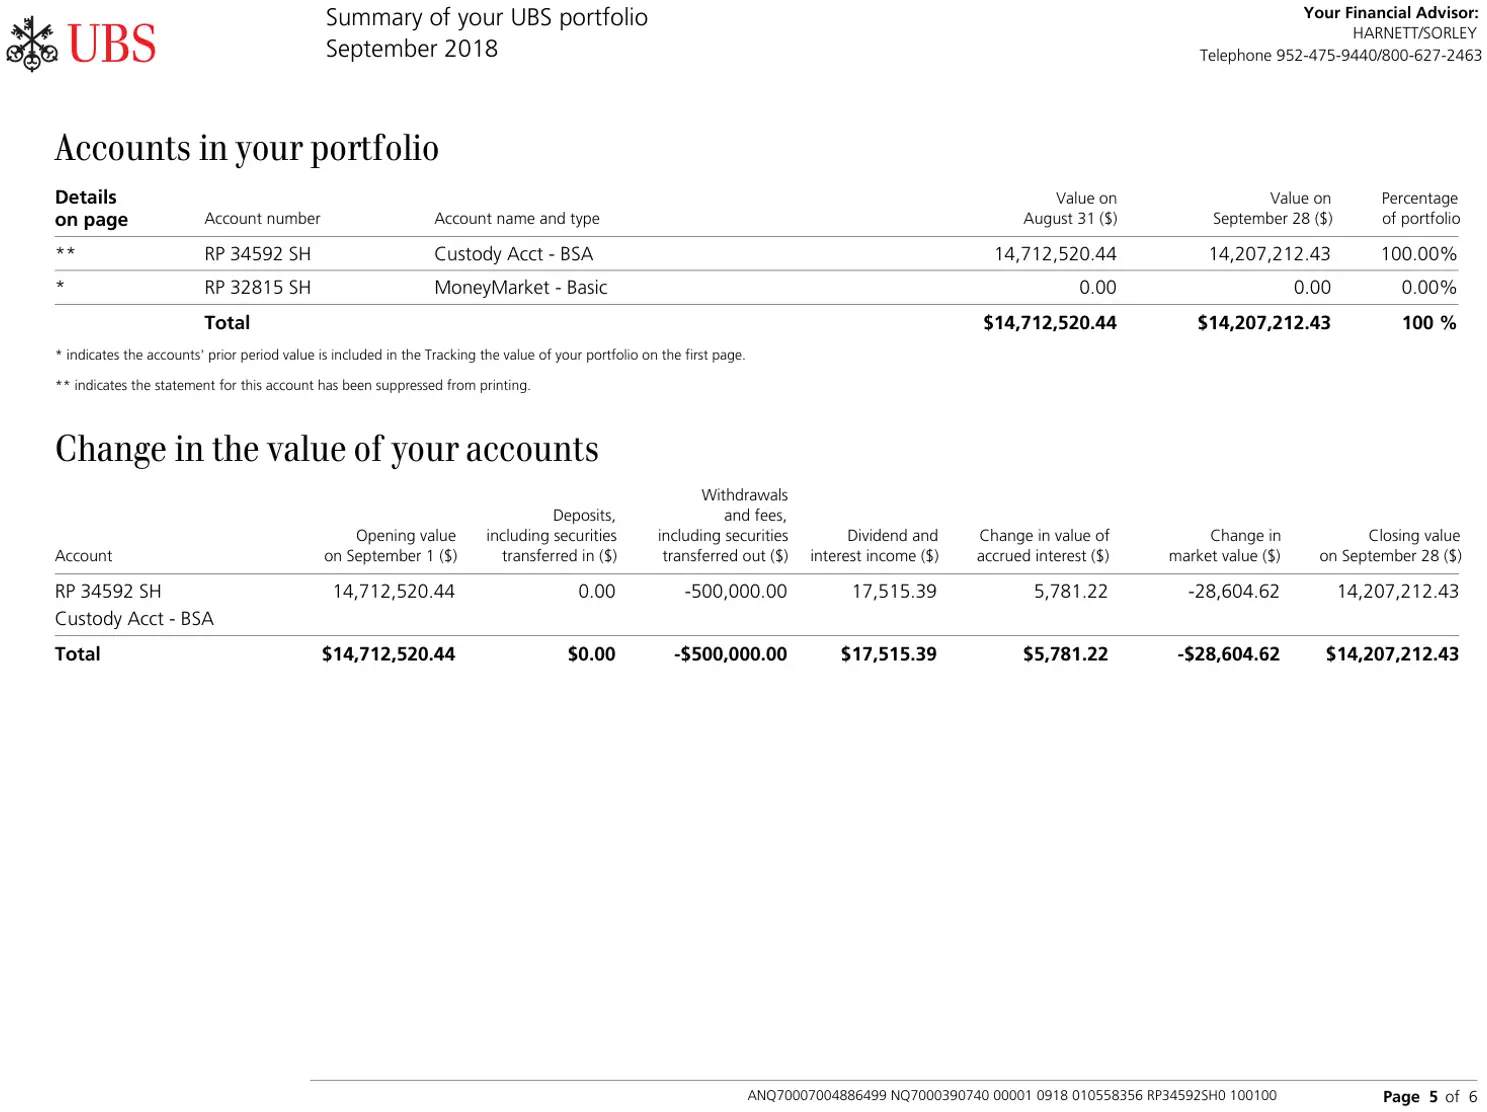
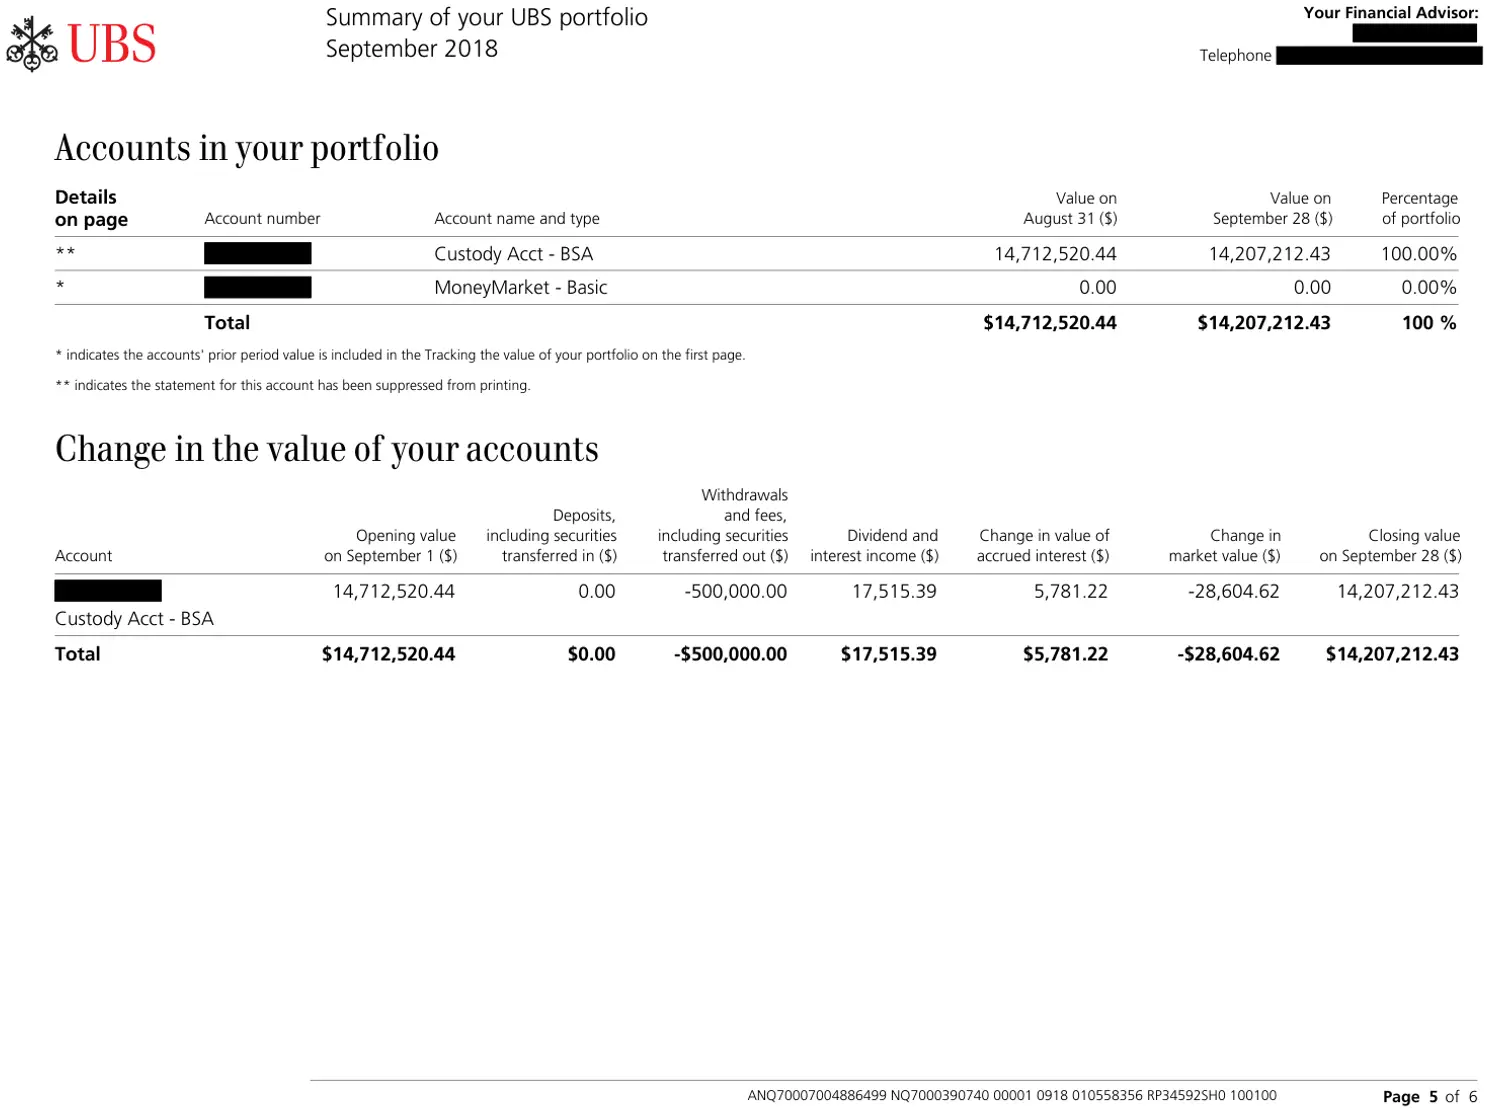
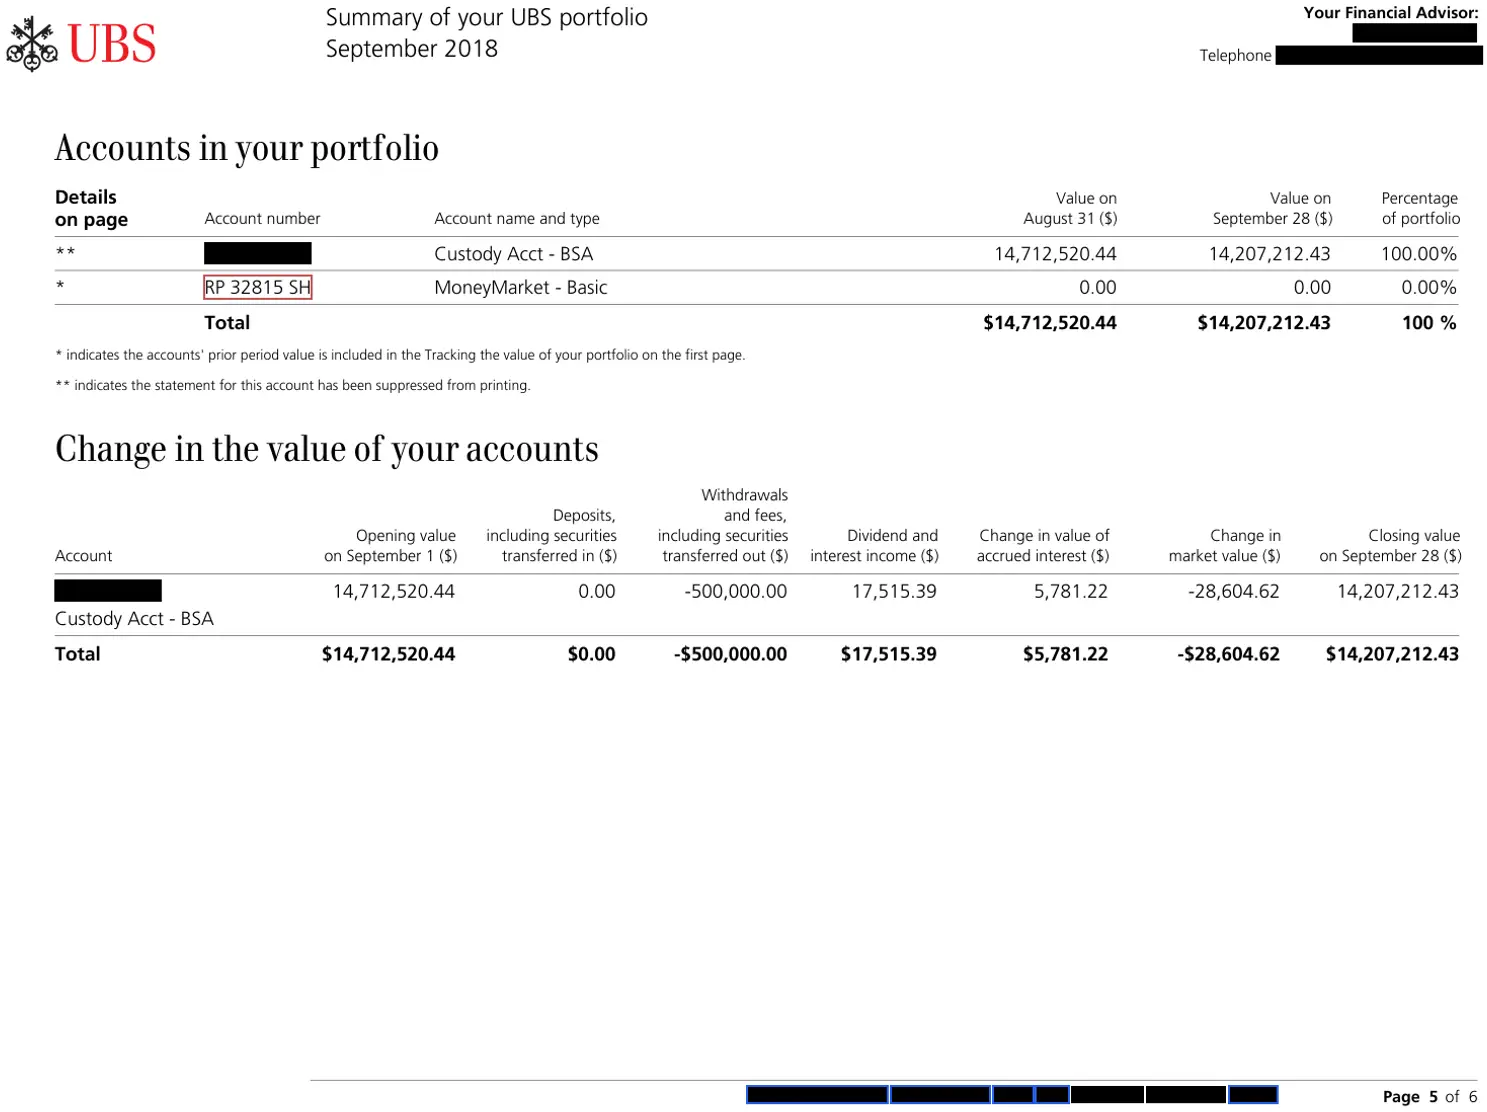
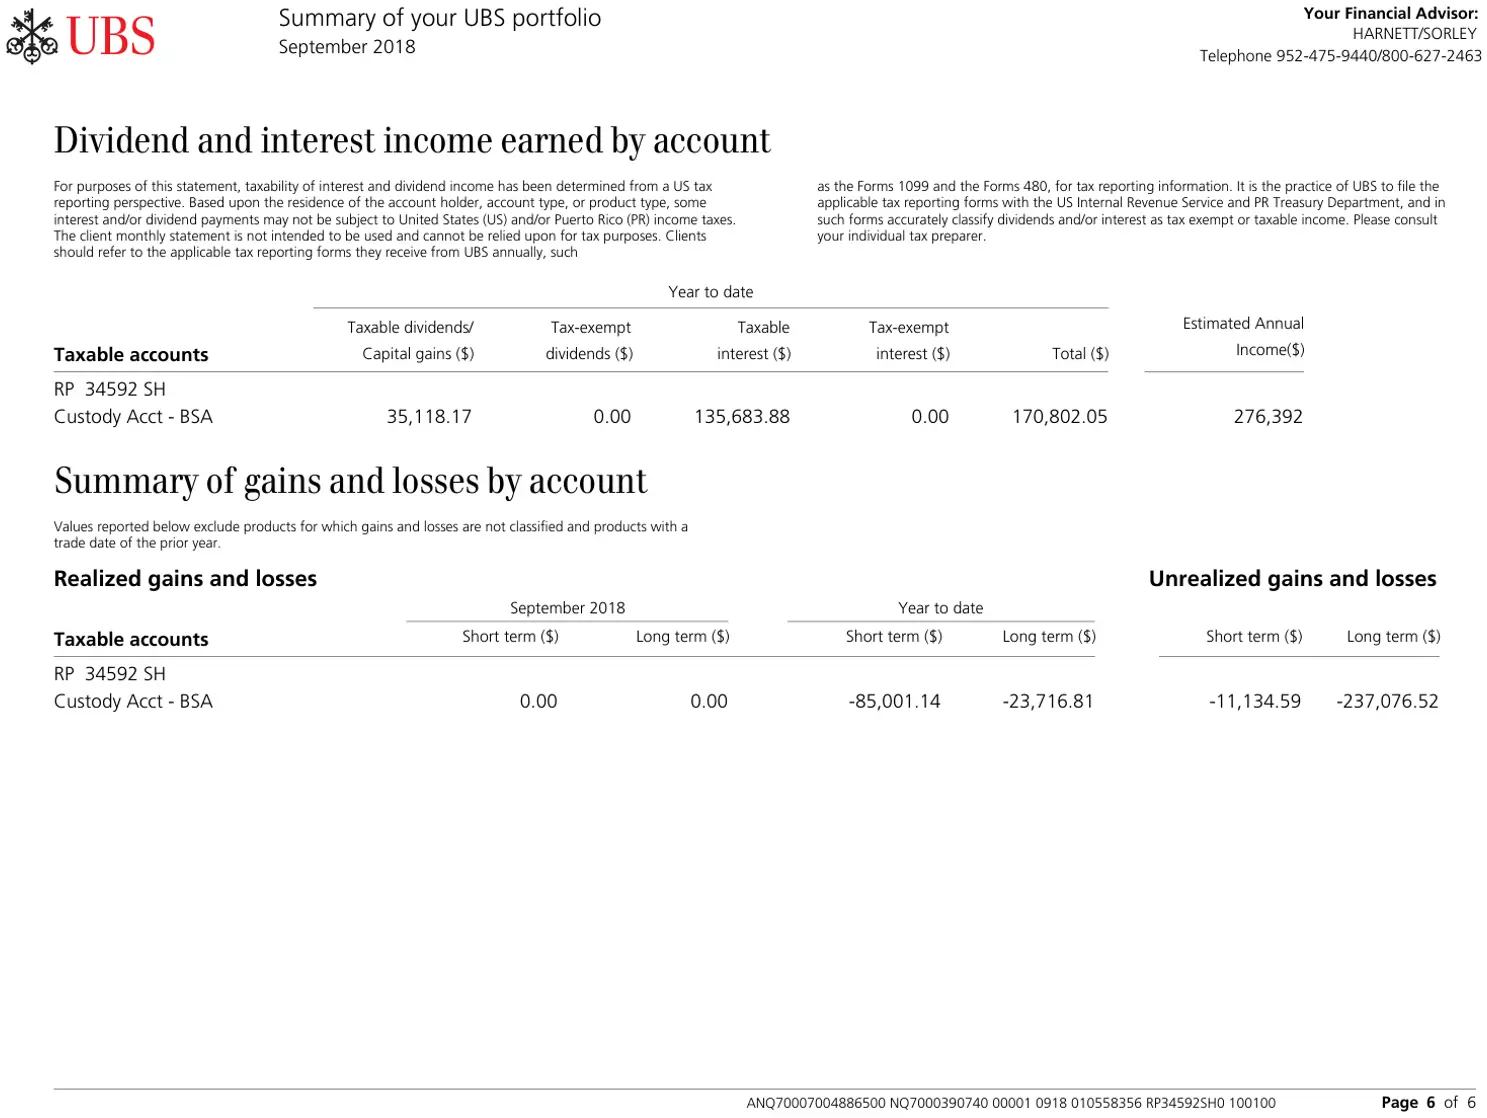
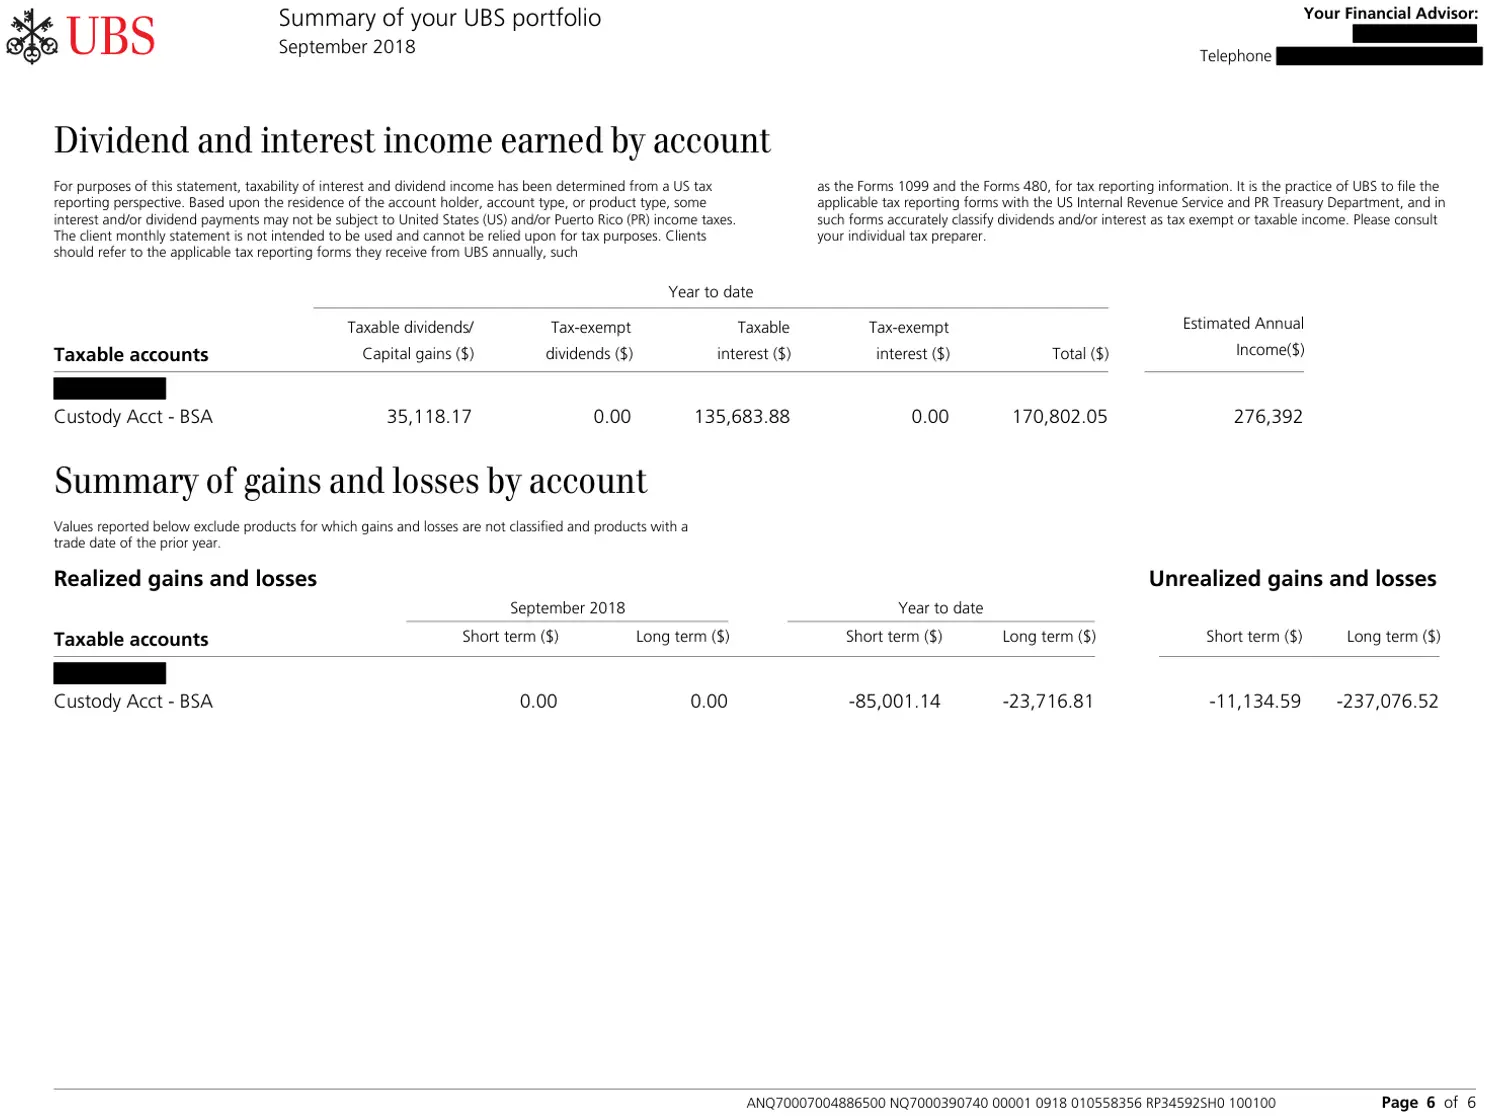
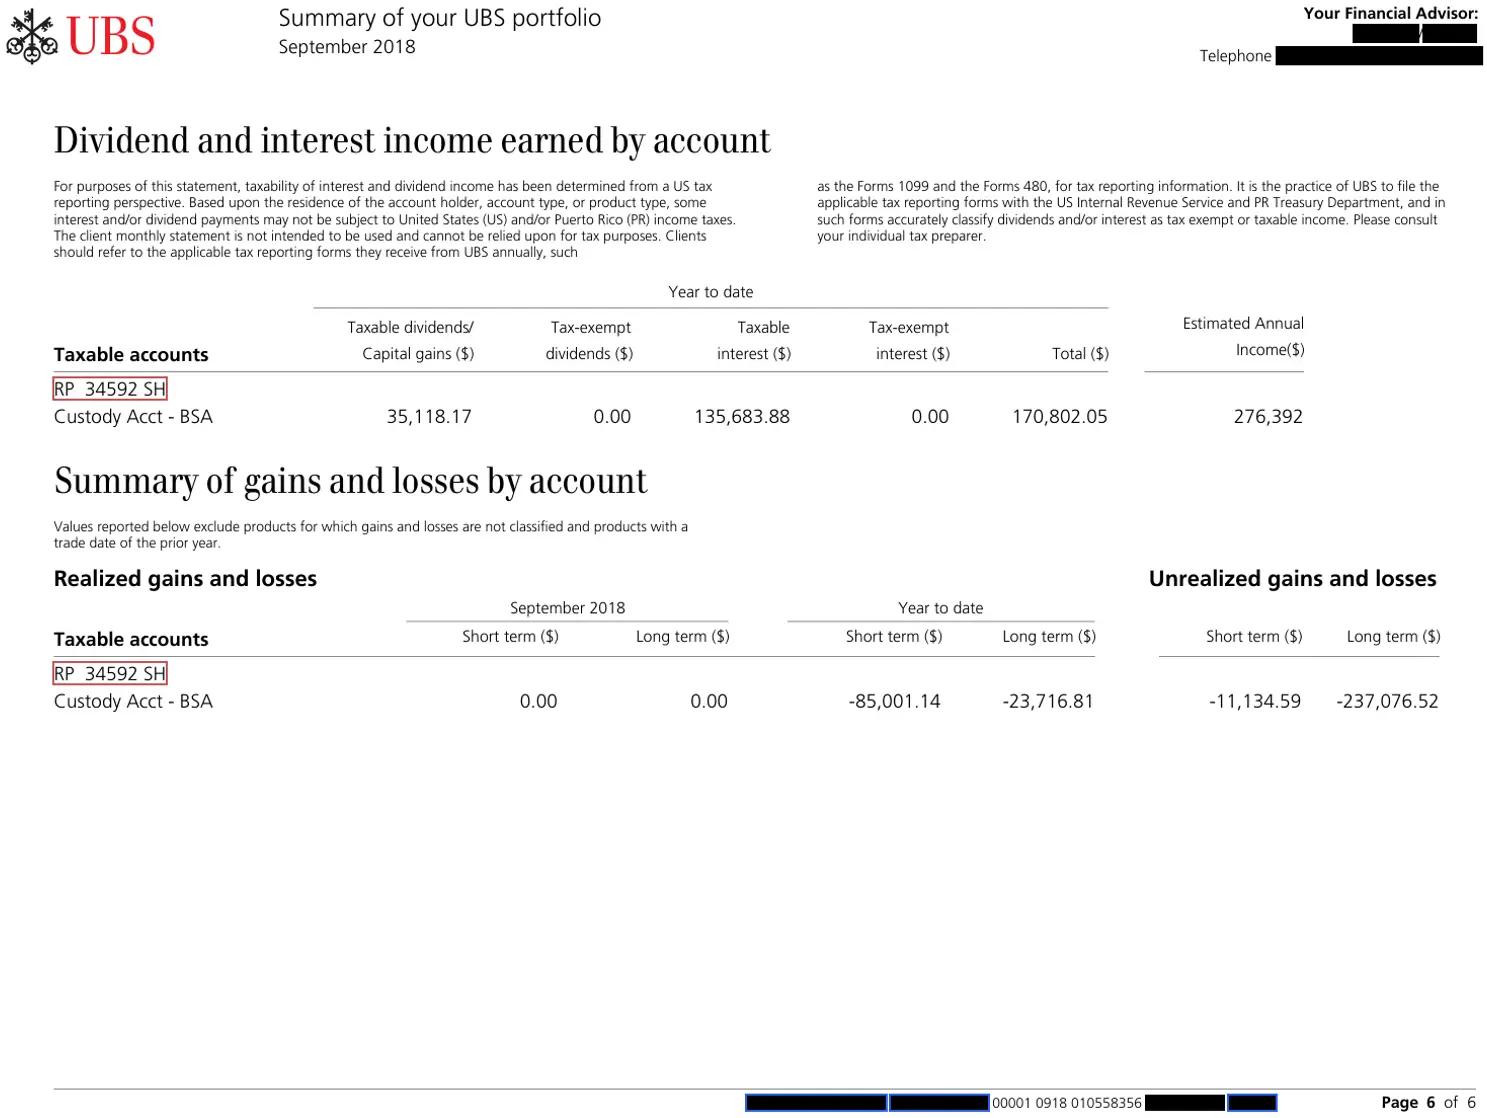
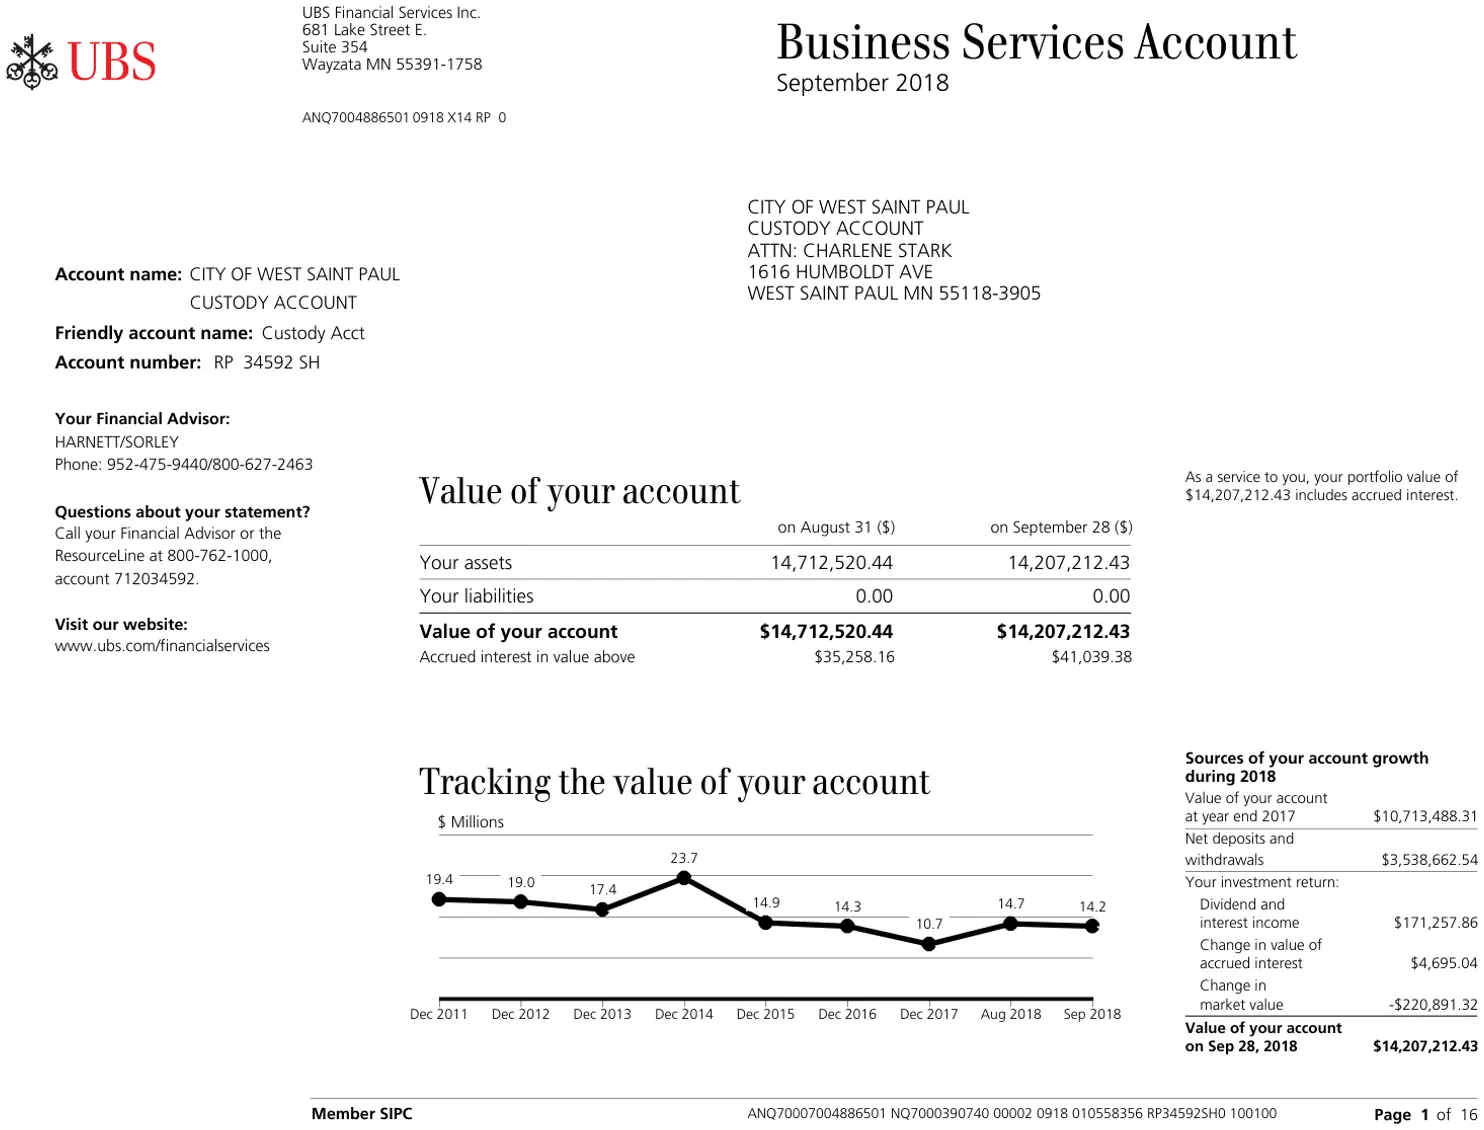
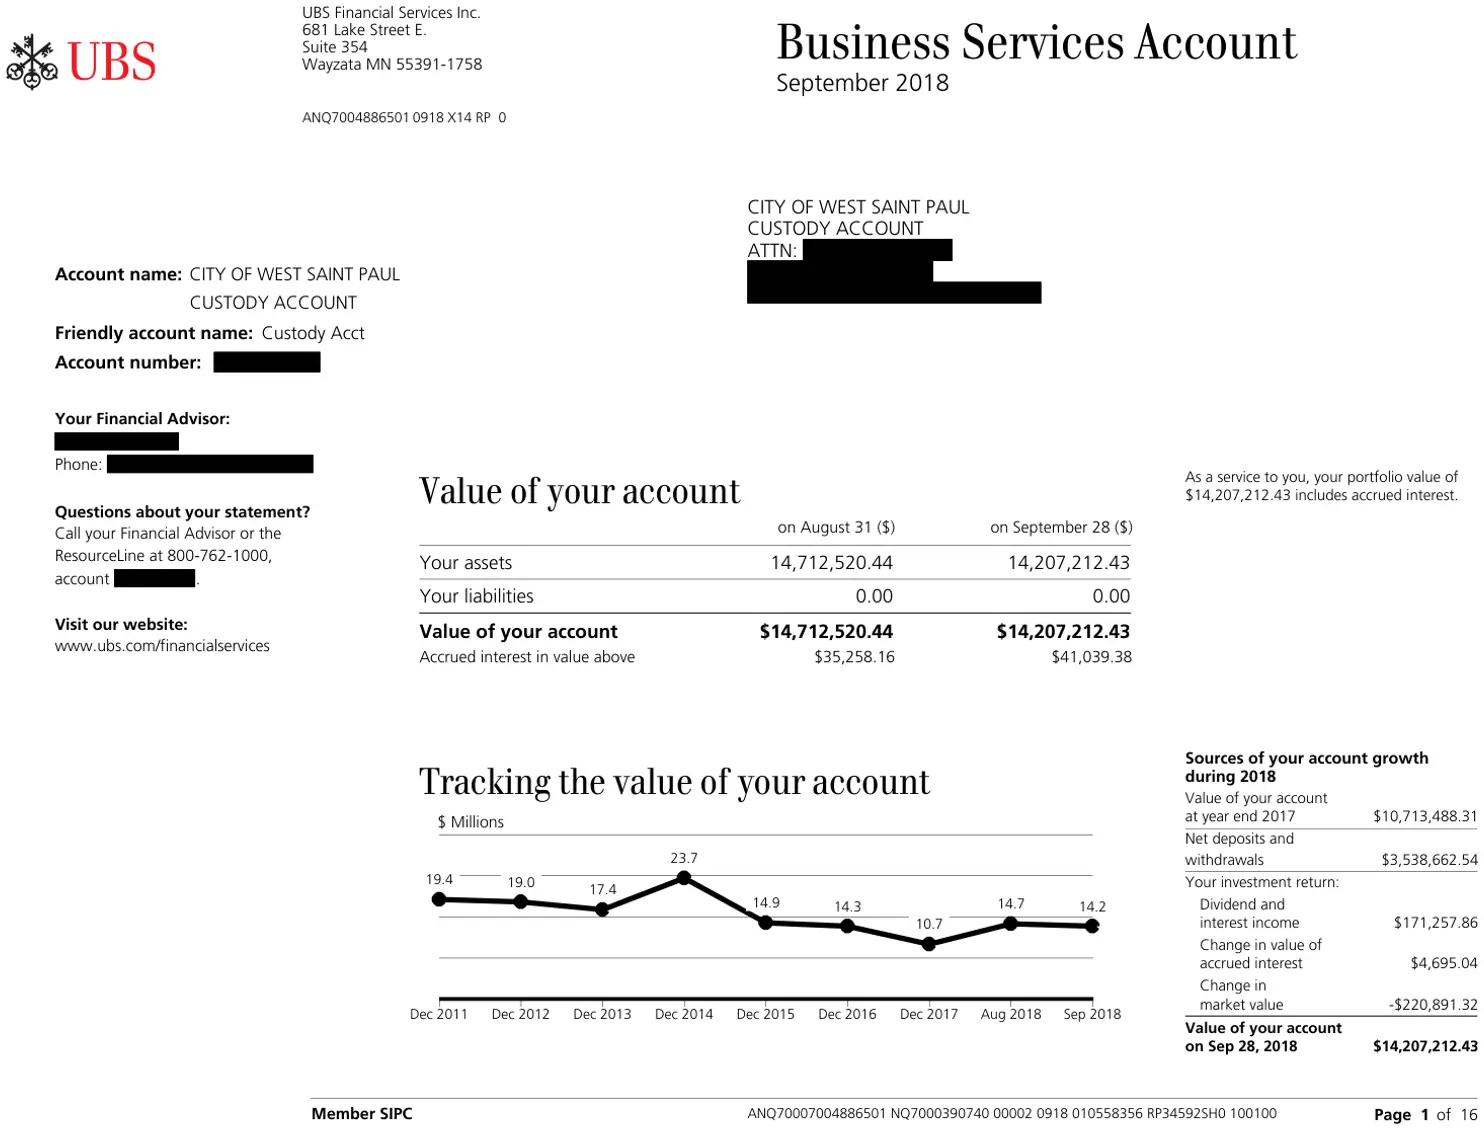
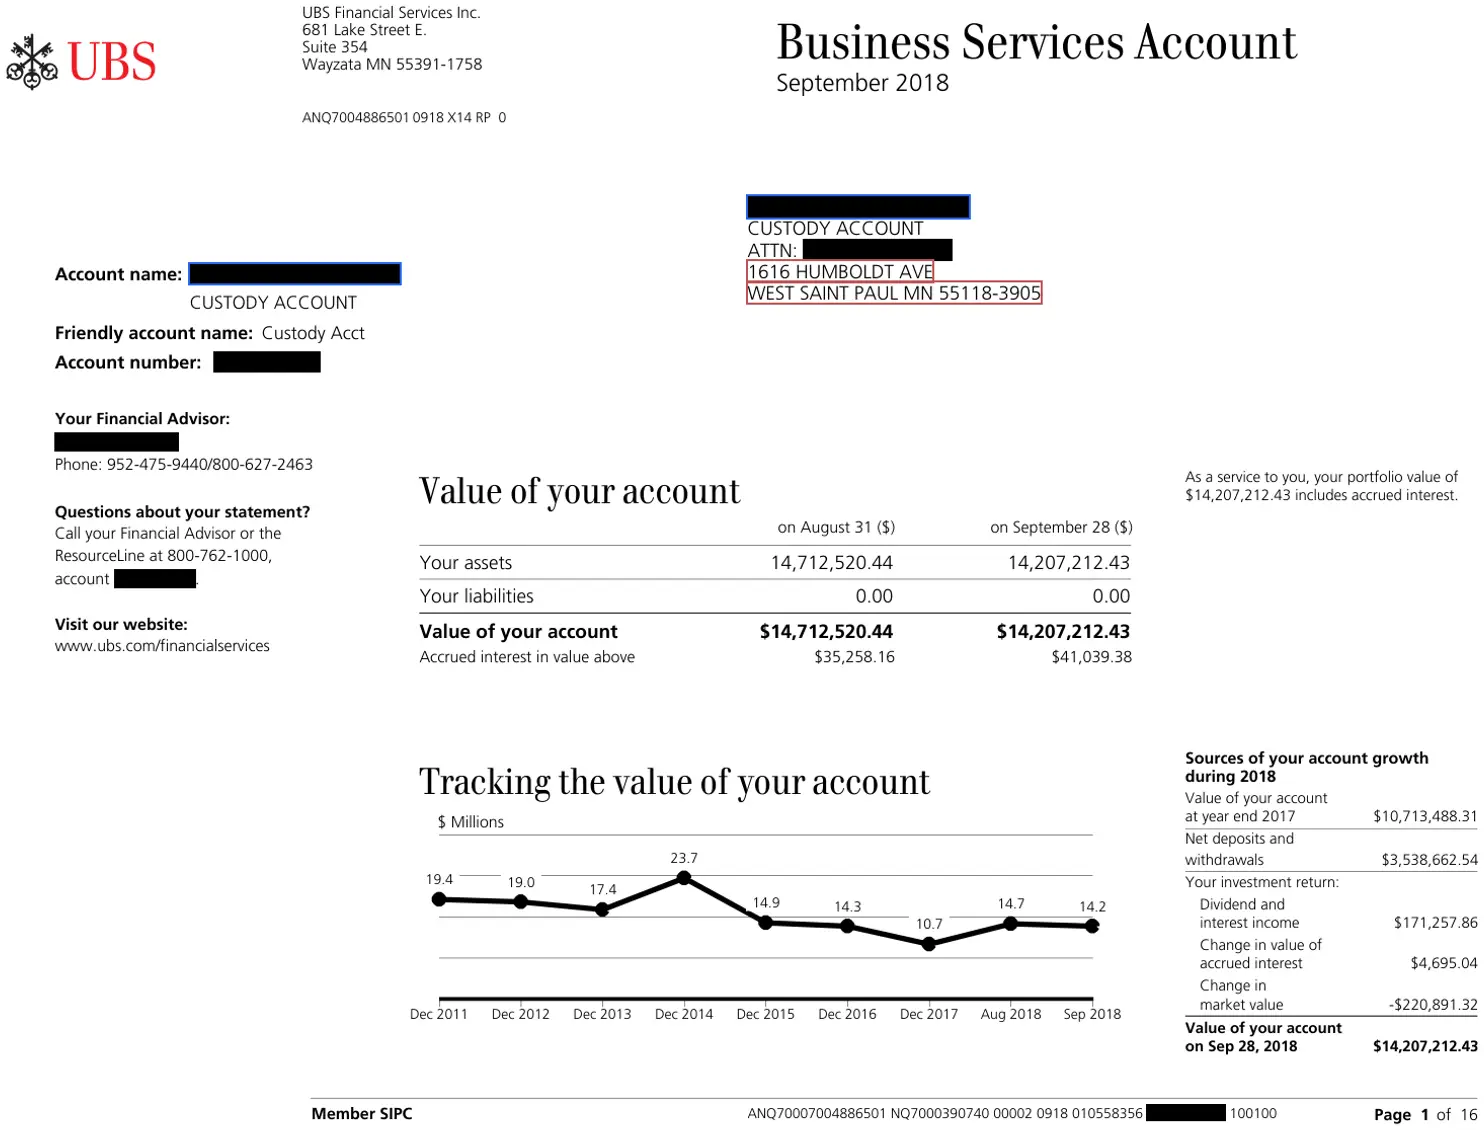
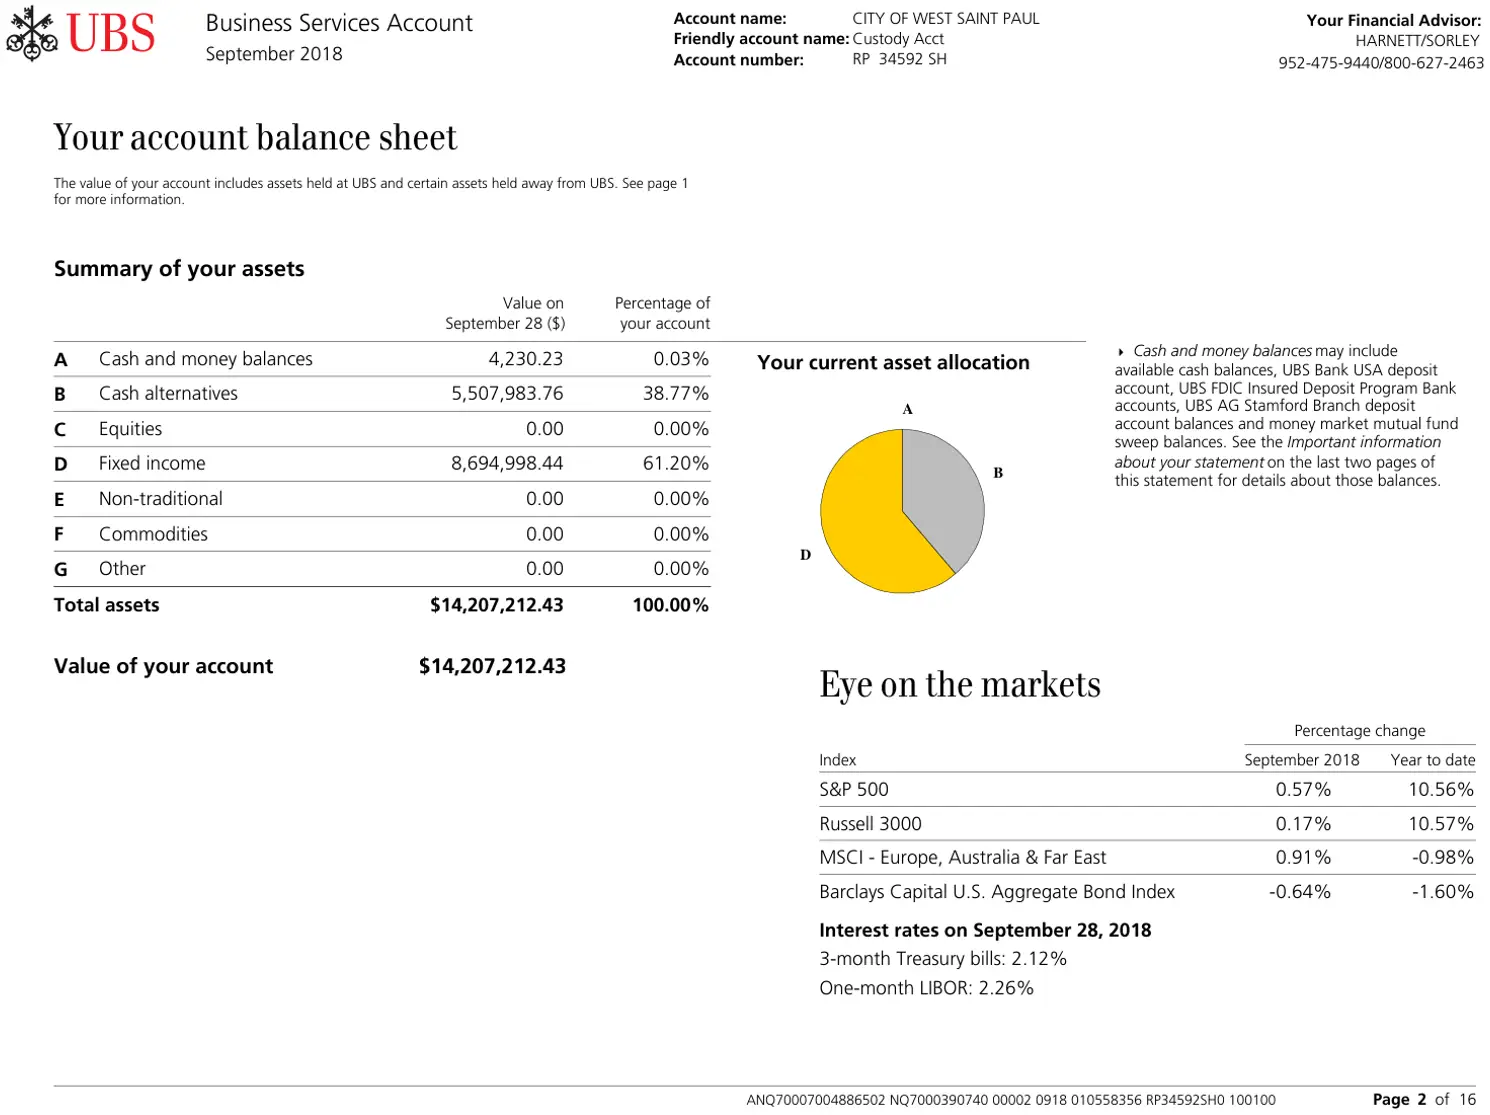
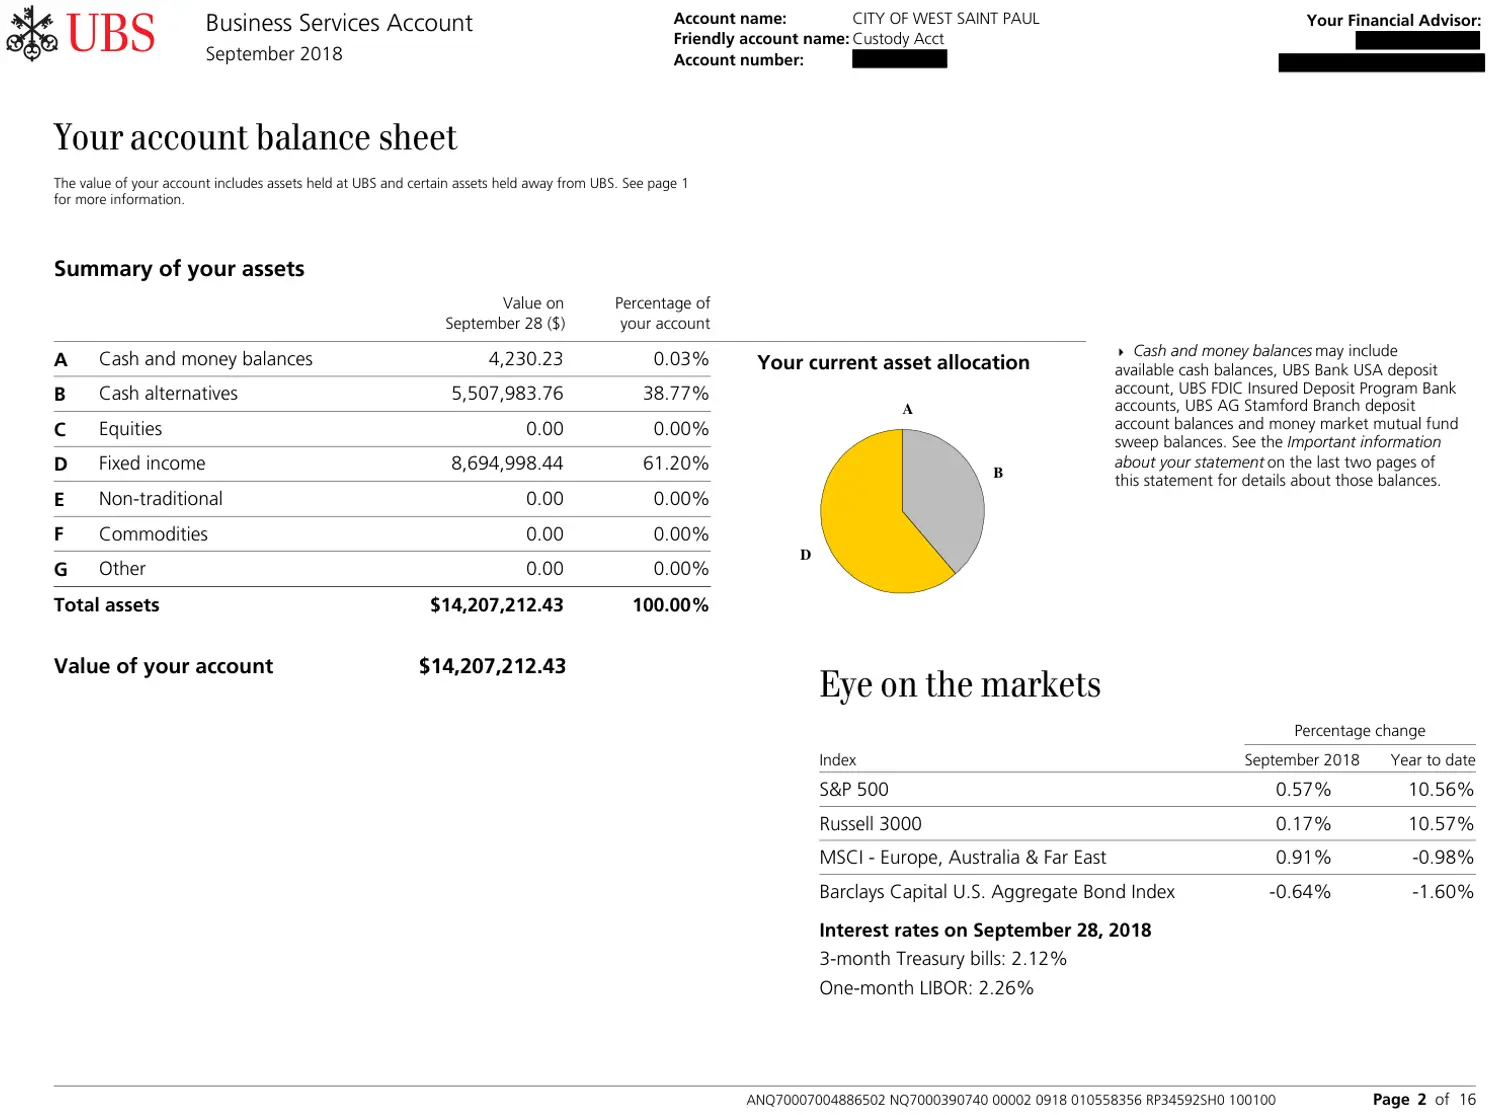
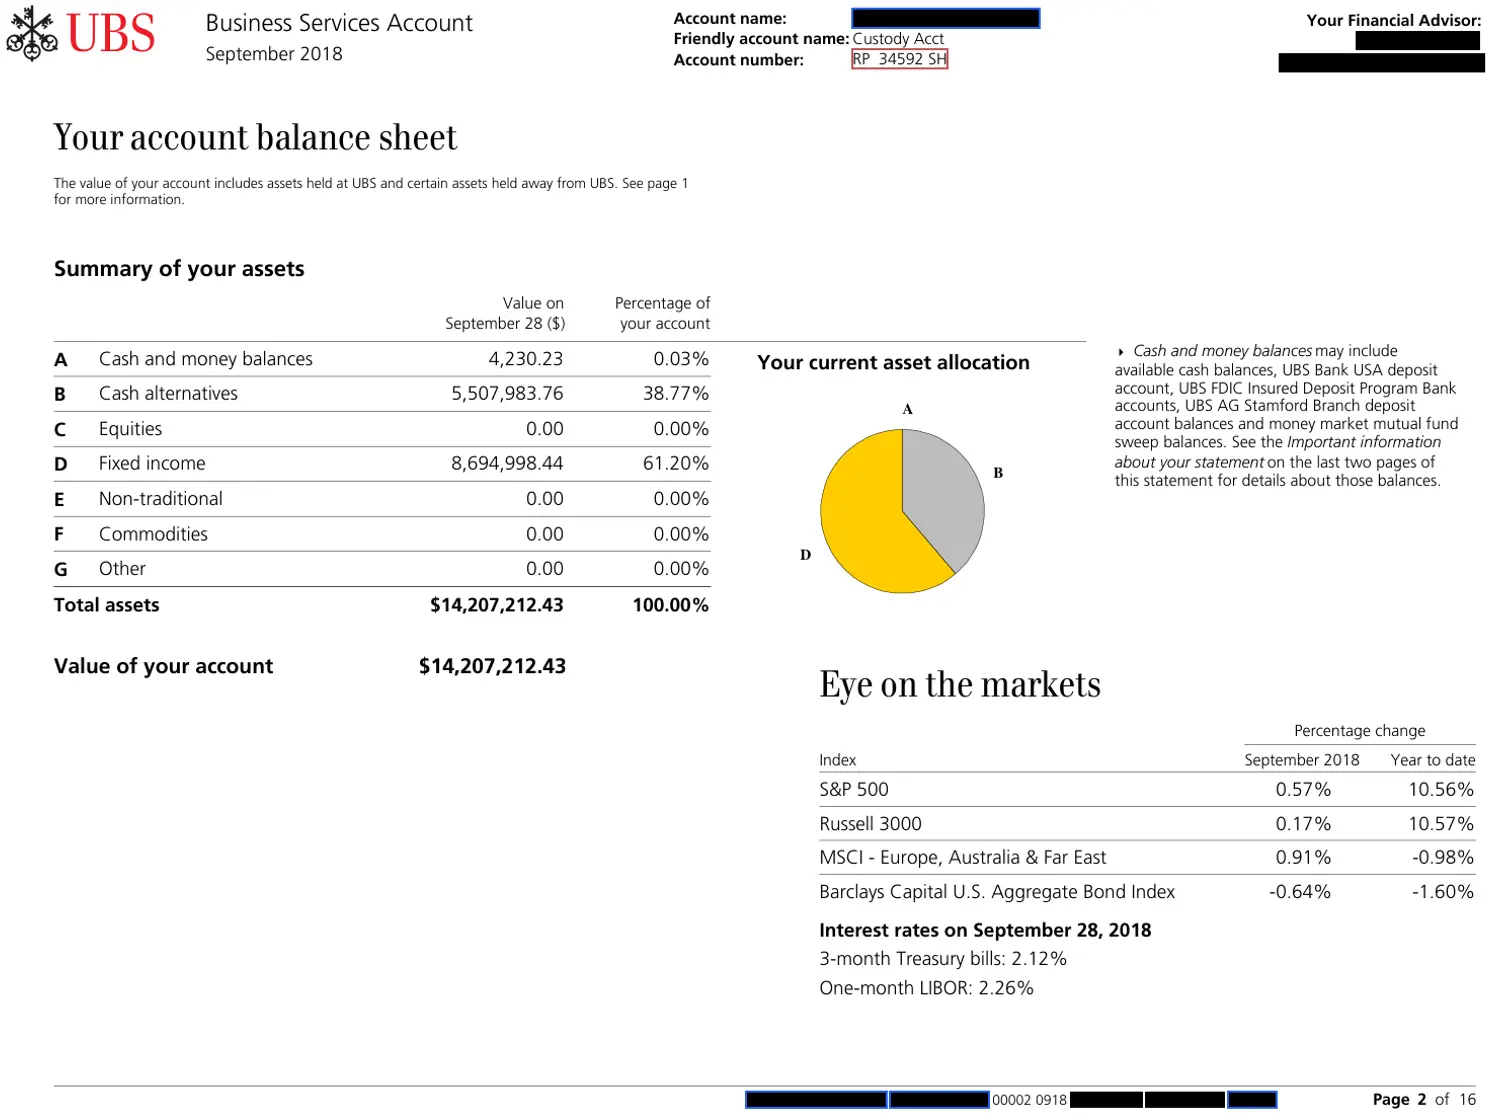
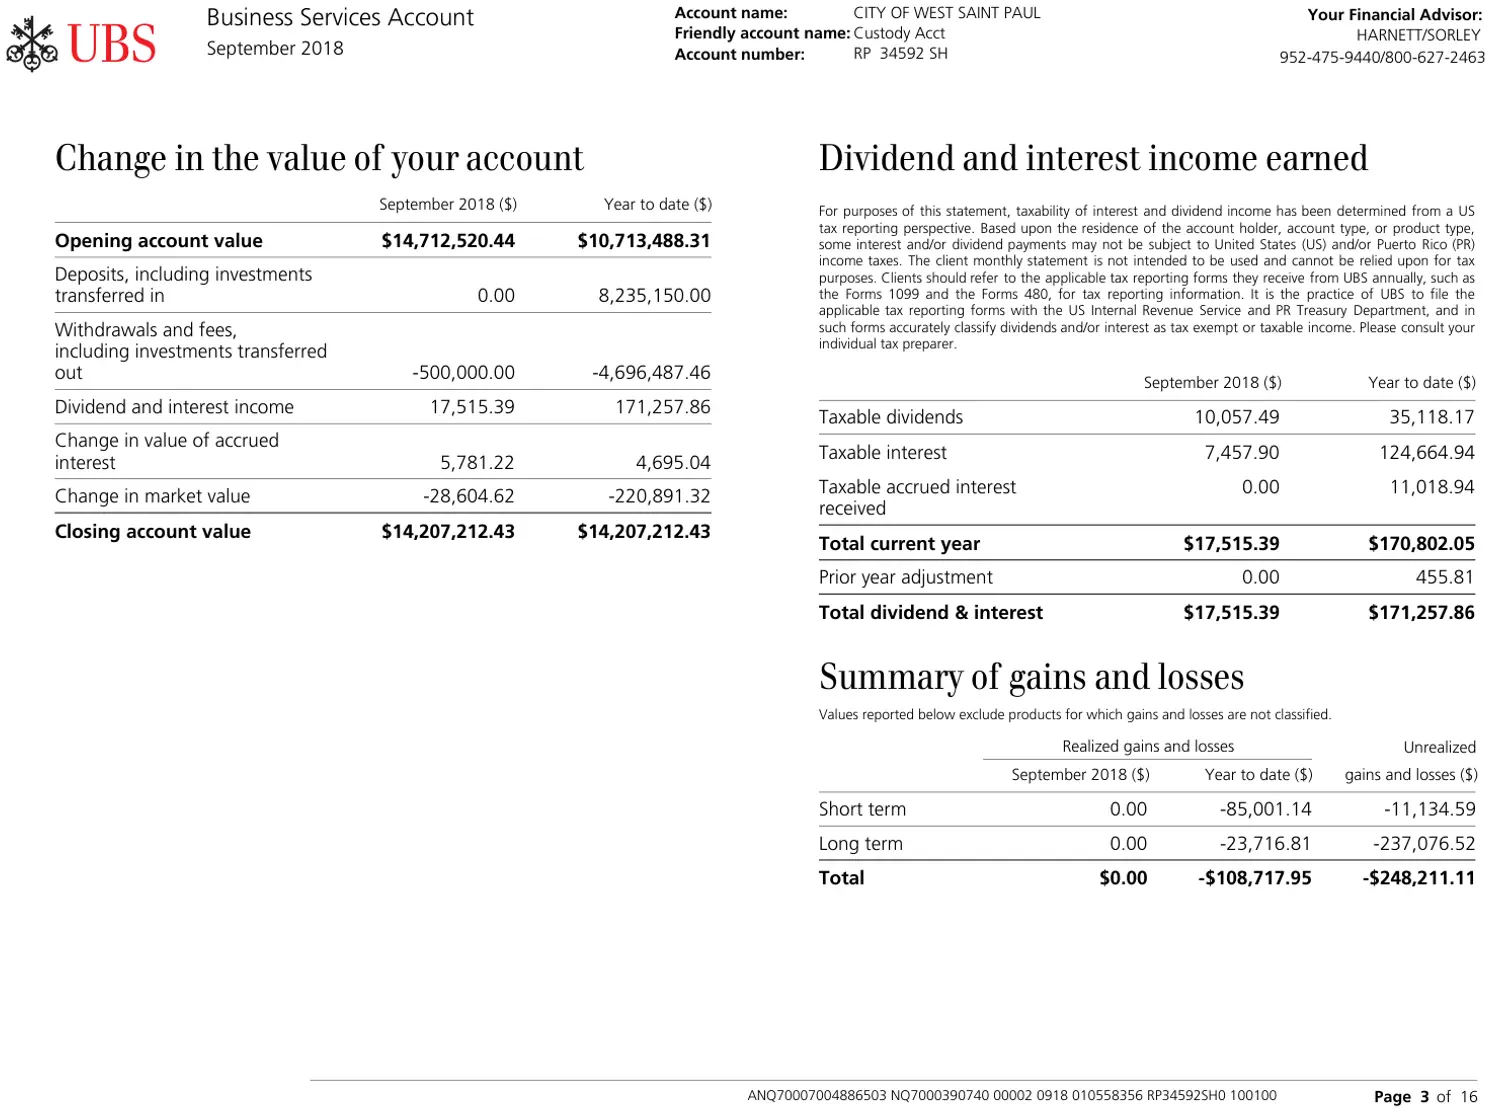
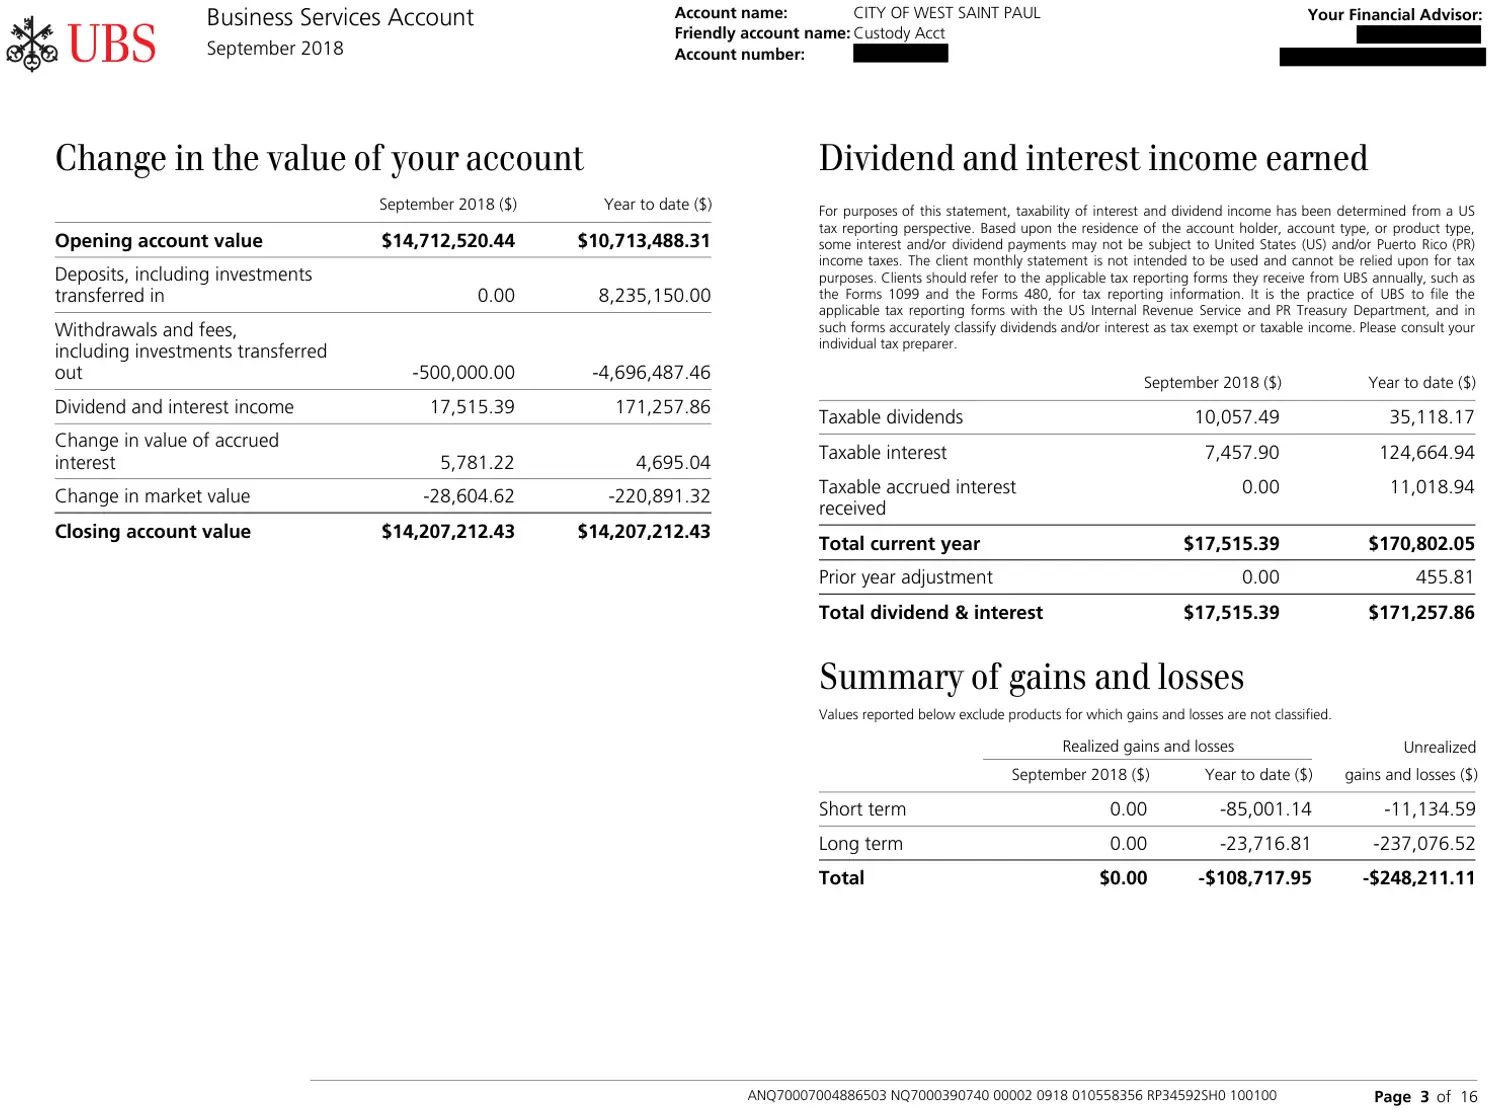
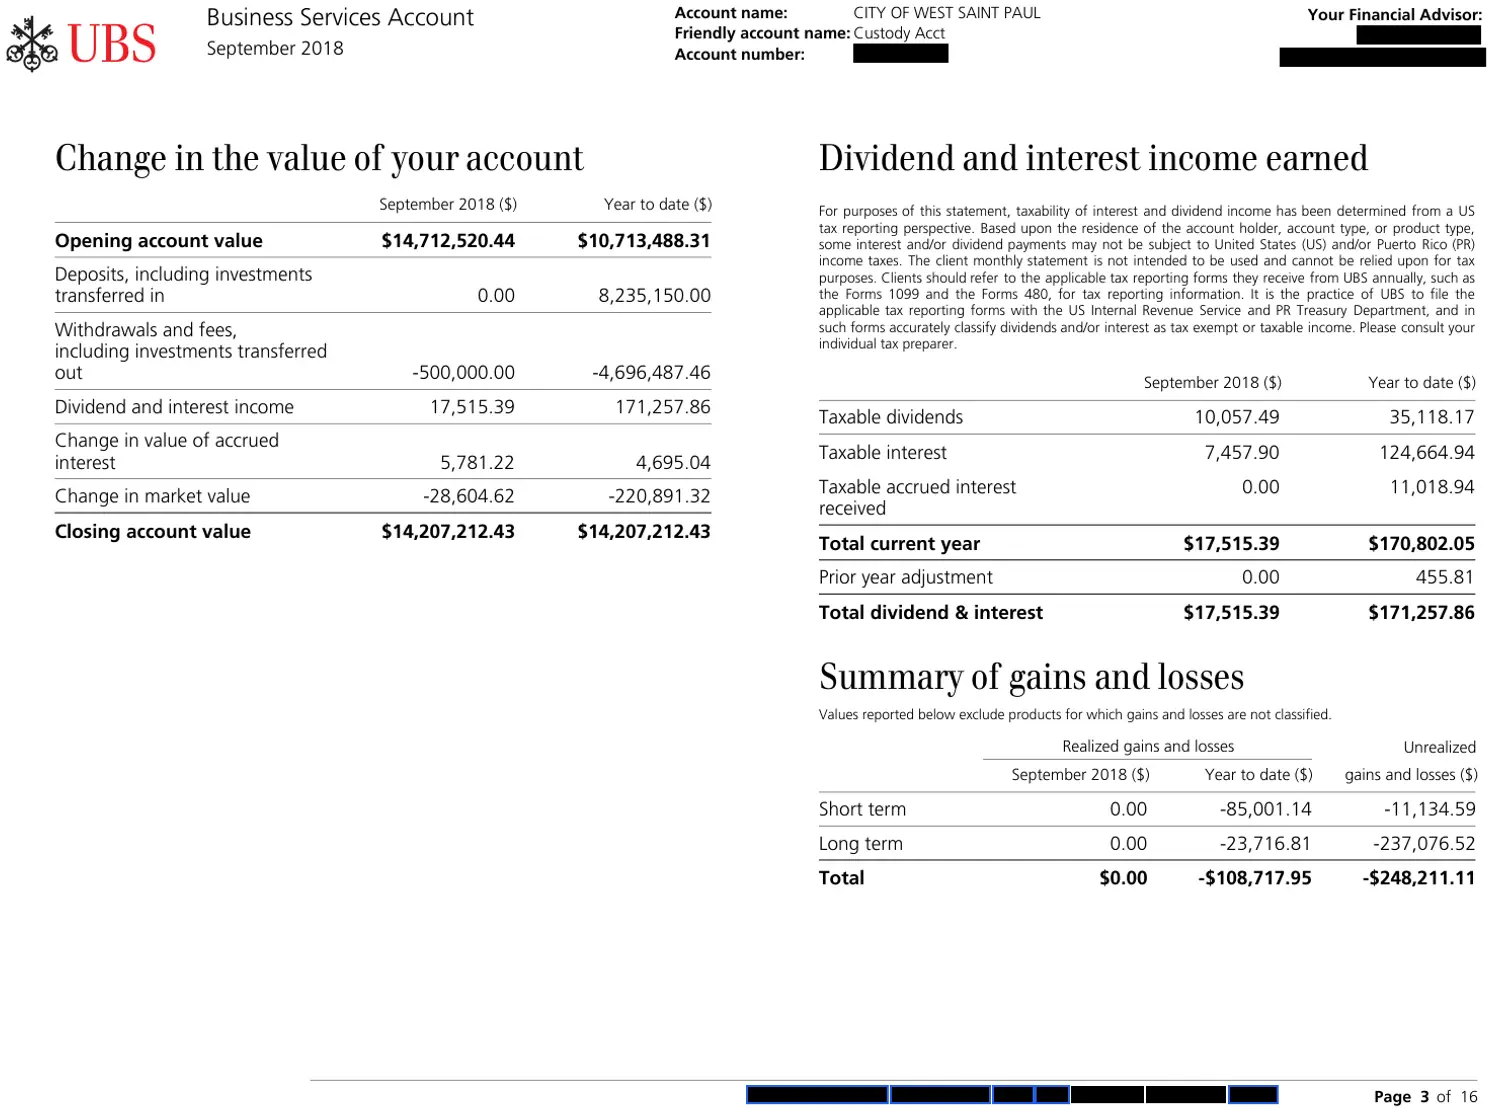
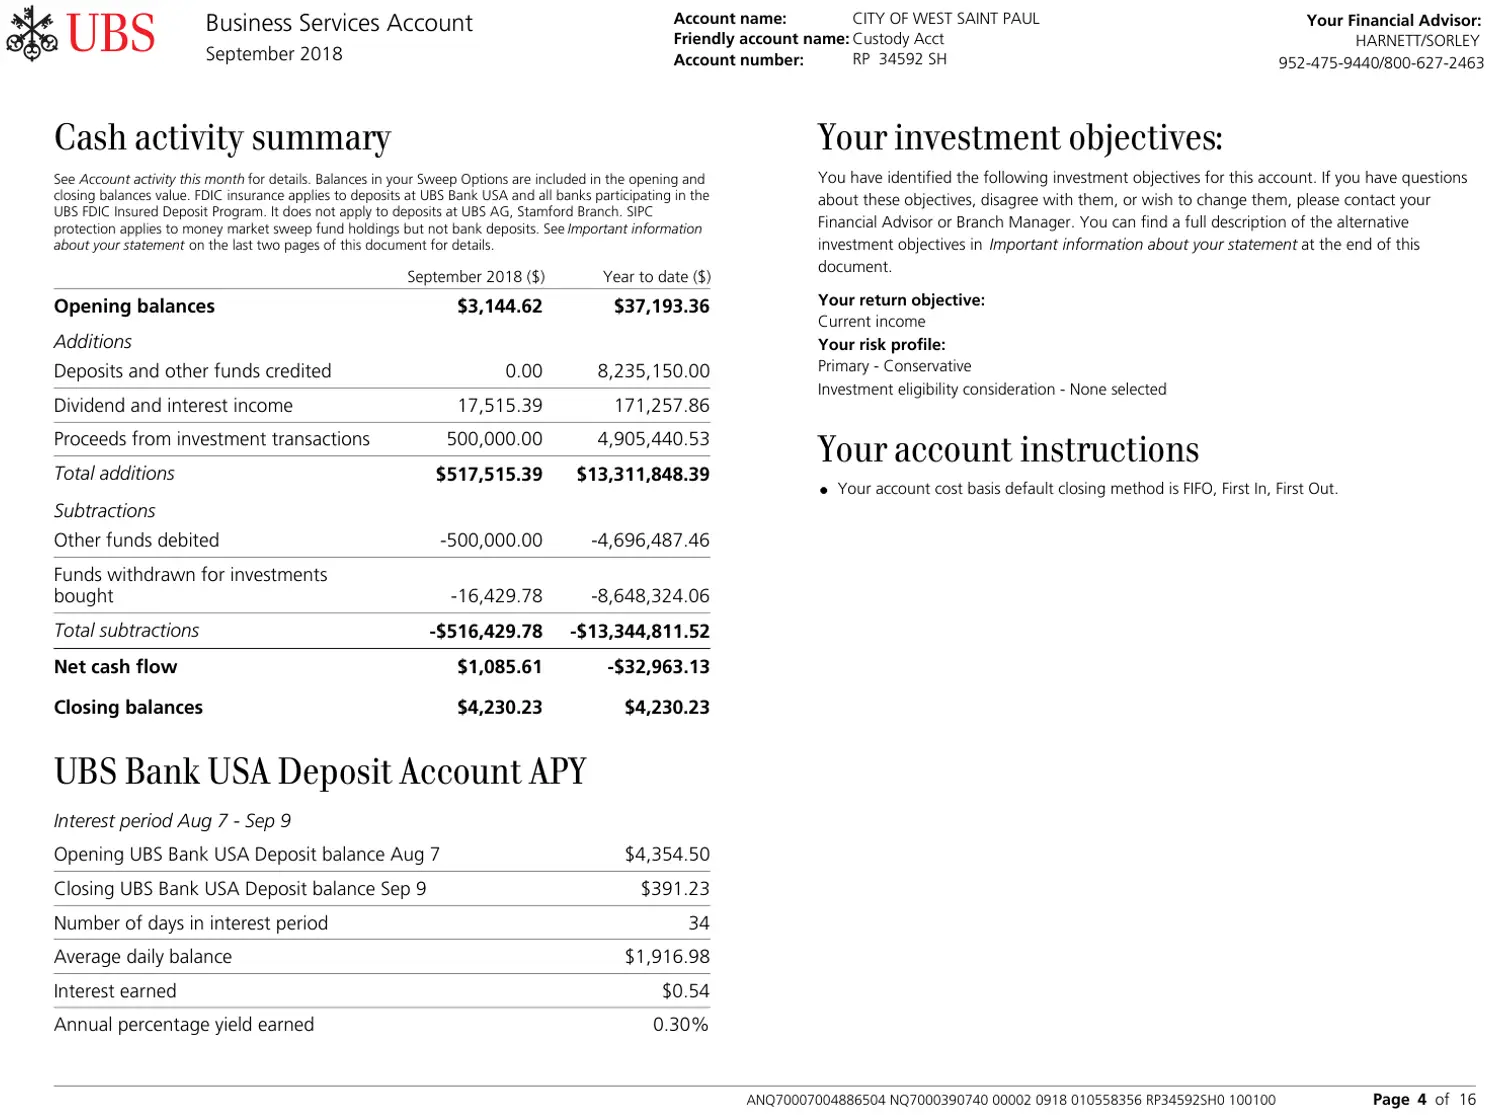
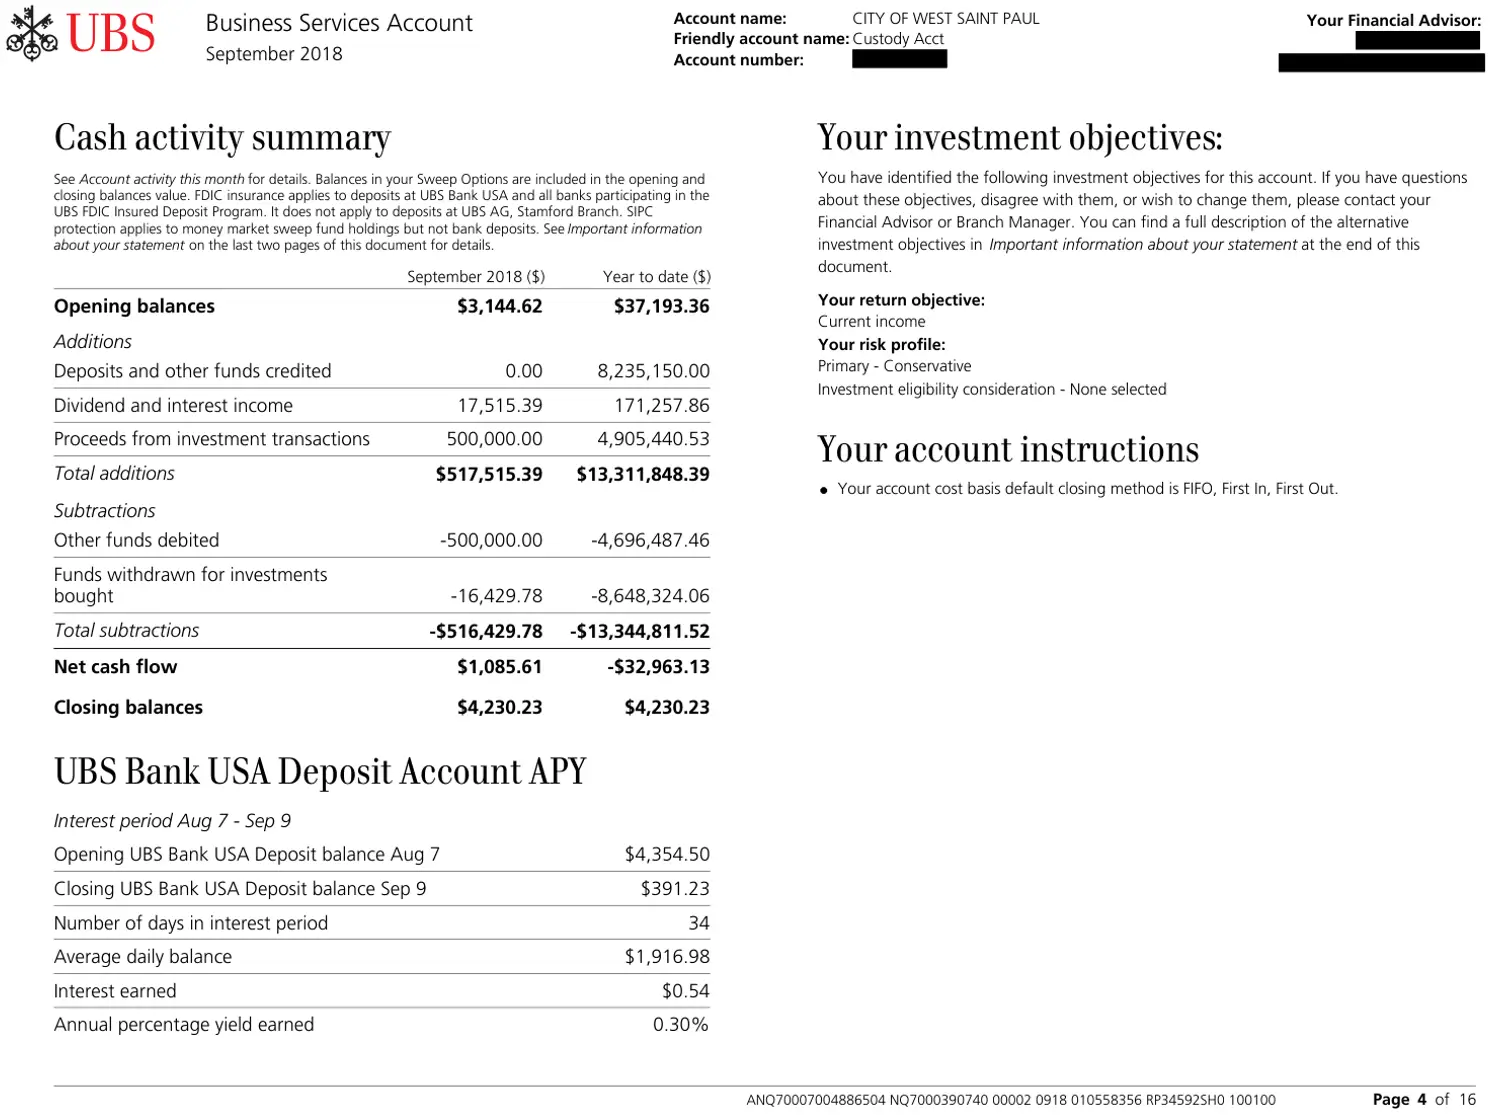
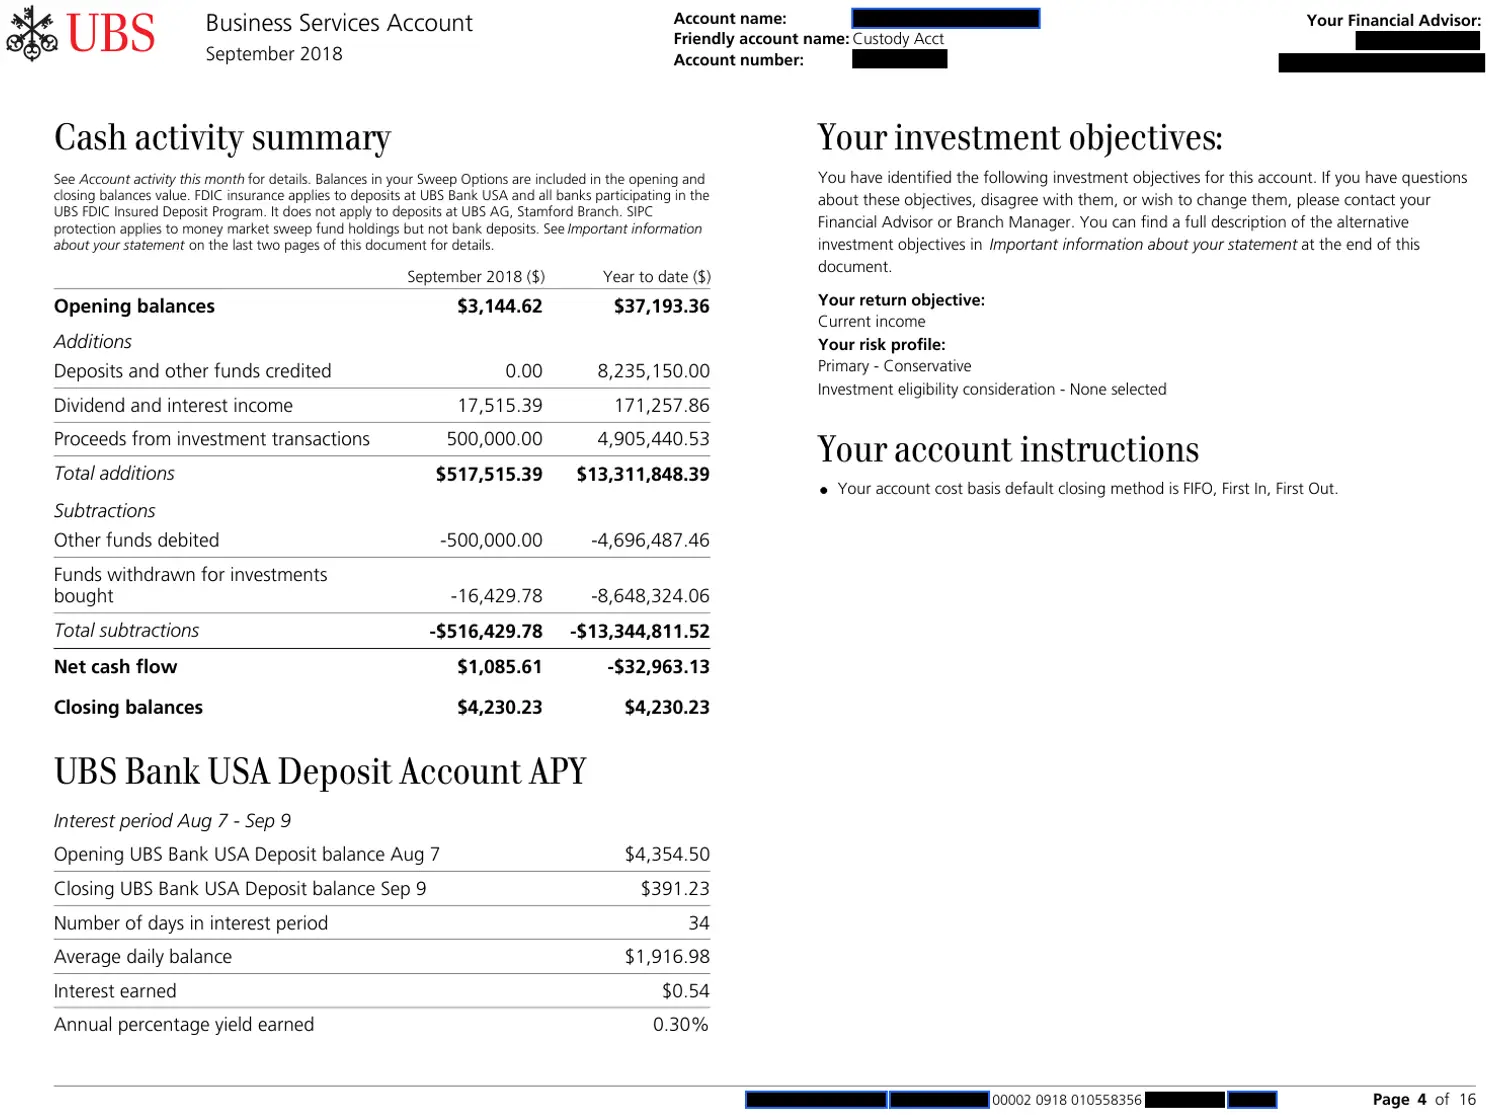
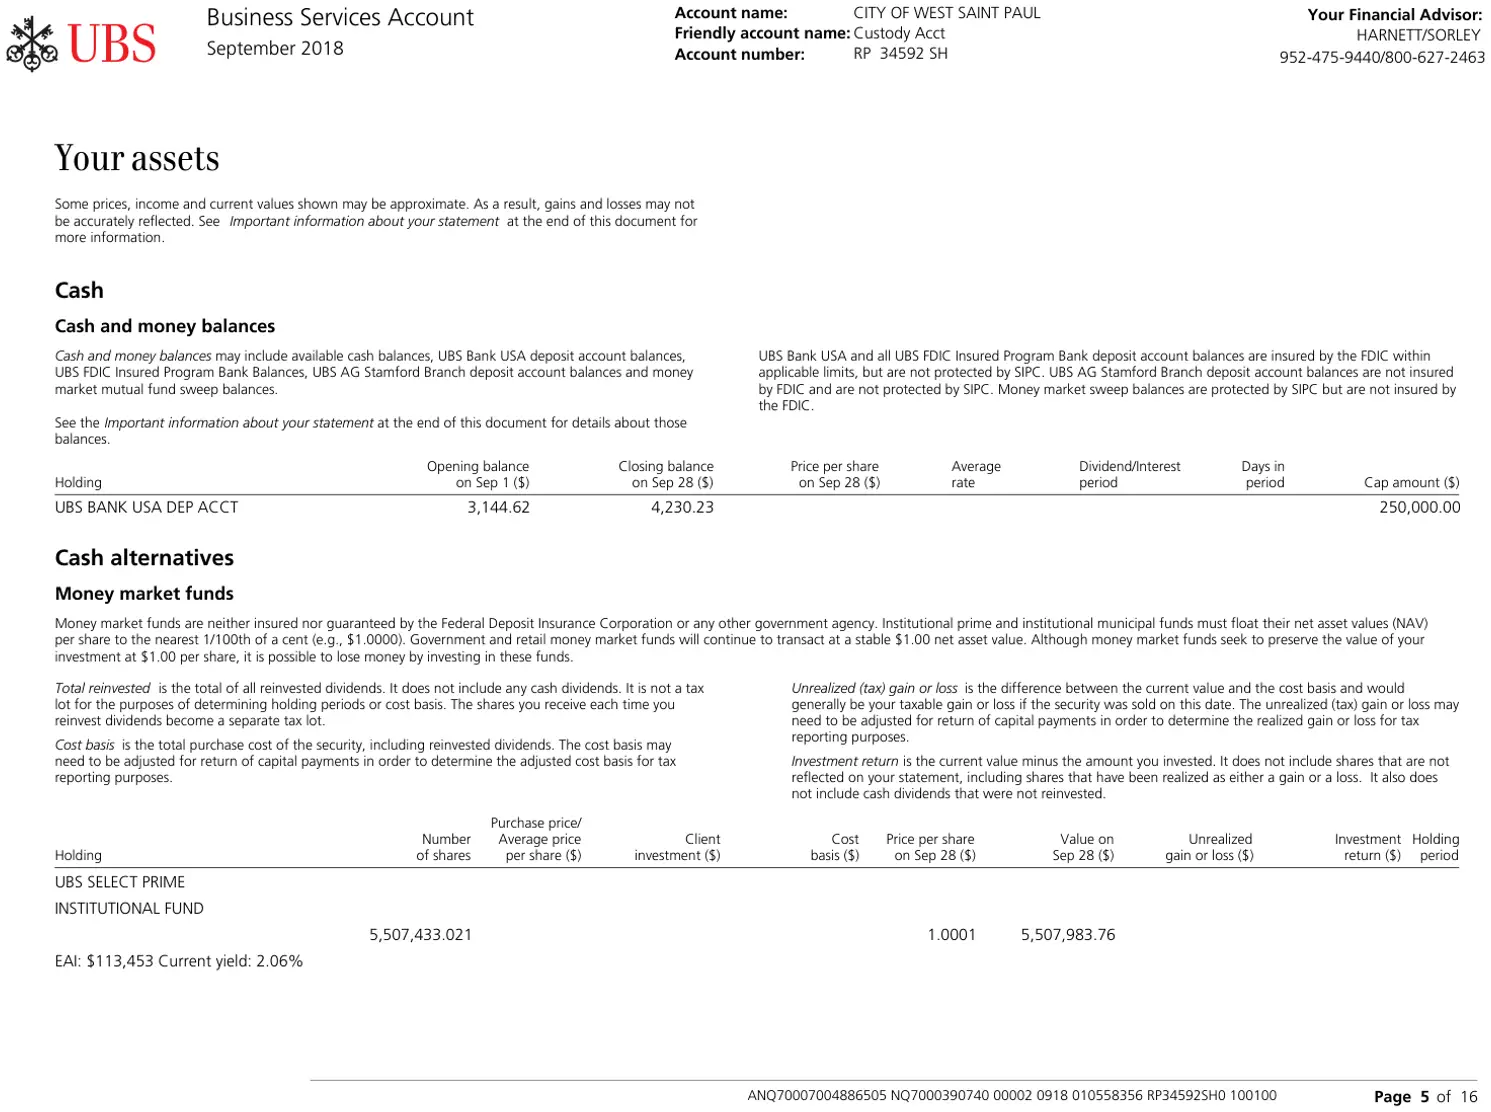
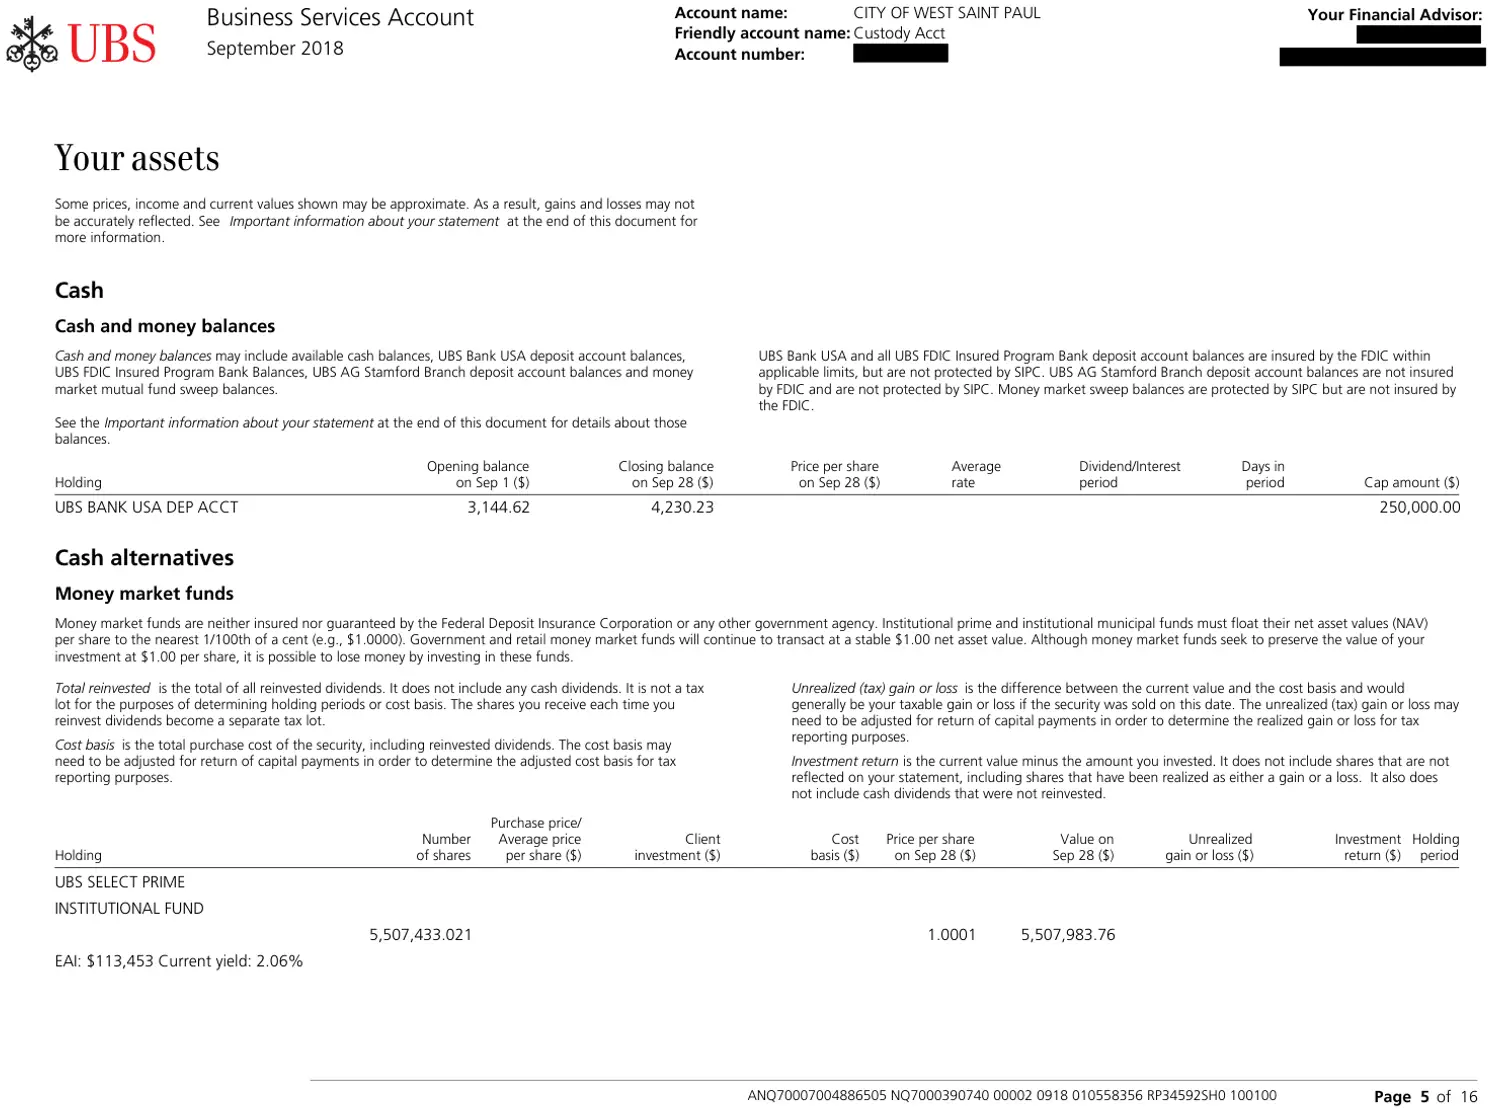
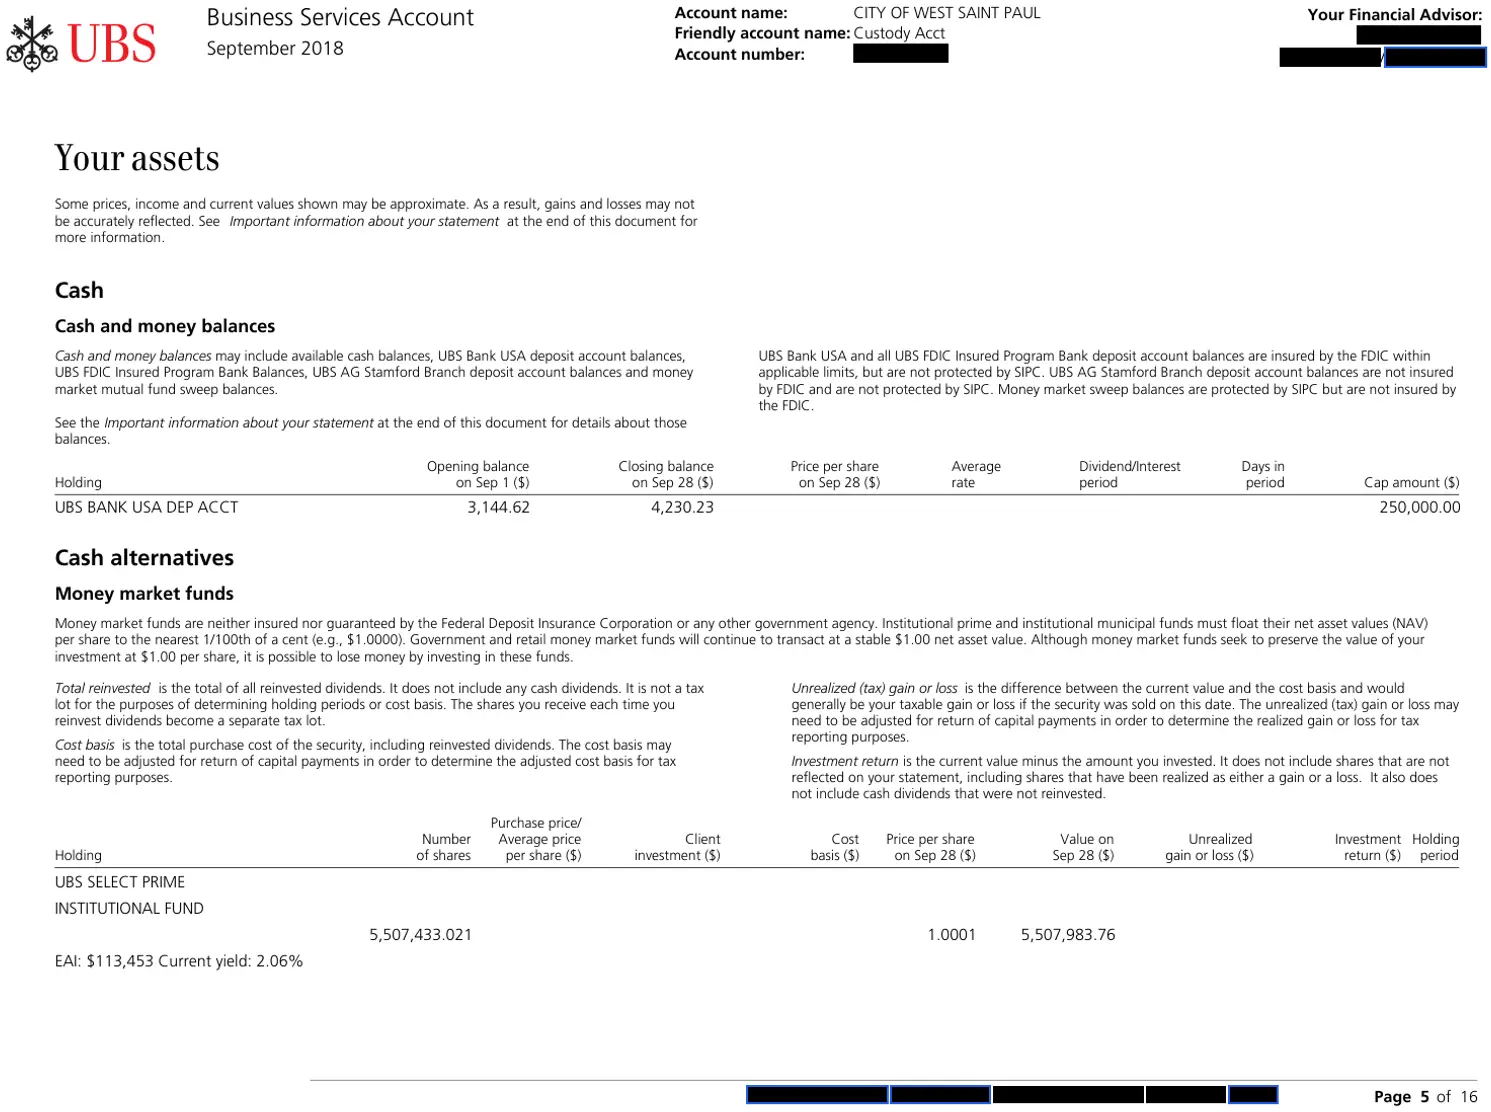
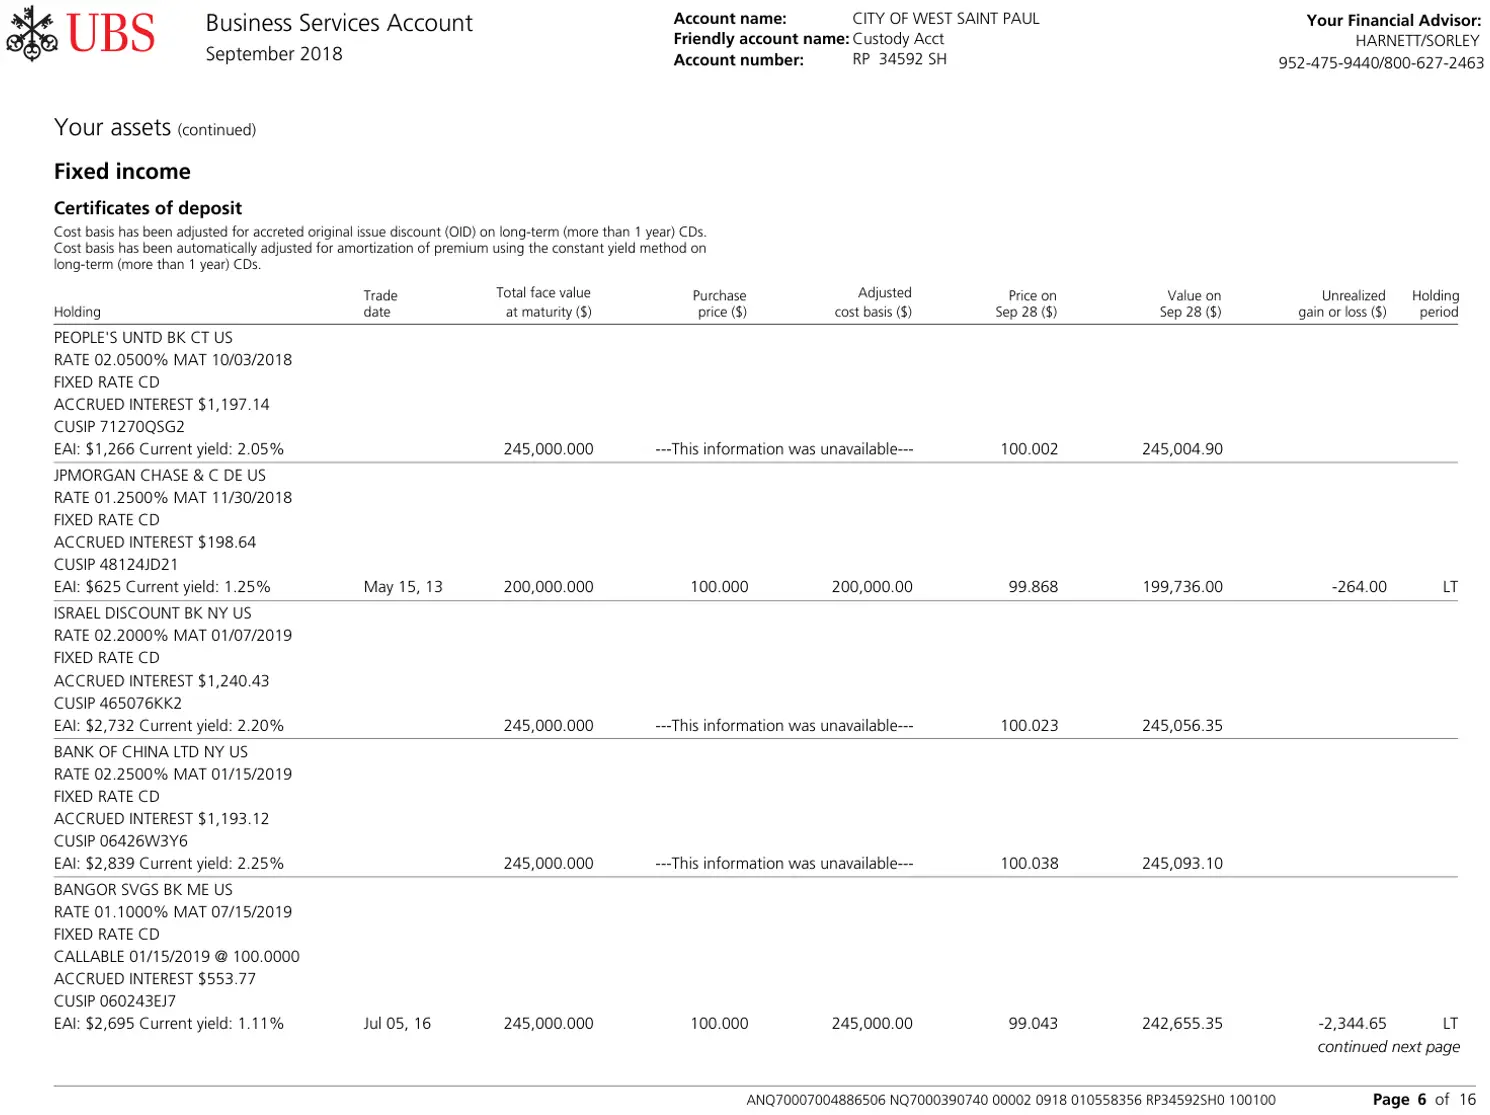
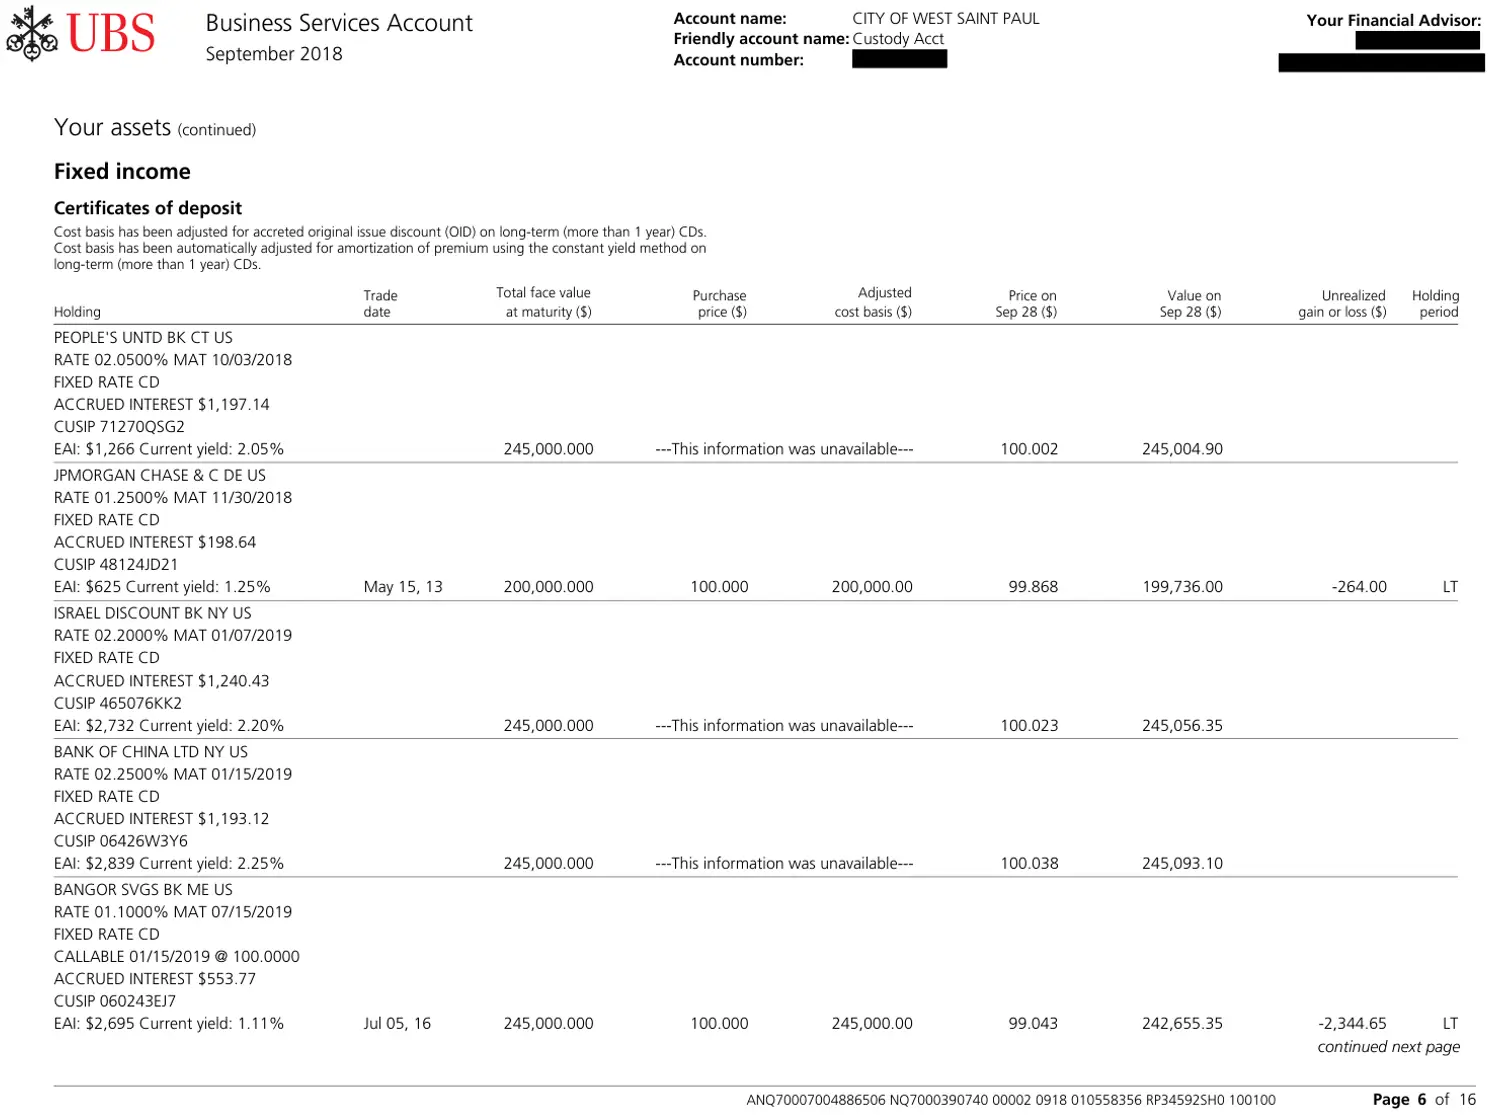
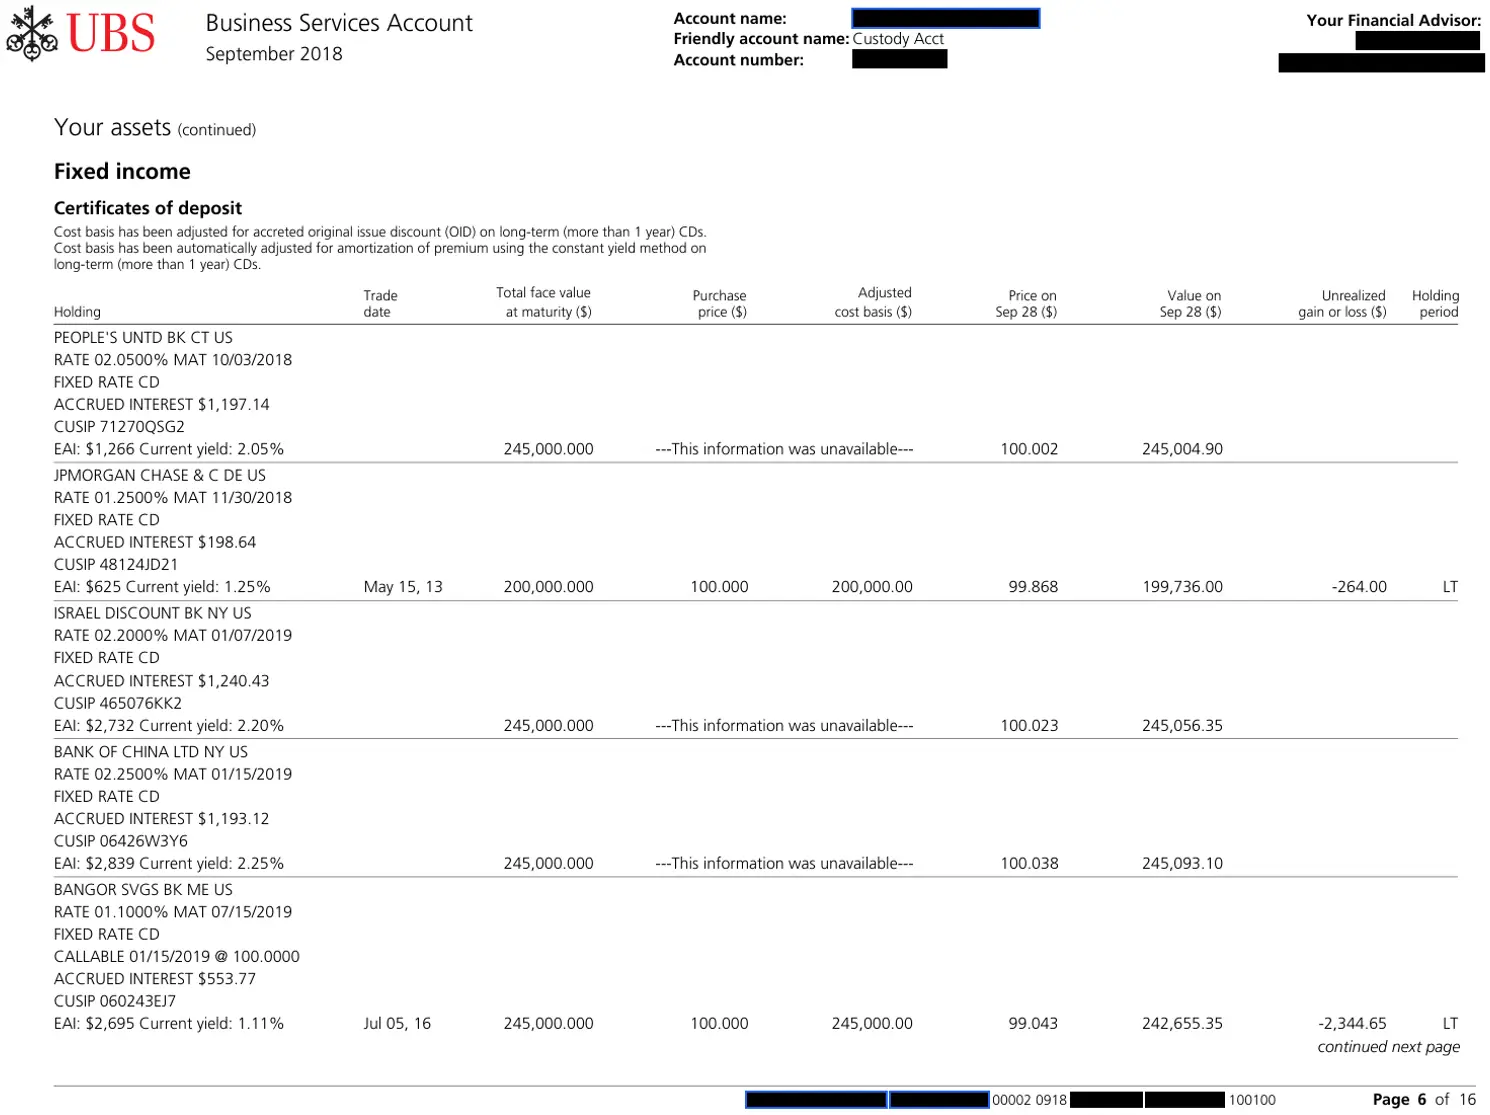
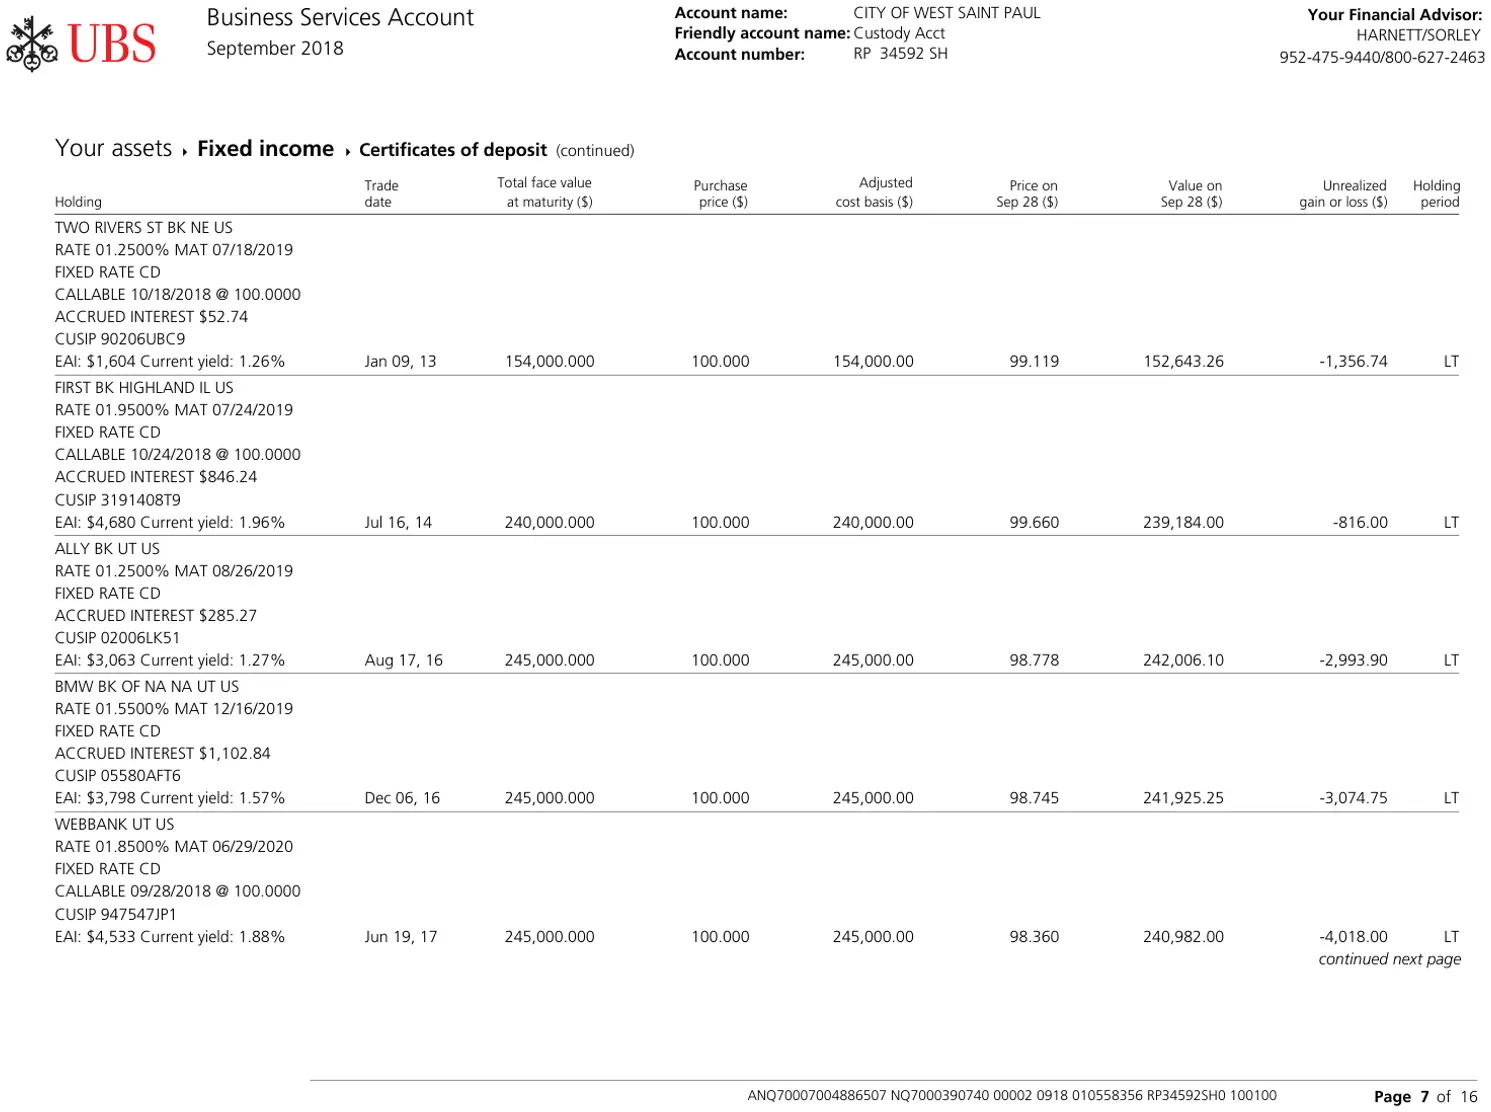
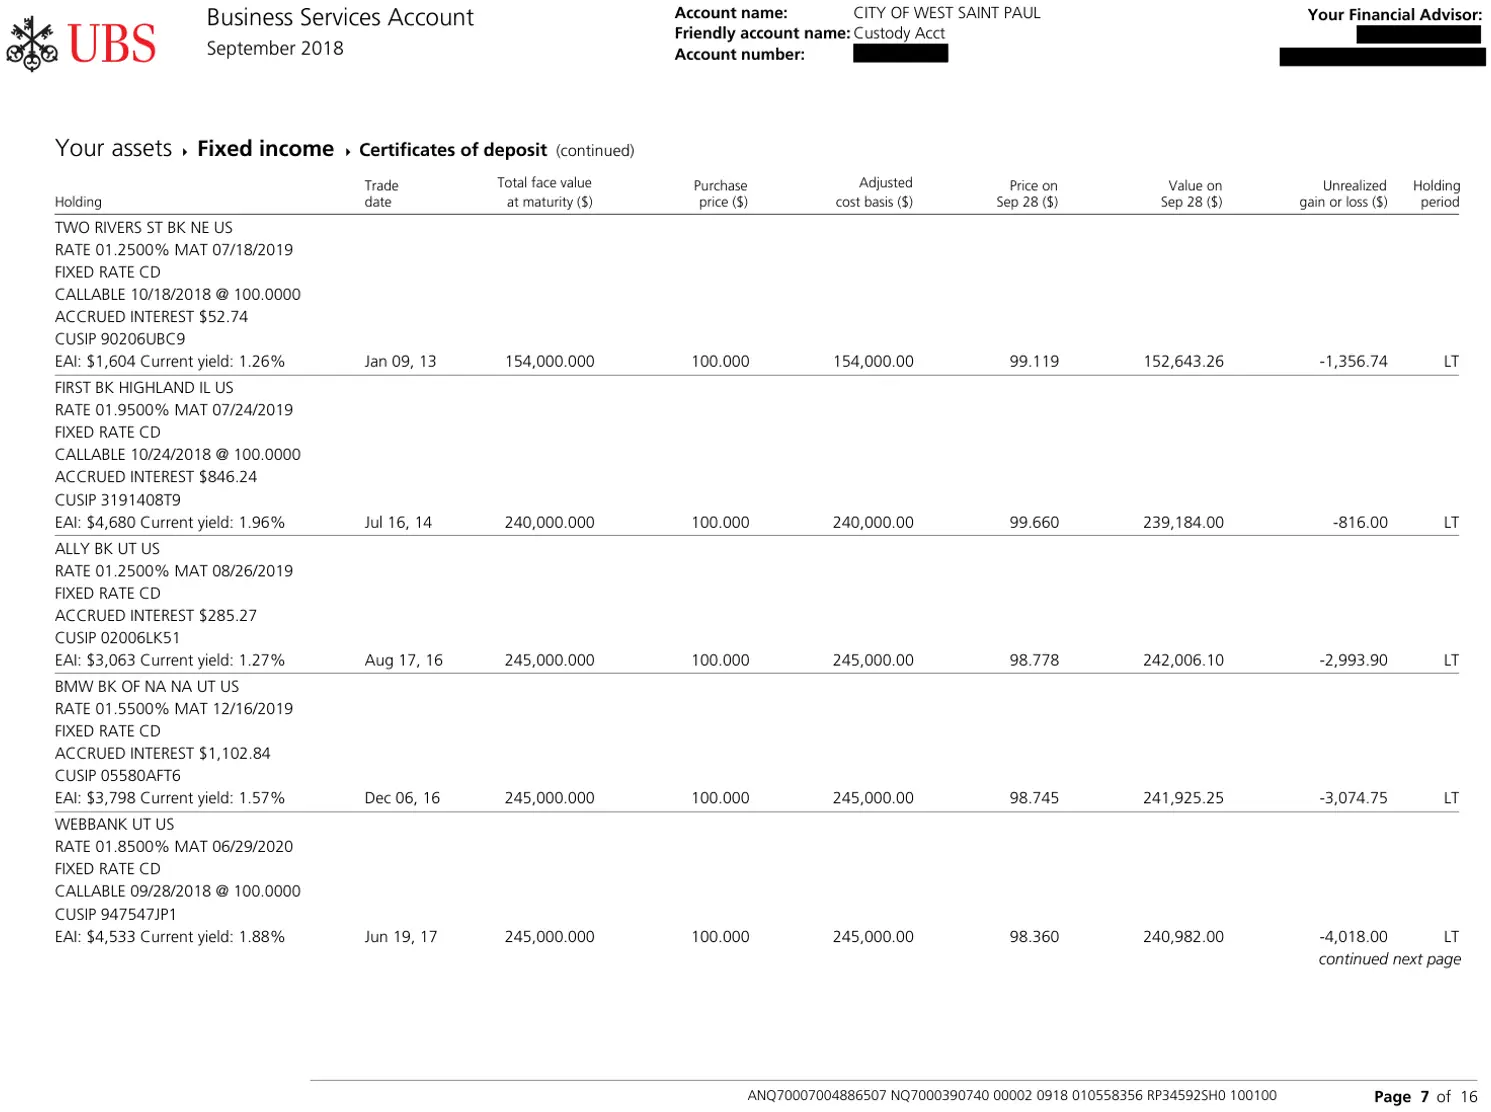
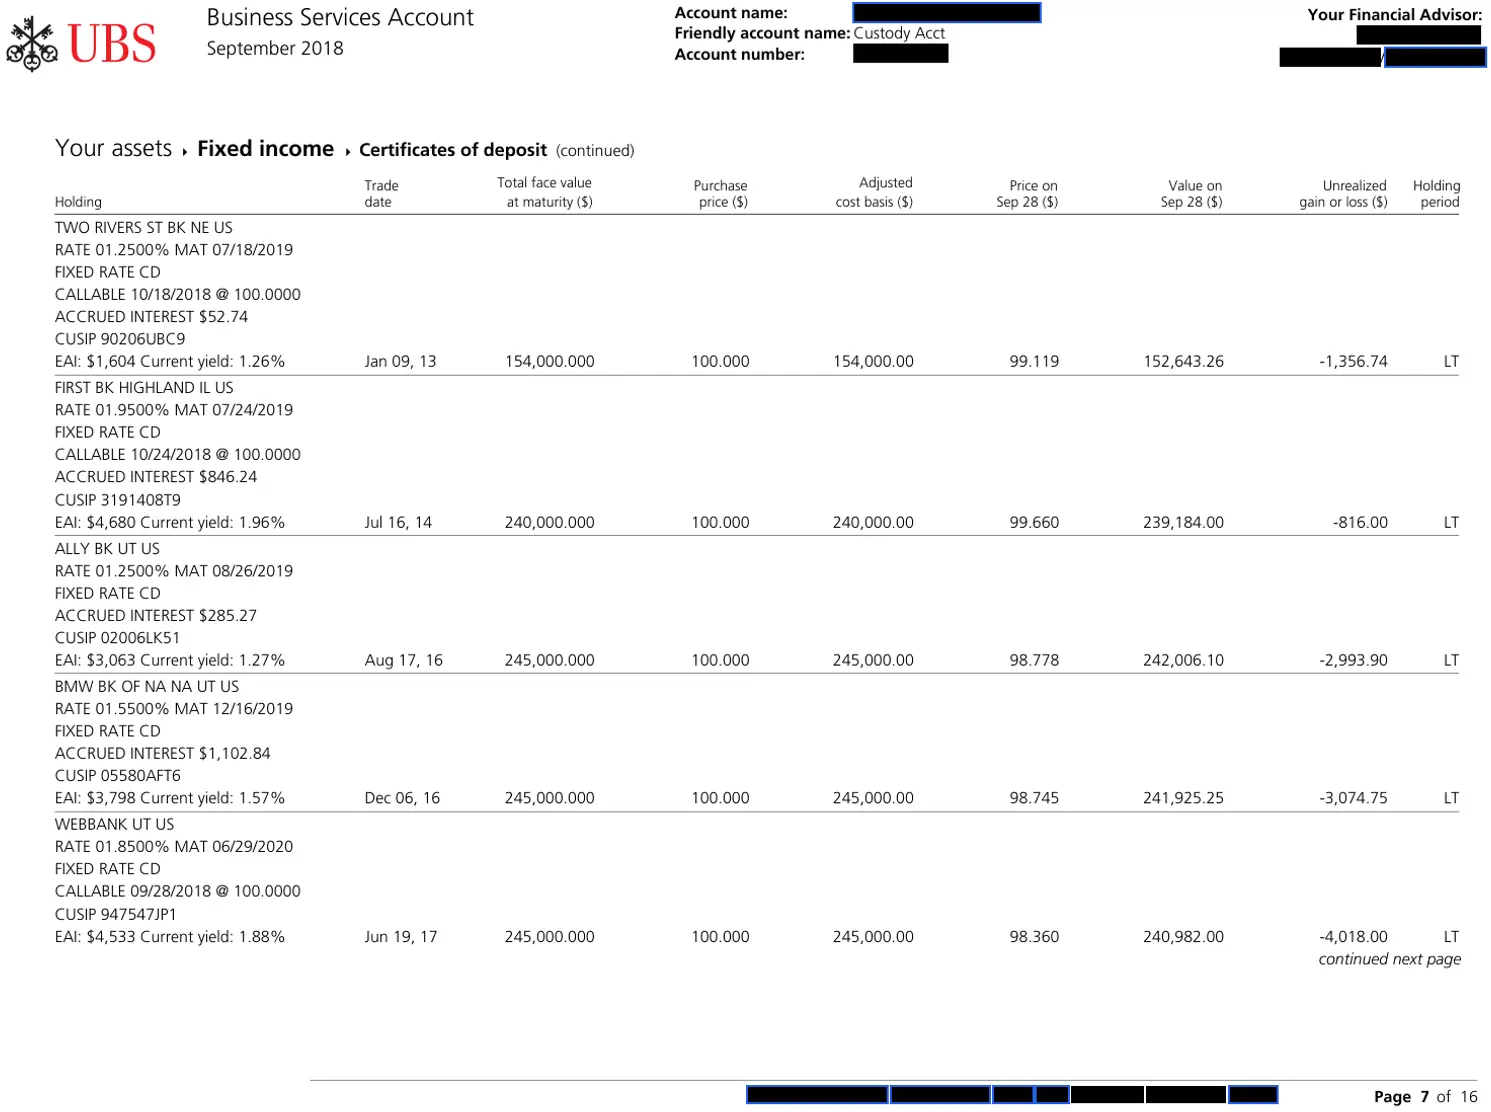
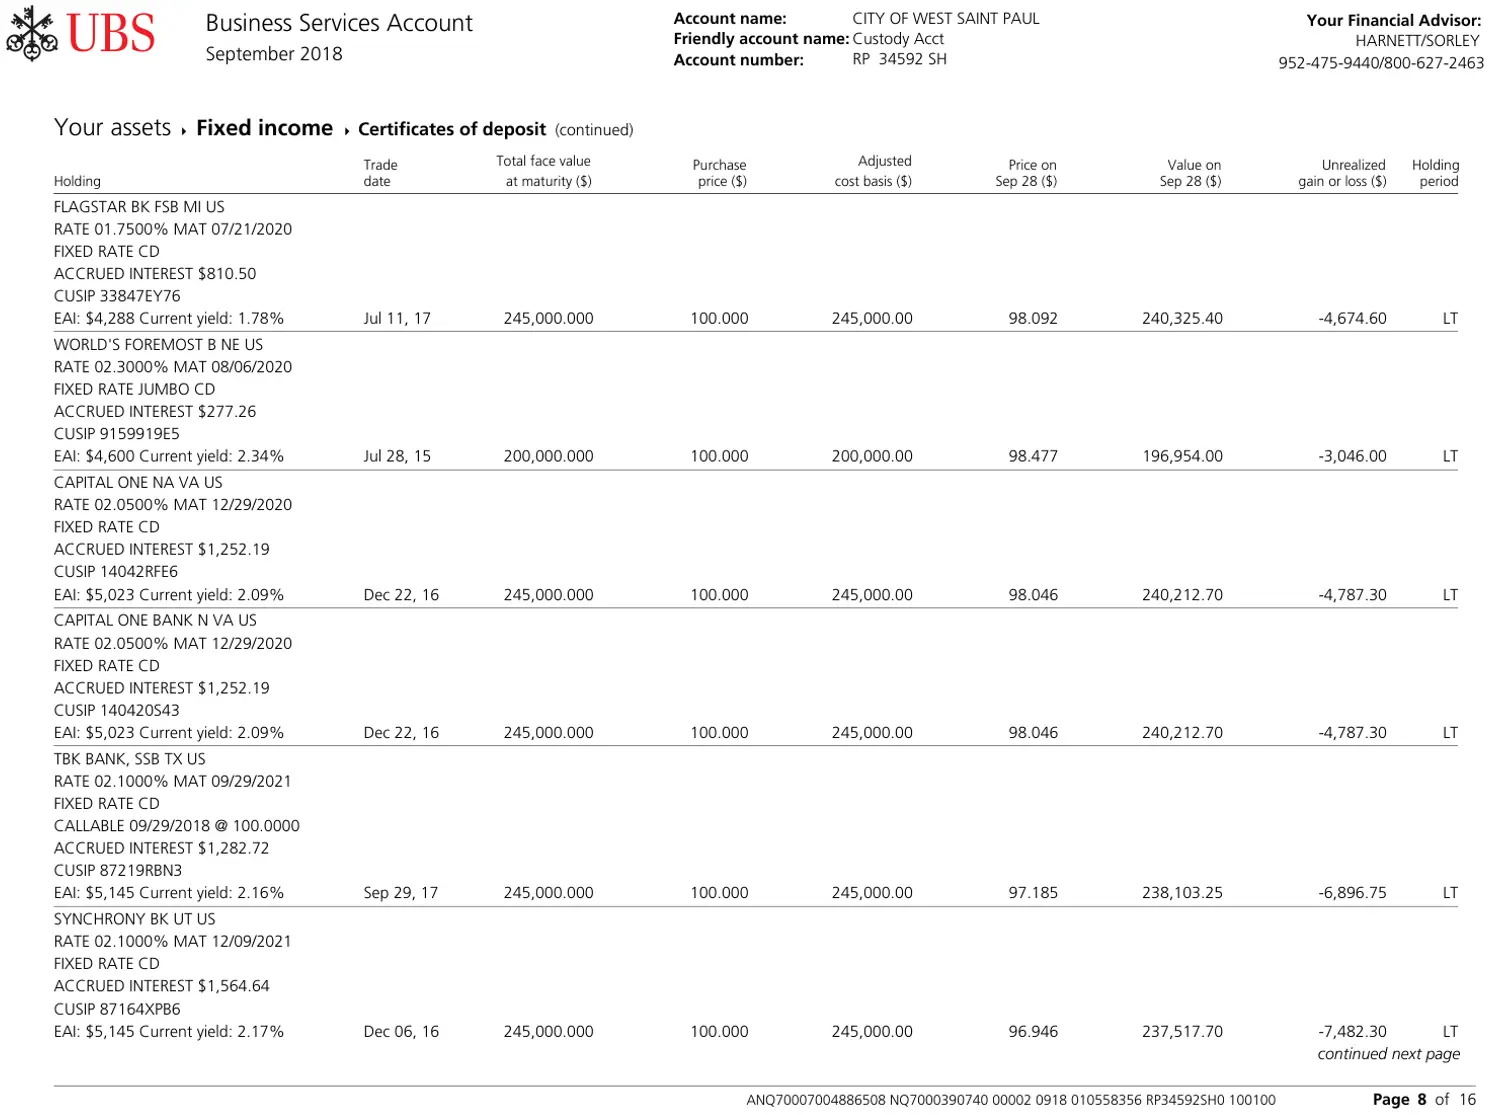
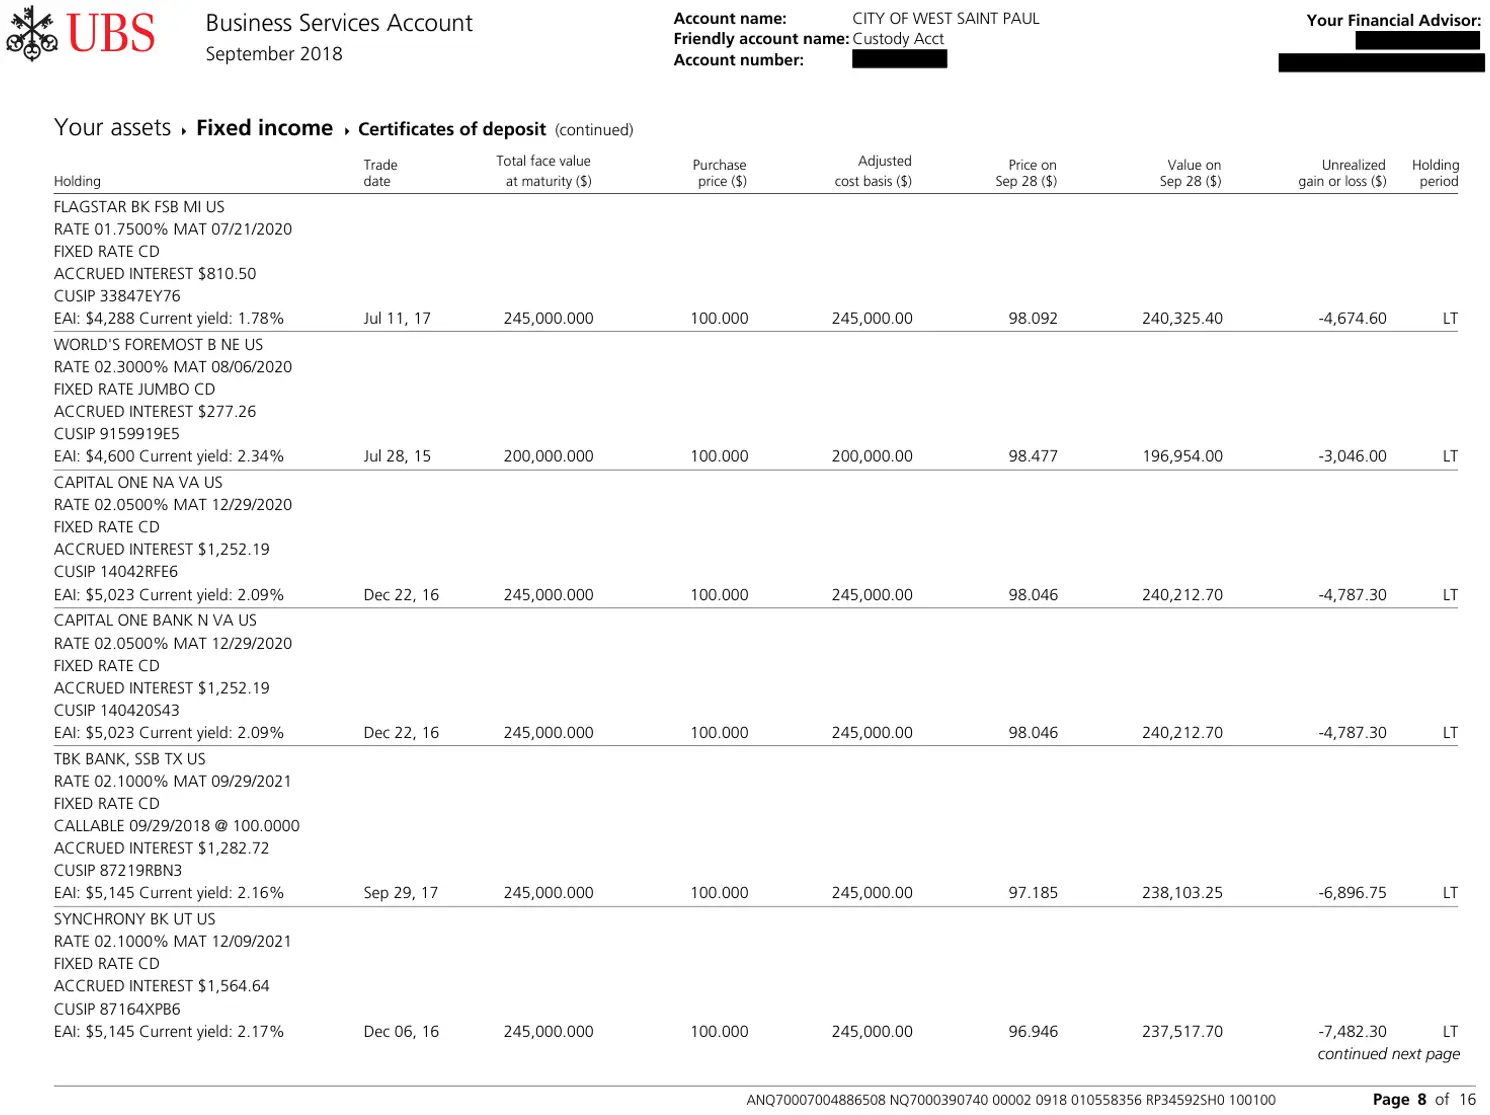
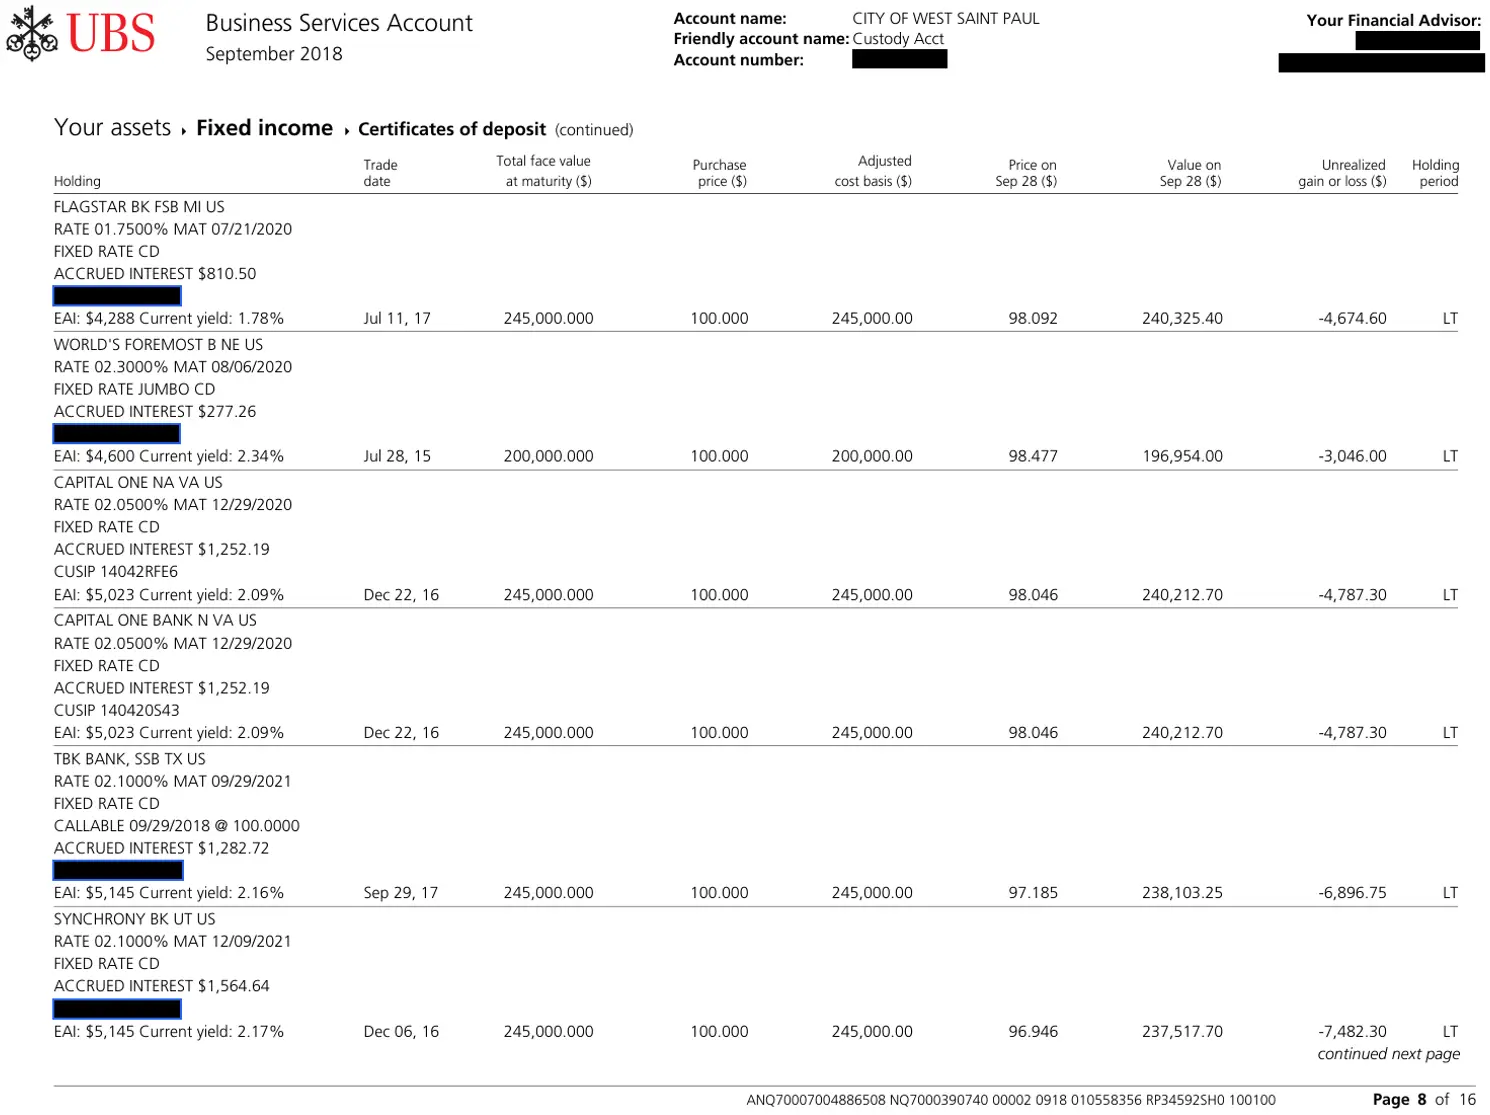
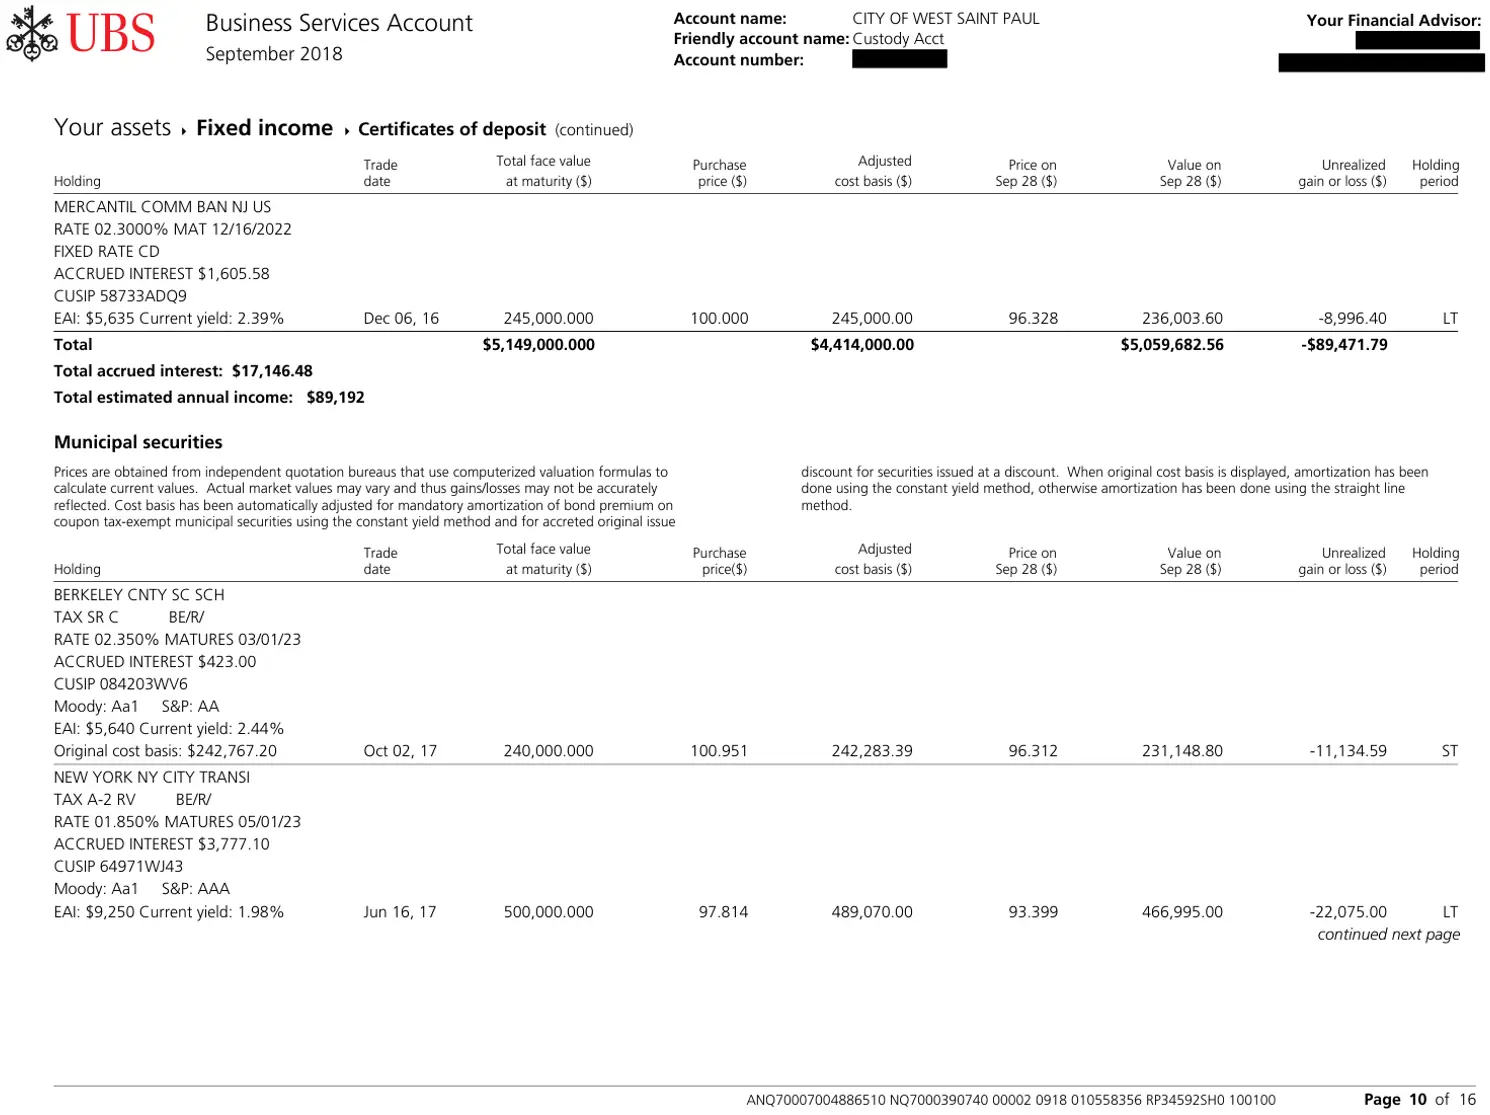
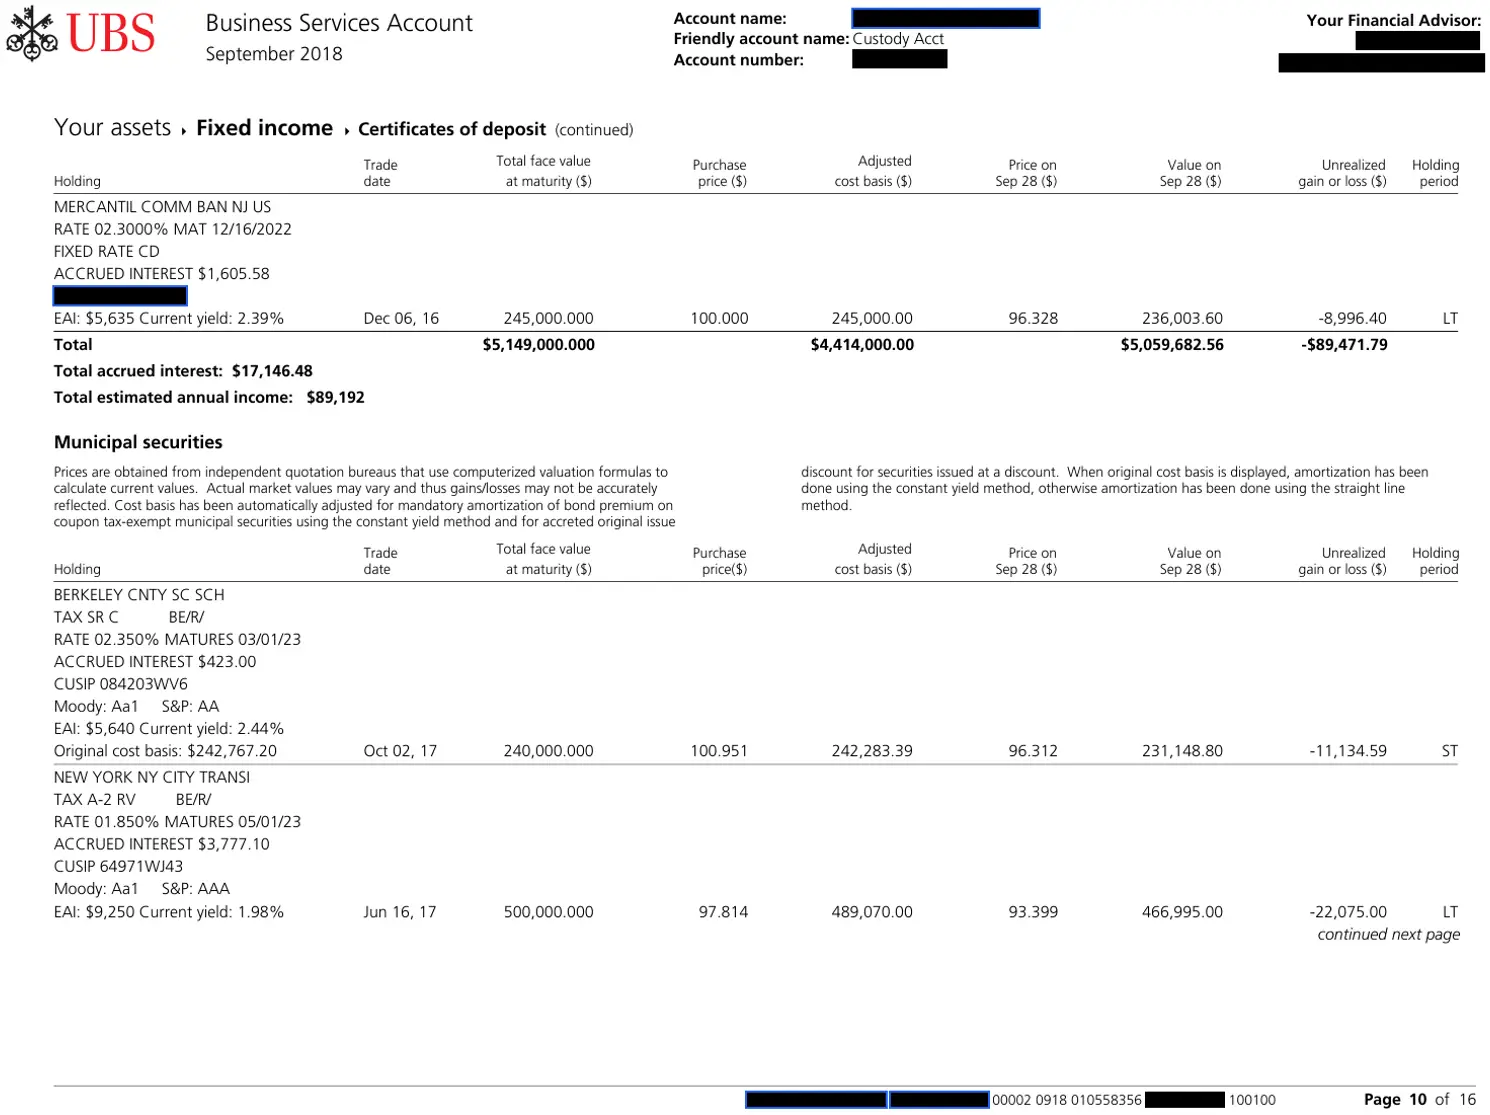
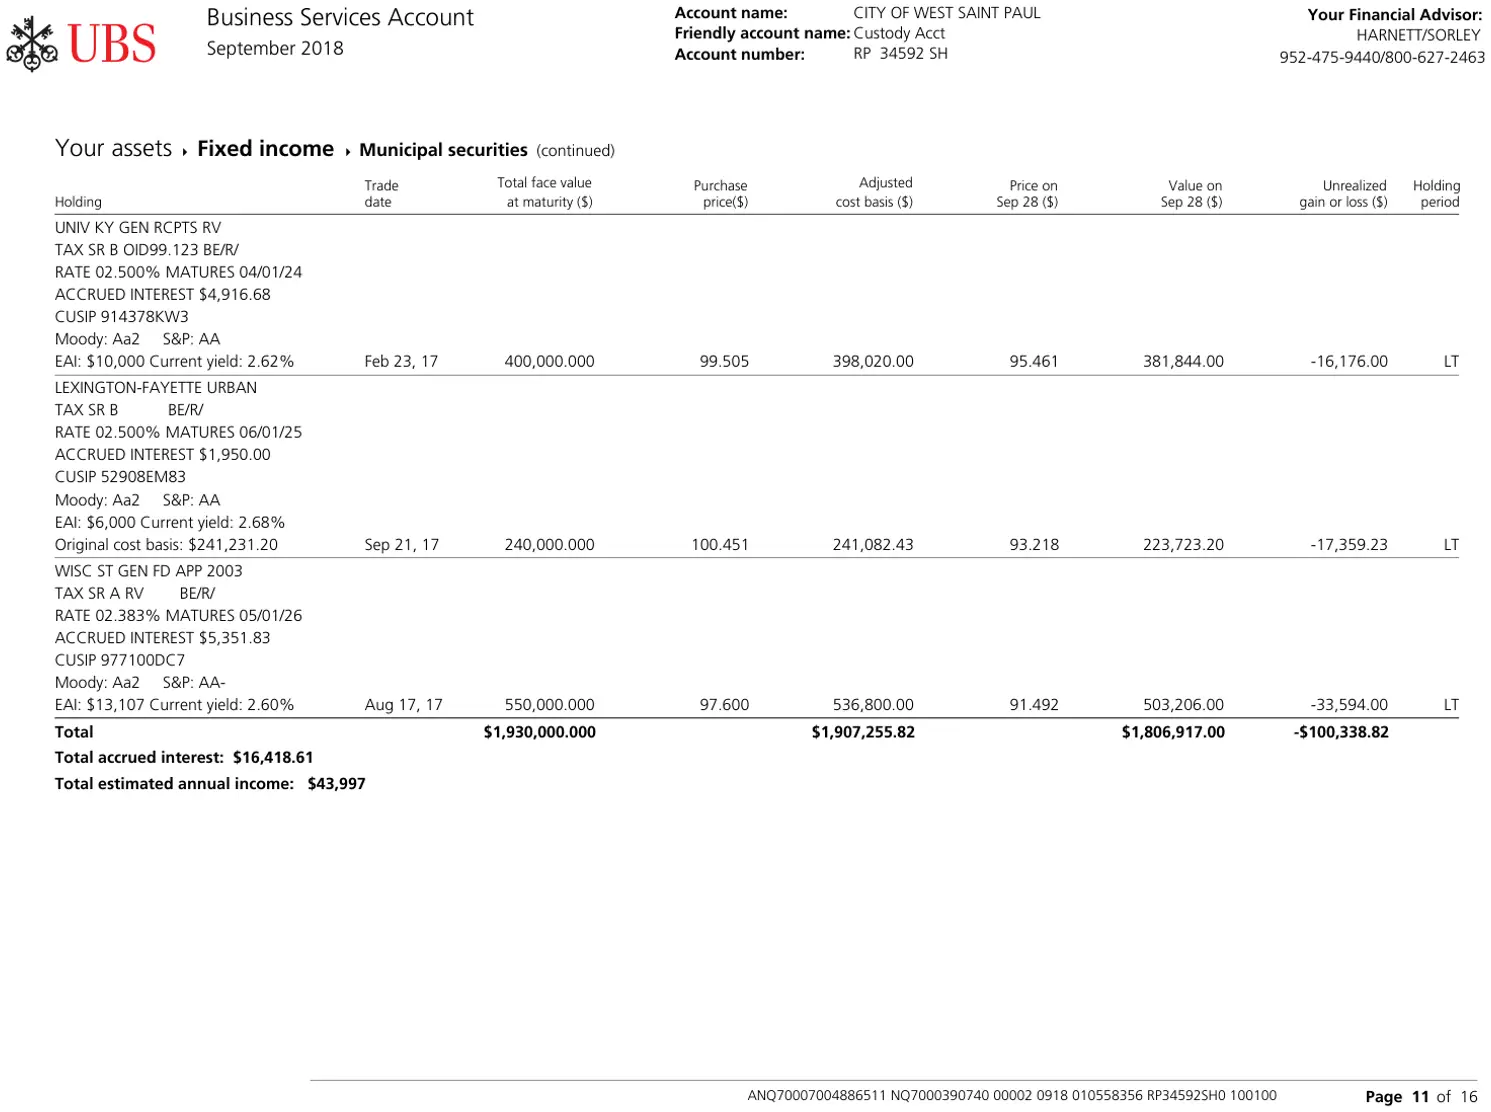
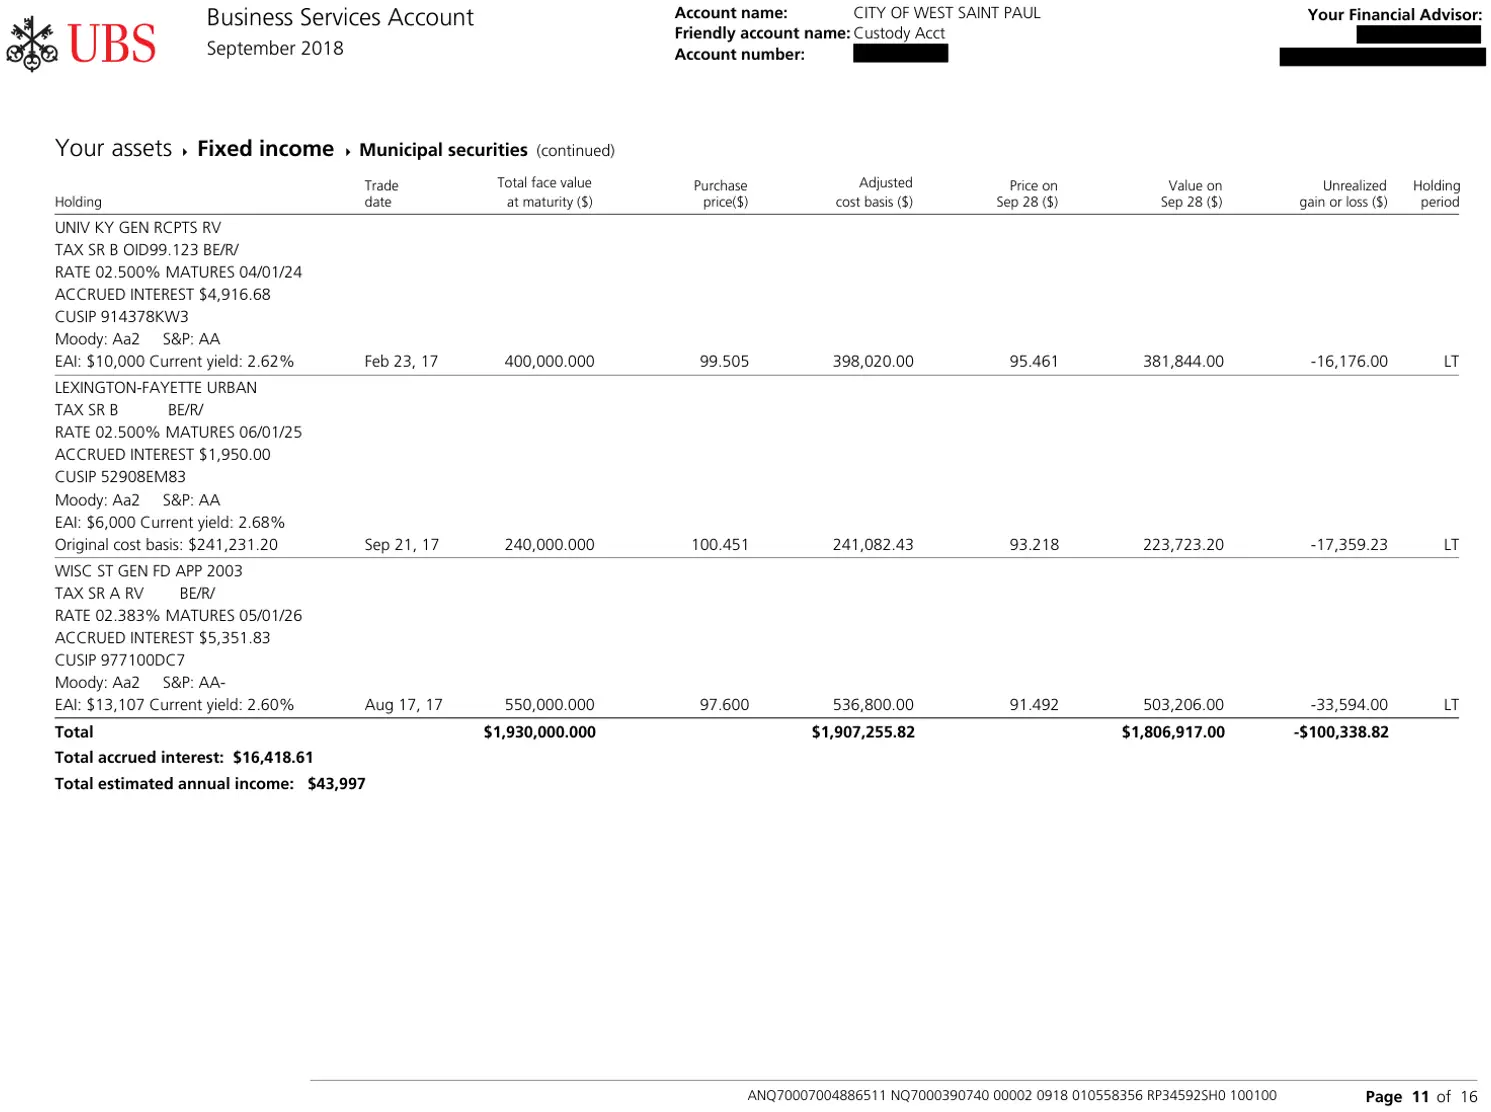
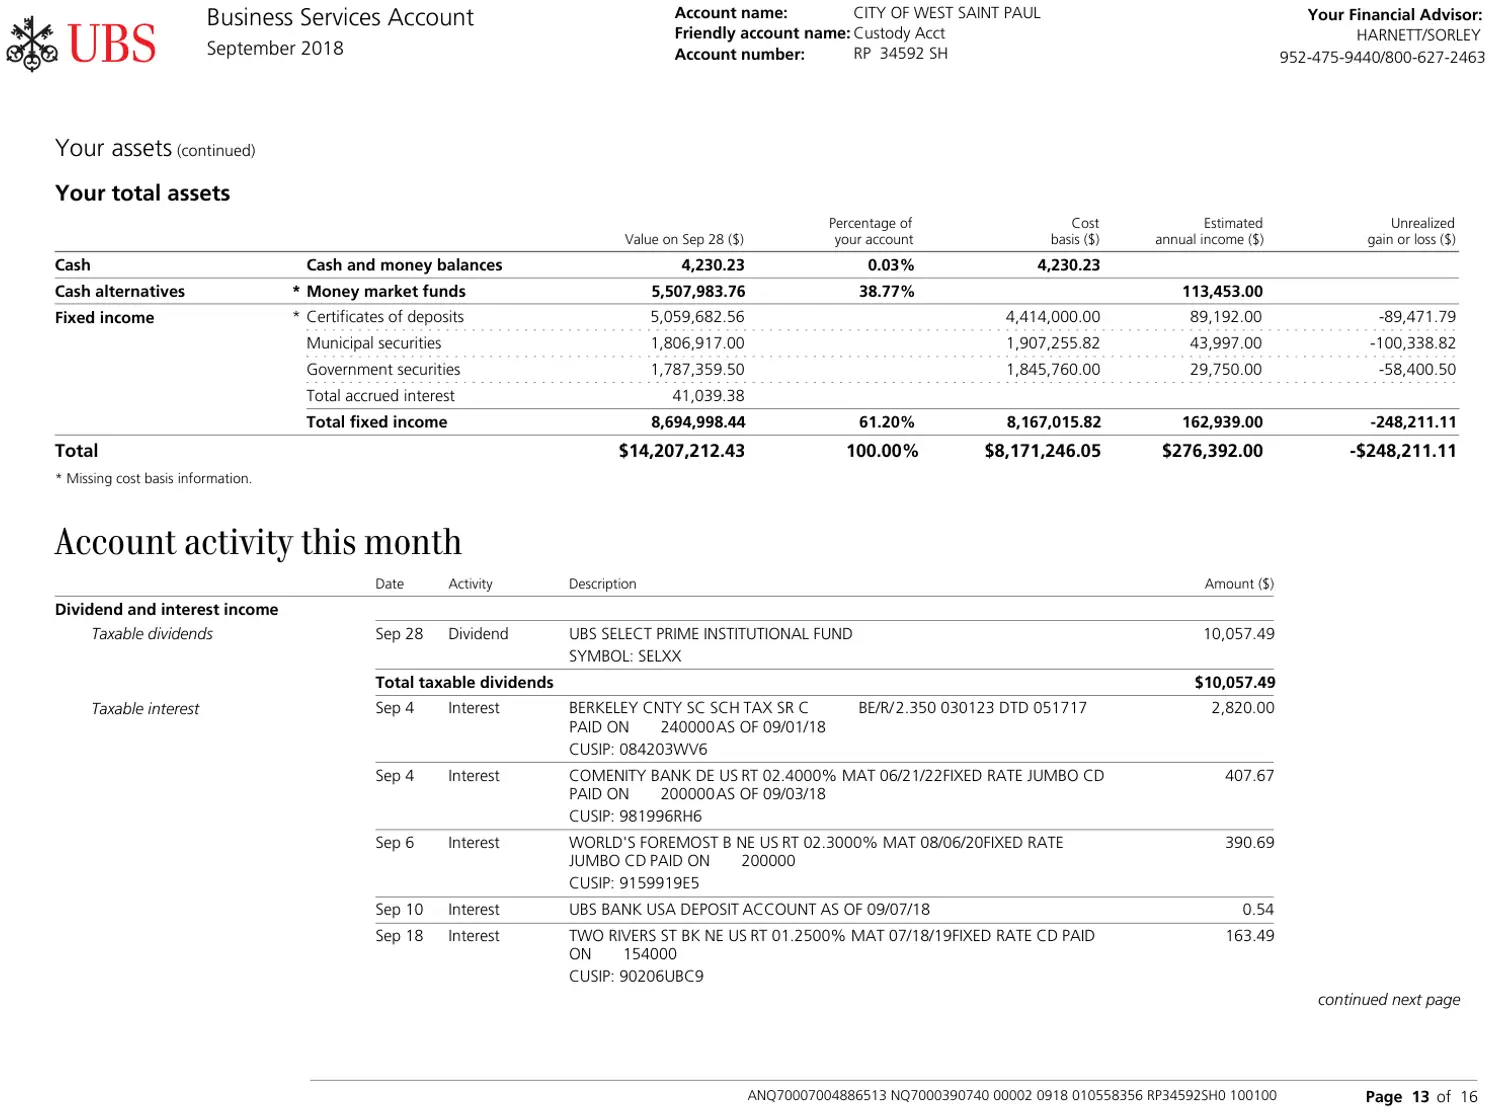
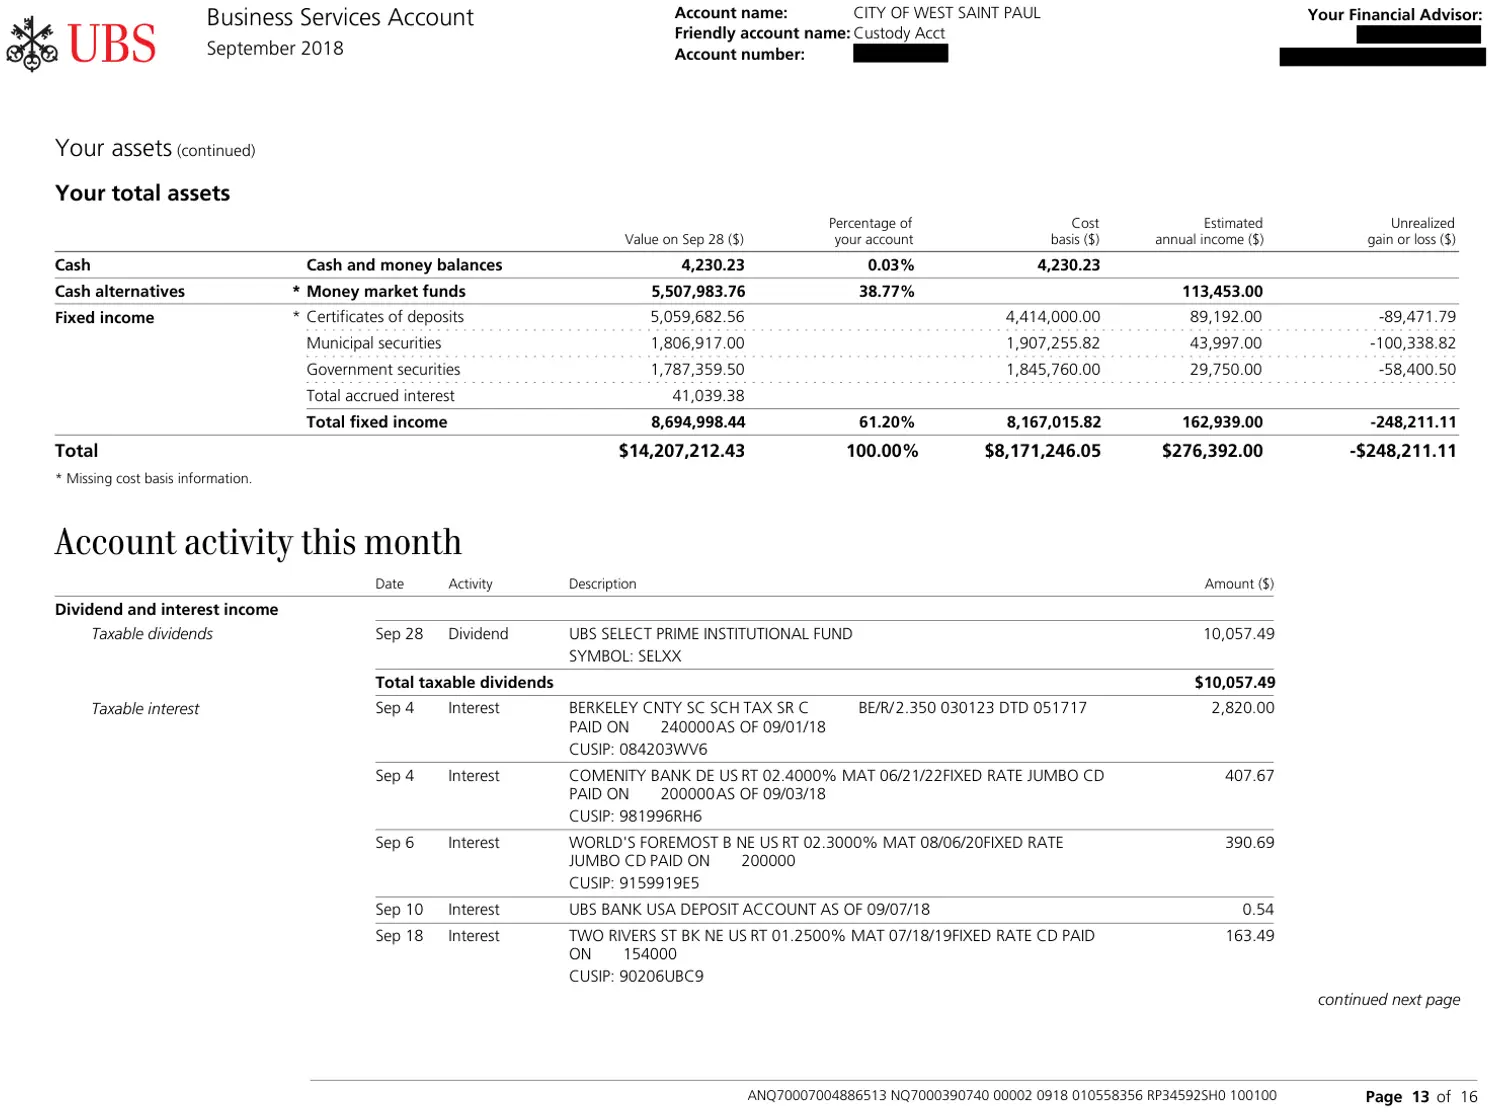
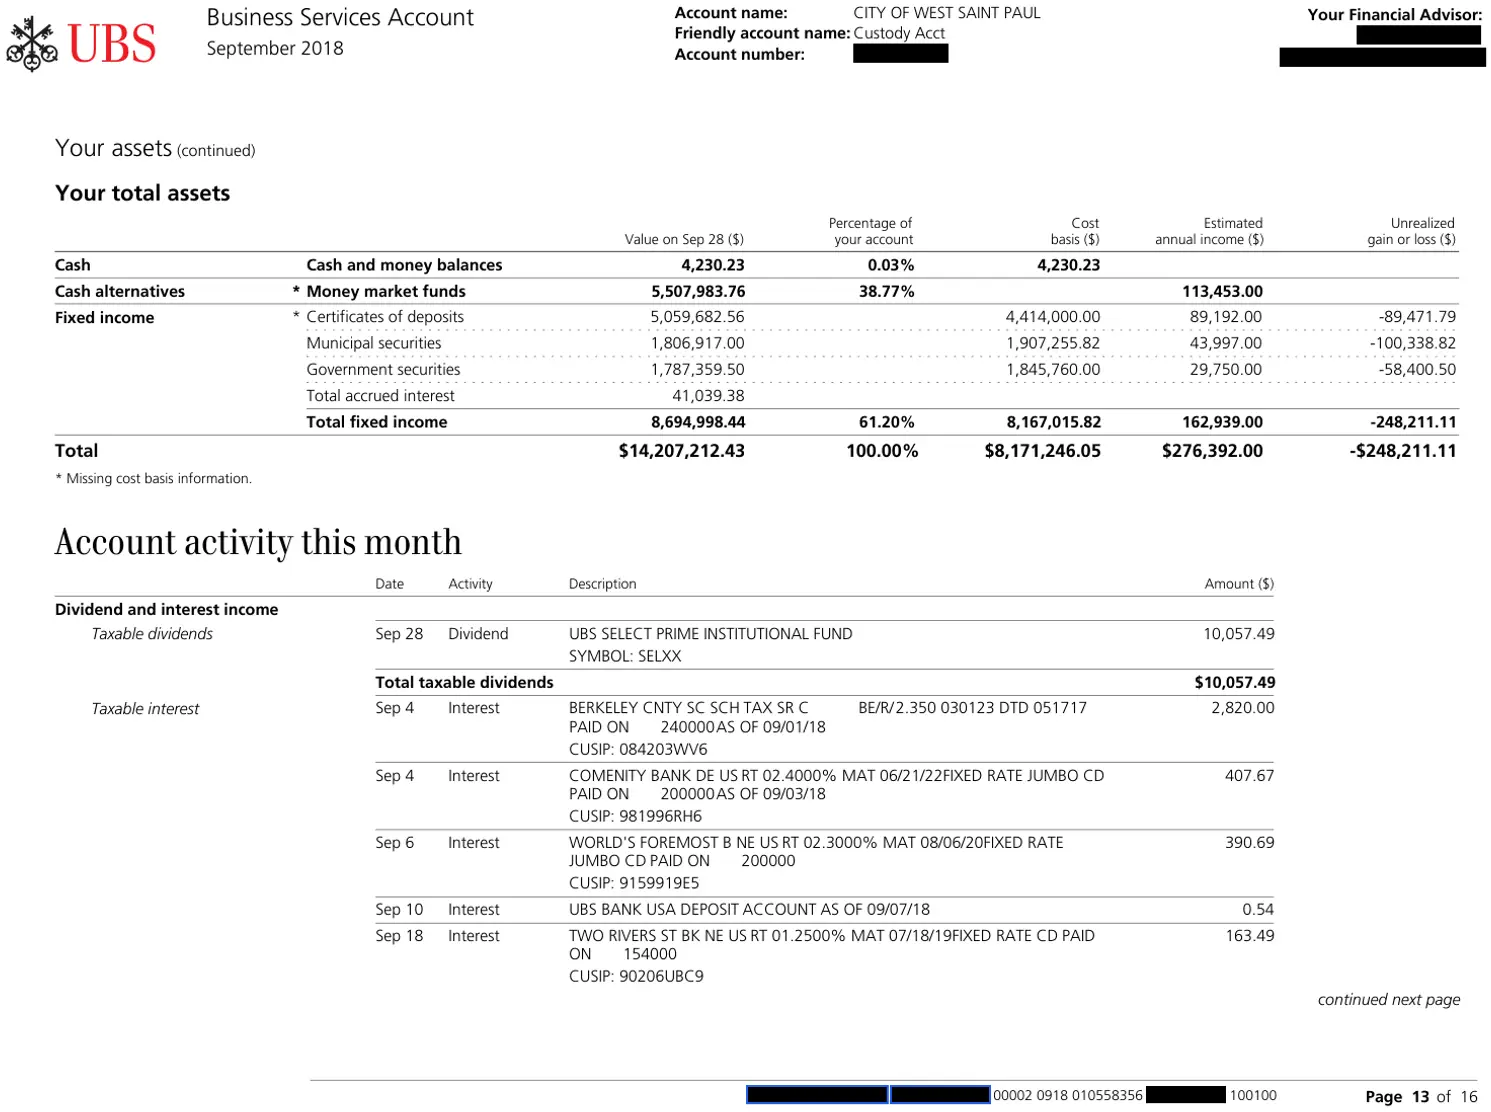
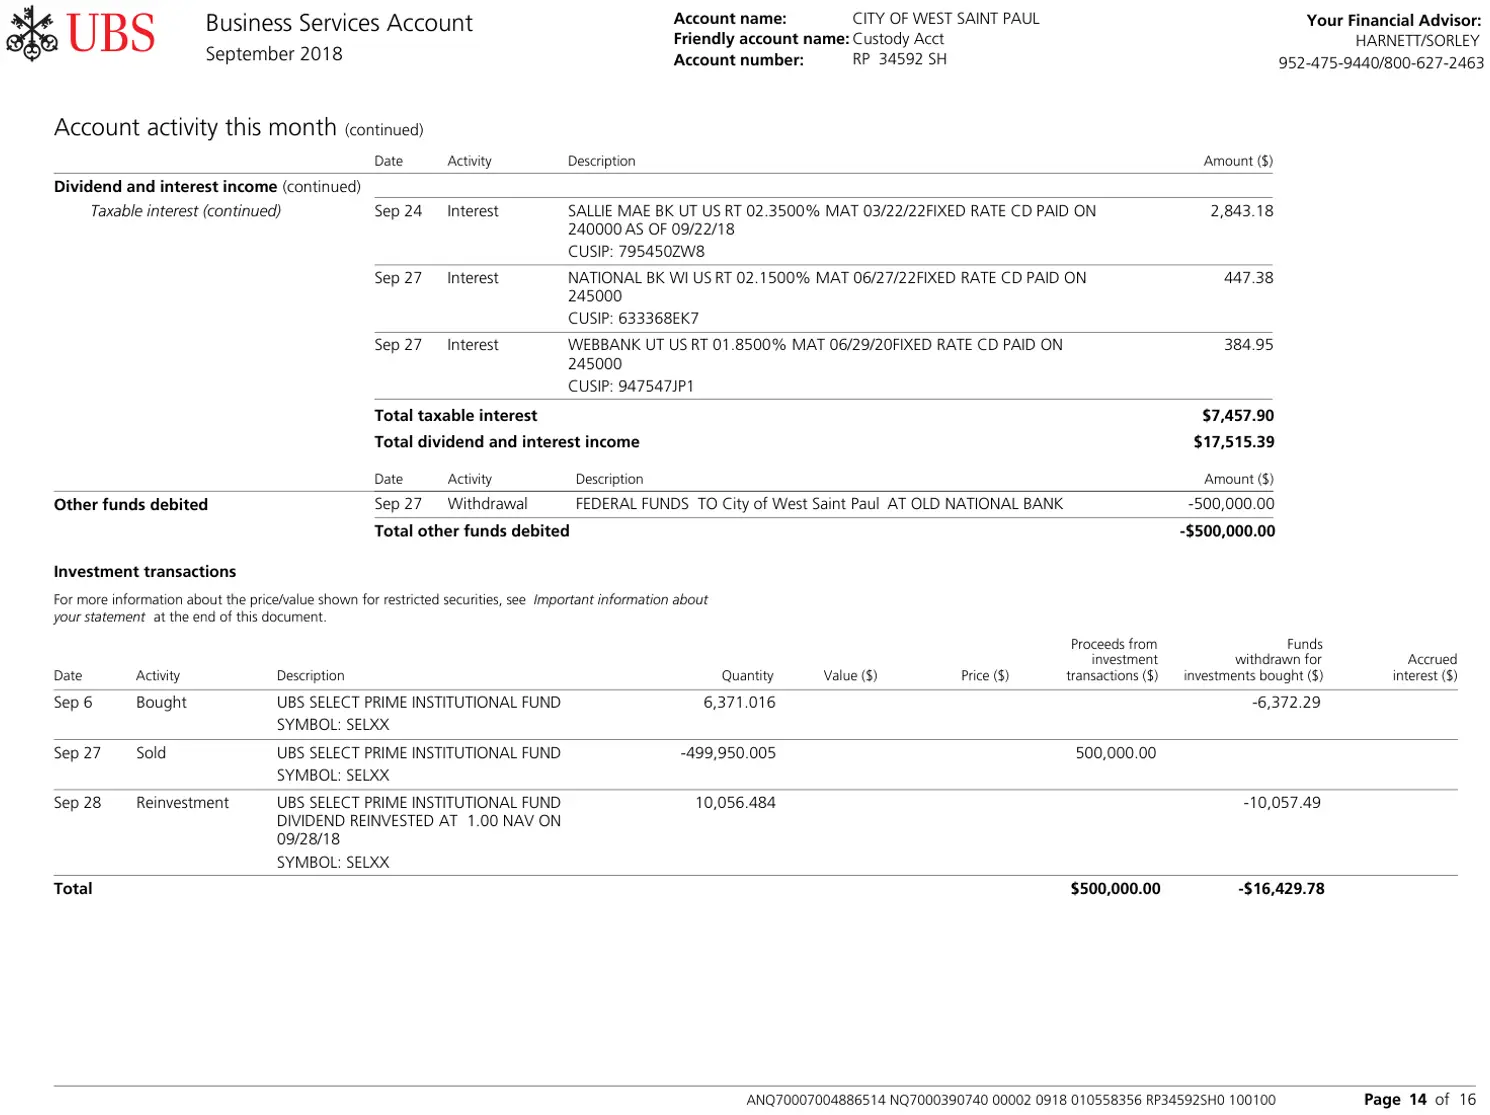
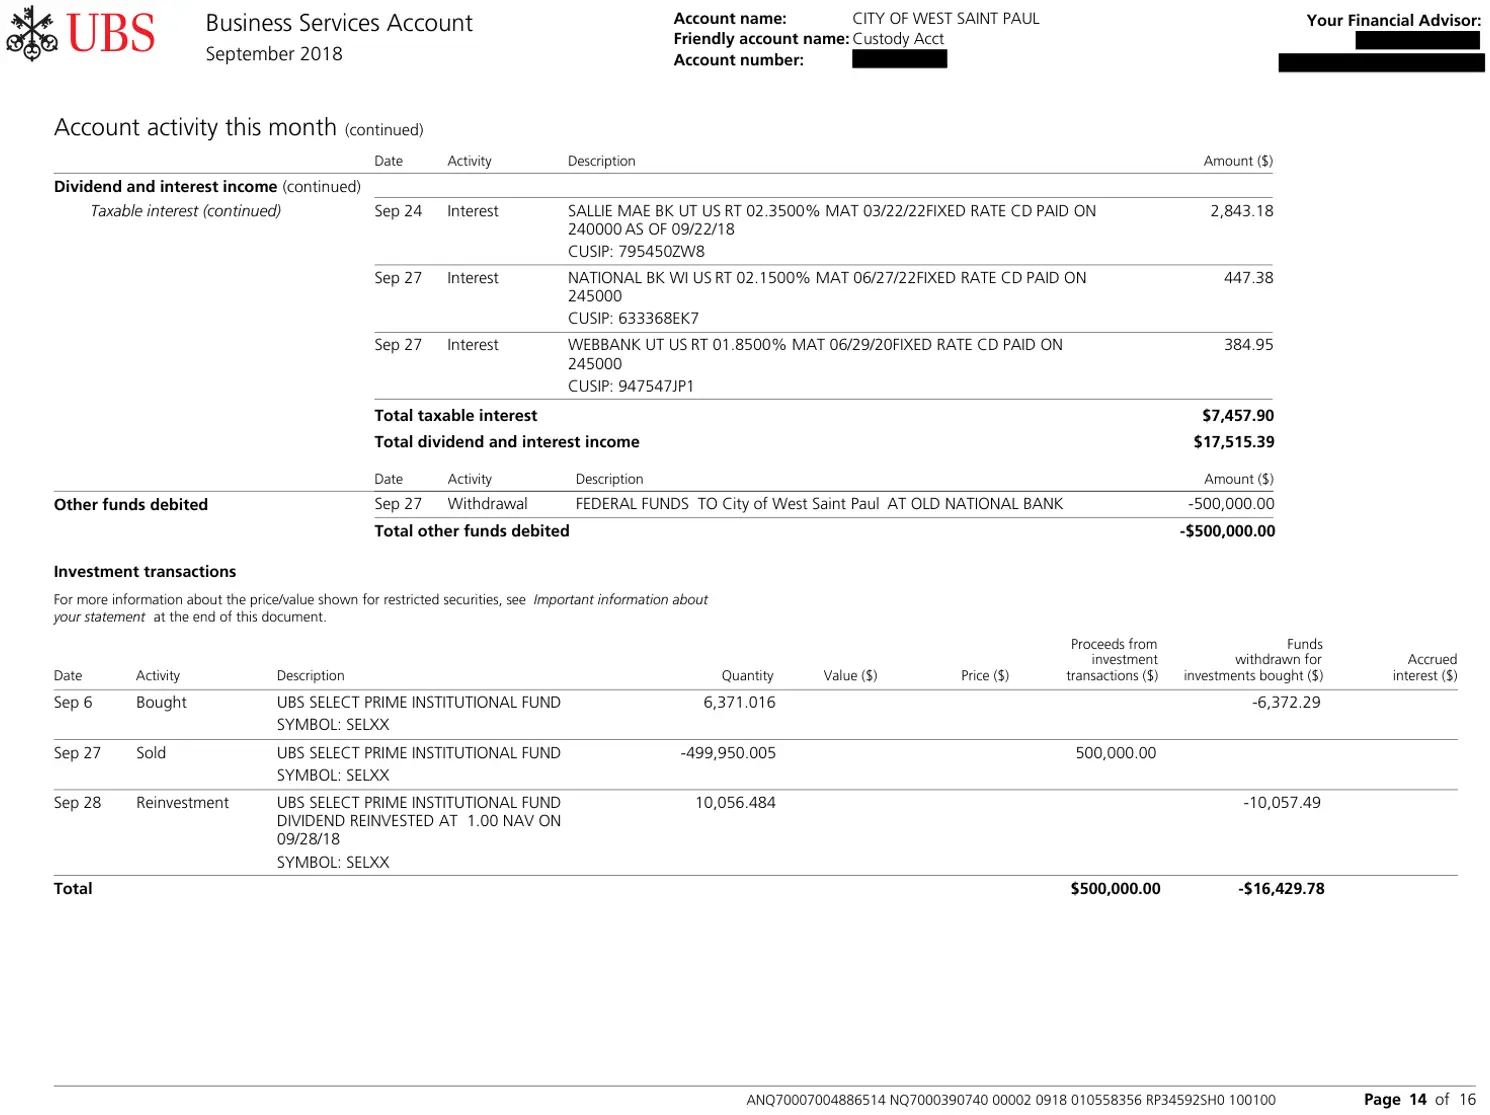
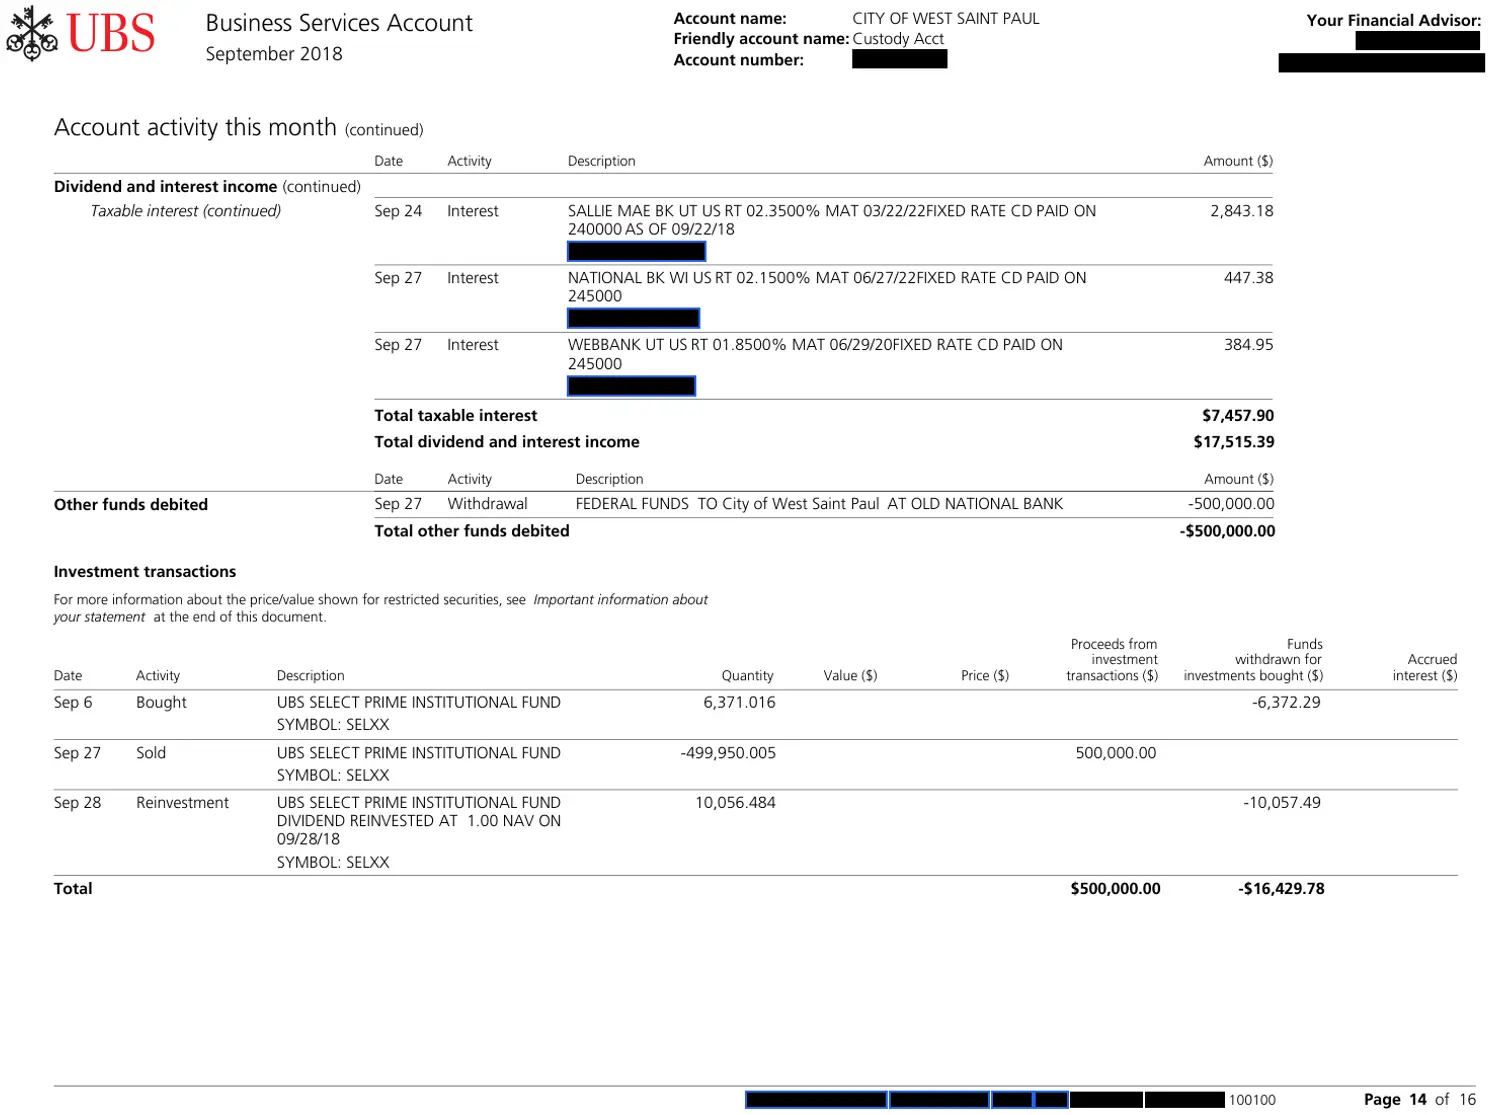
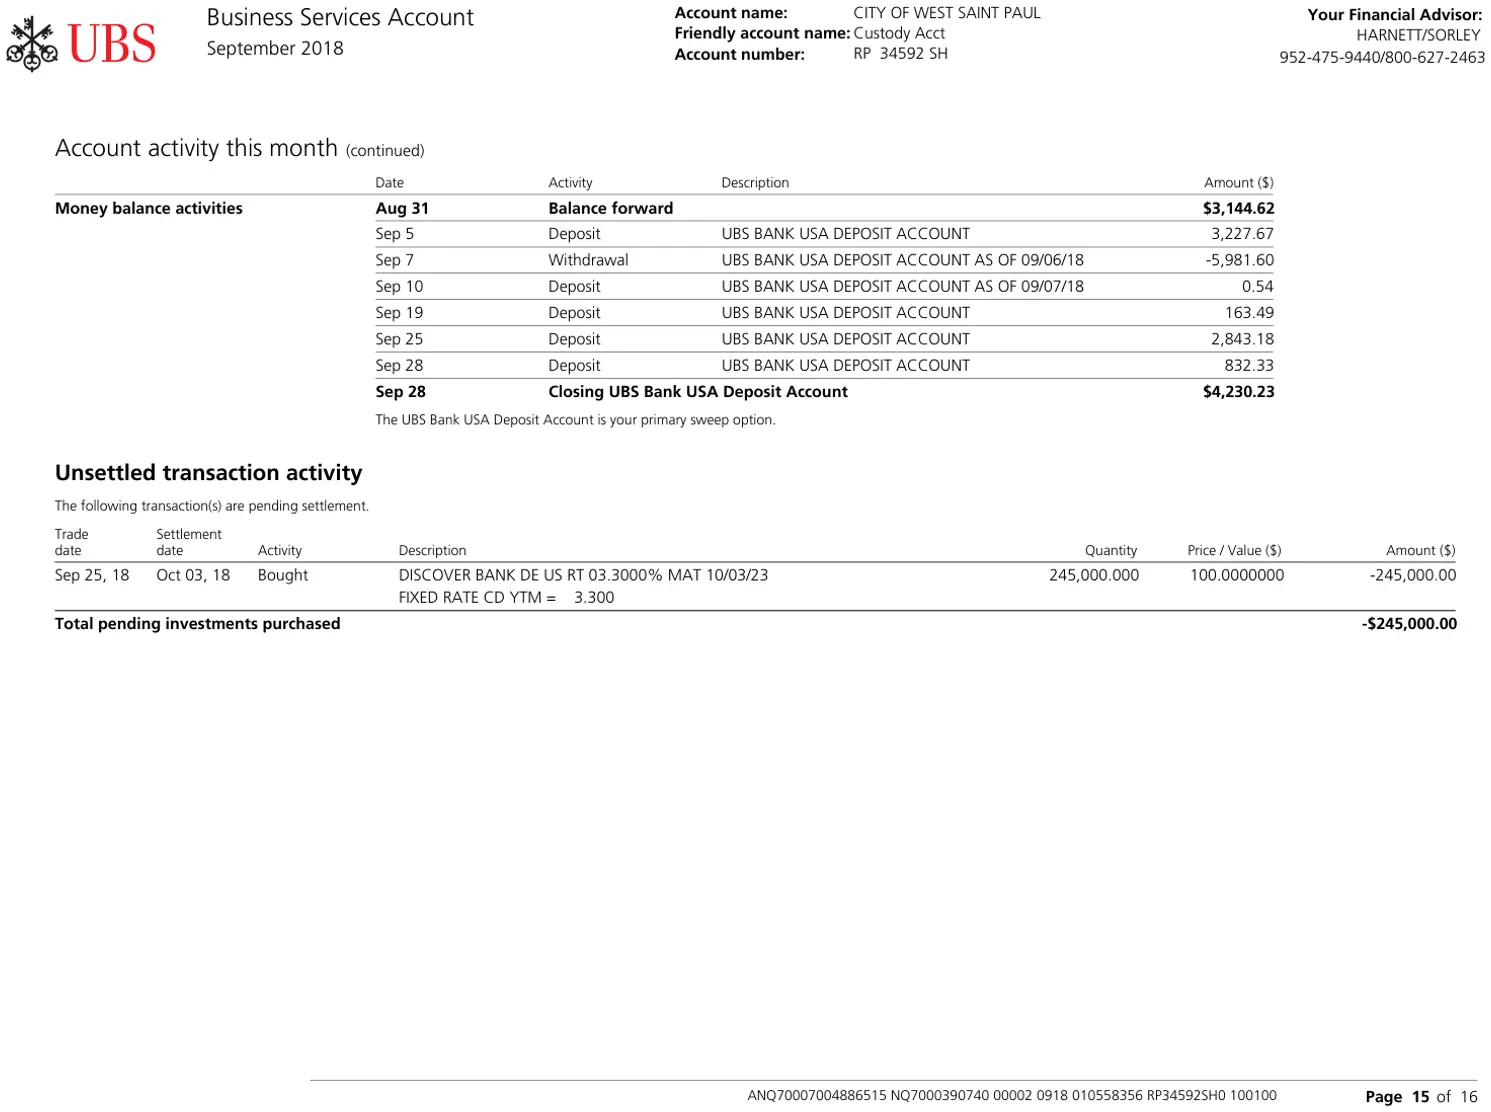
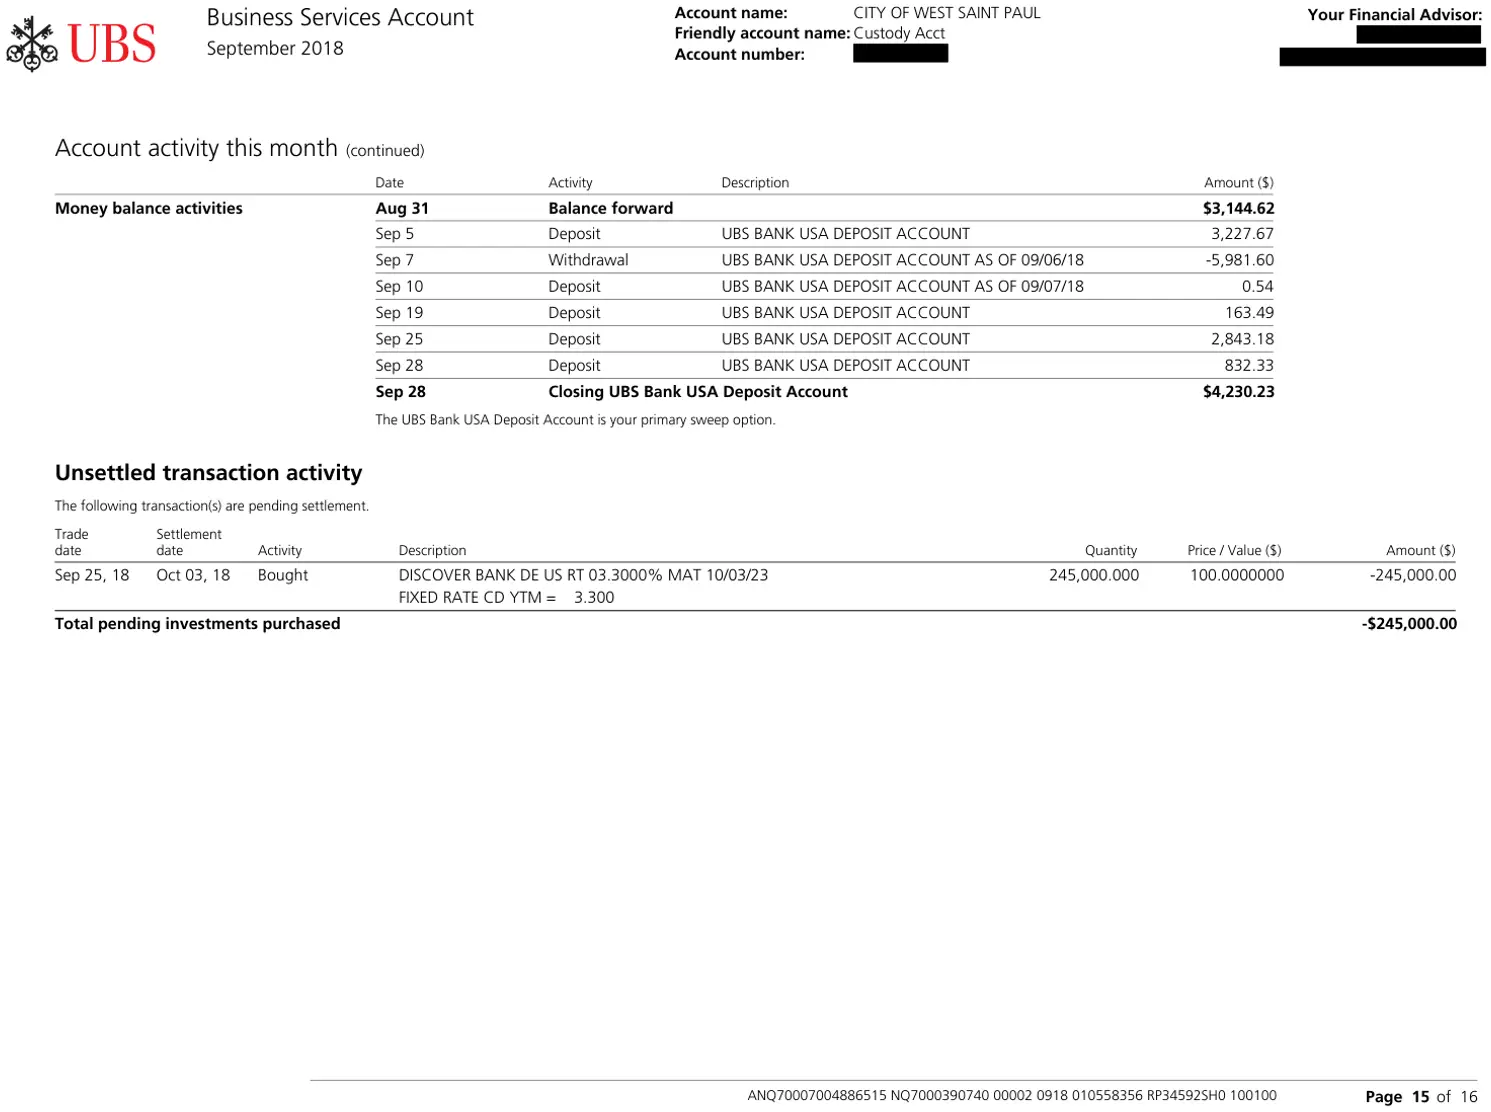
cfpb-sample-credit-card-statement-handout.pdf
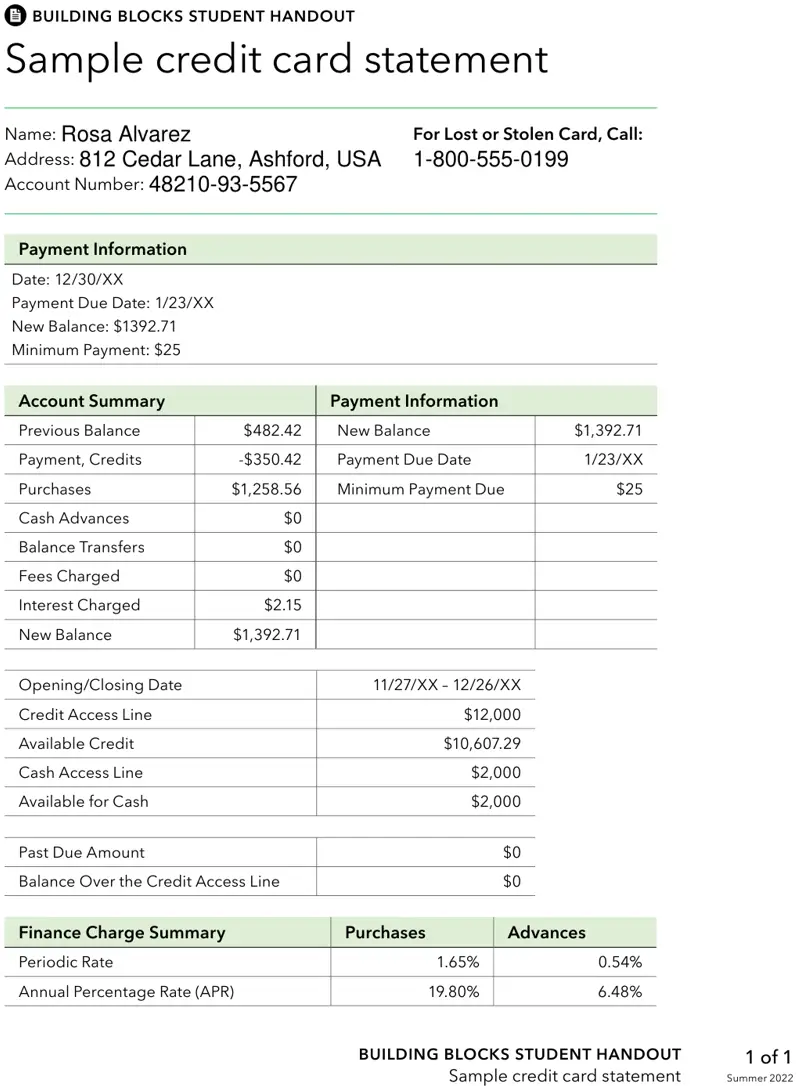
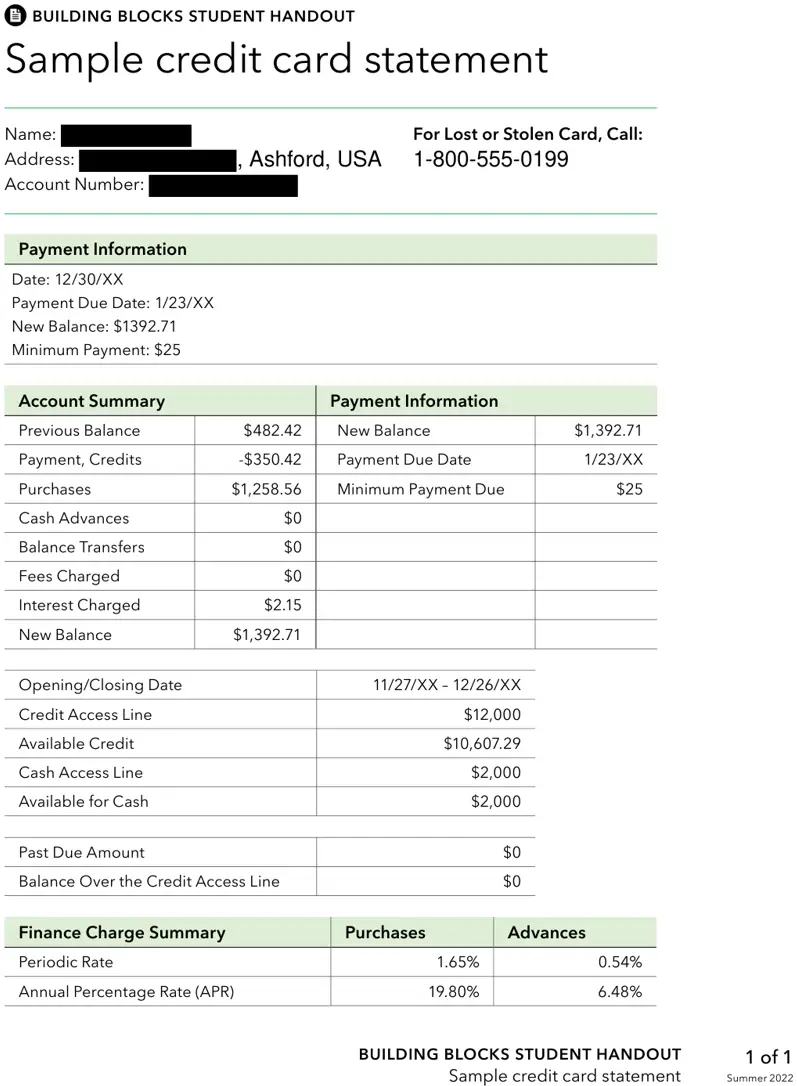
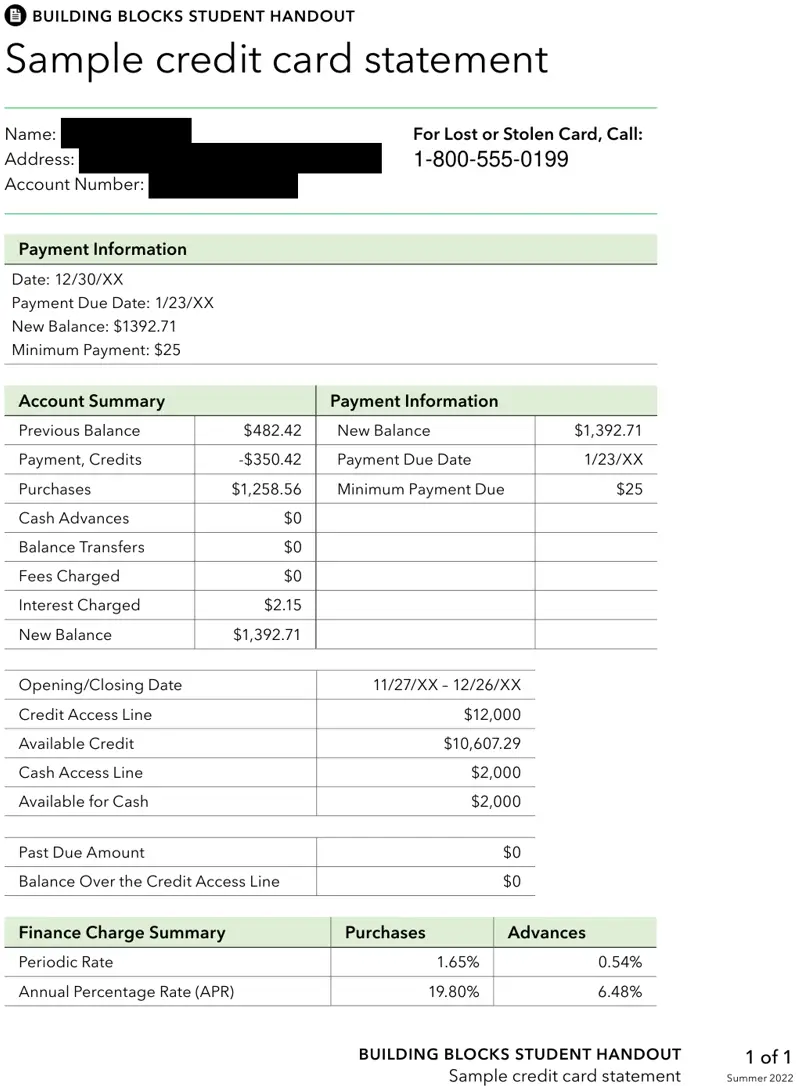
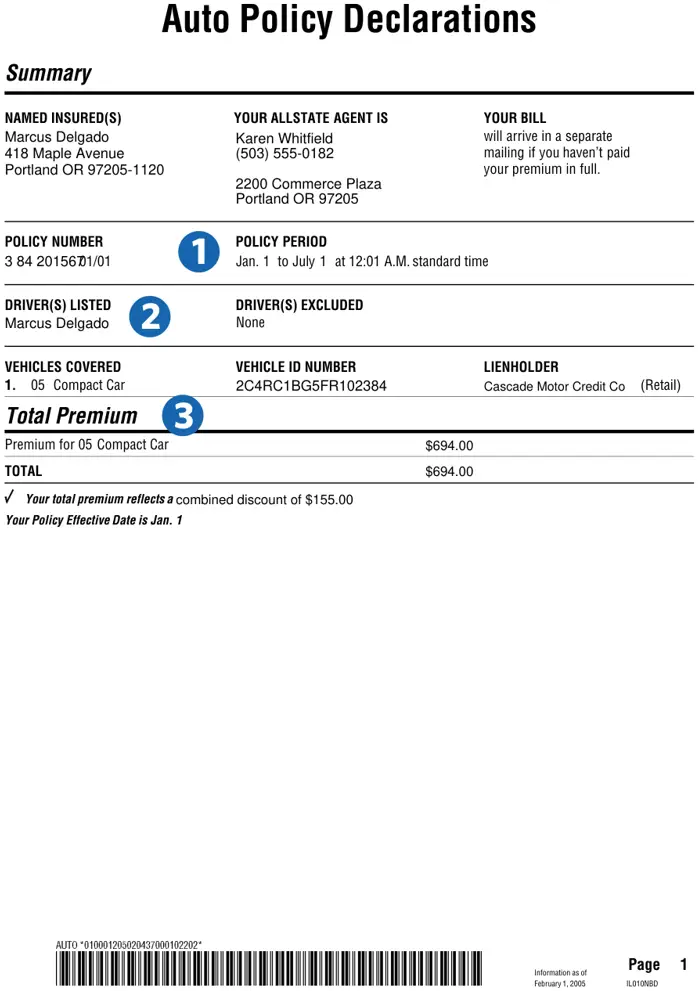
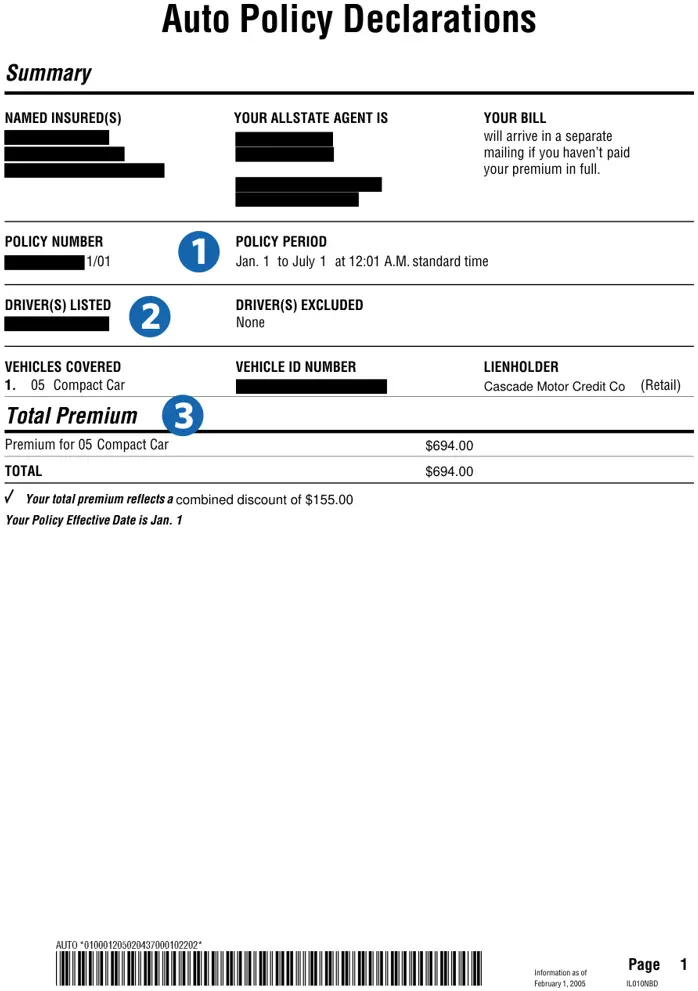
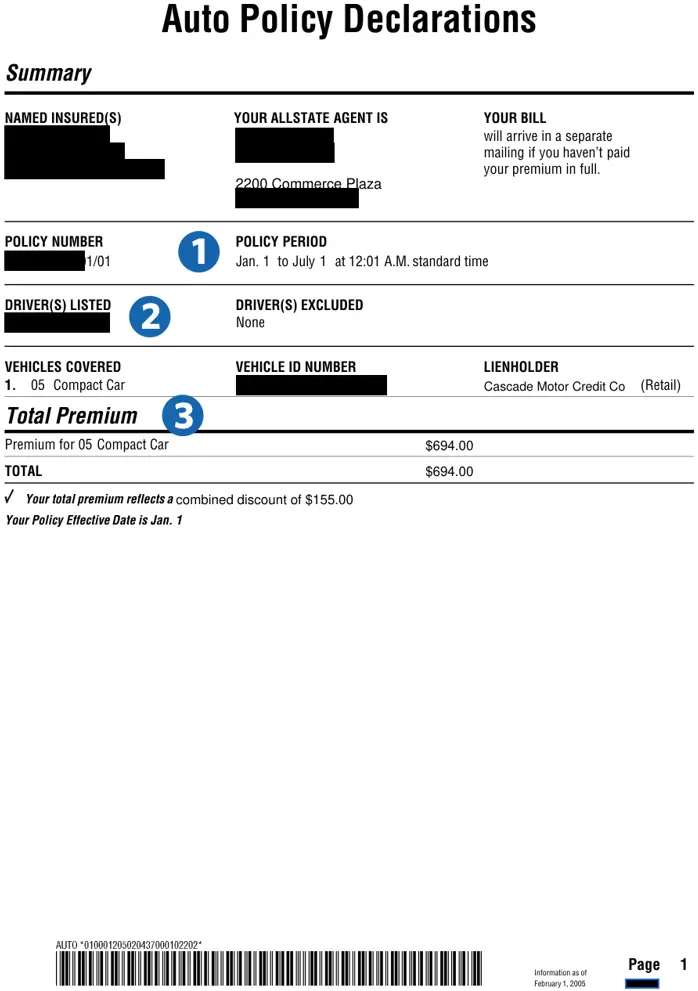
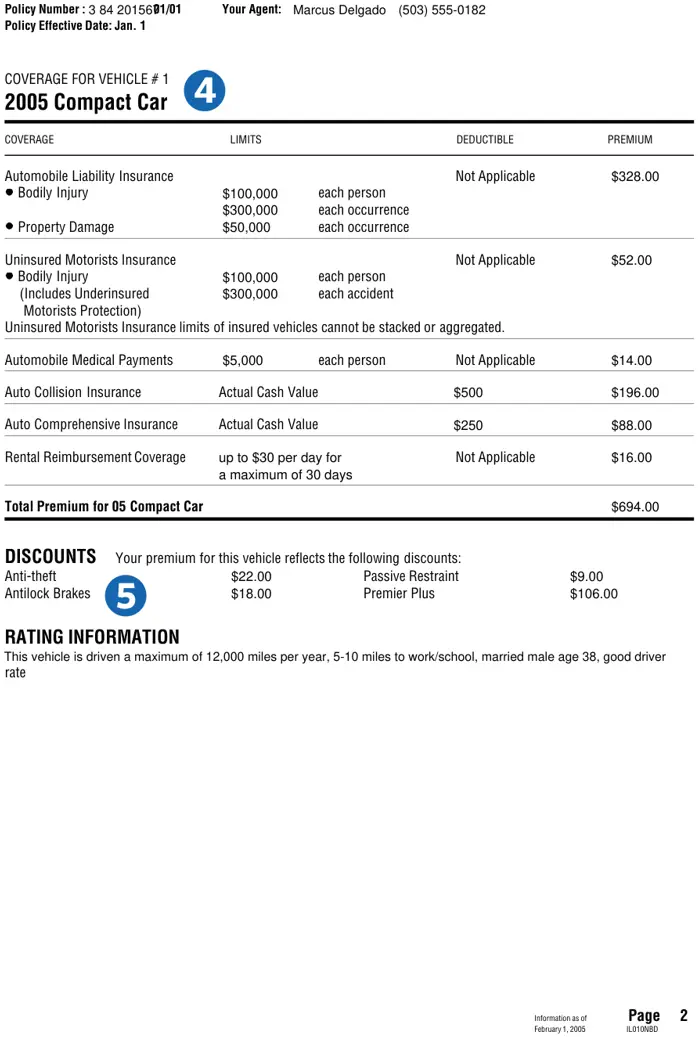
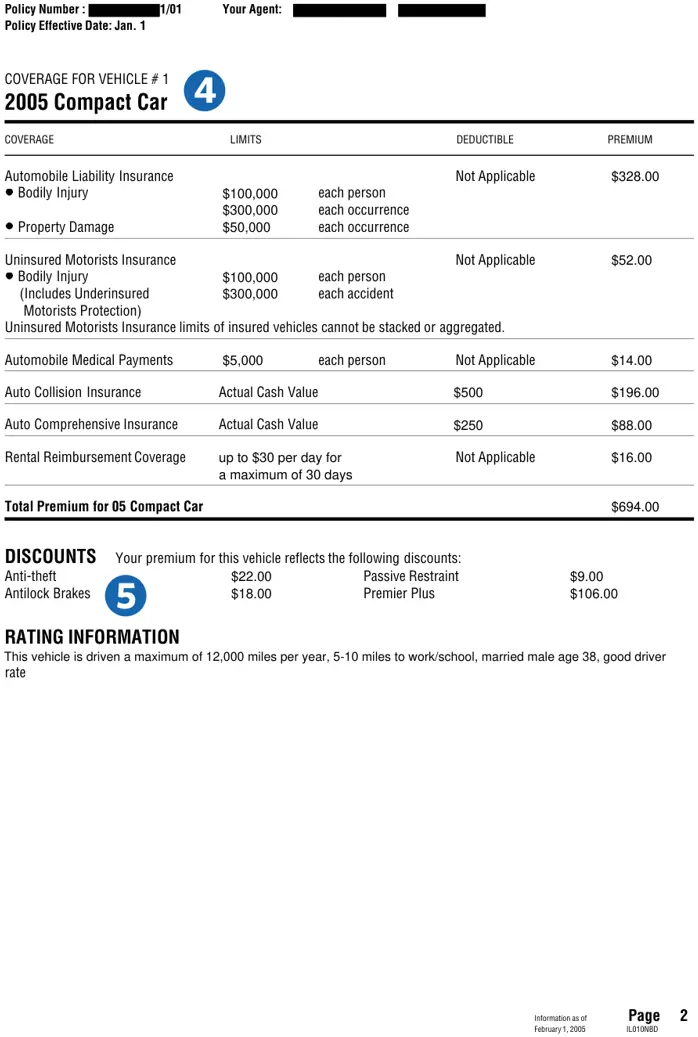
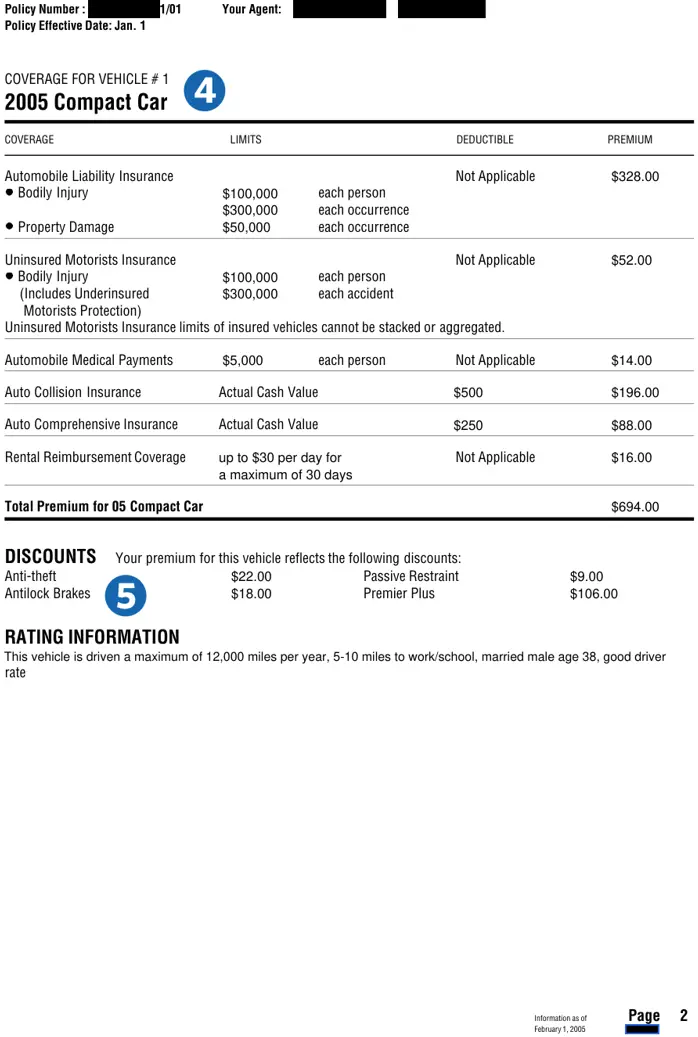
allstate-auto-declarations-sample.pdf
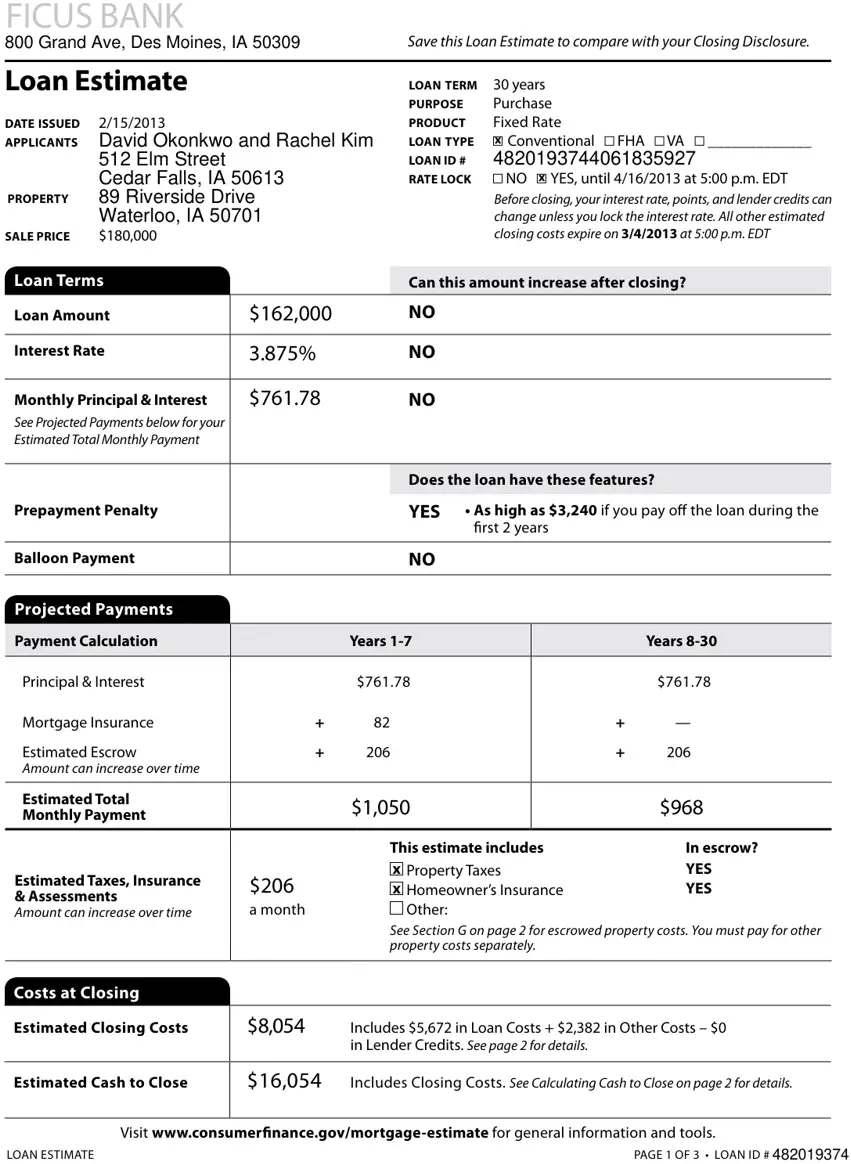
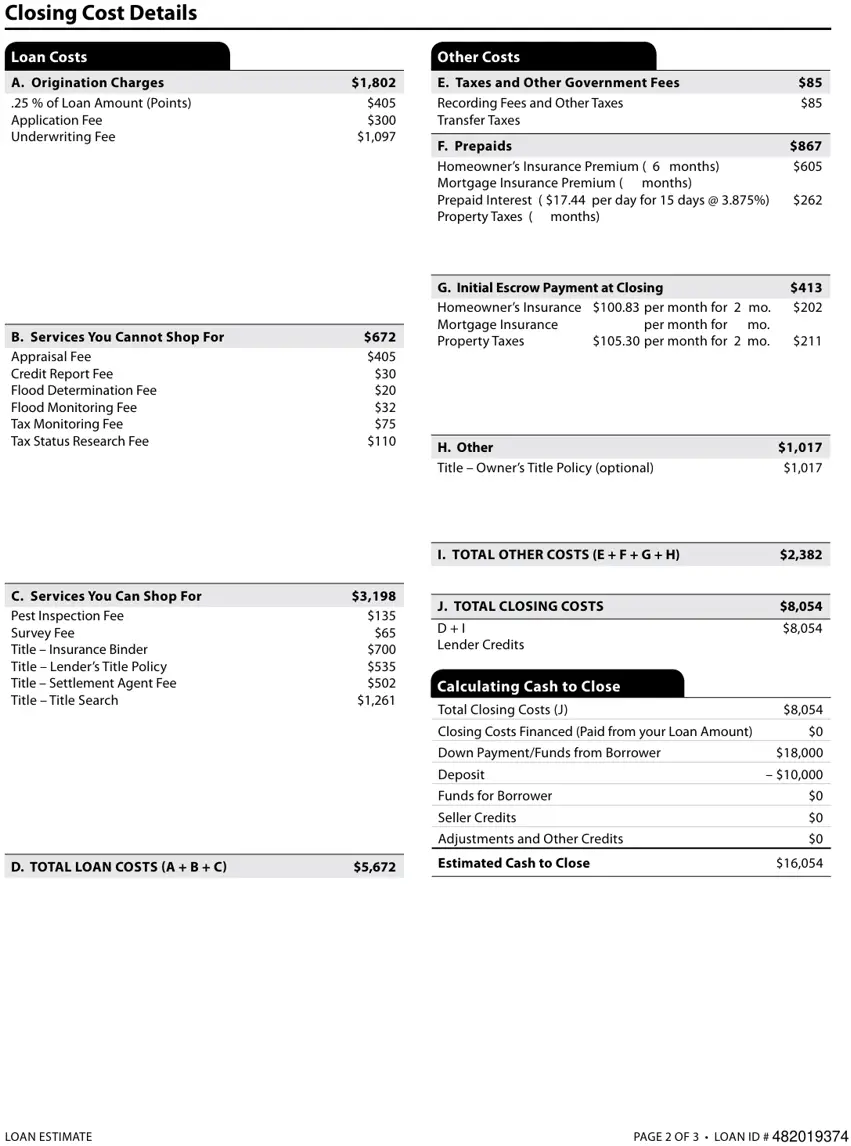
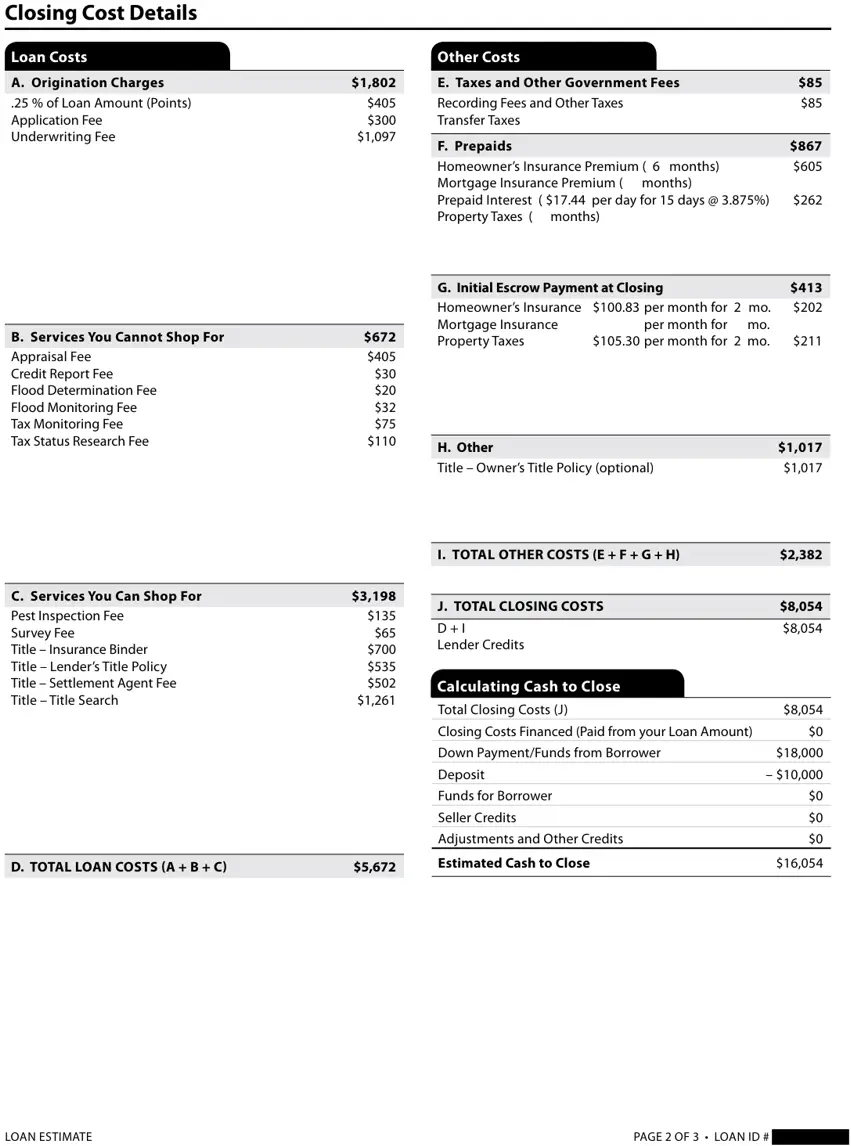
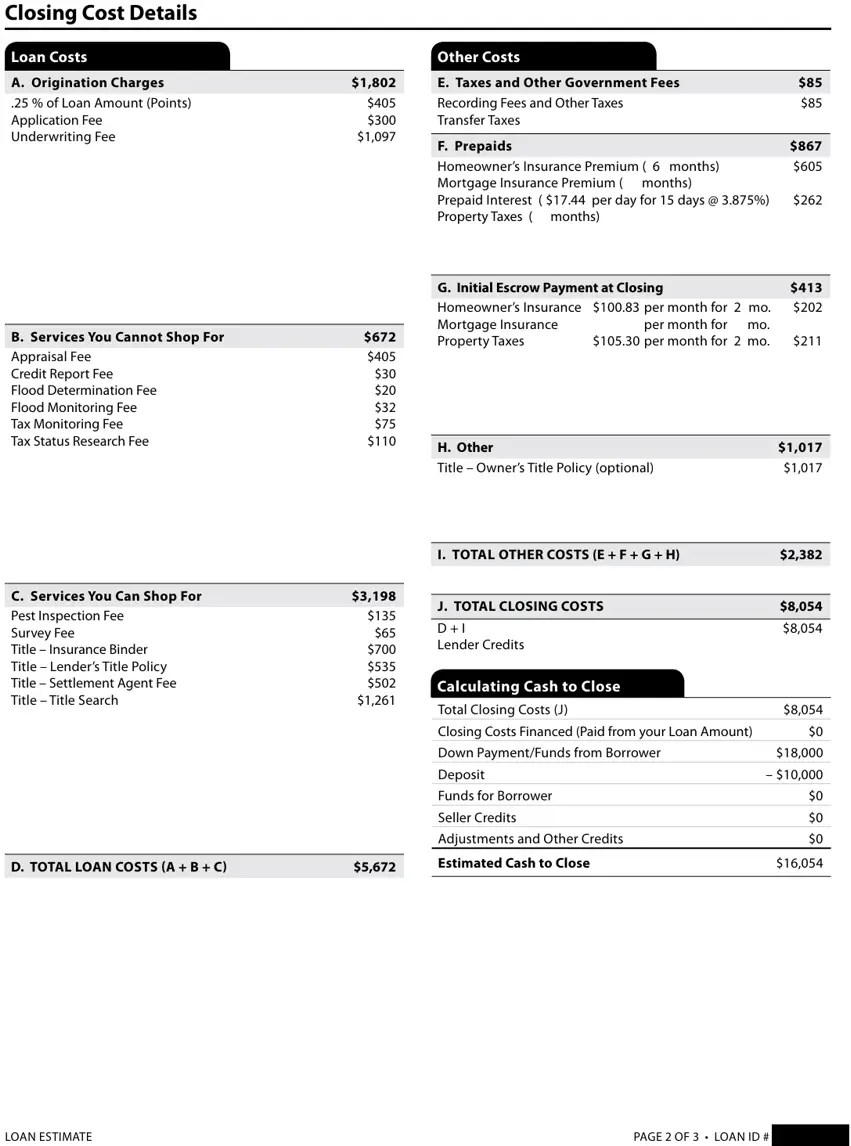
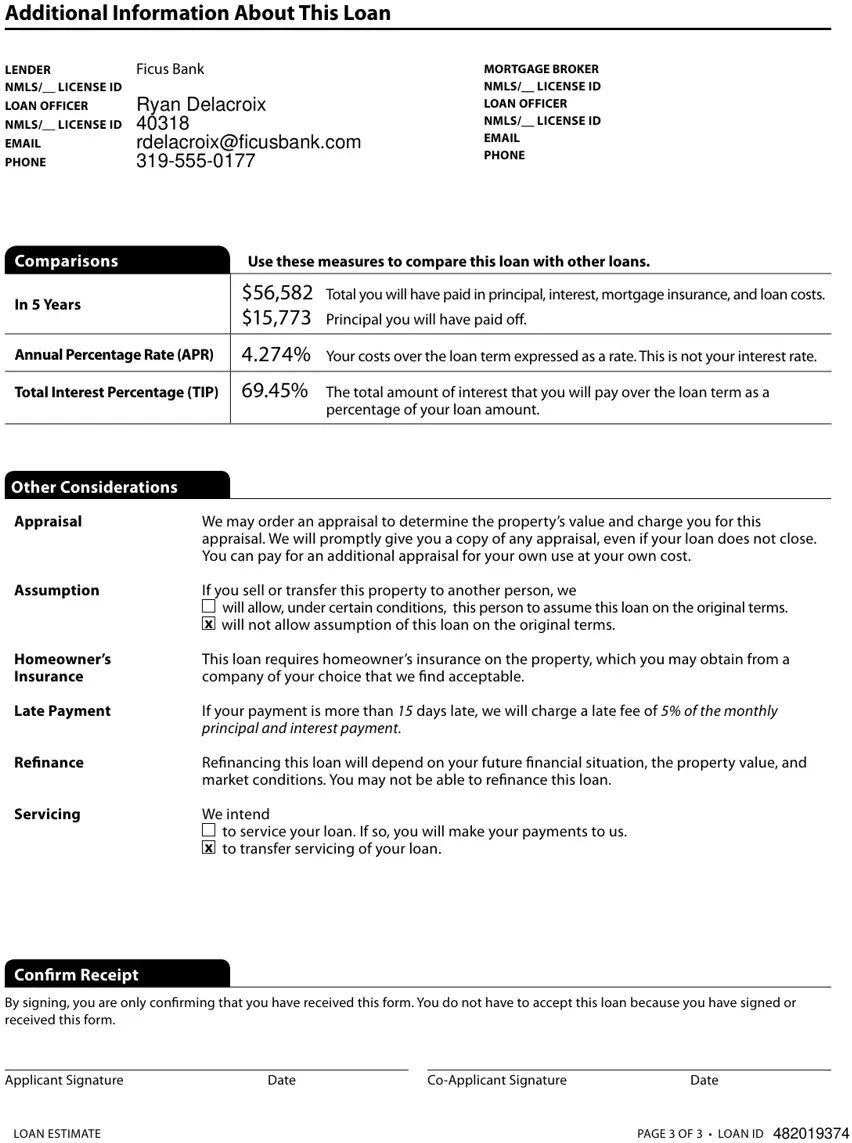
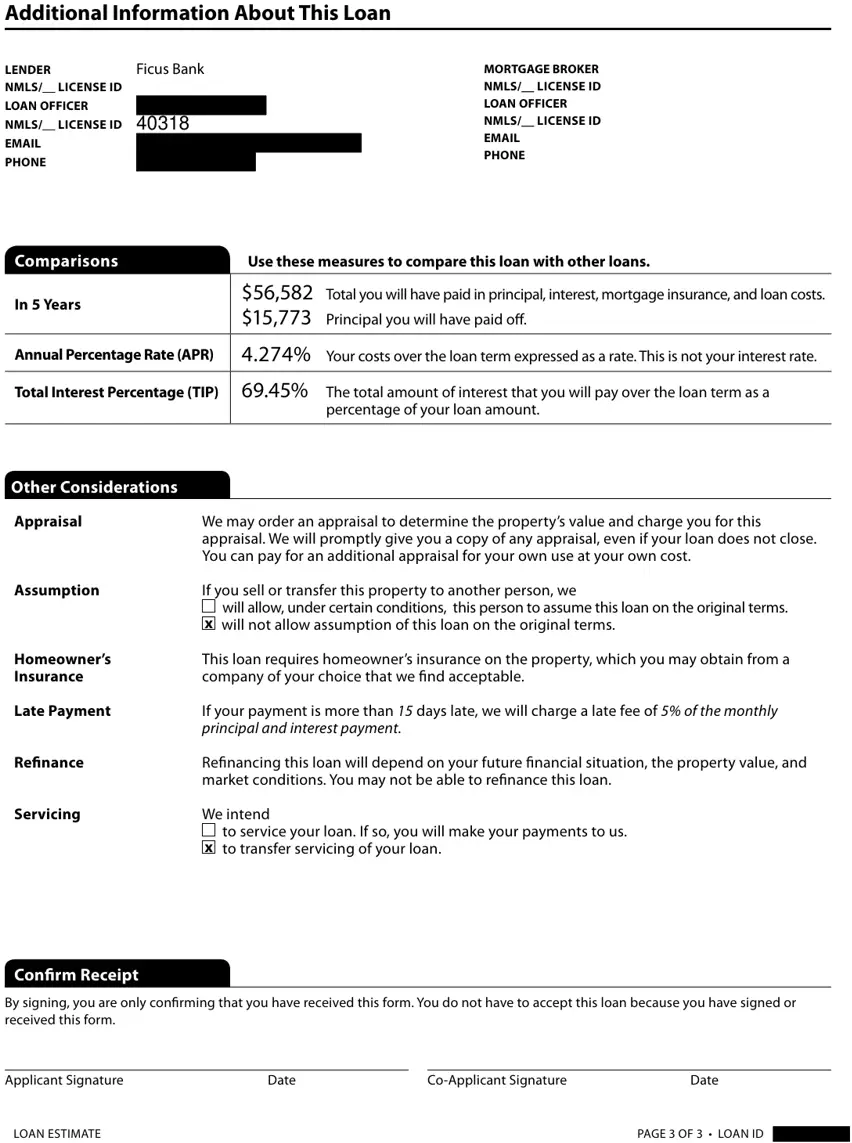
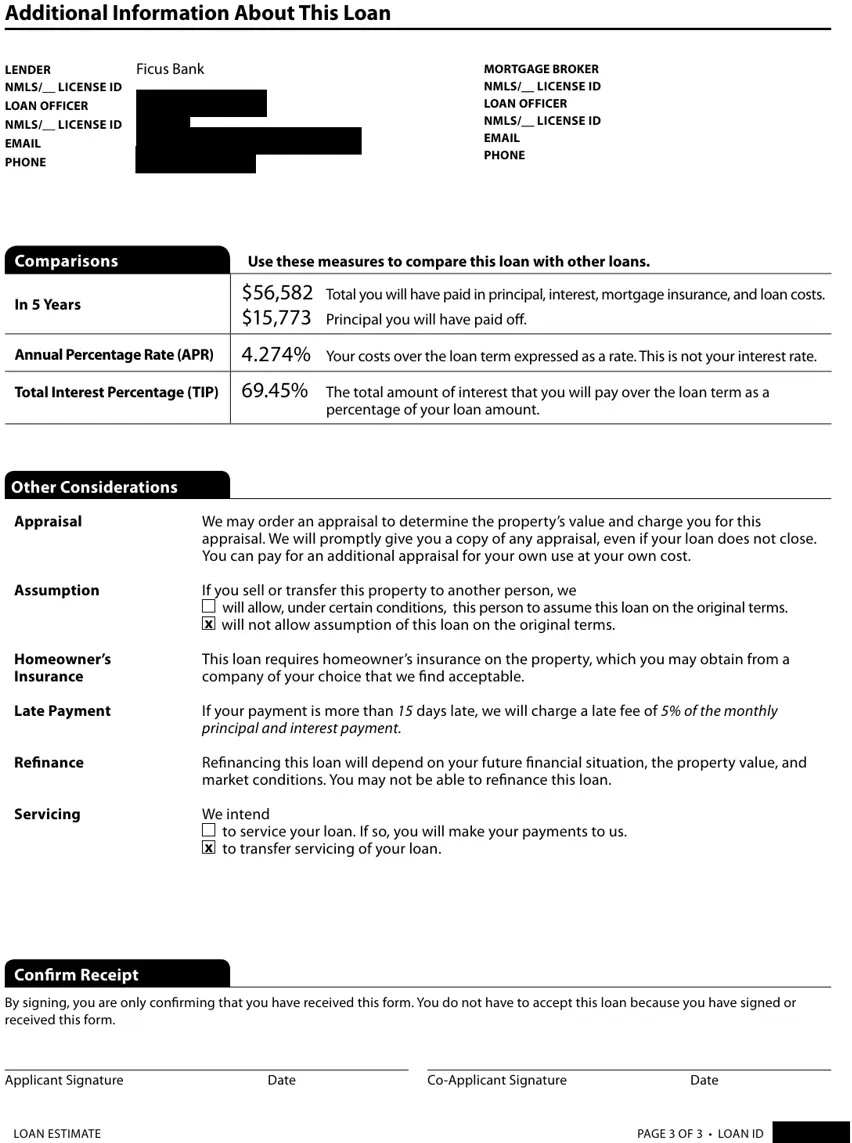
cfpb-ficus-bank-loan-estimate-sample.pdf
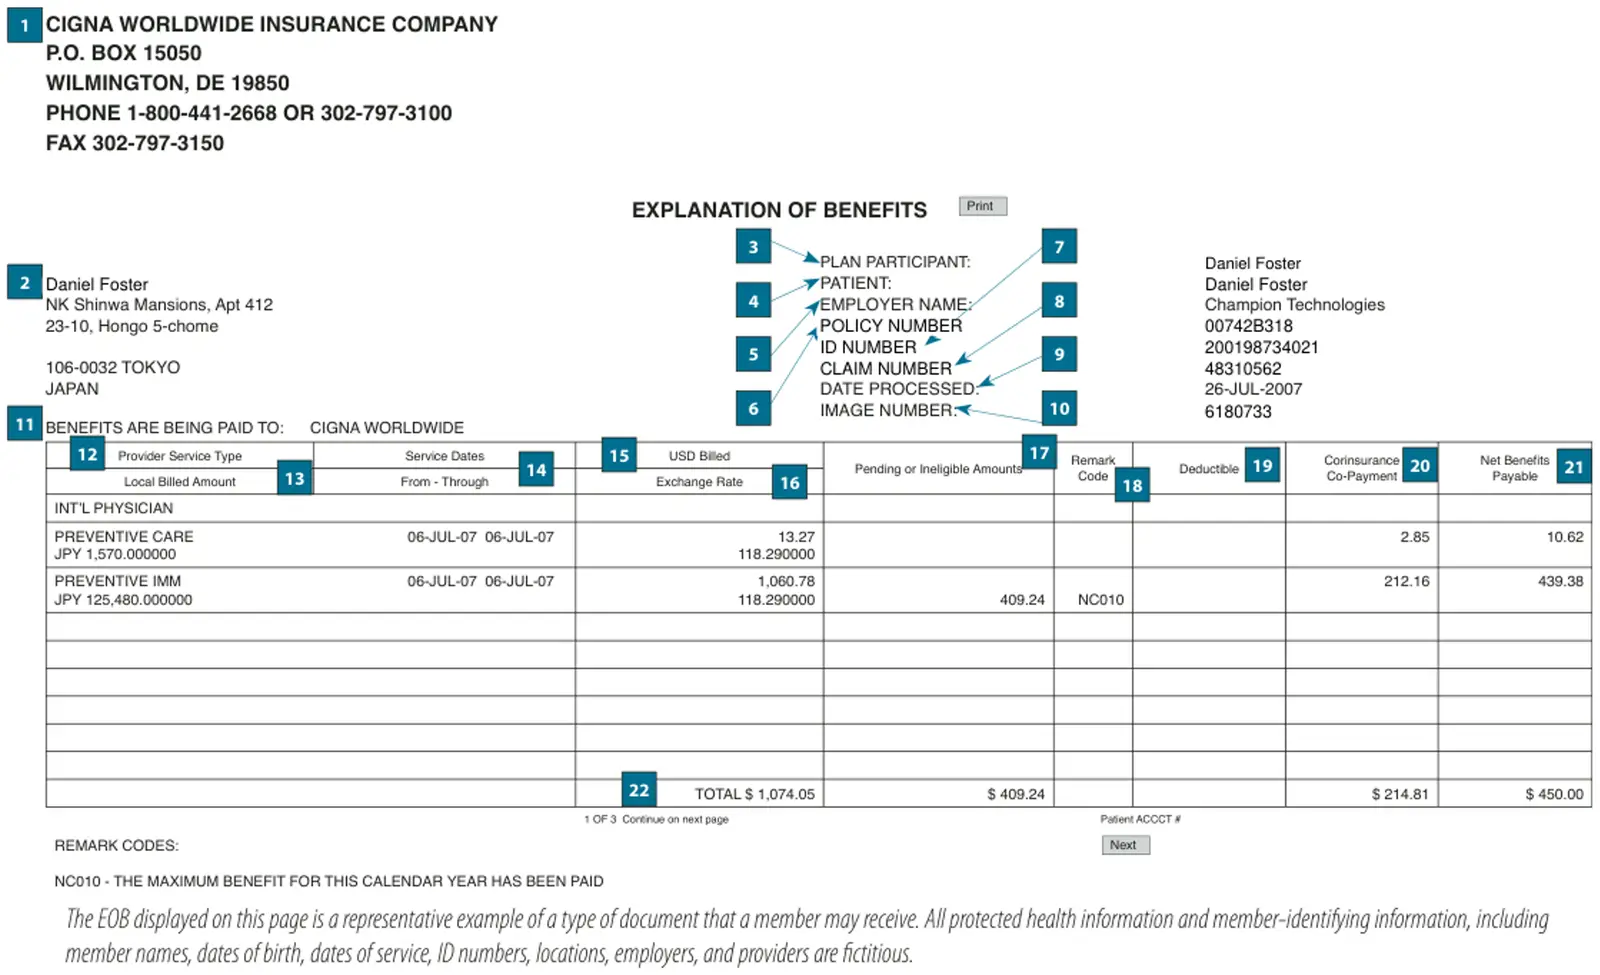
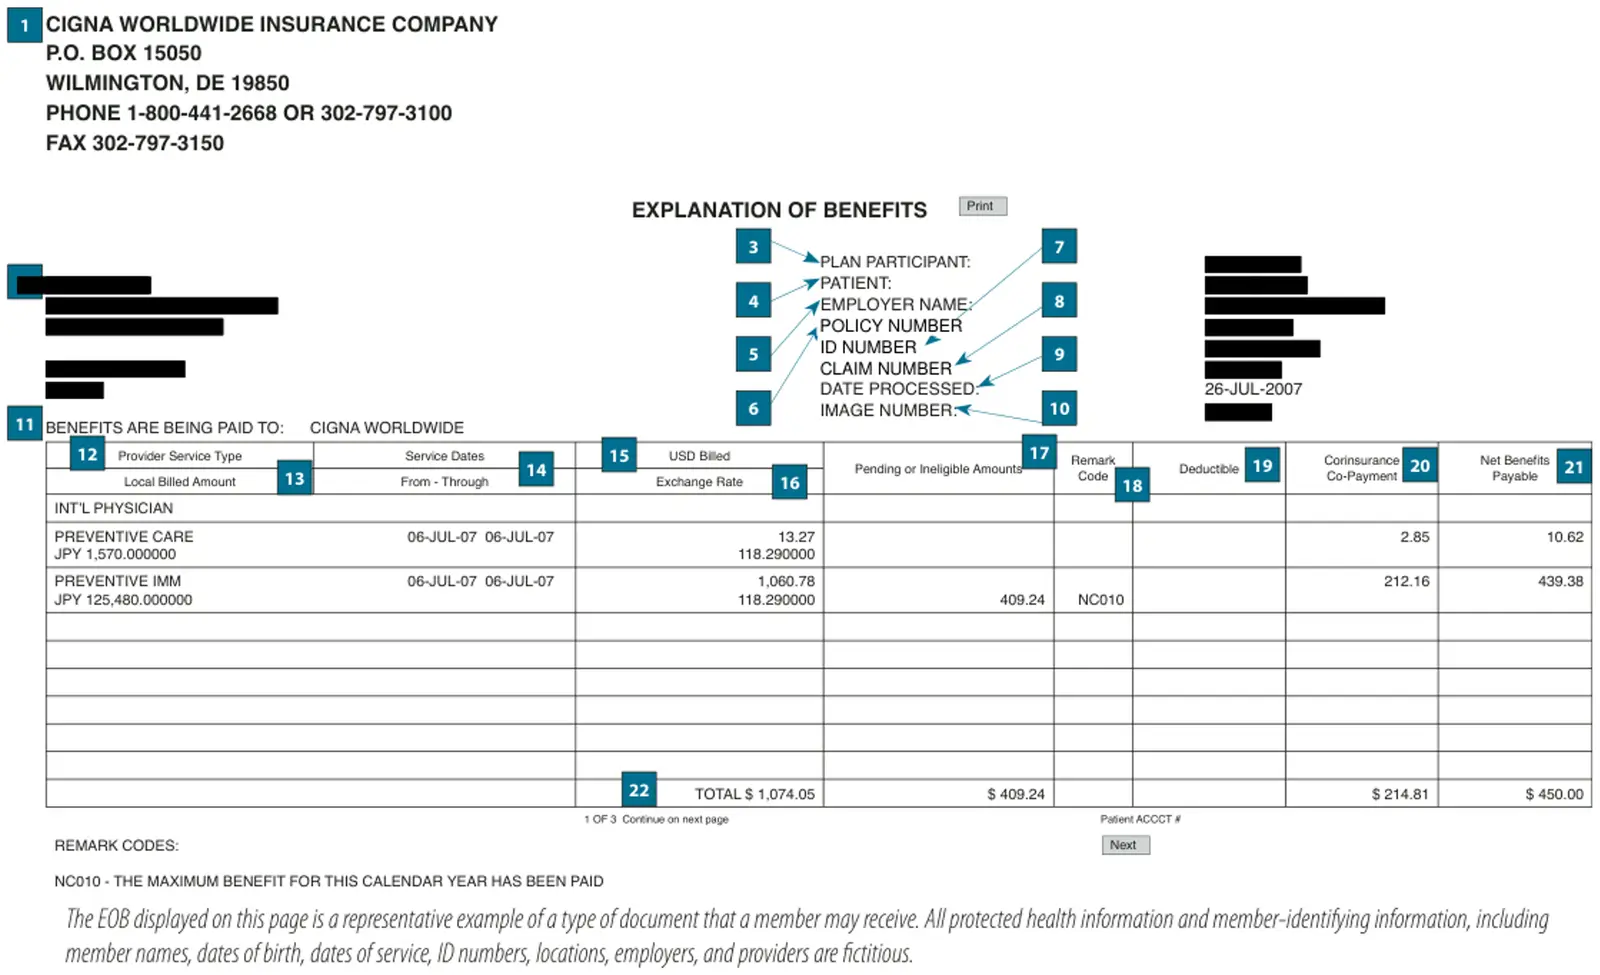
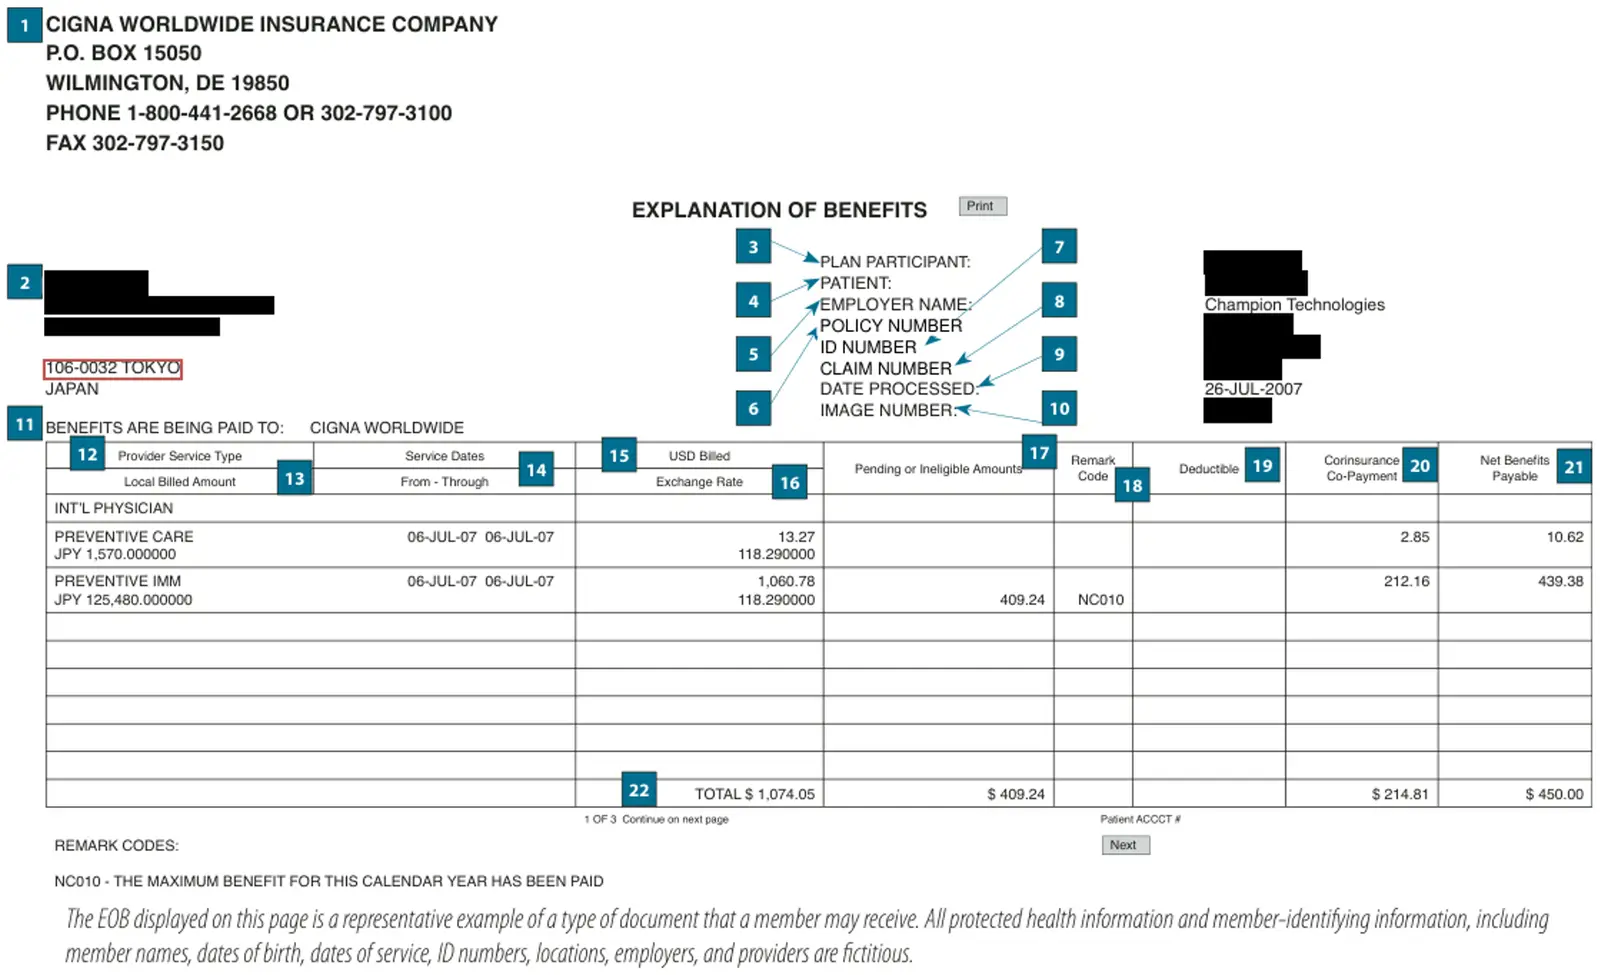
cigna-eob-example.pdf
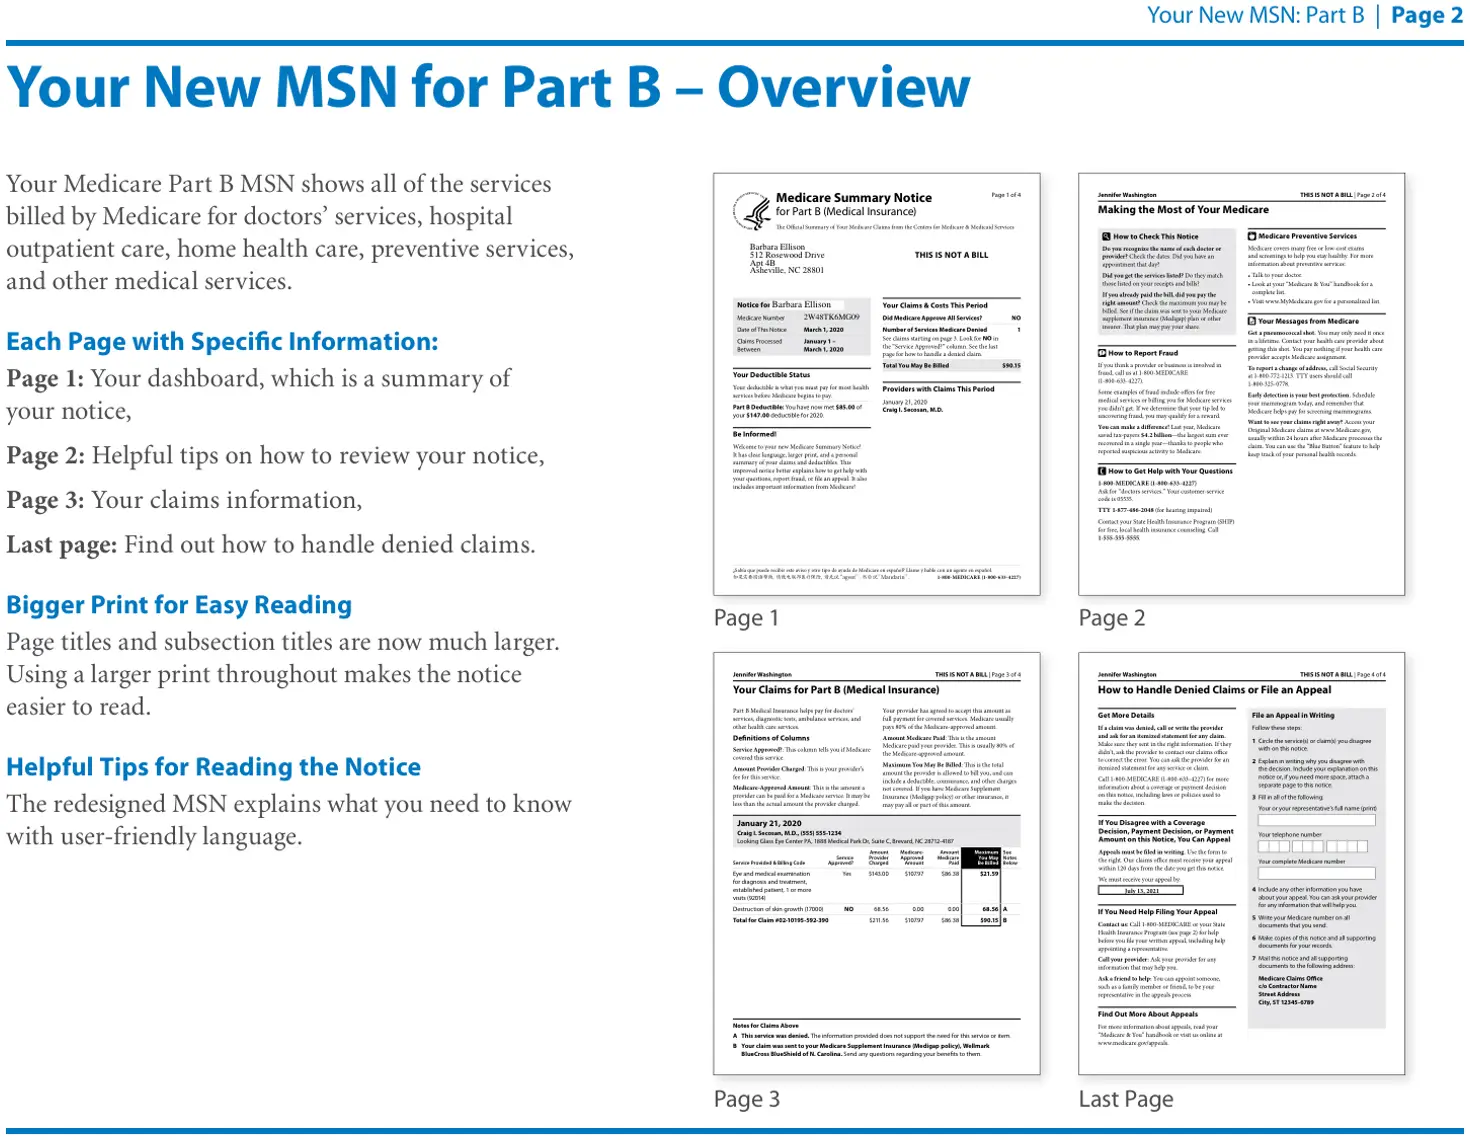
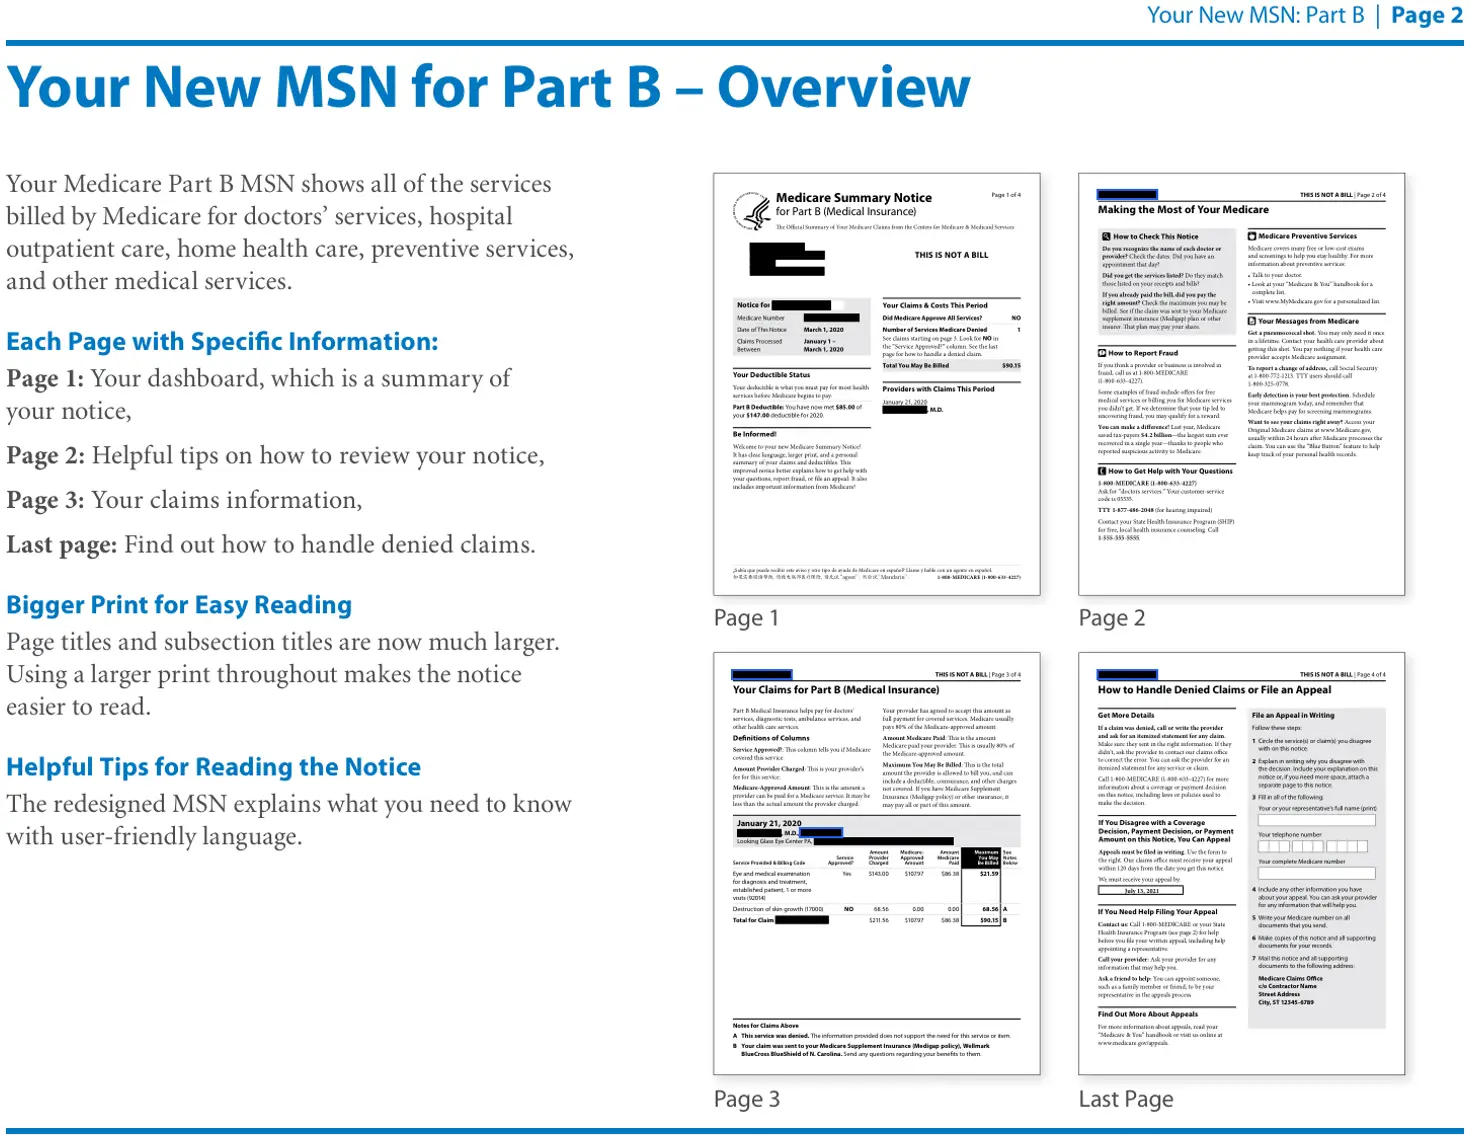
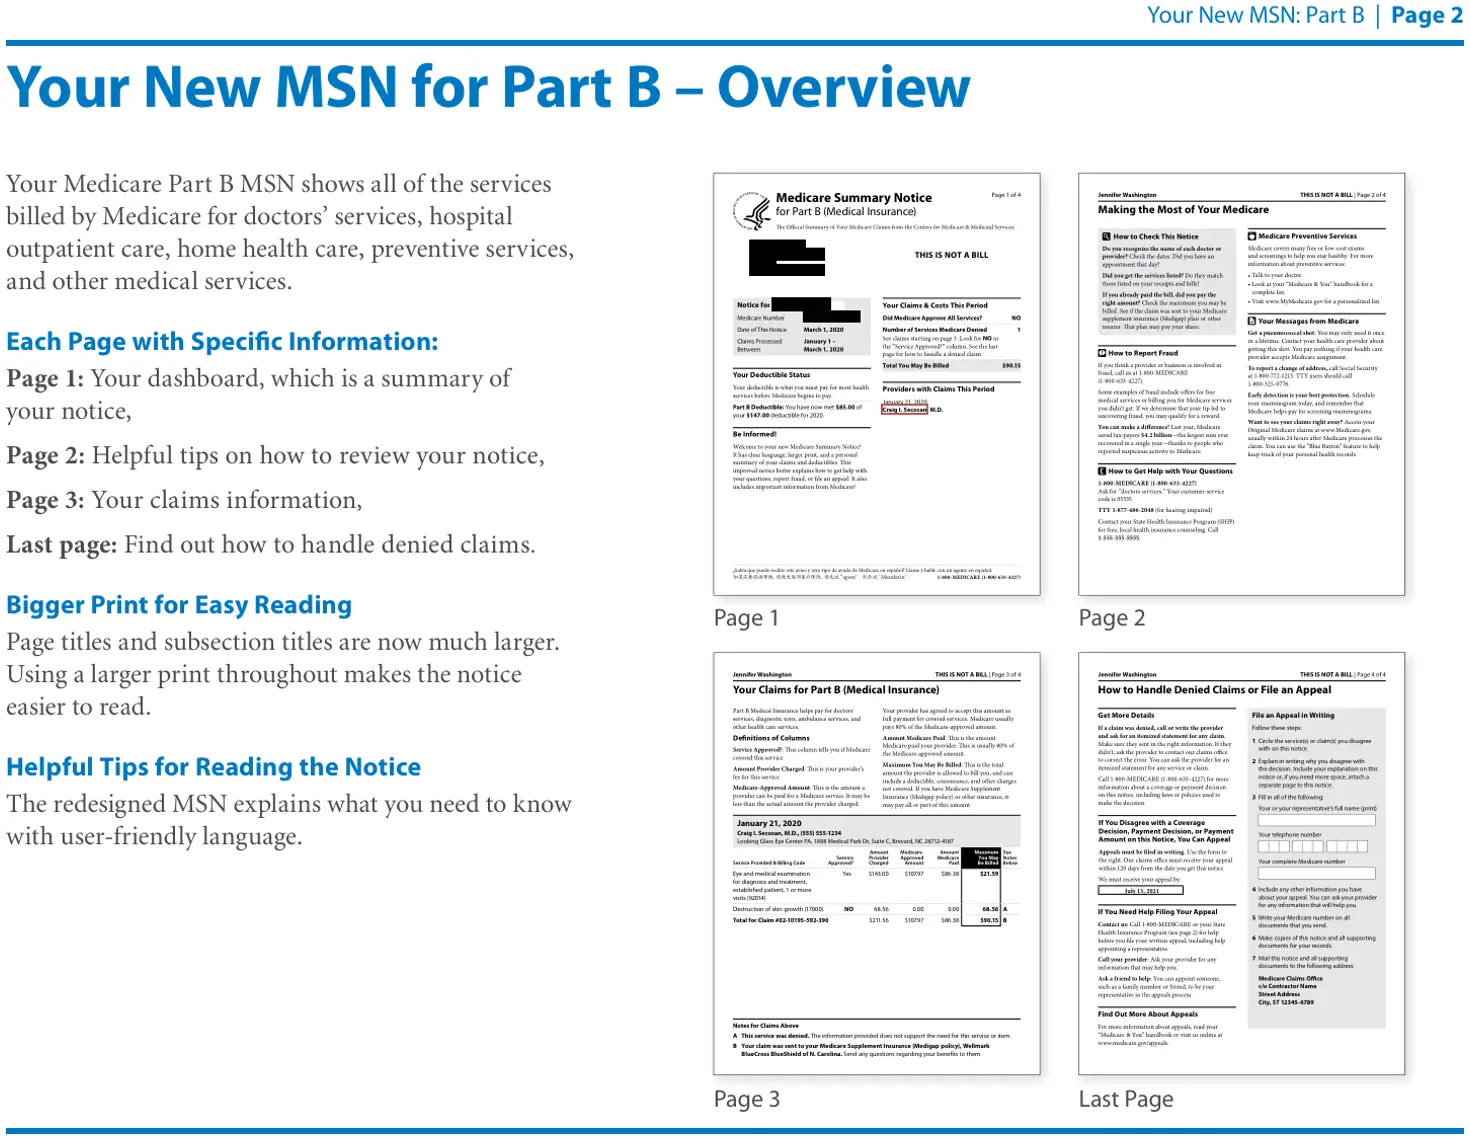
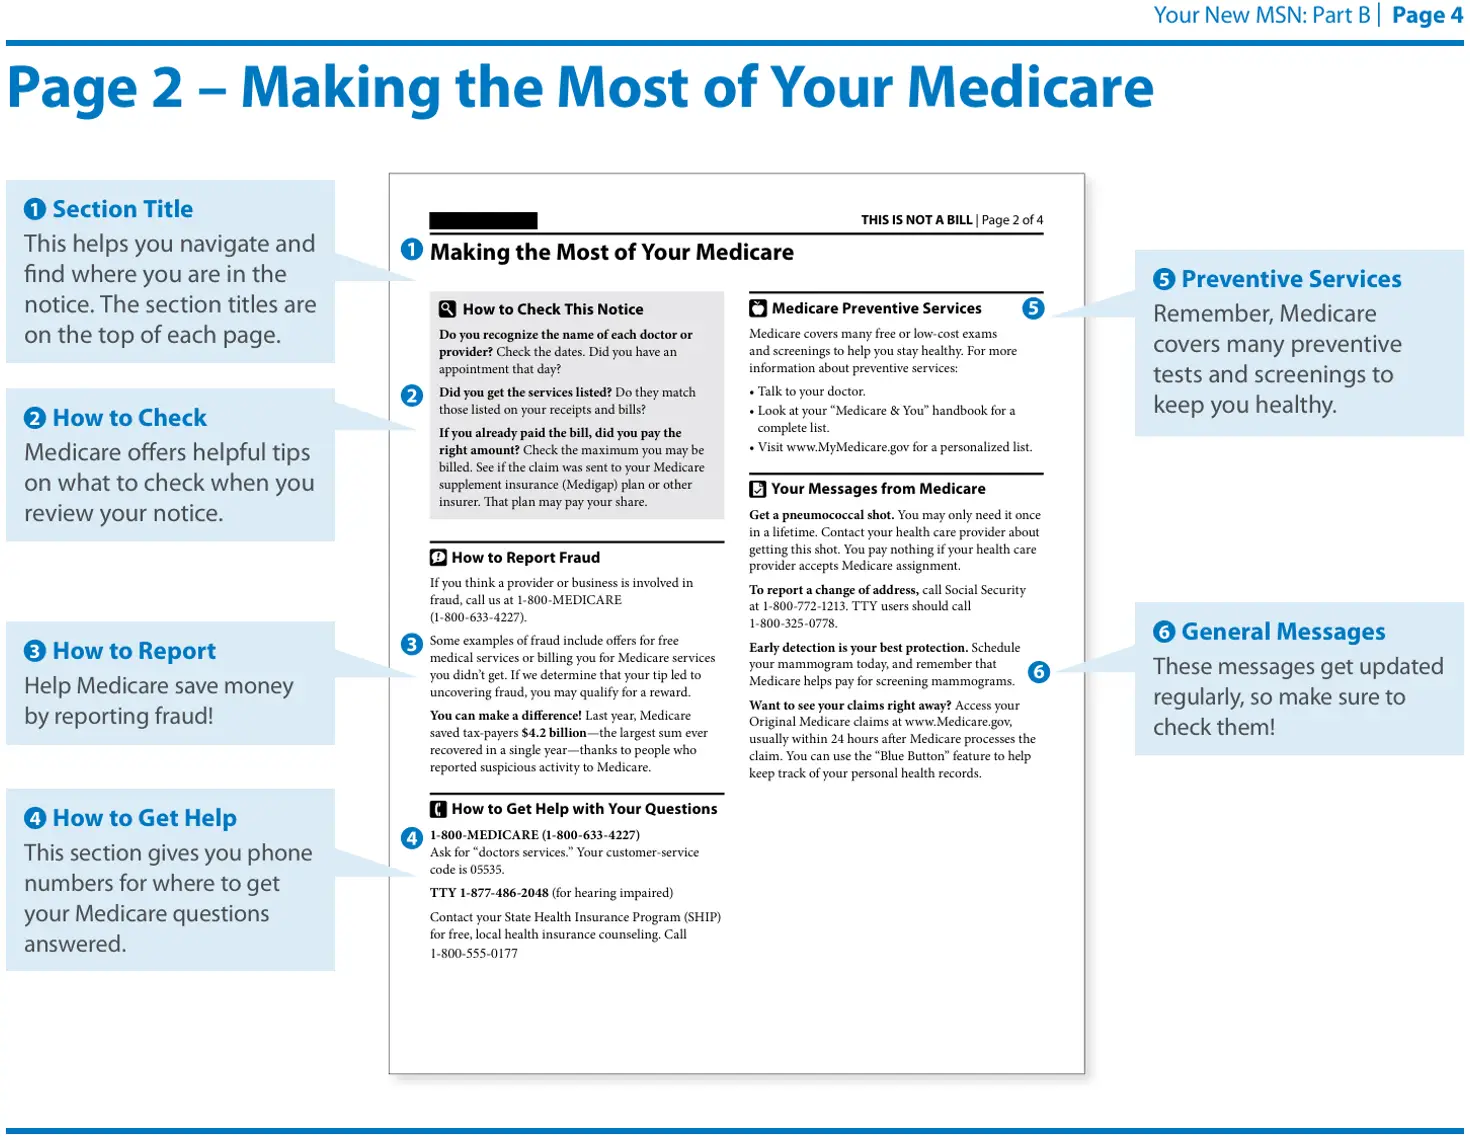
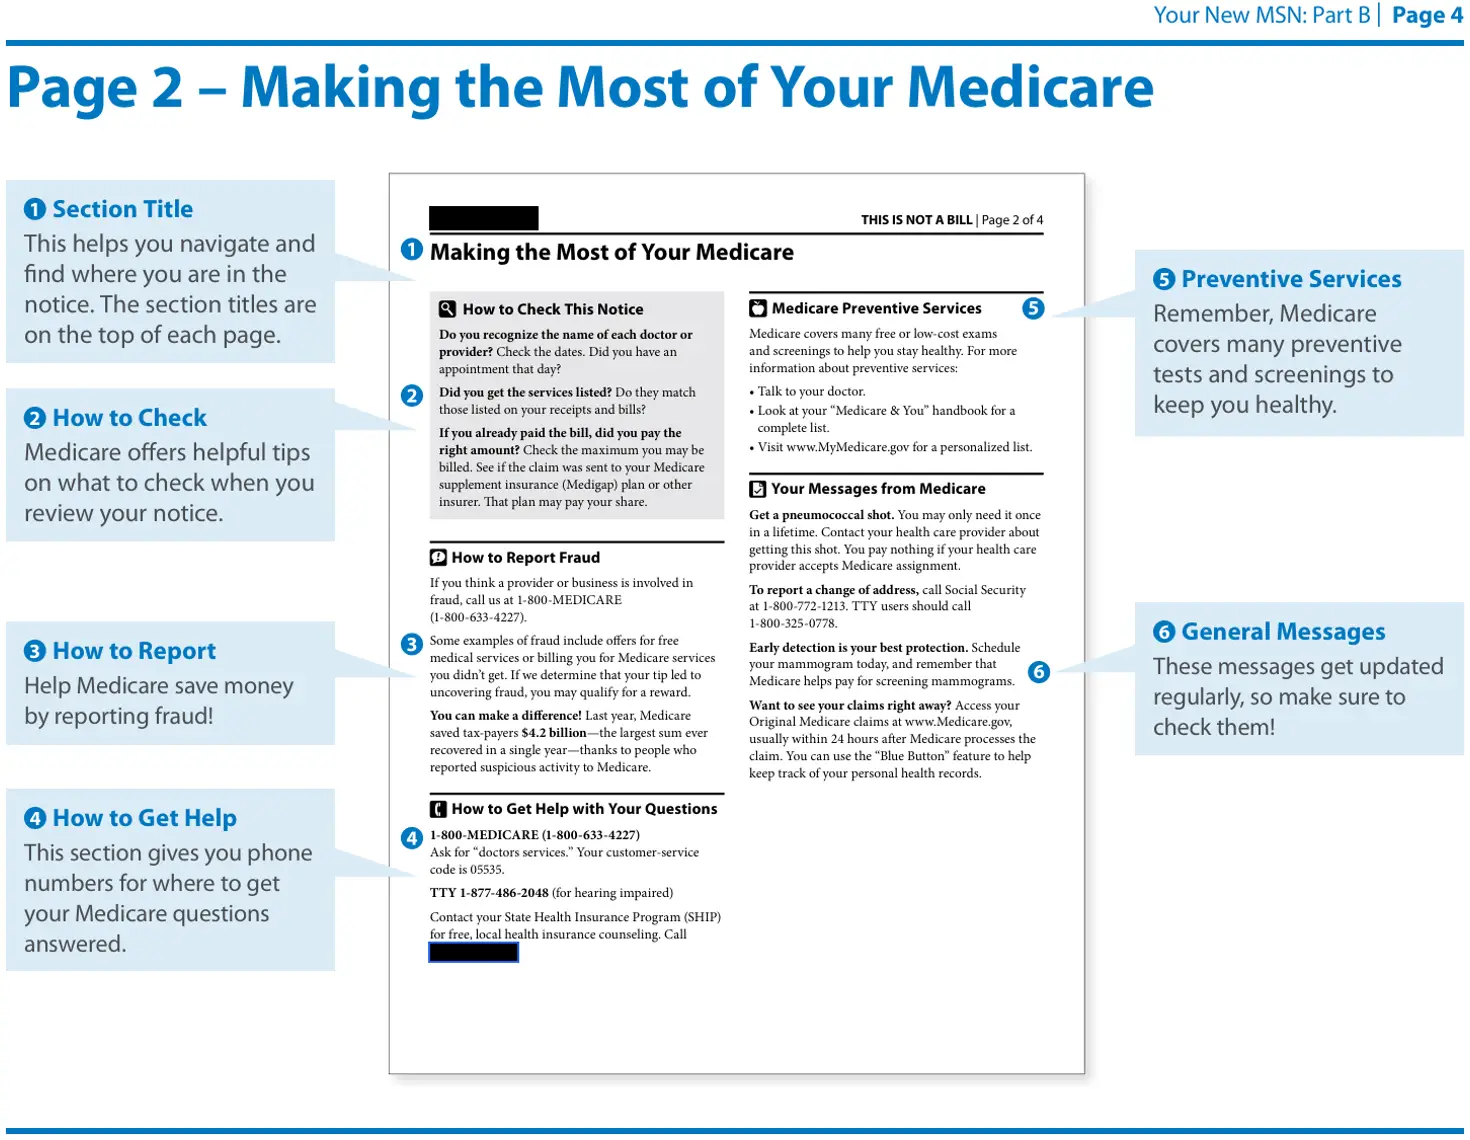
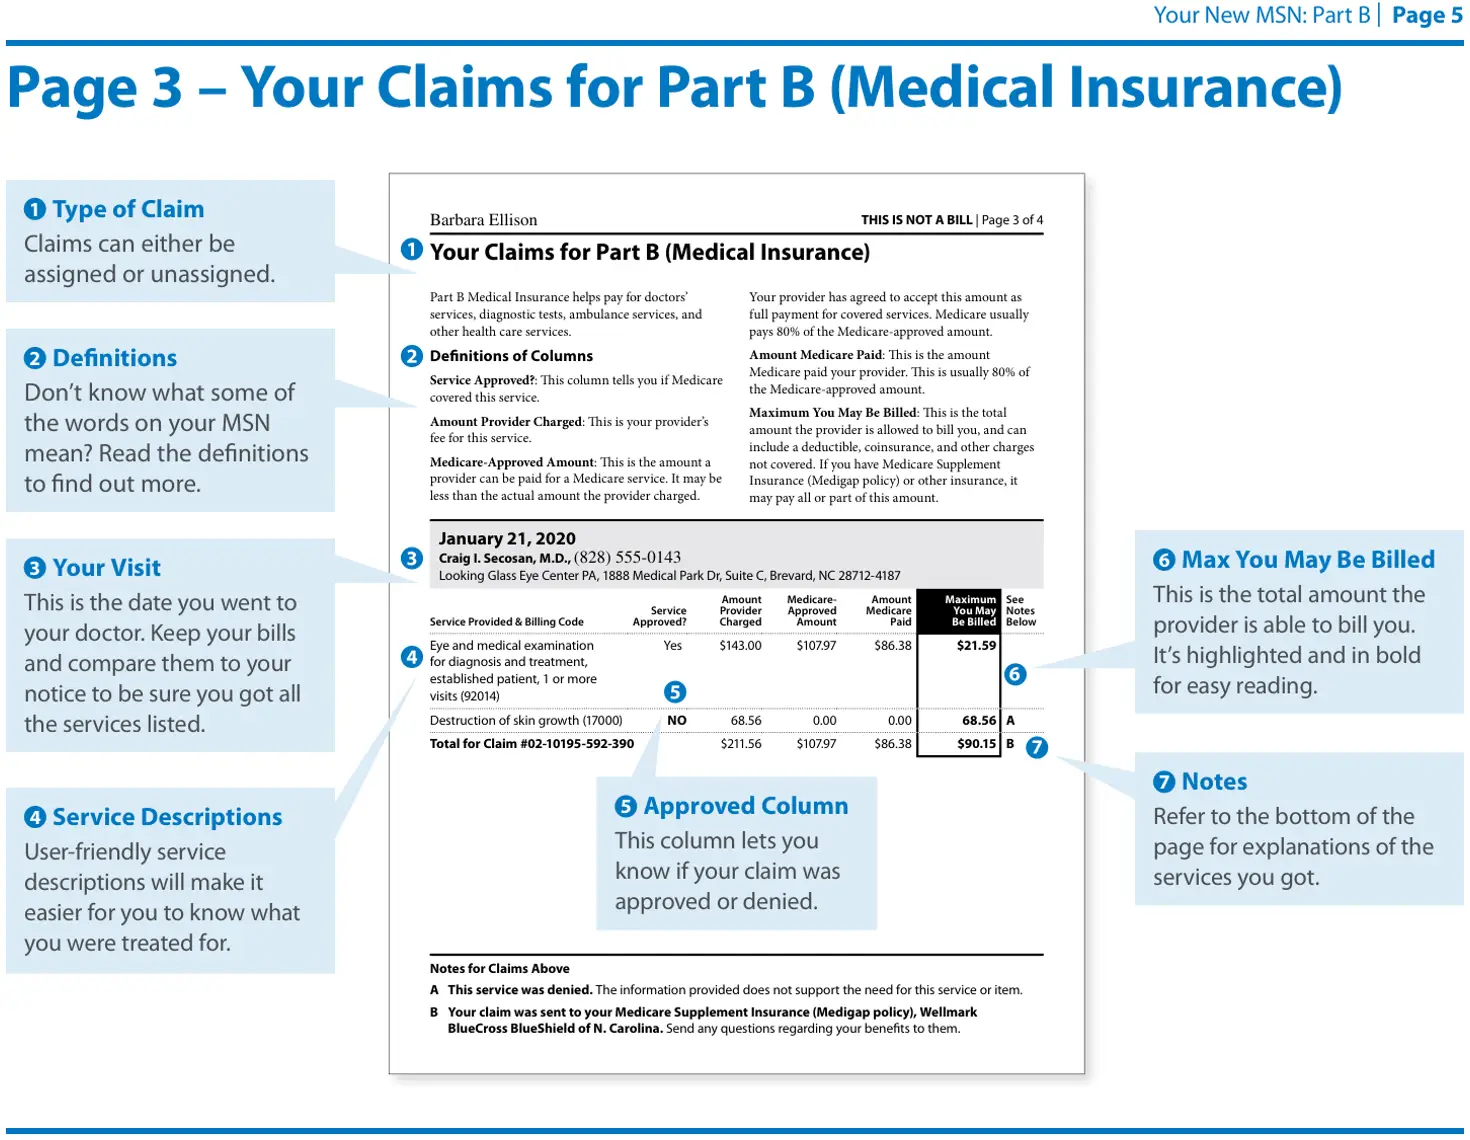
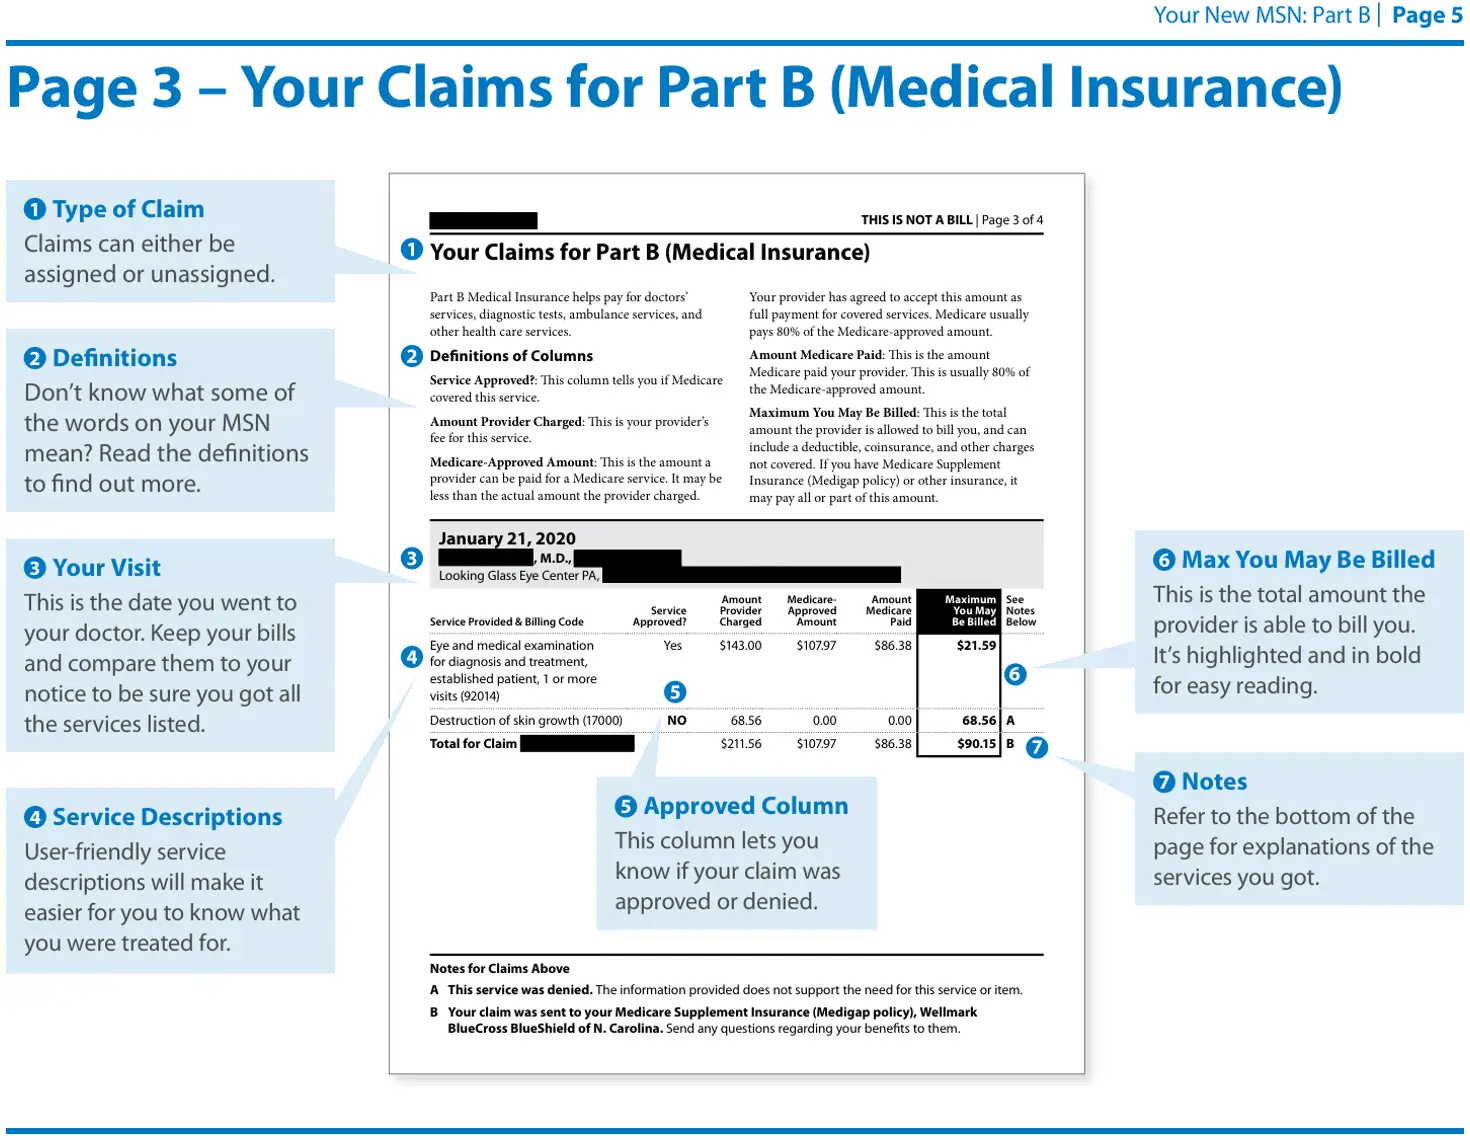
medicare-sample-part-b-msn.pdf
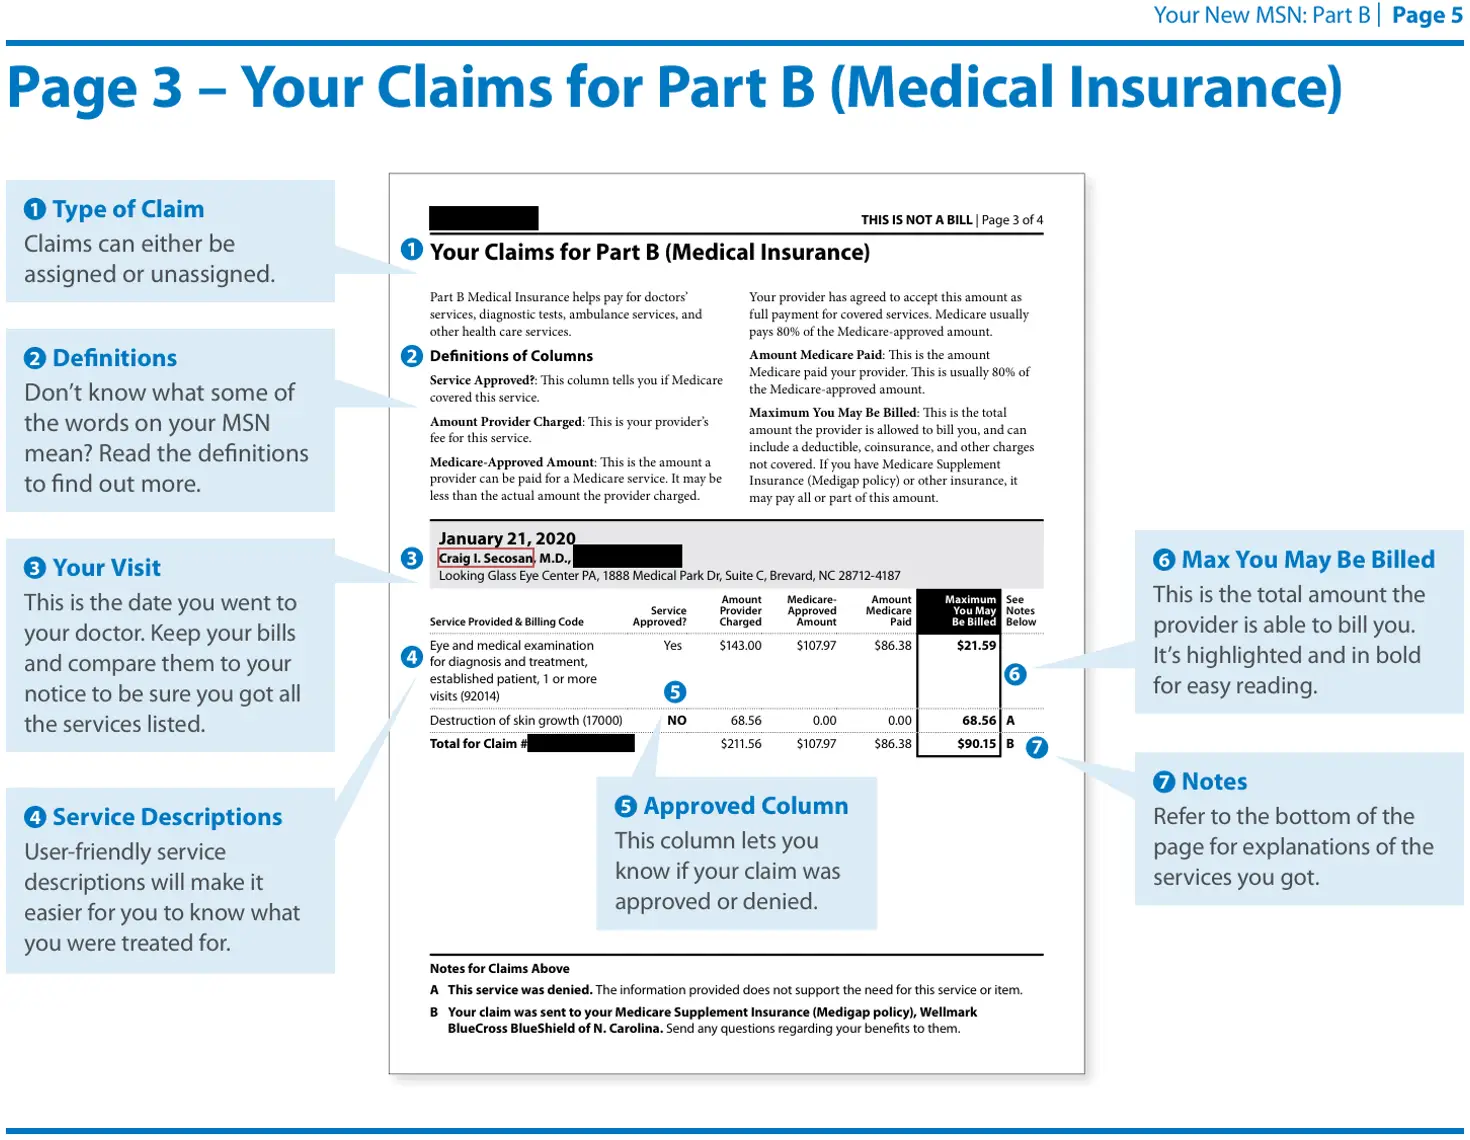
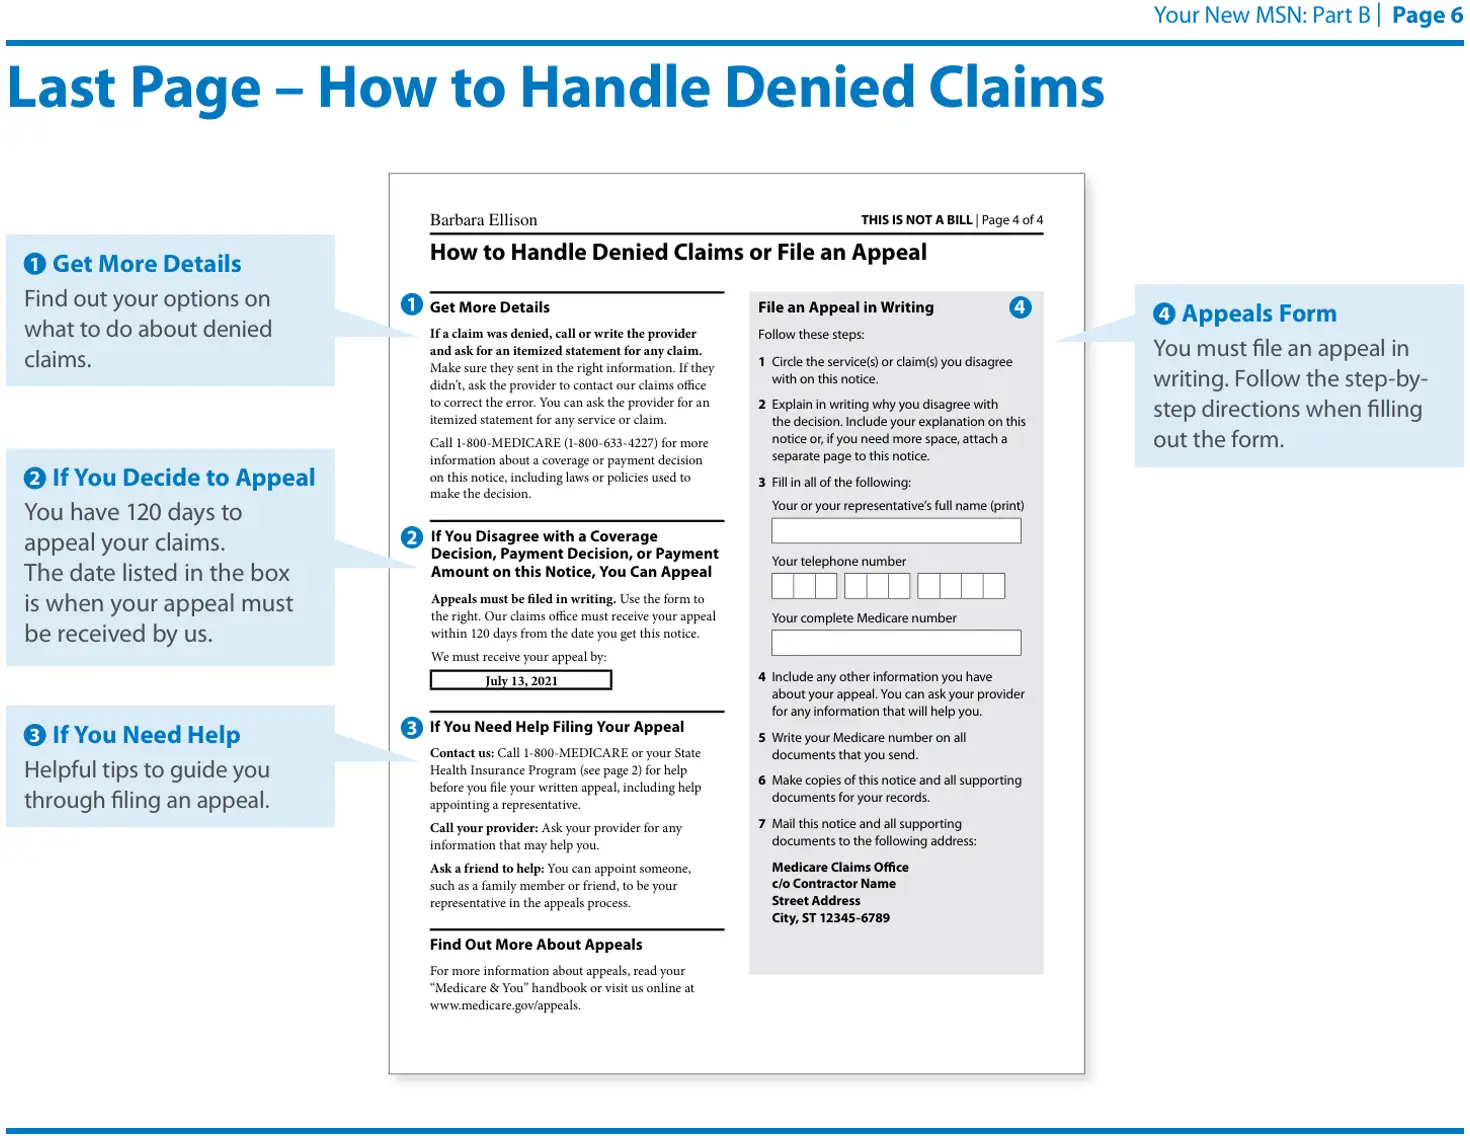
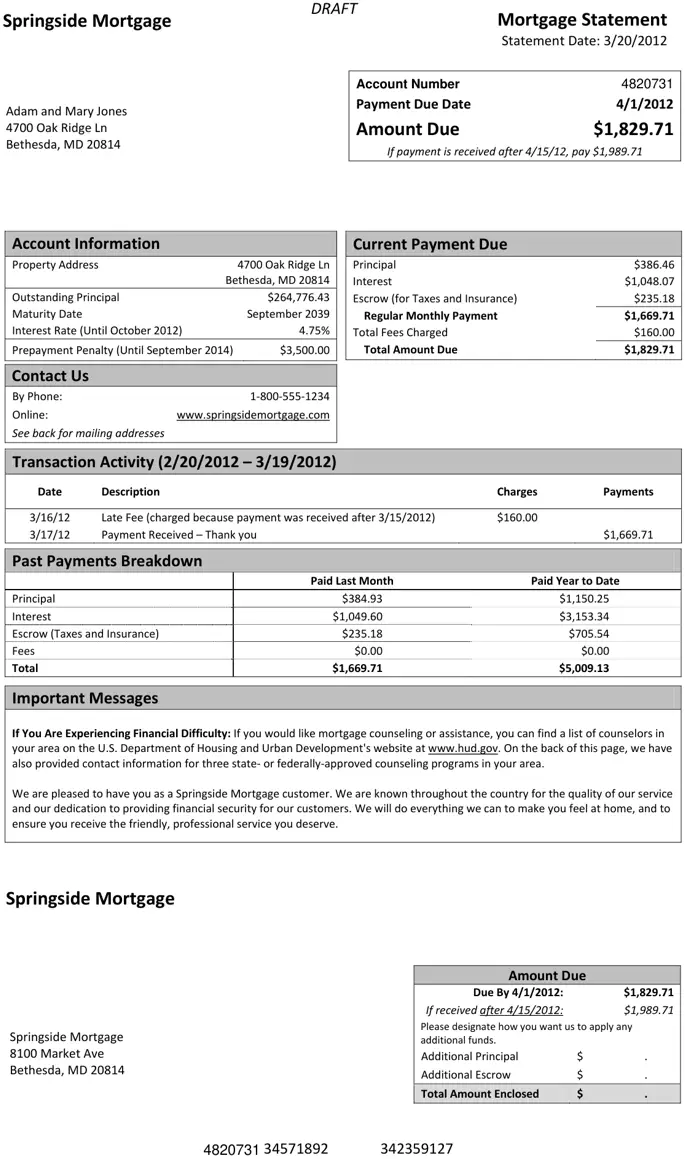
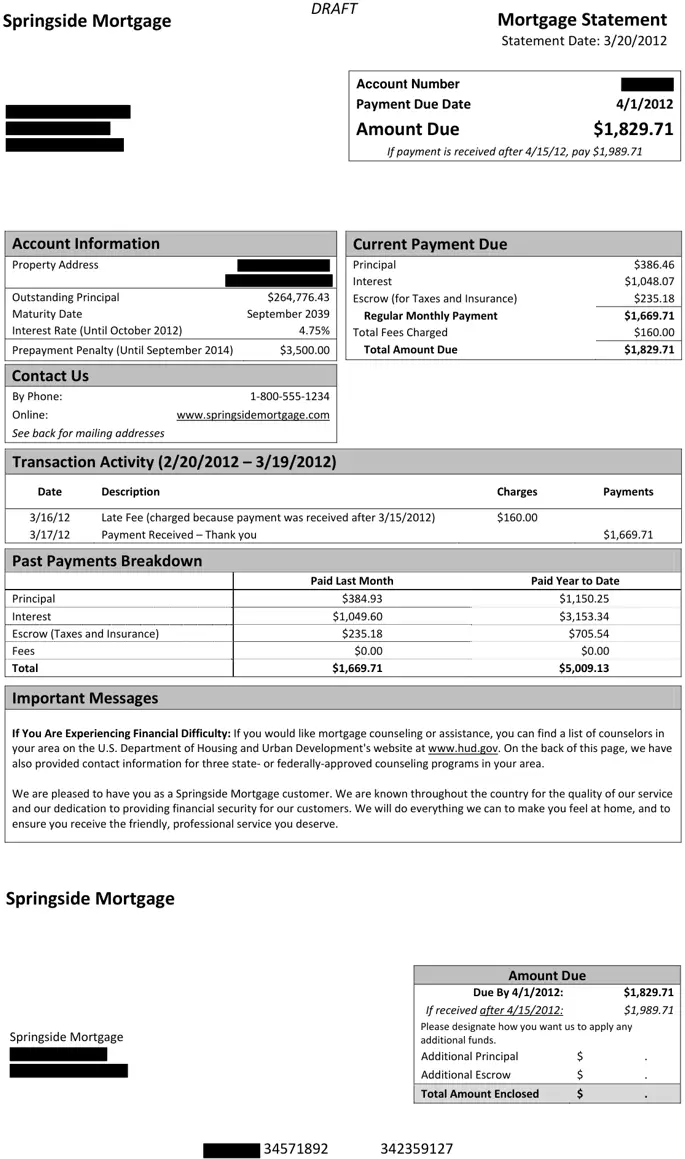
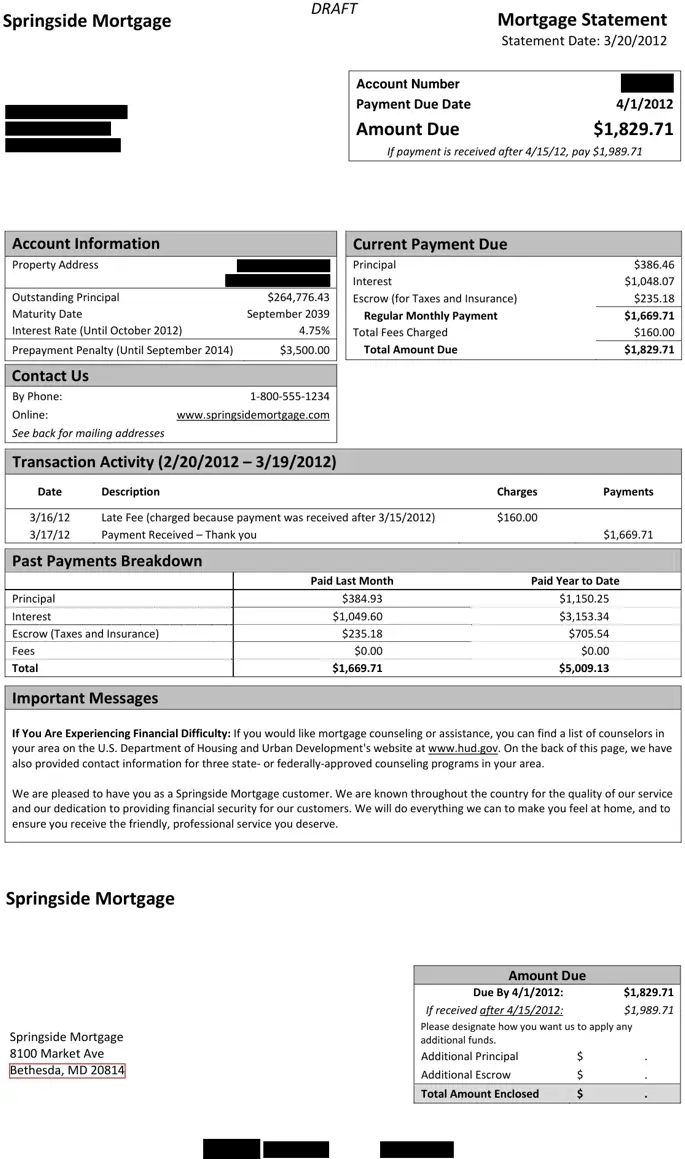
cfpb-draft-periodic-mortgage-statement.pdf
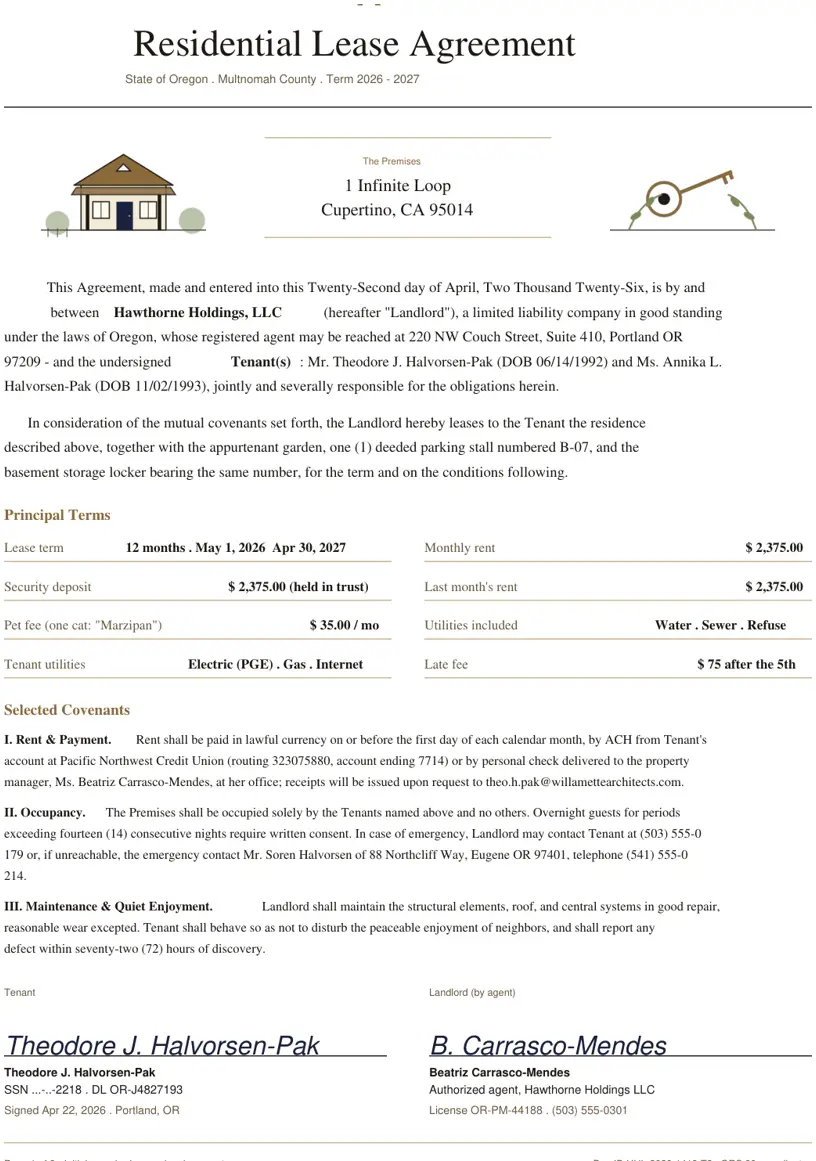
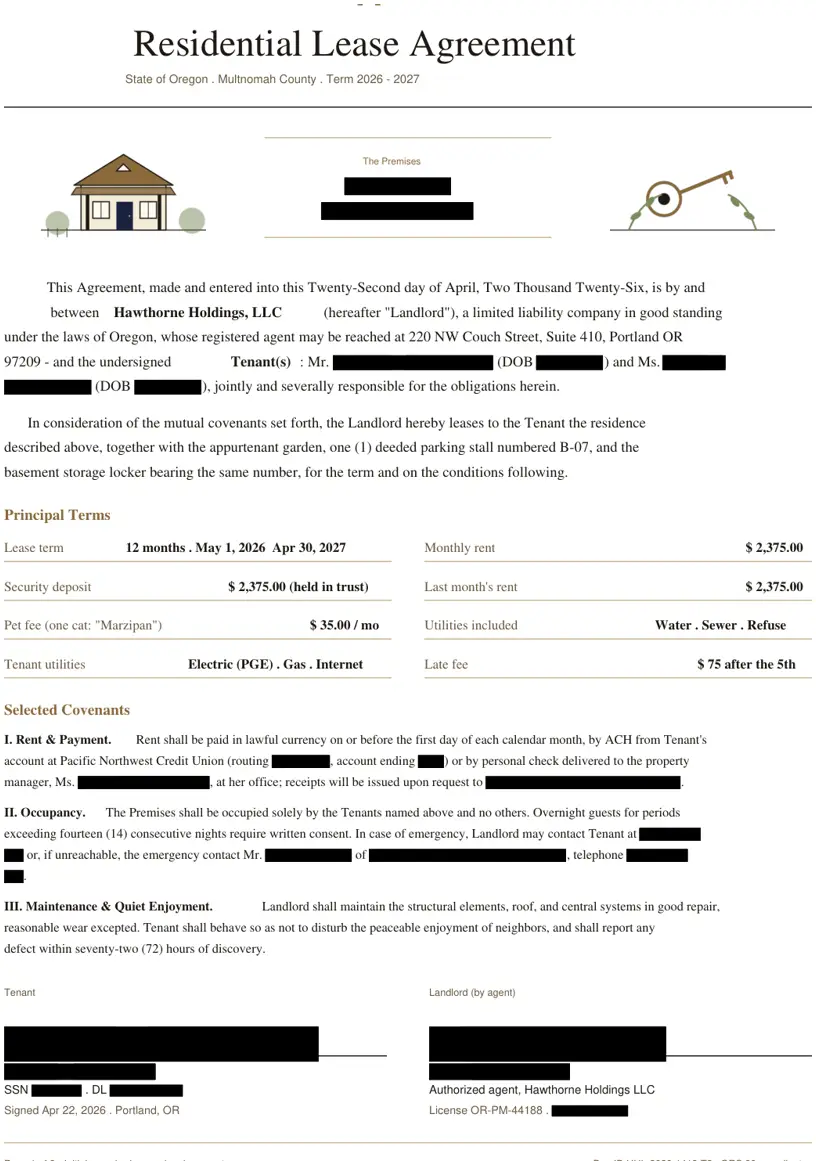
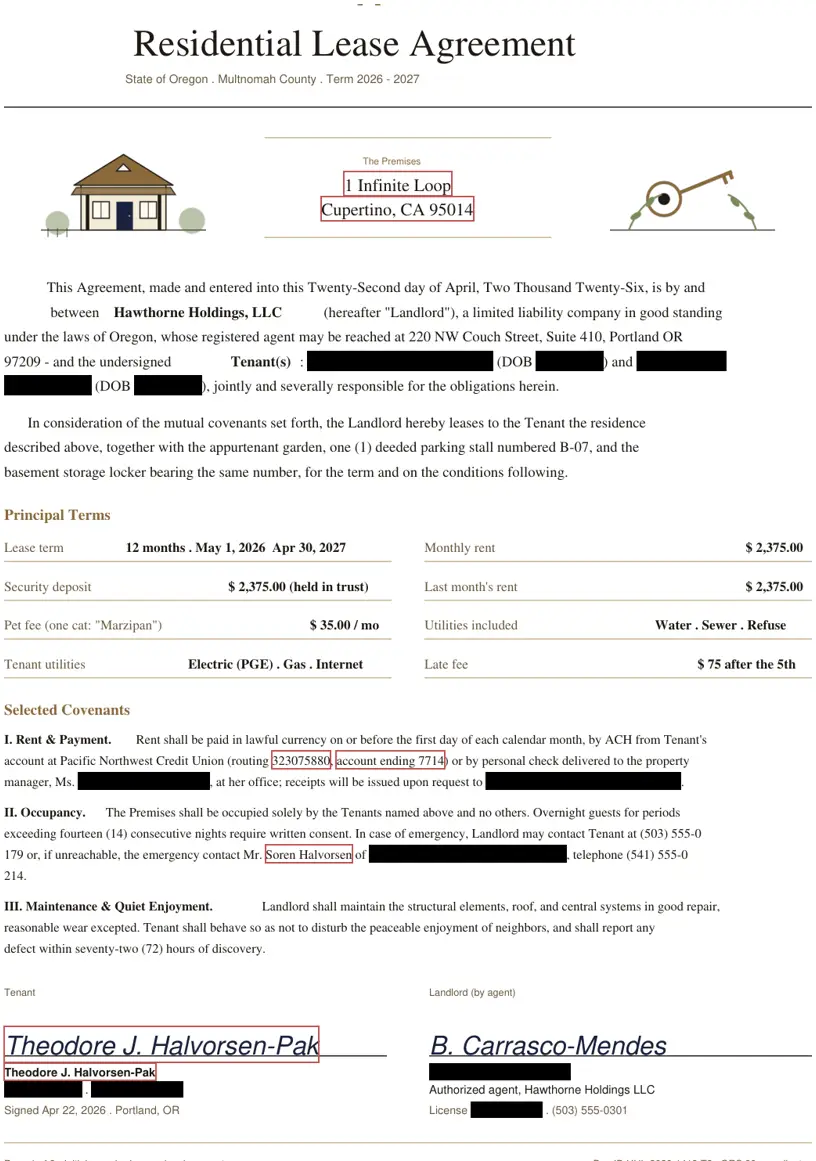
Lease_Agreement_signed.pdf
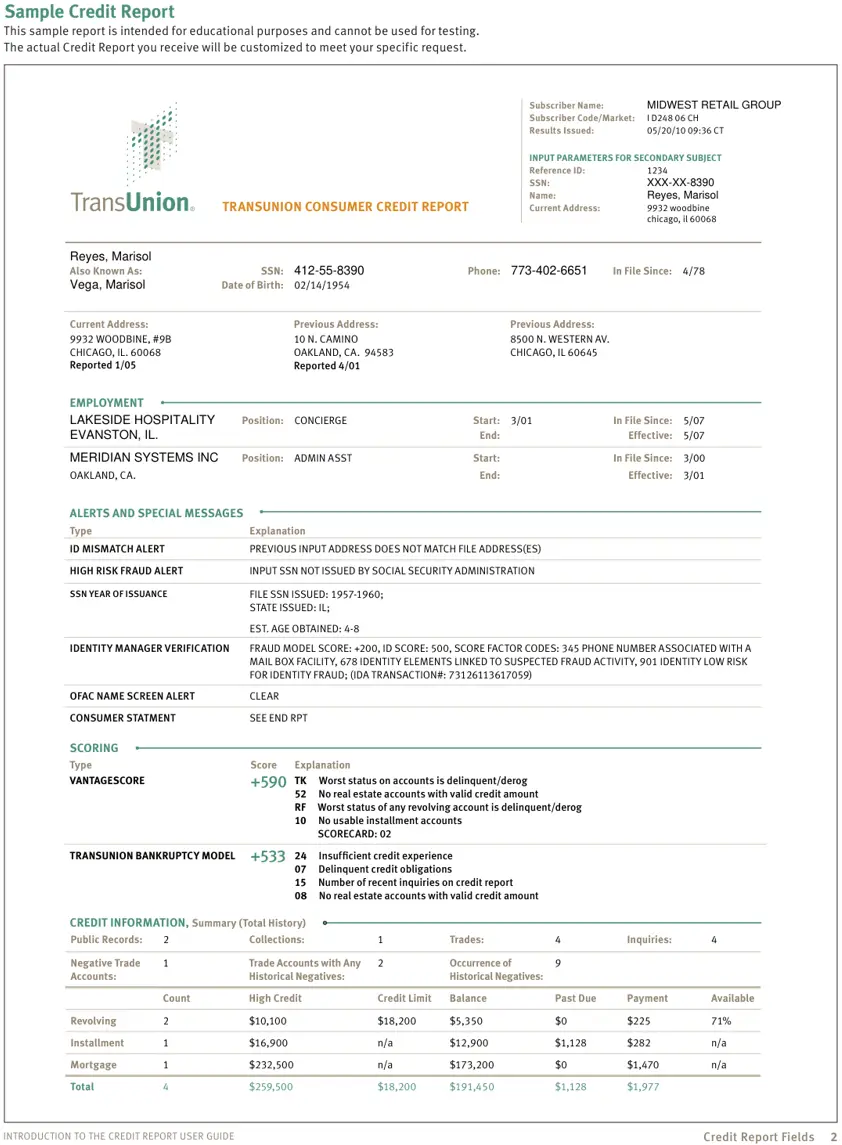
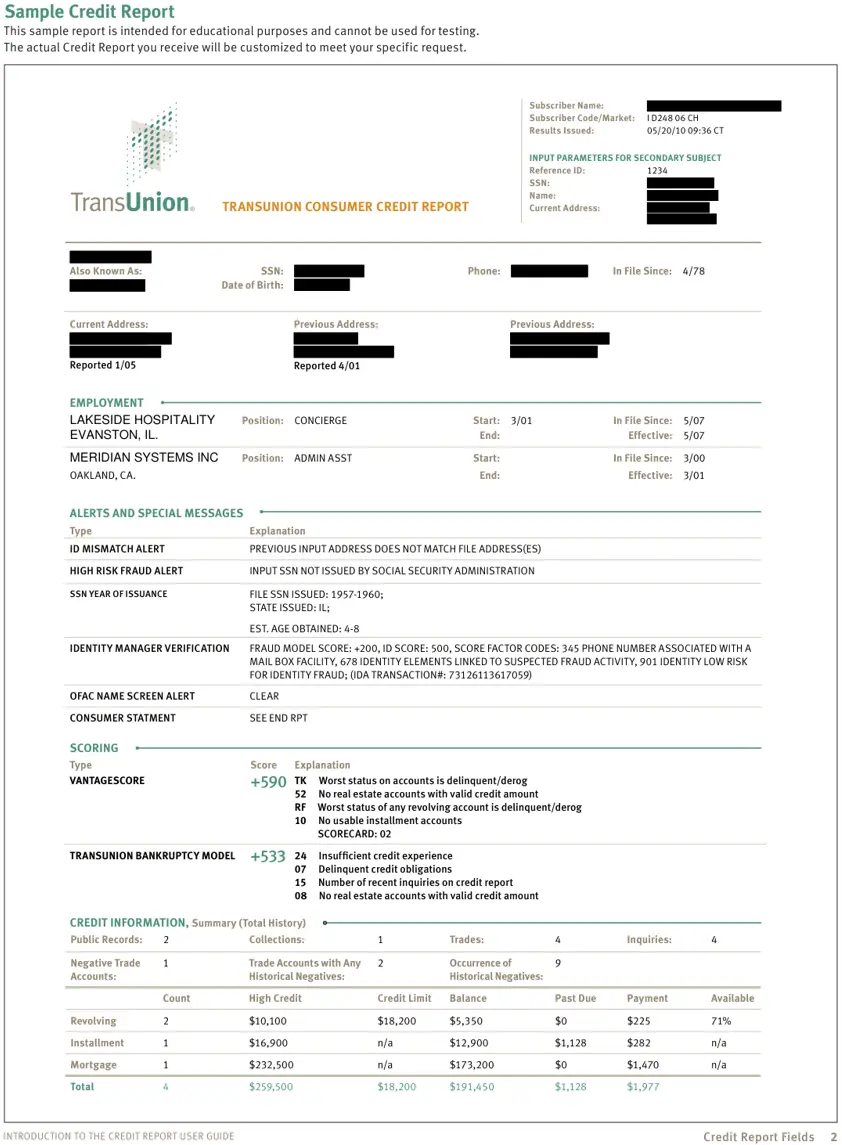
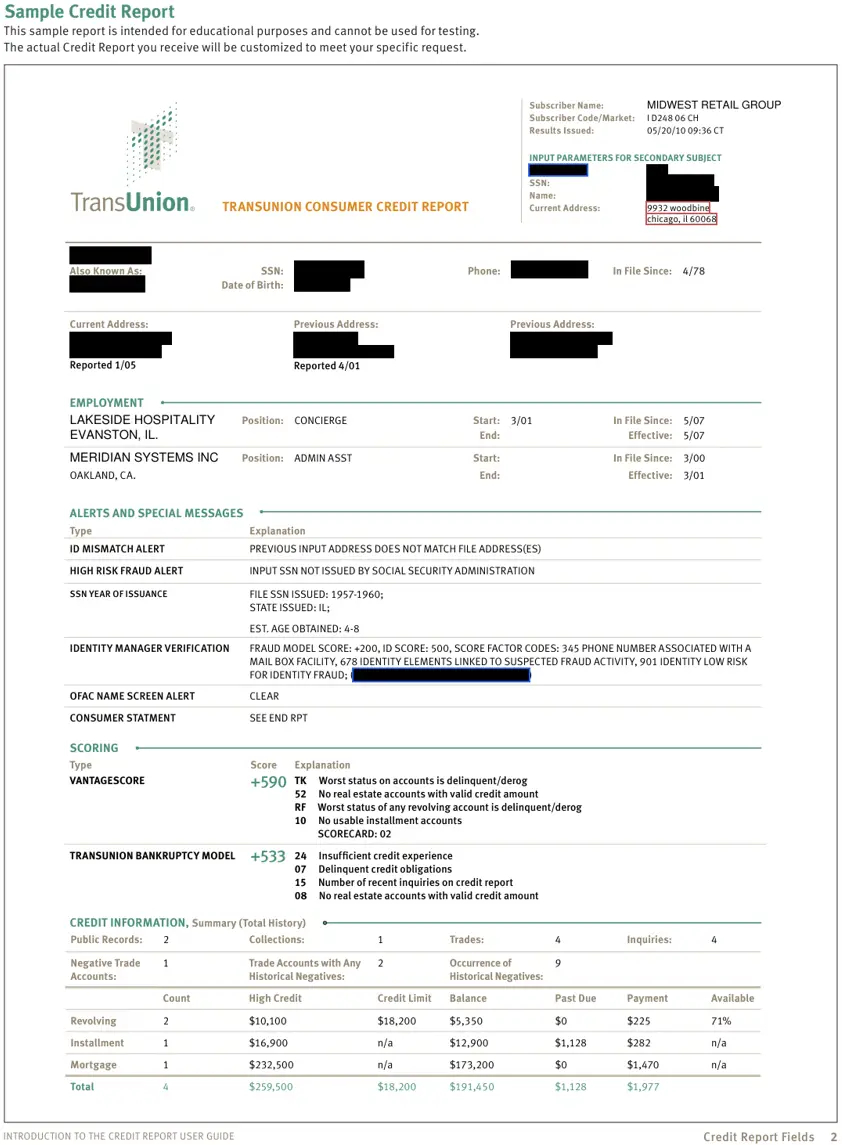
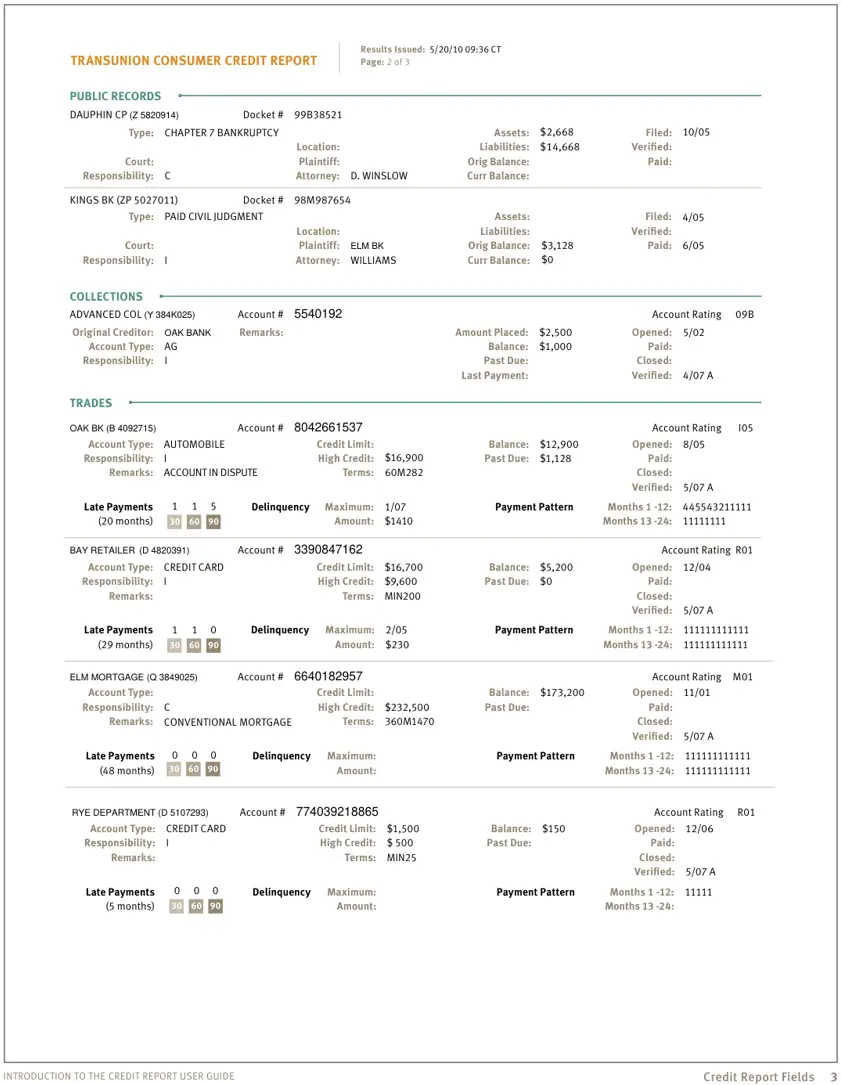
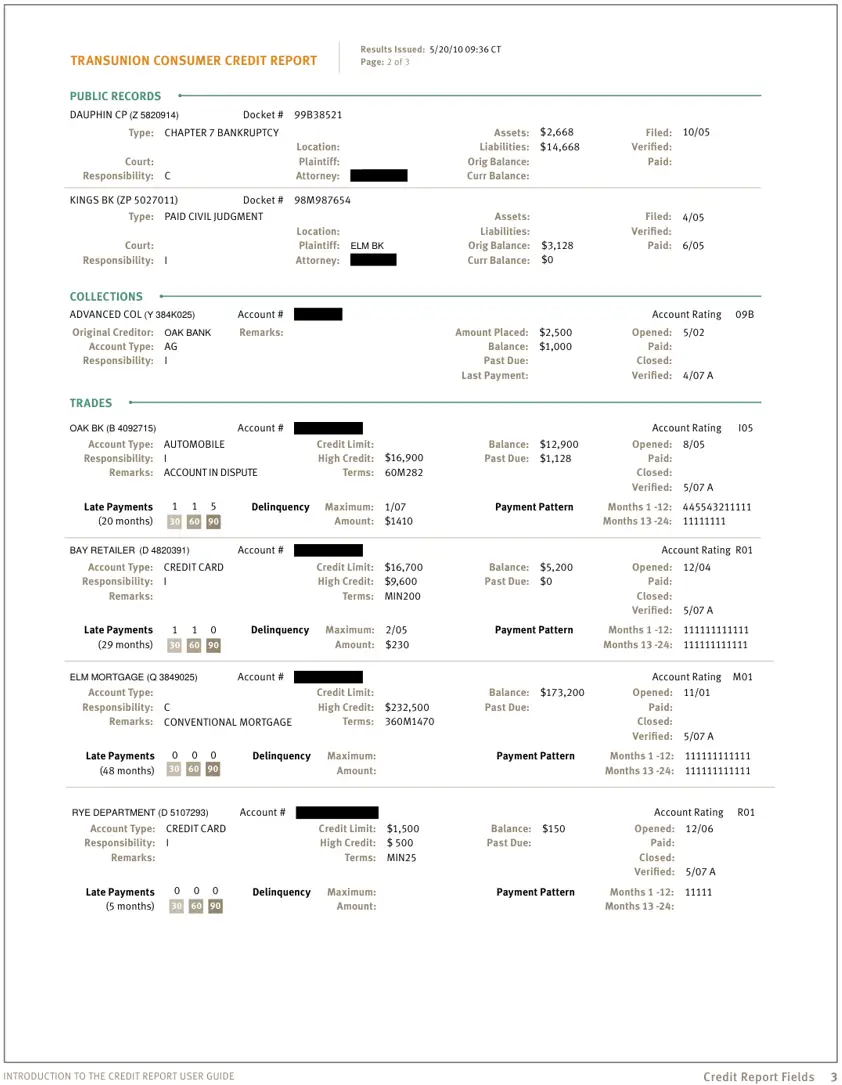
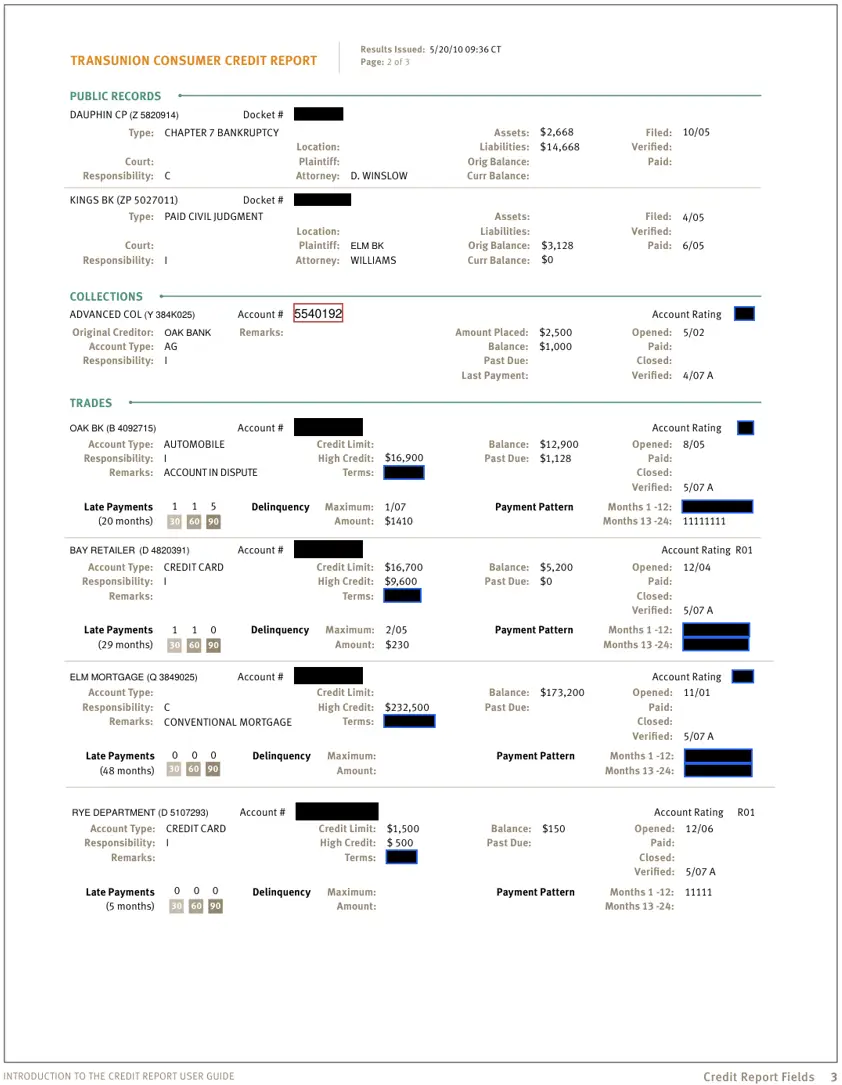
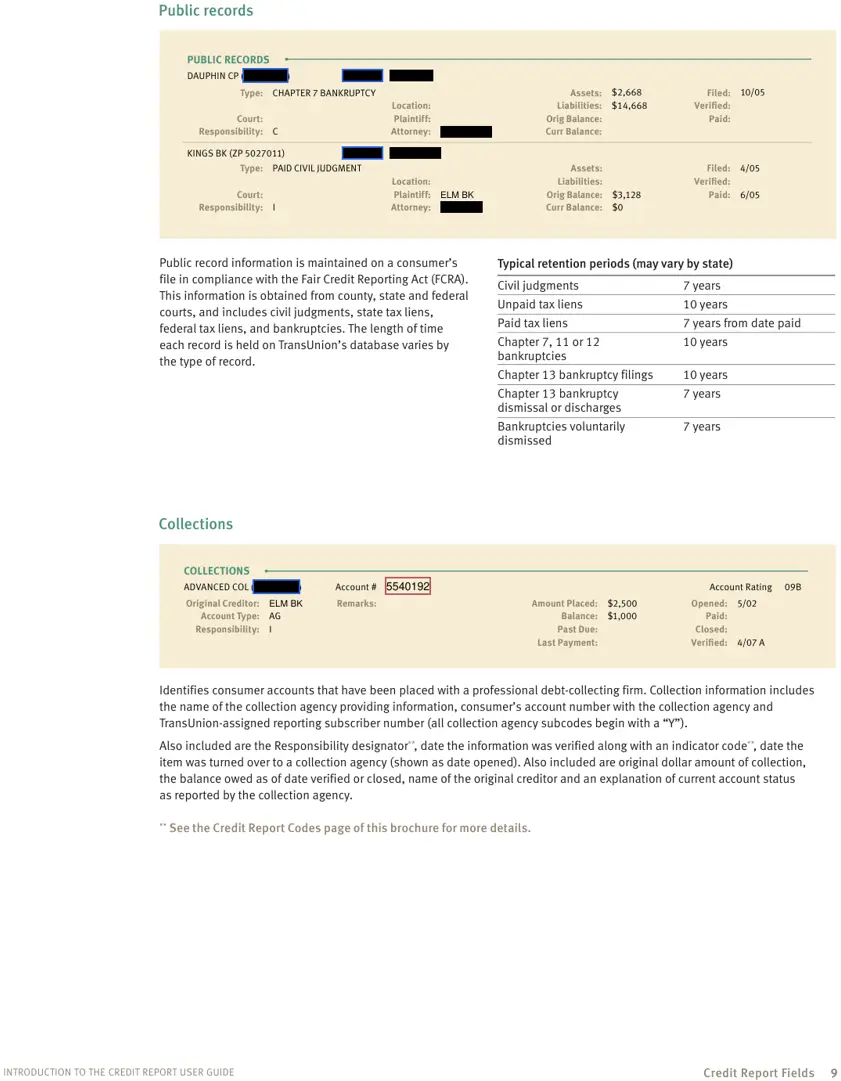
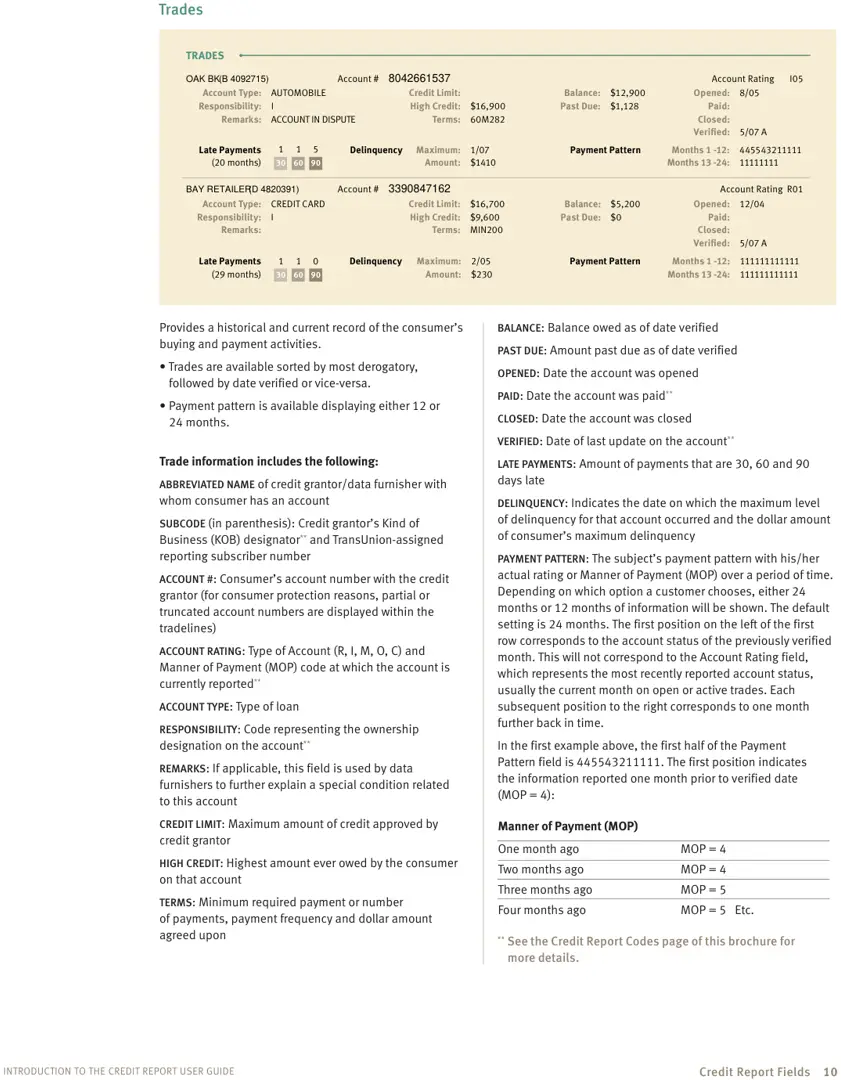
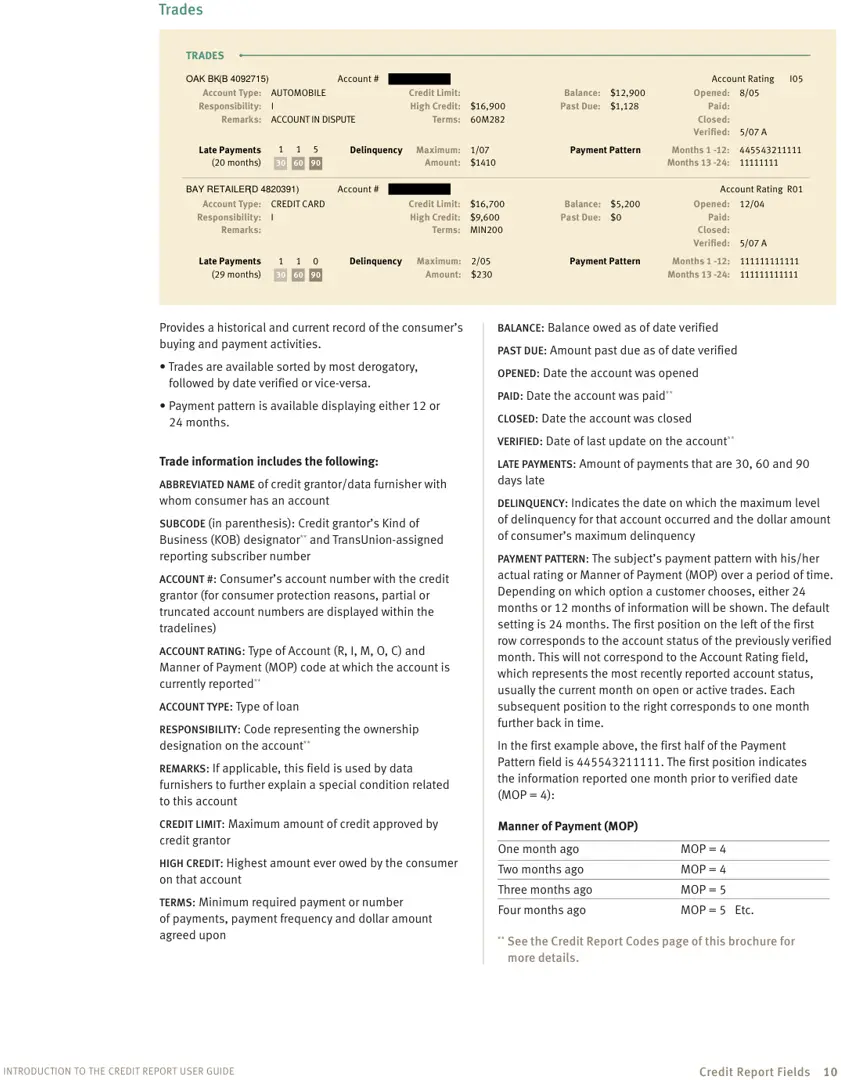
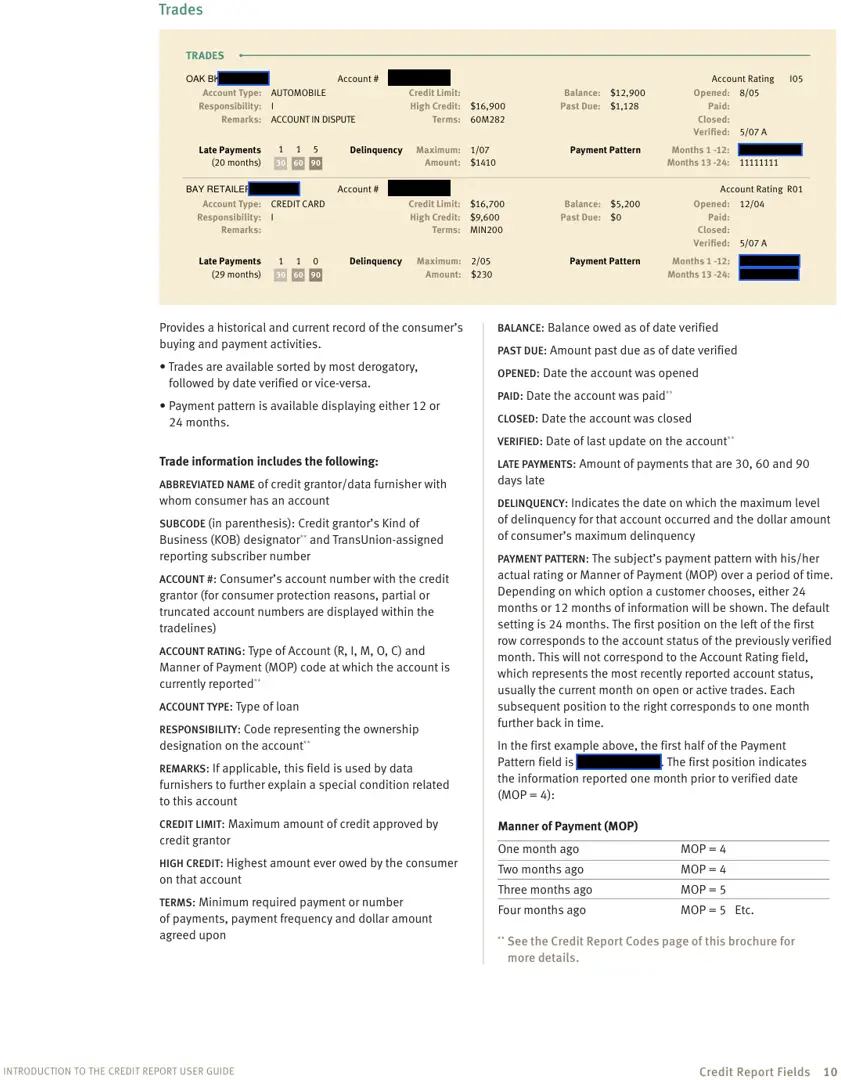
transunion-cameo-credit-report-sample.pdf
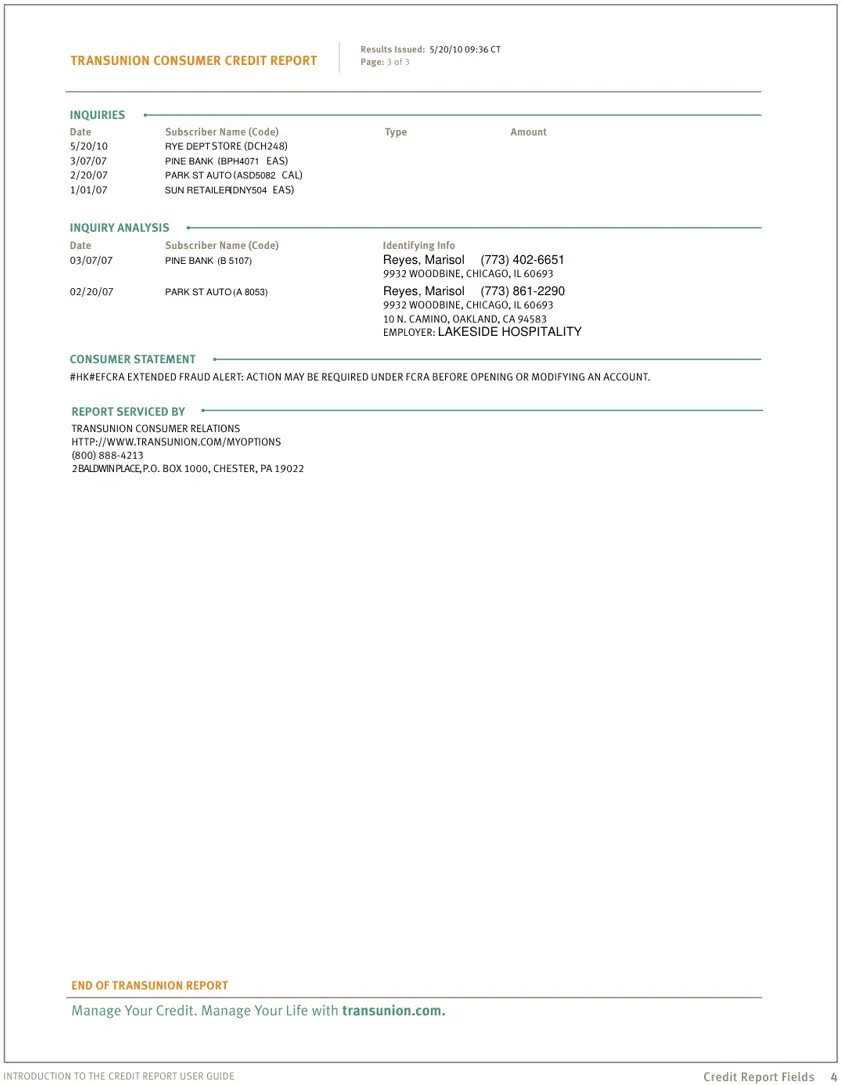
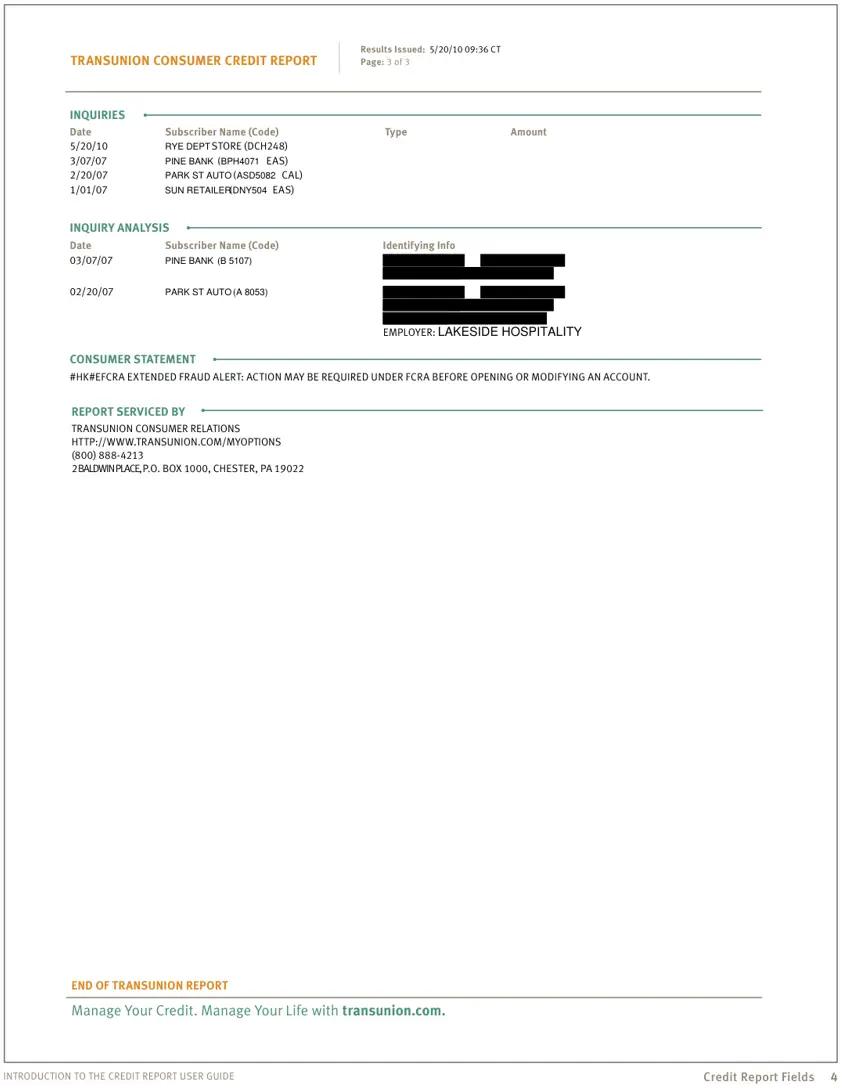
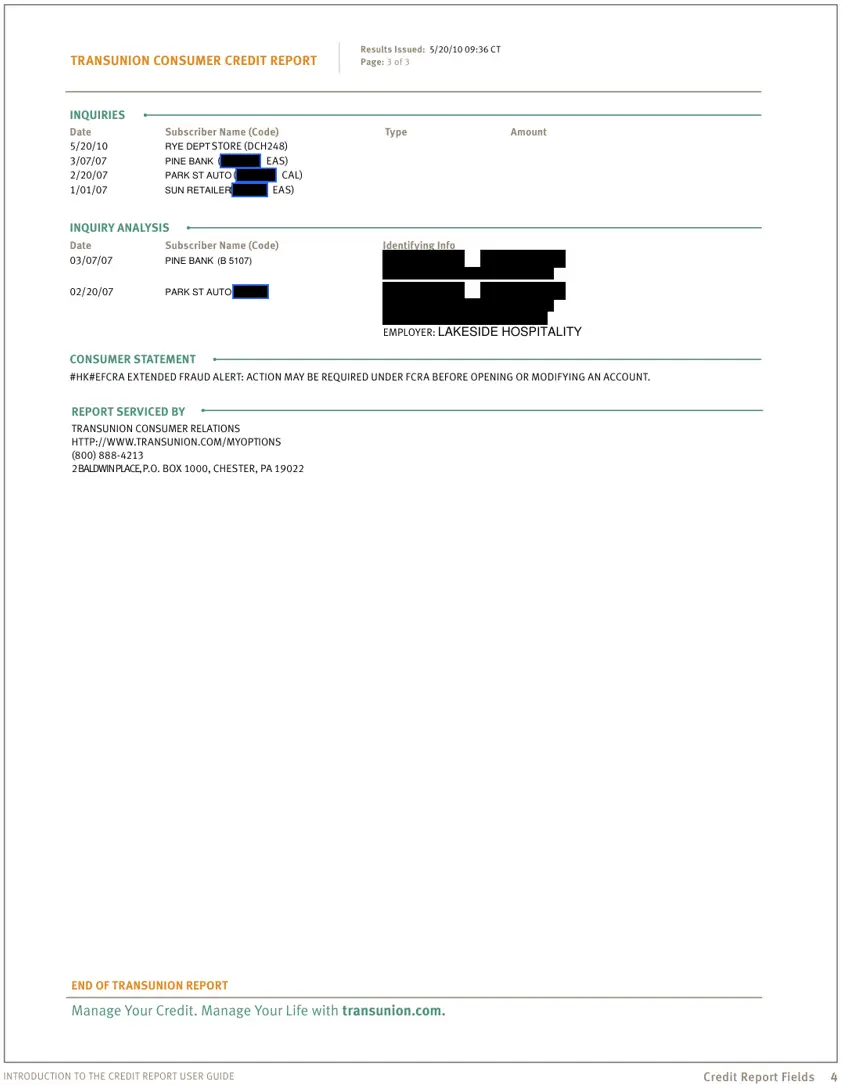
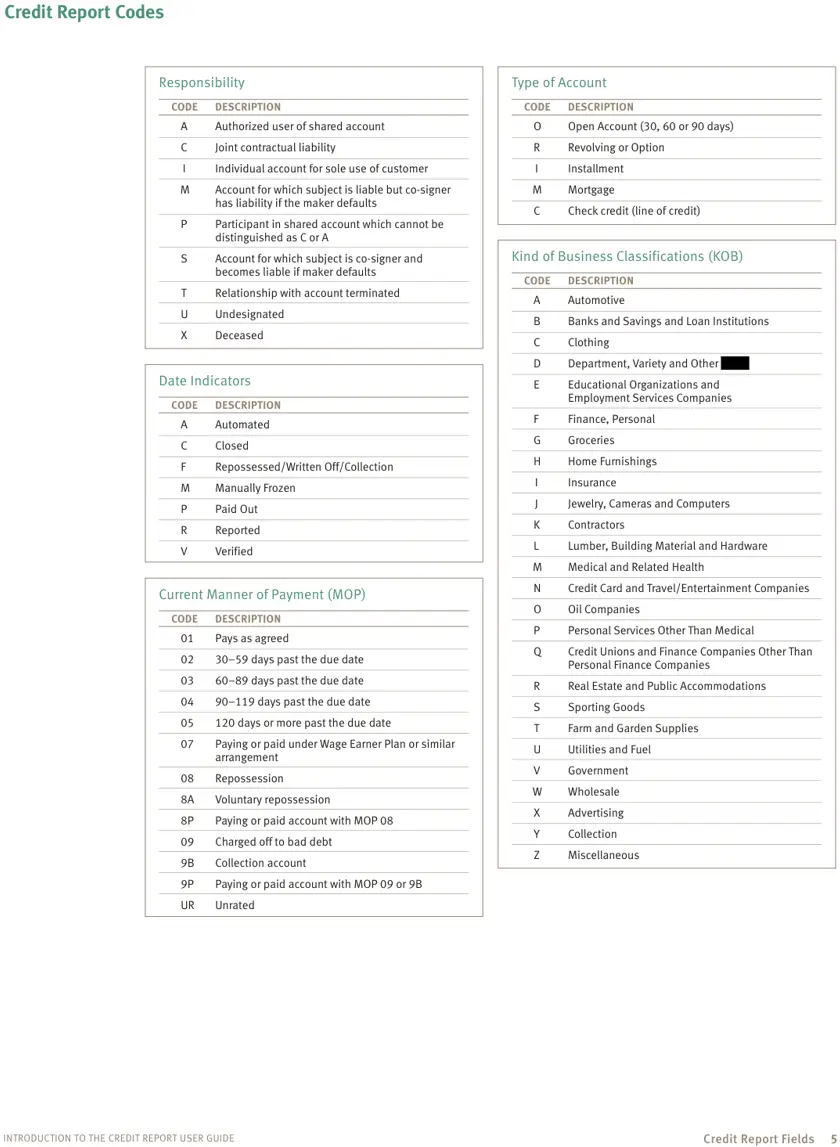
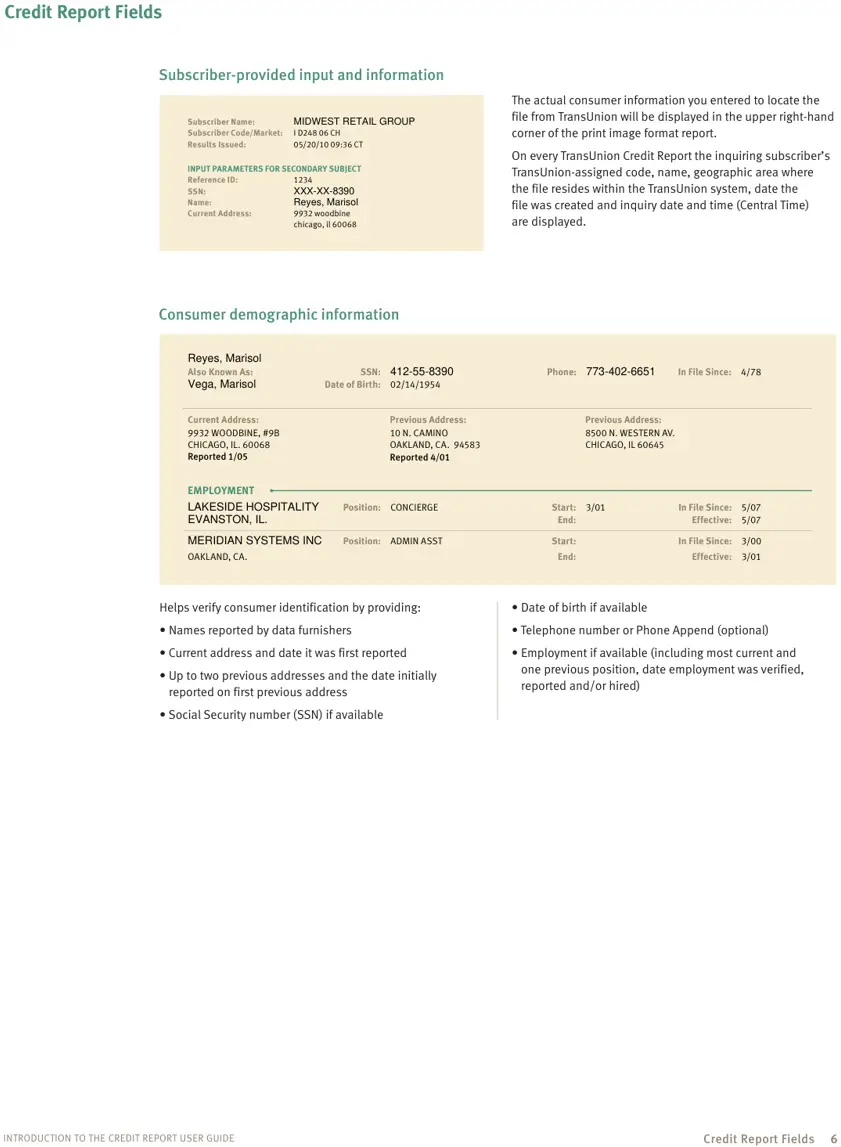
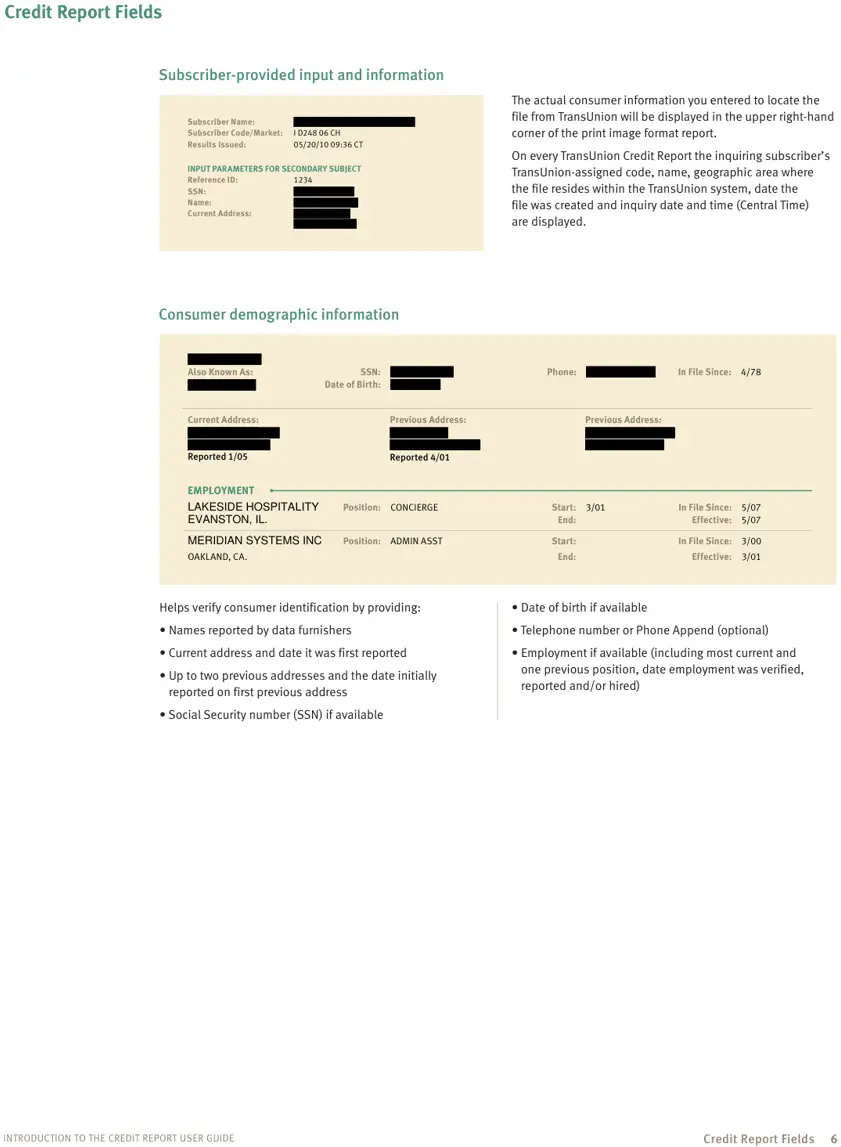
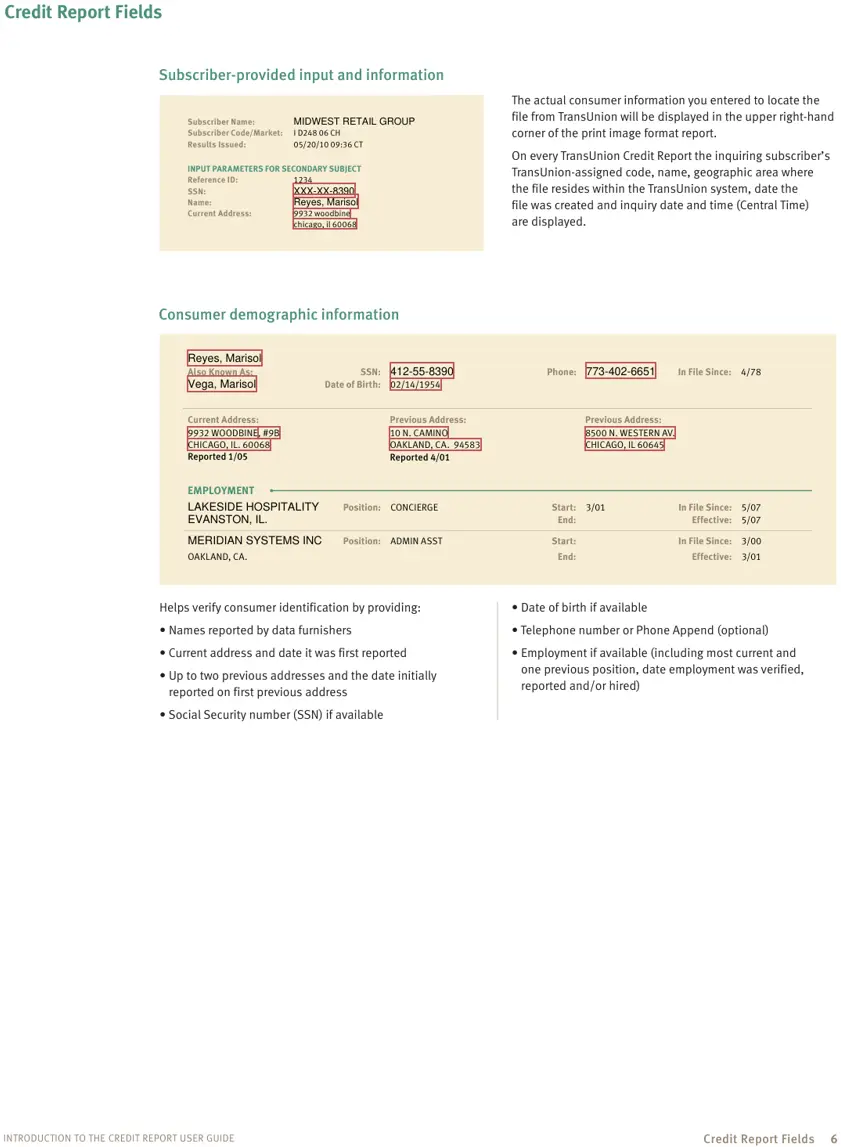
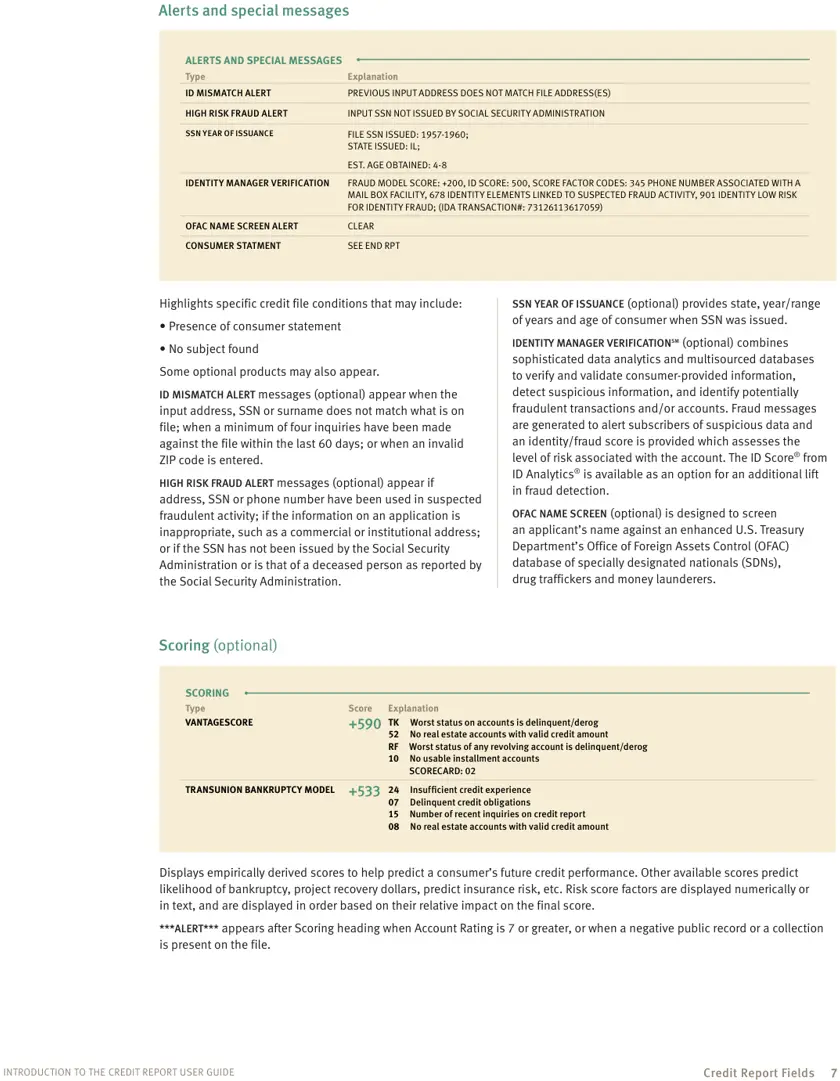
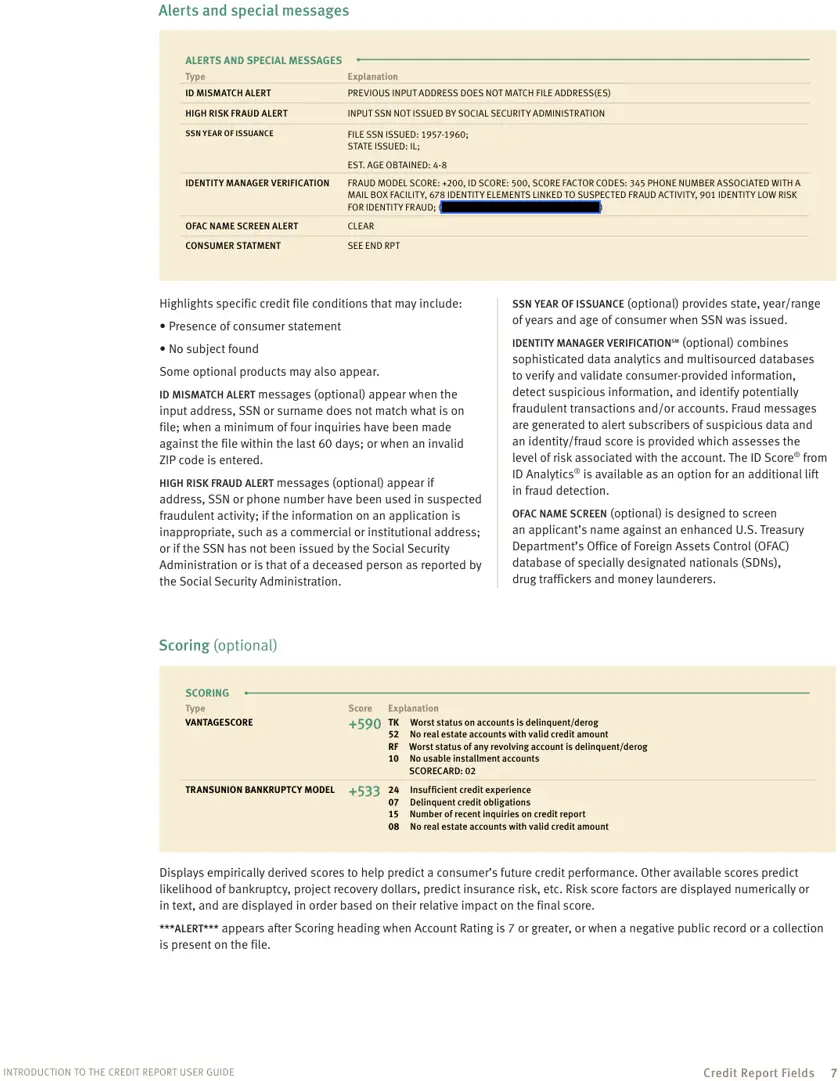
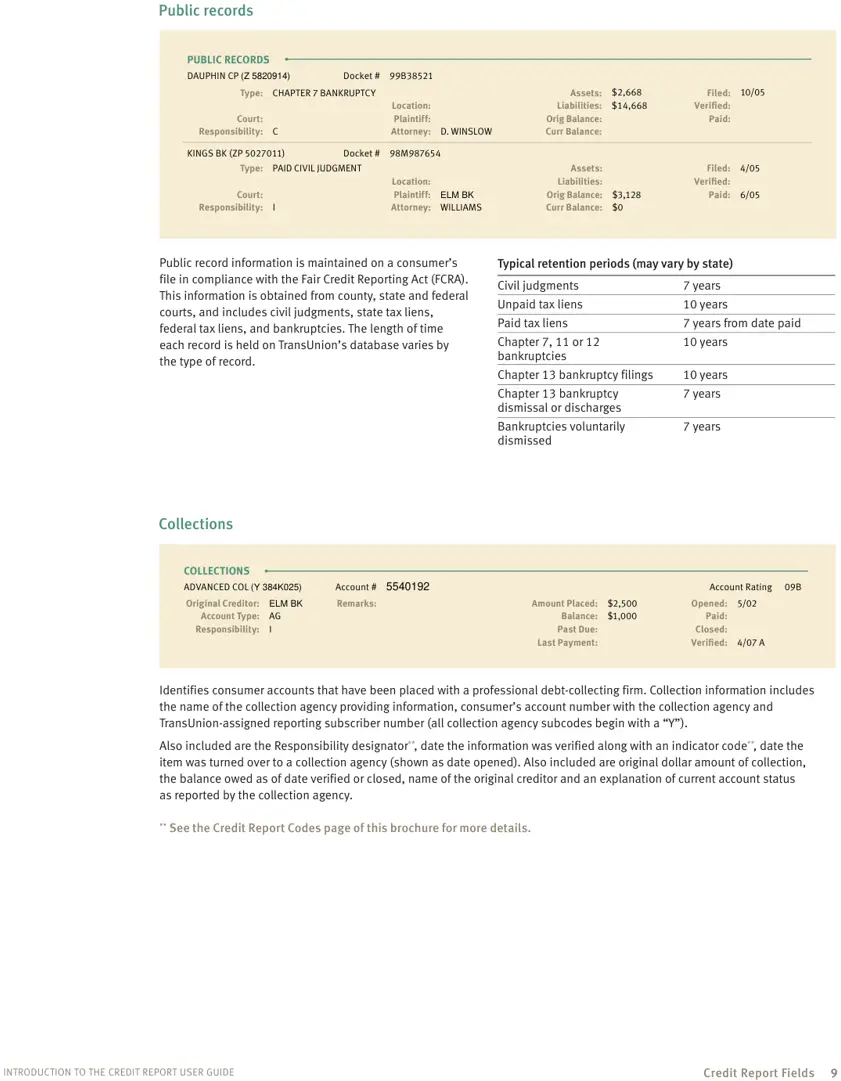
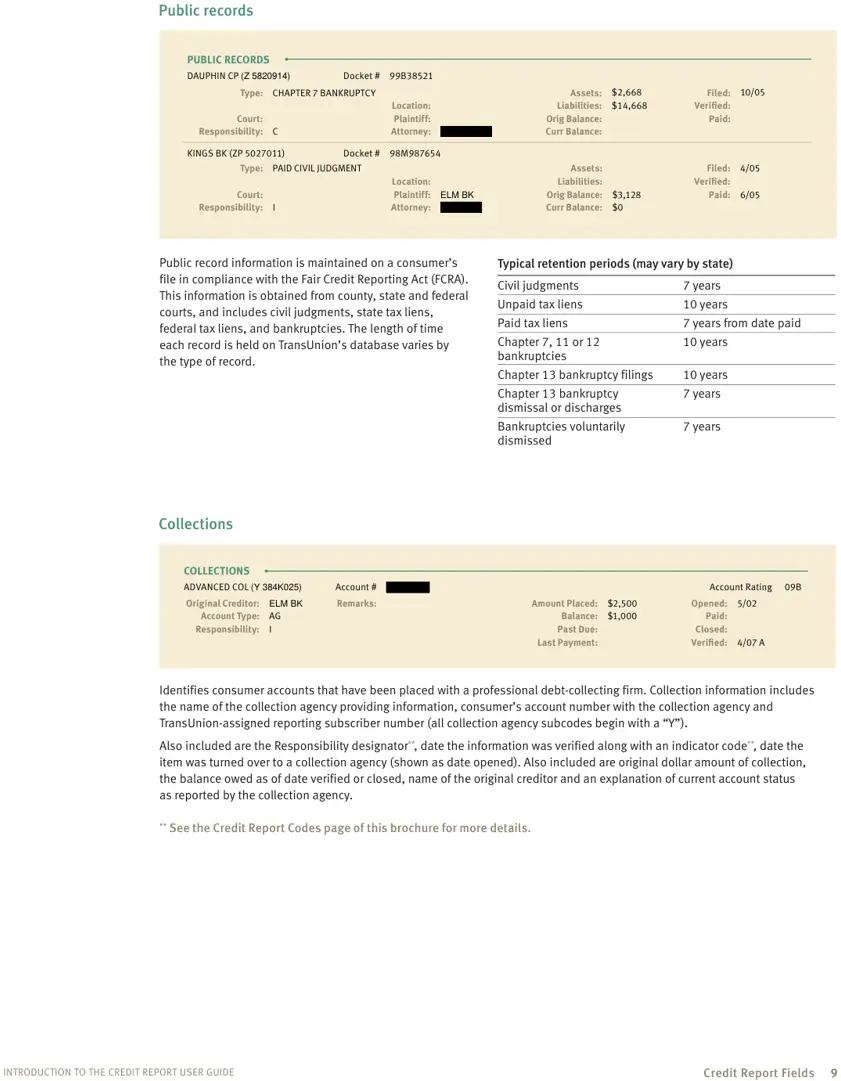
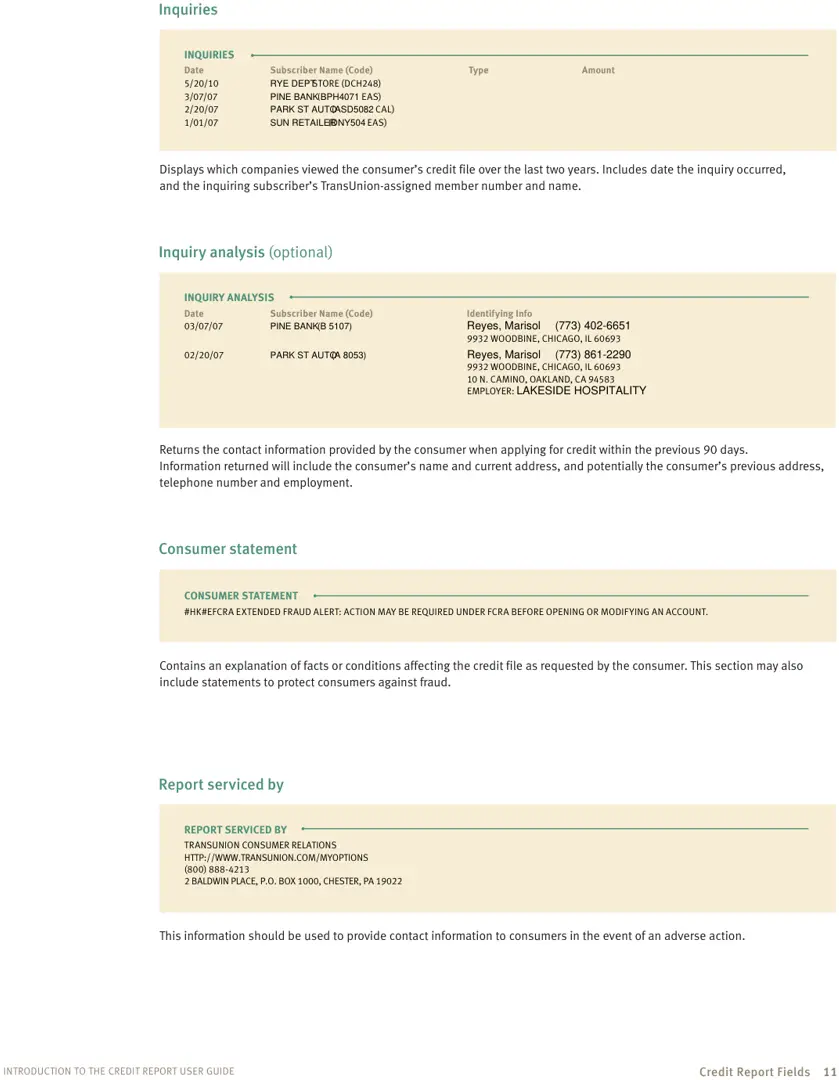
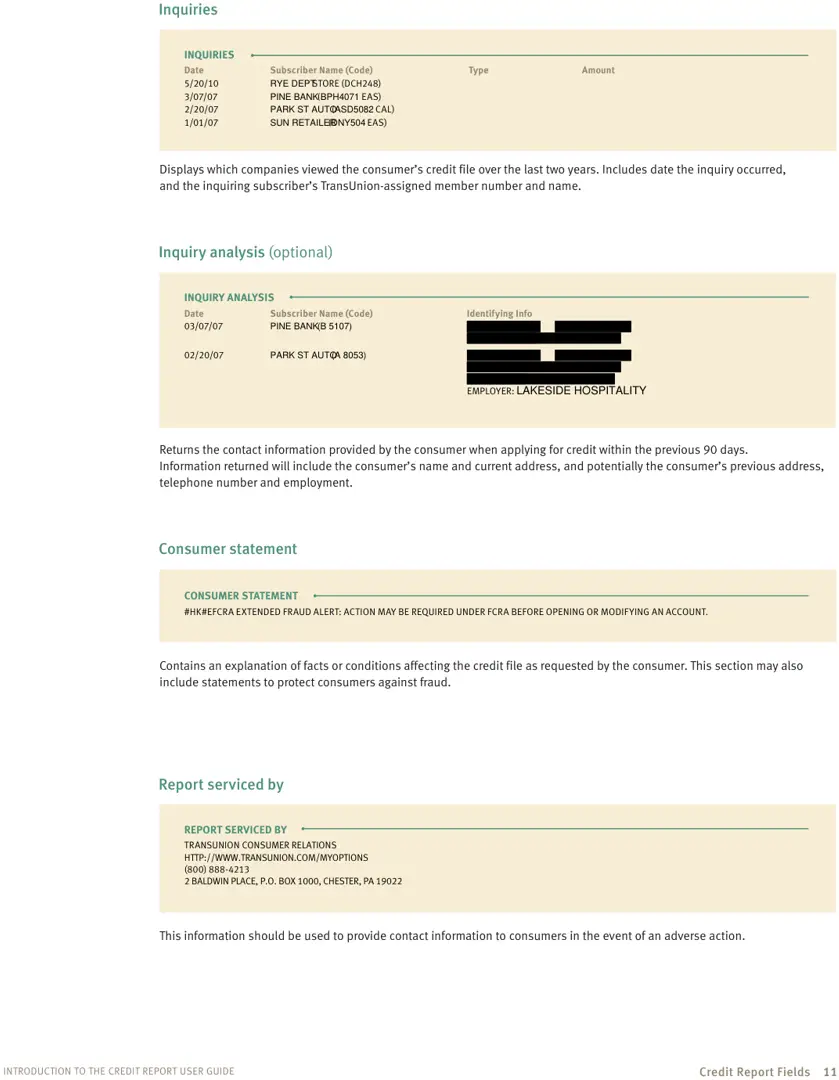
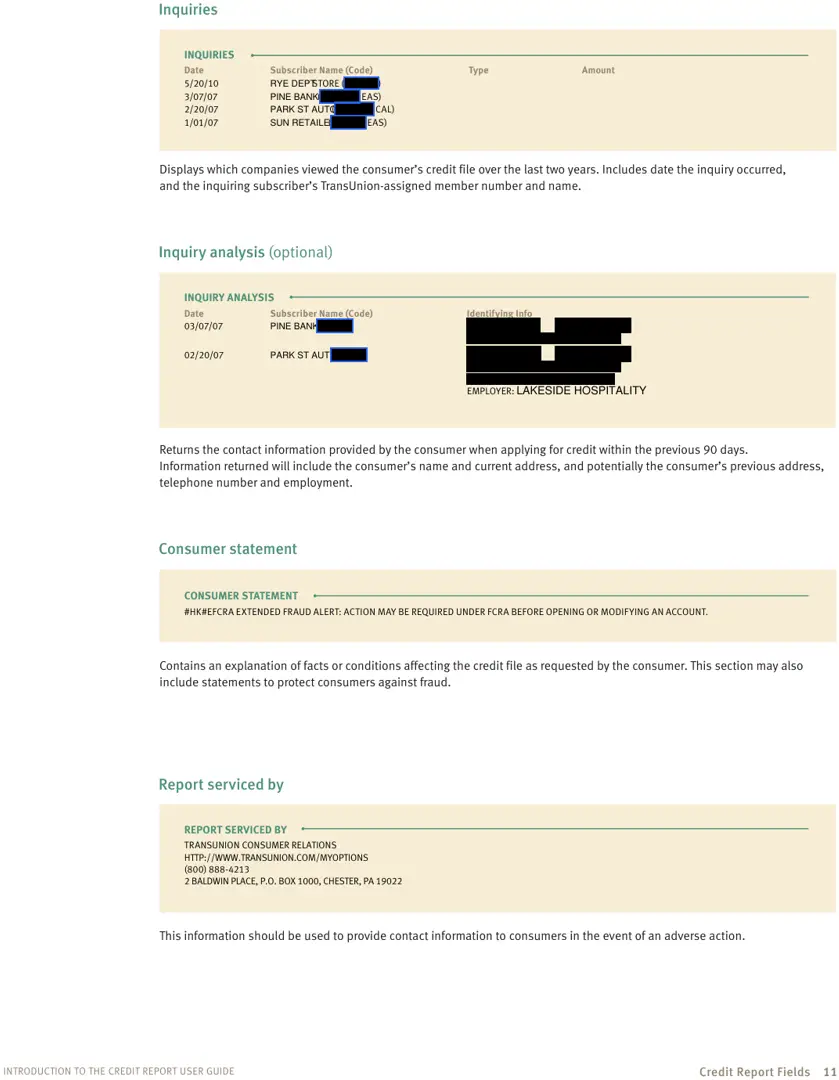
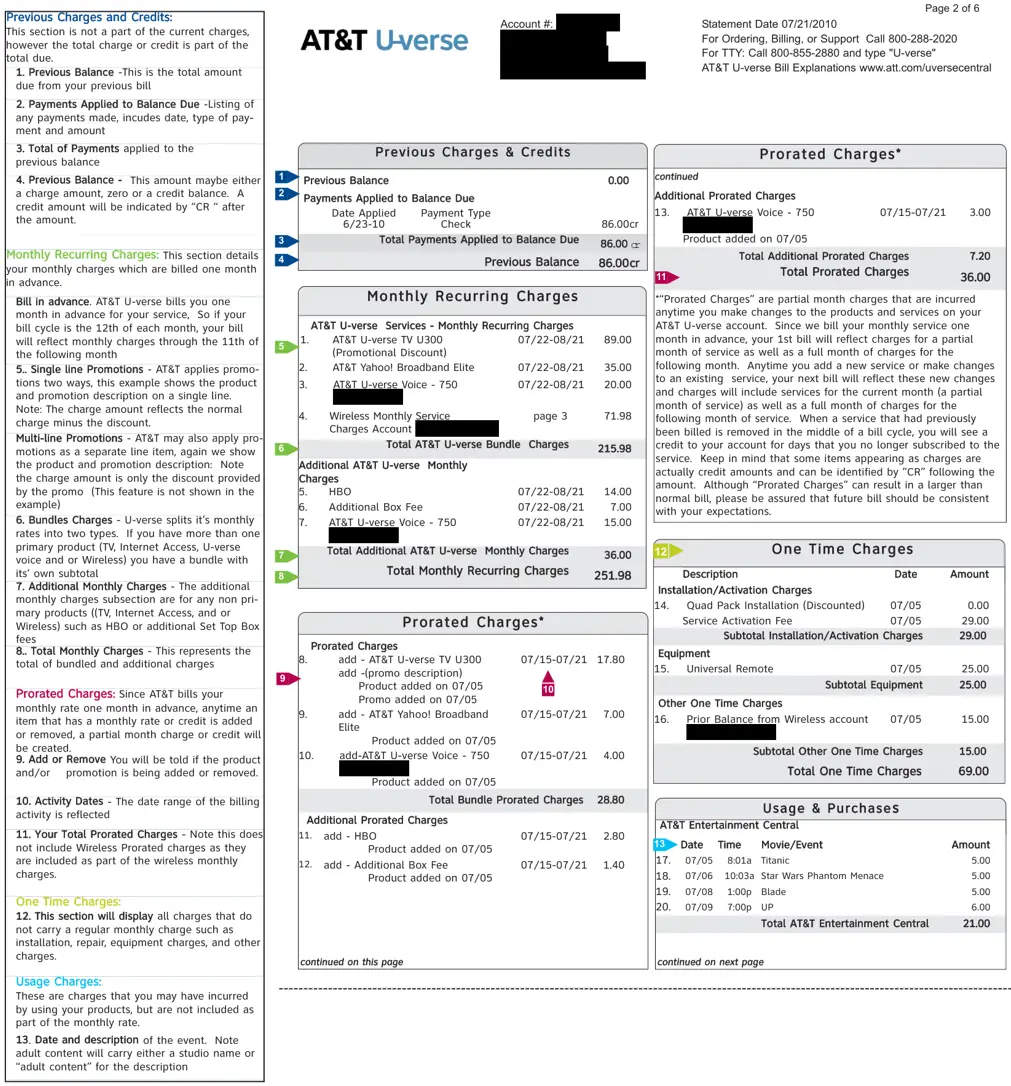
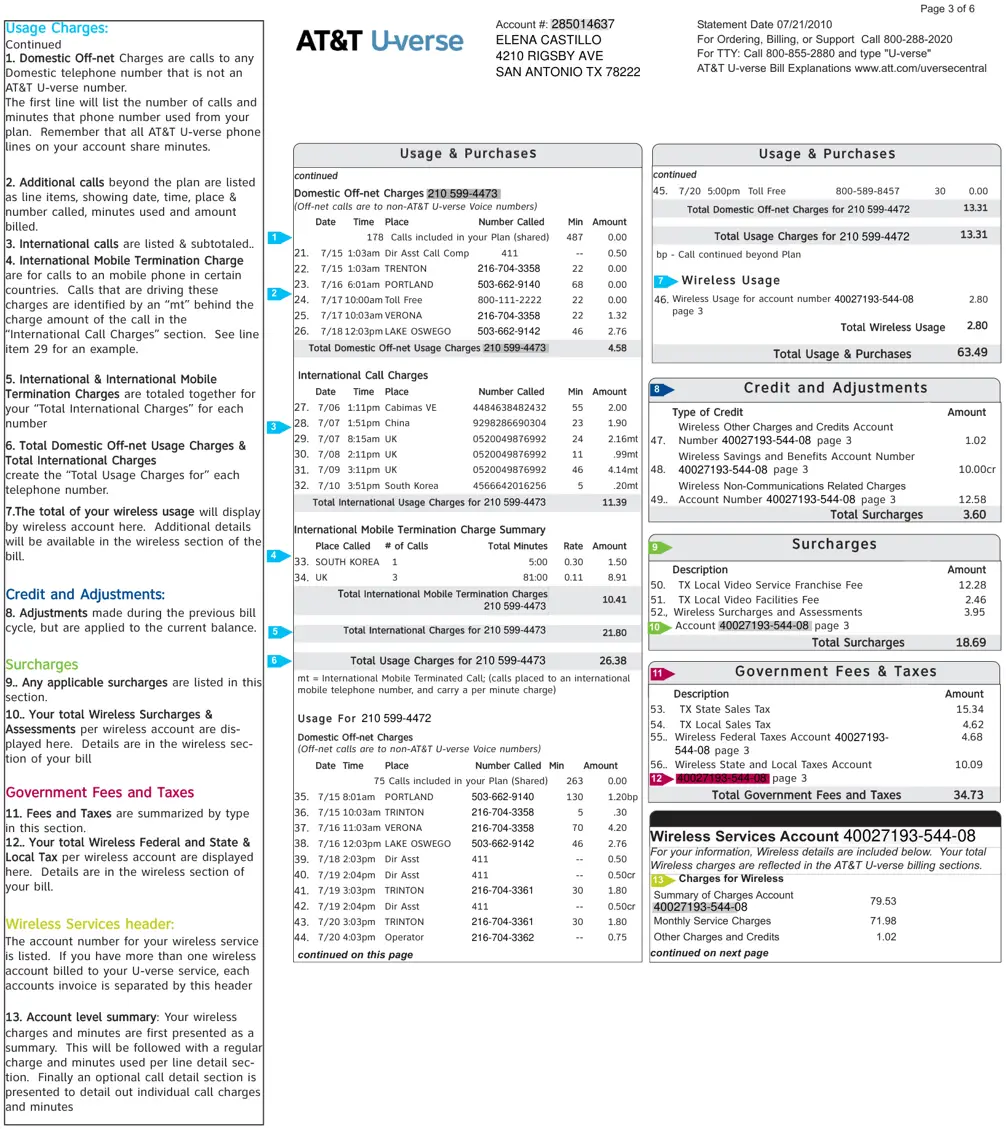
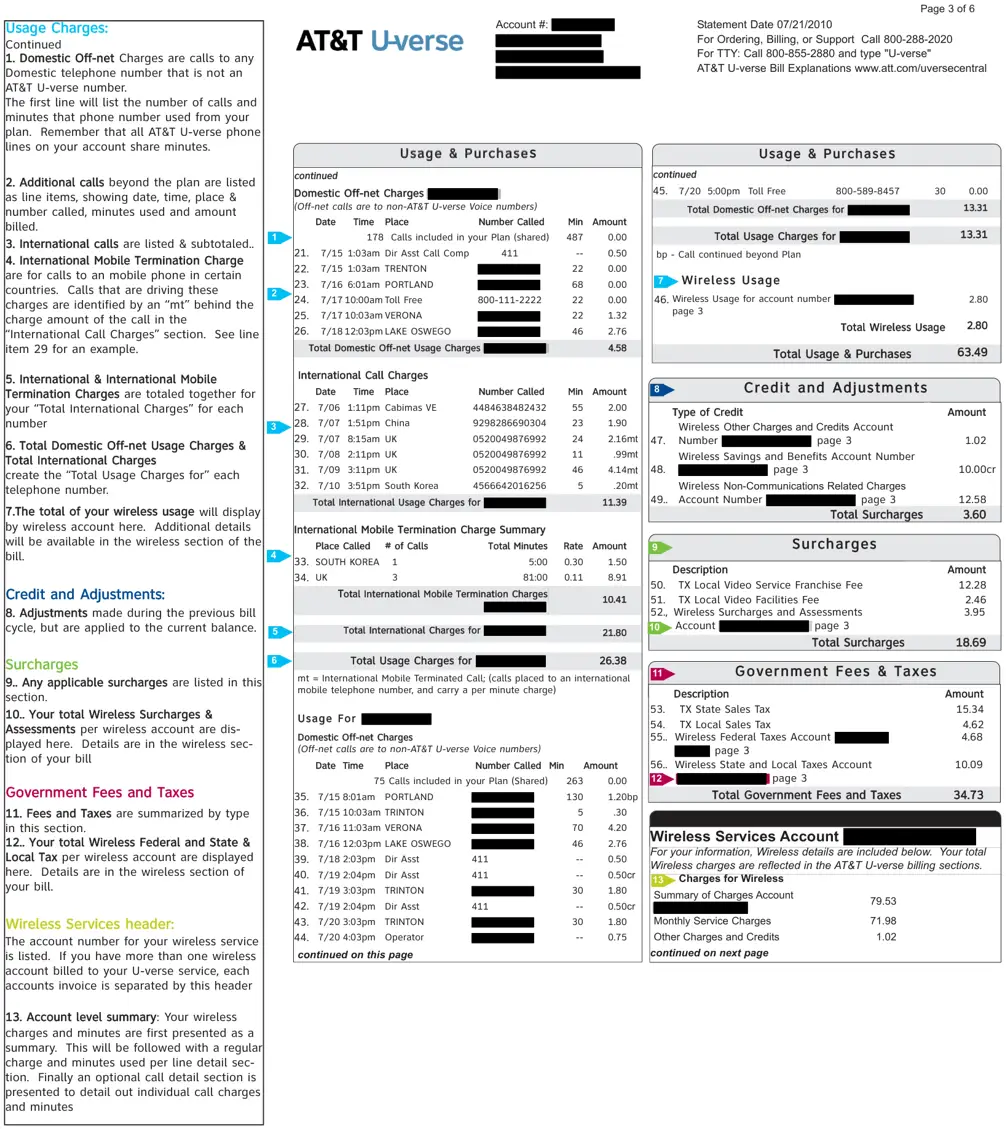
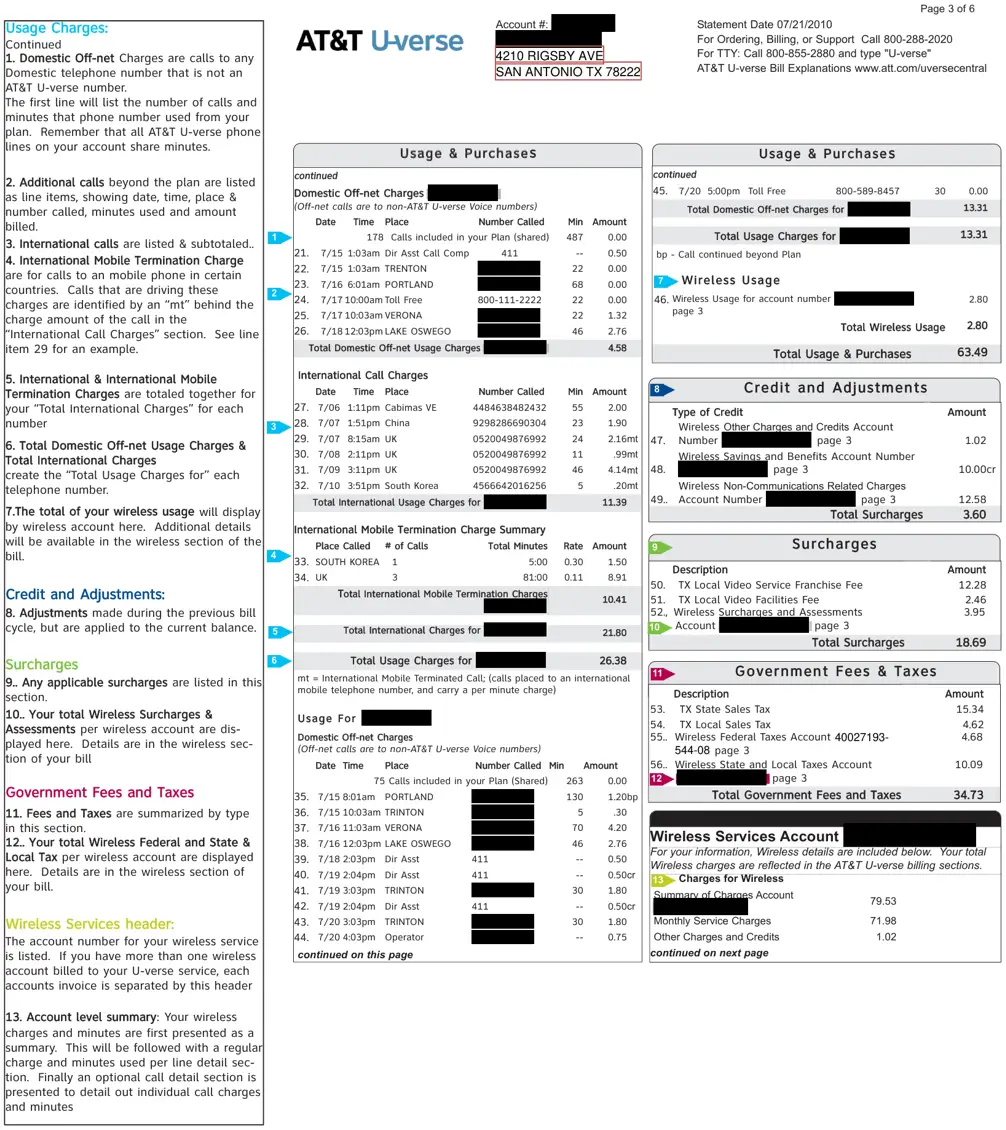
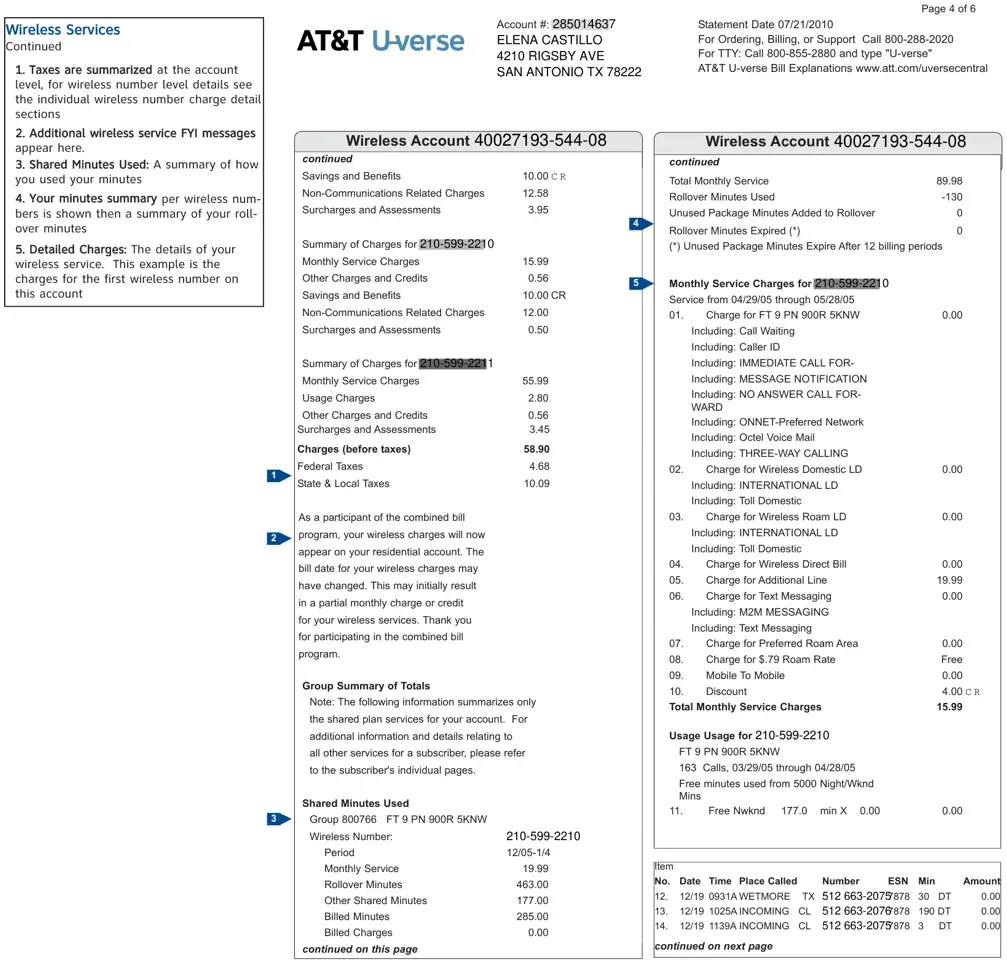
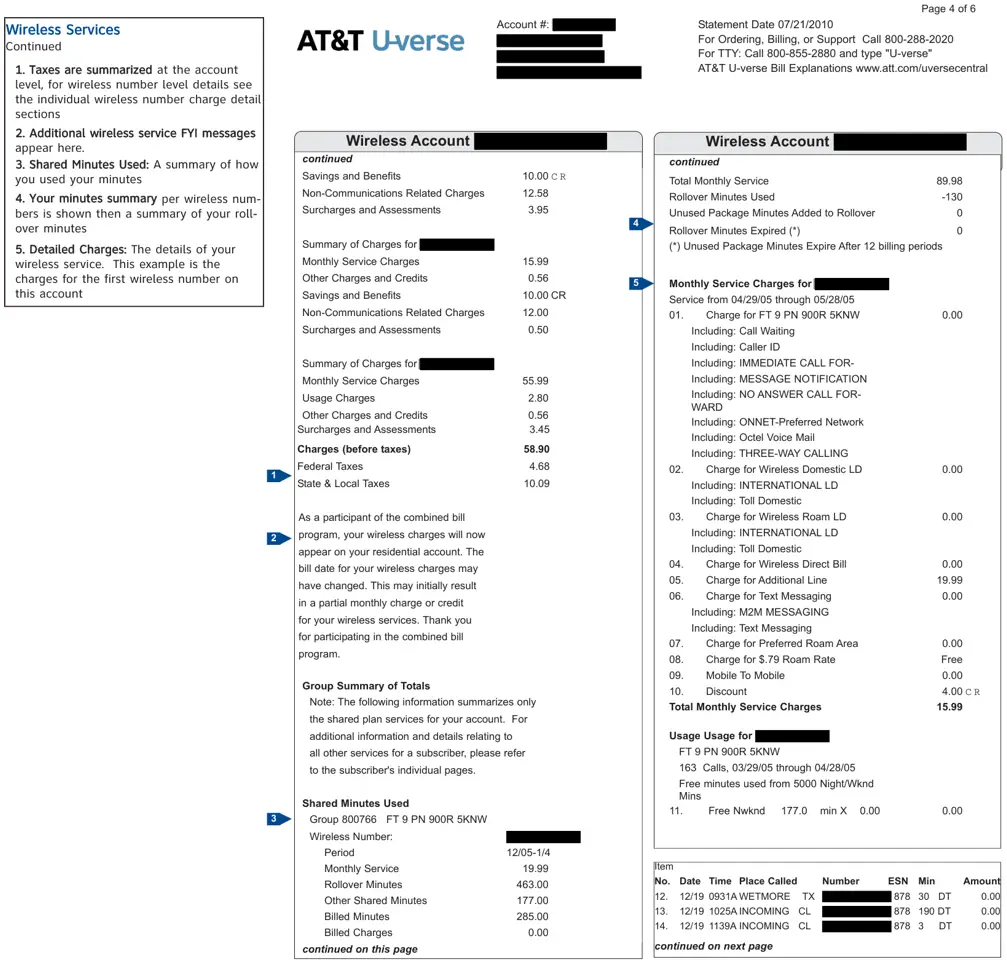
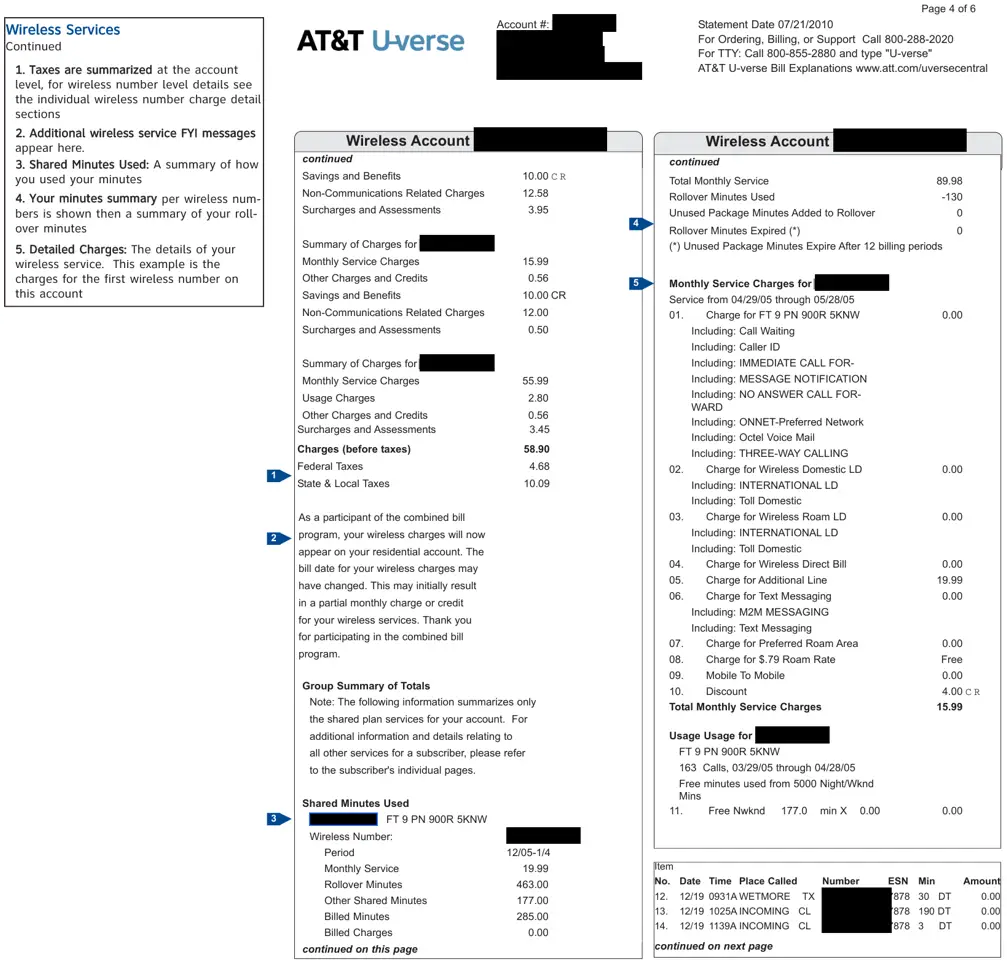
att-uverse-sample-bill.pdf
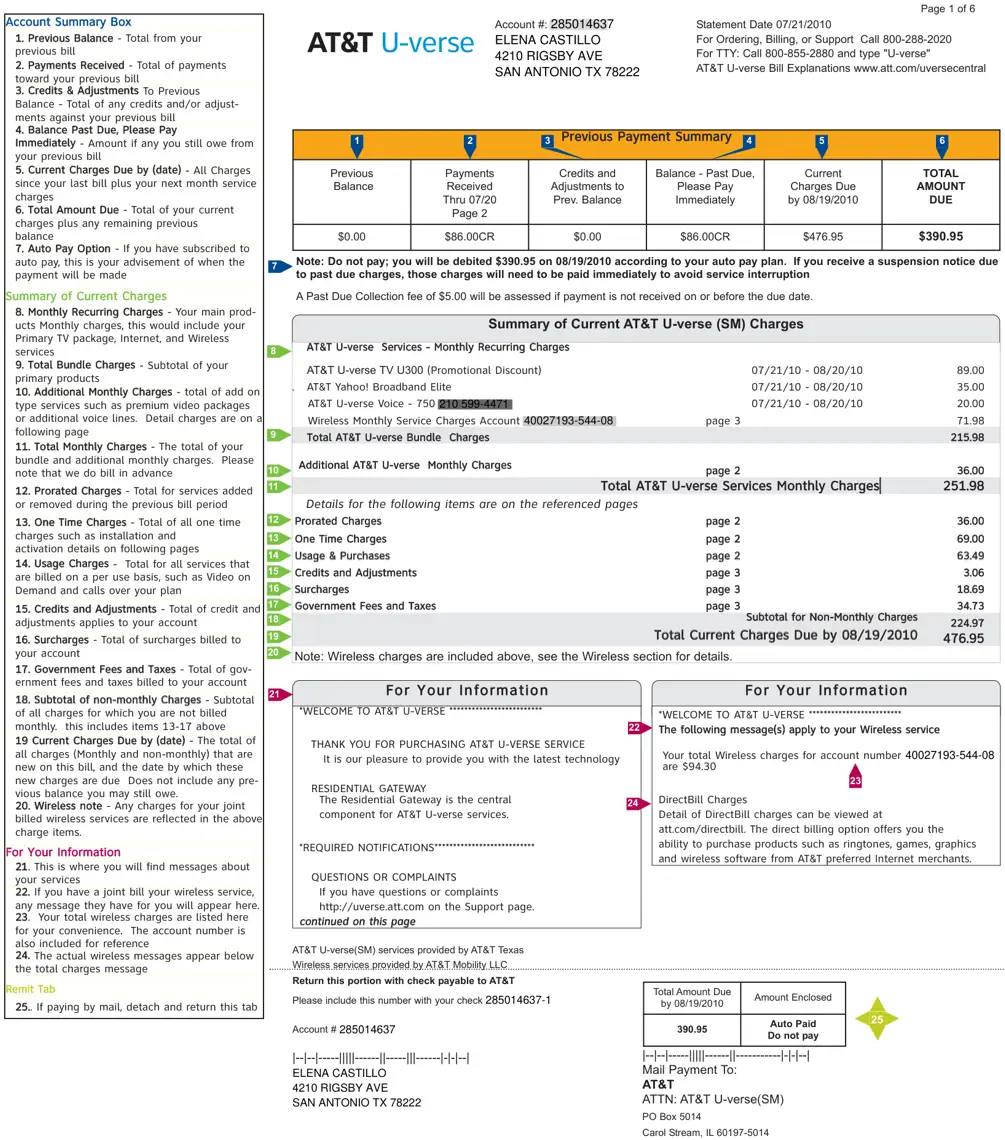
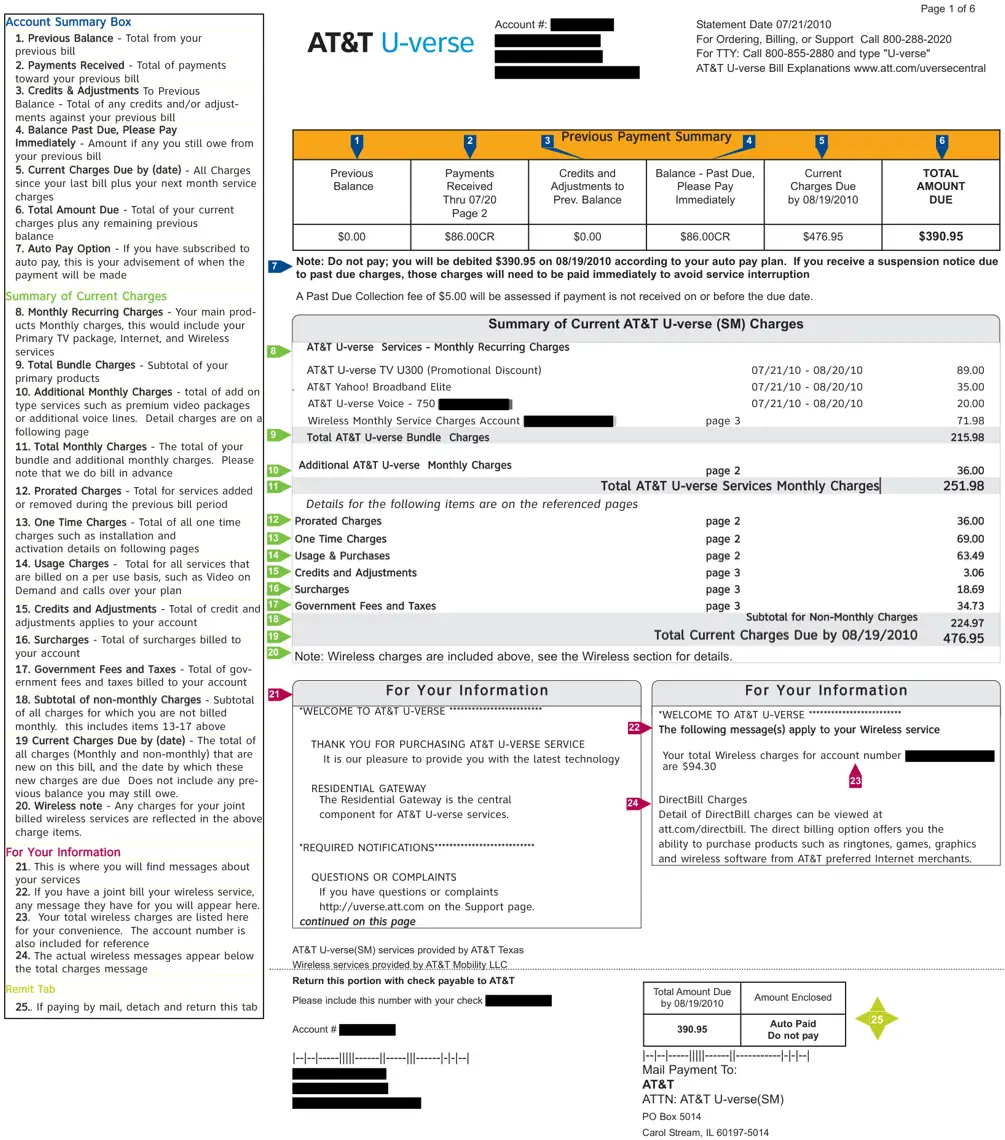
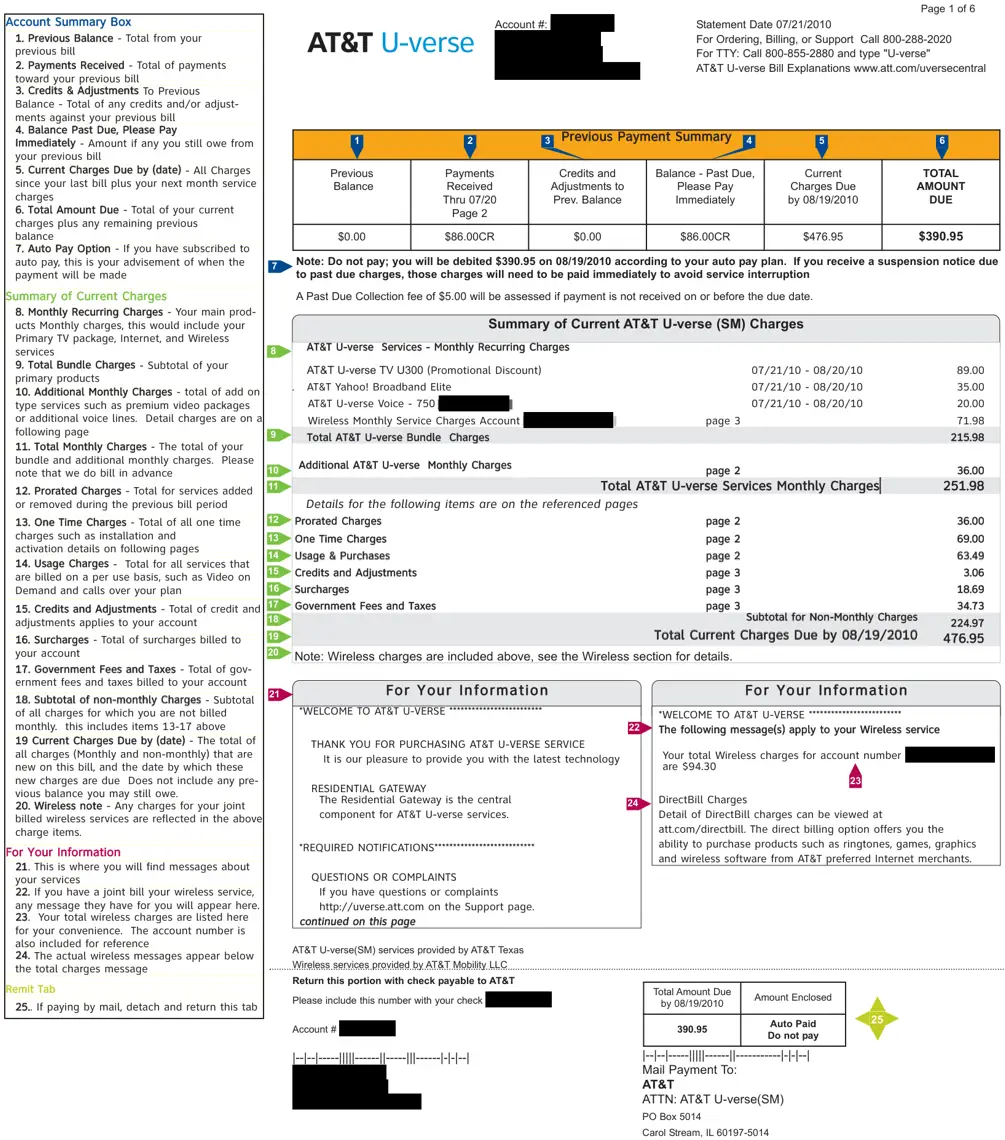
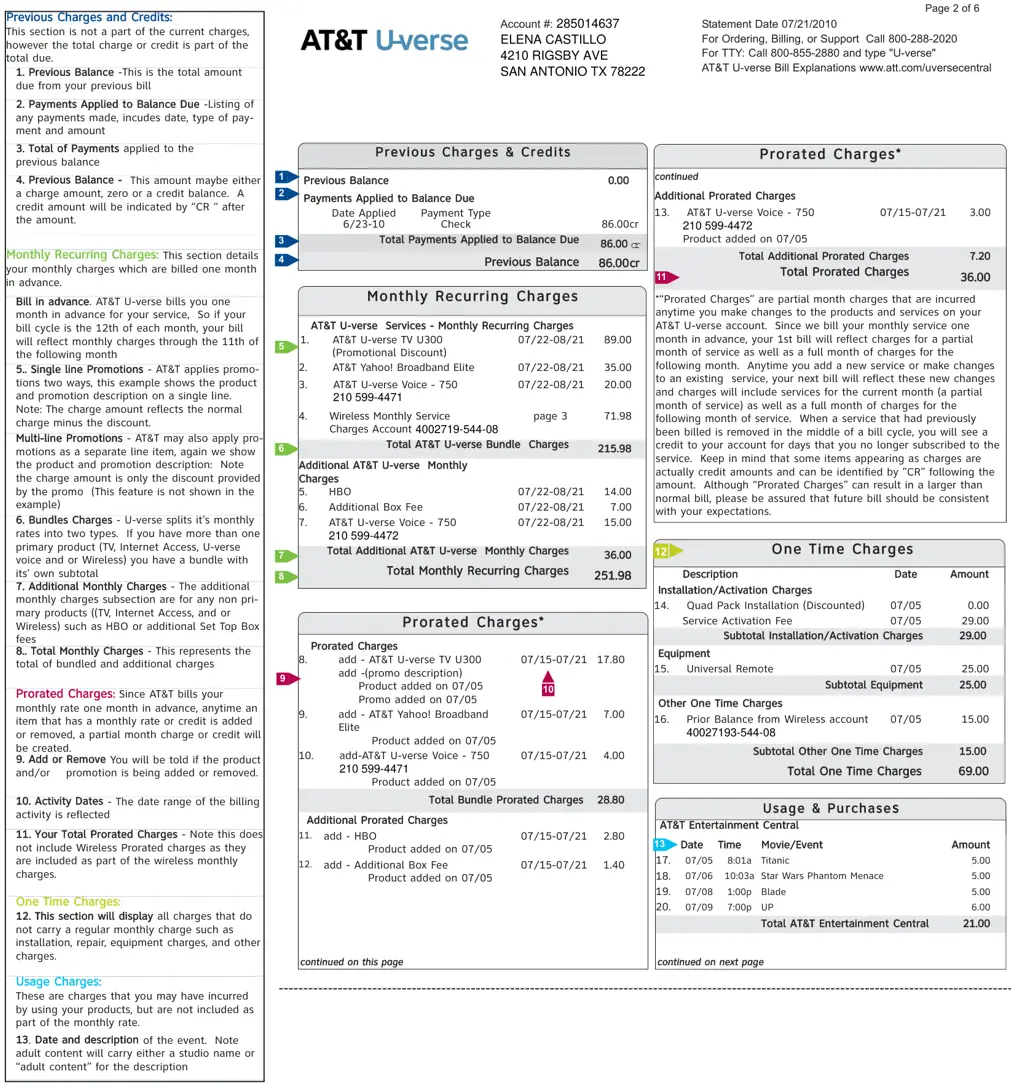
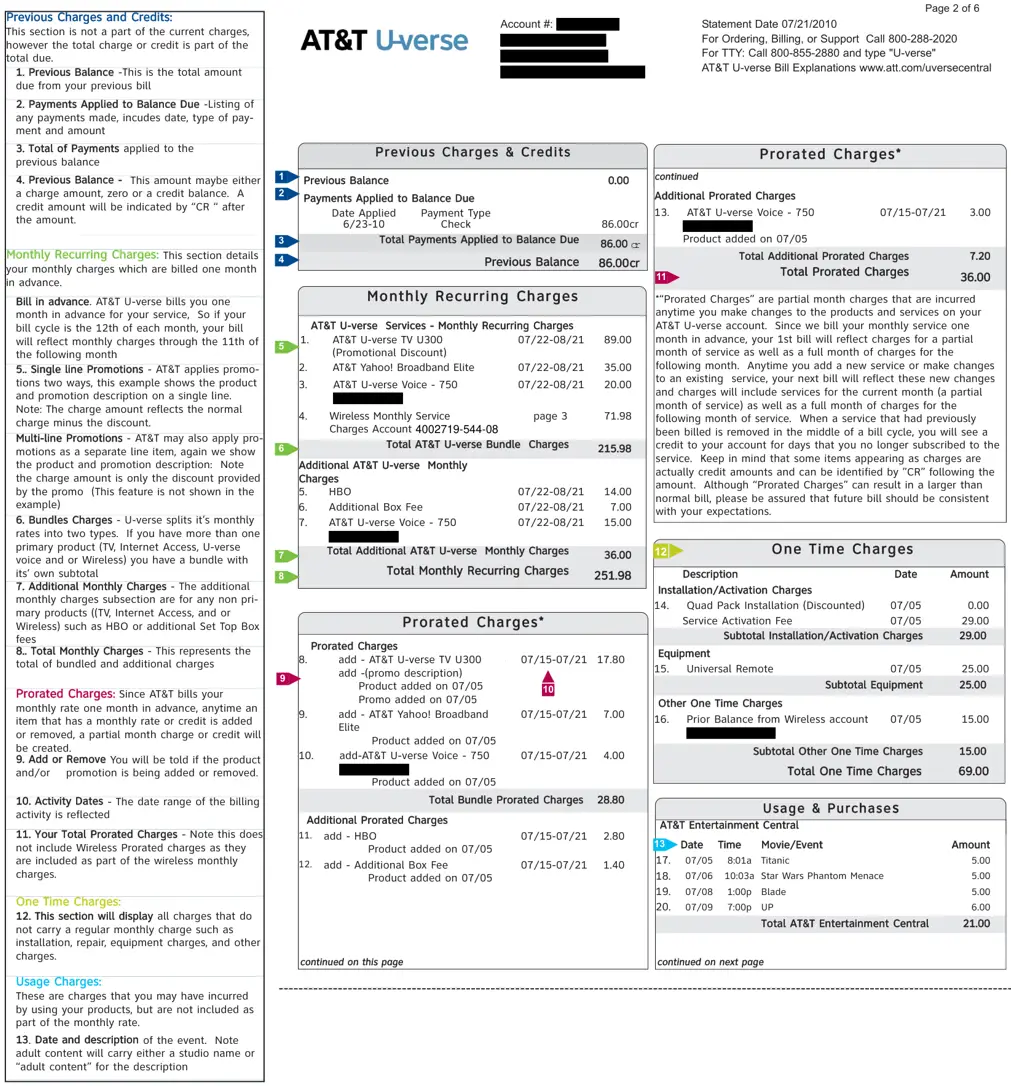
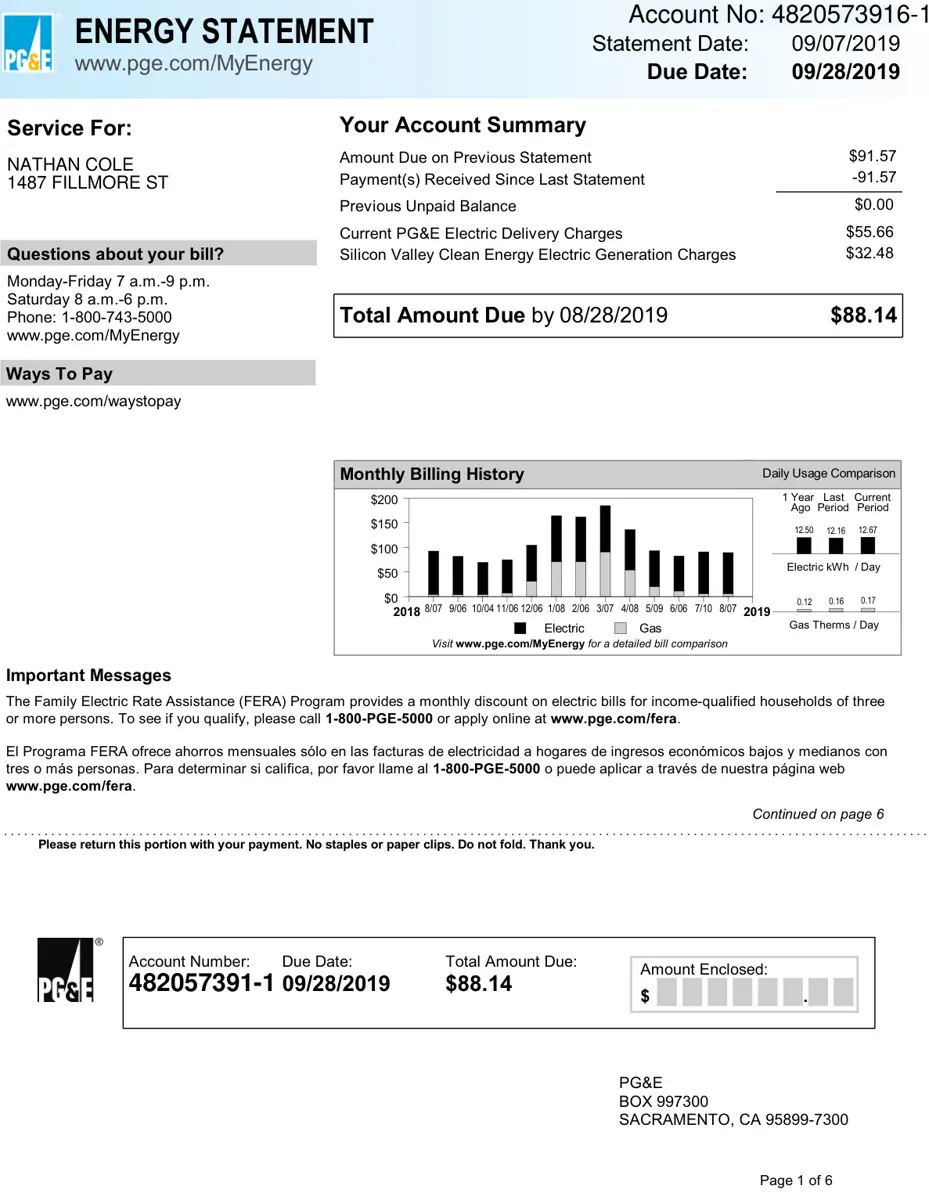
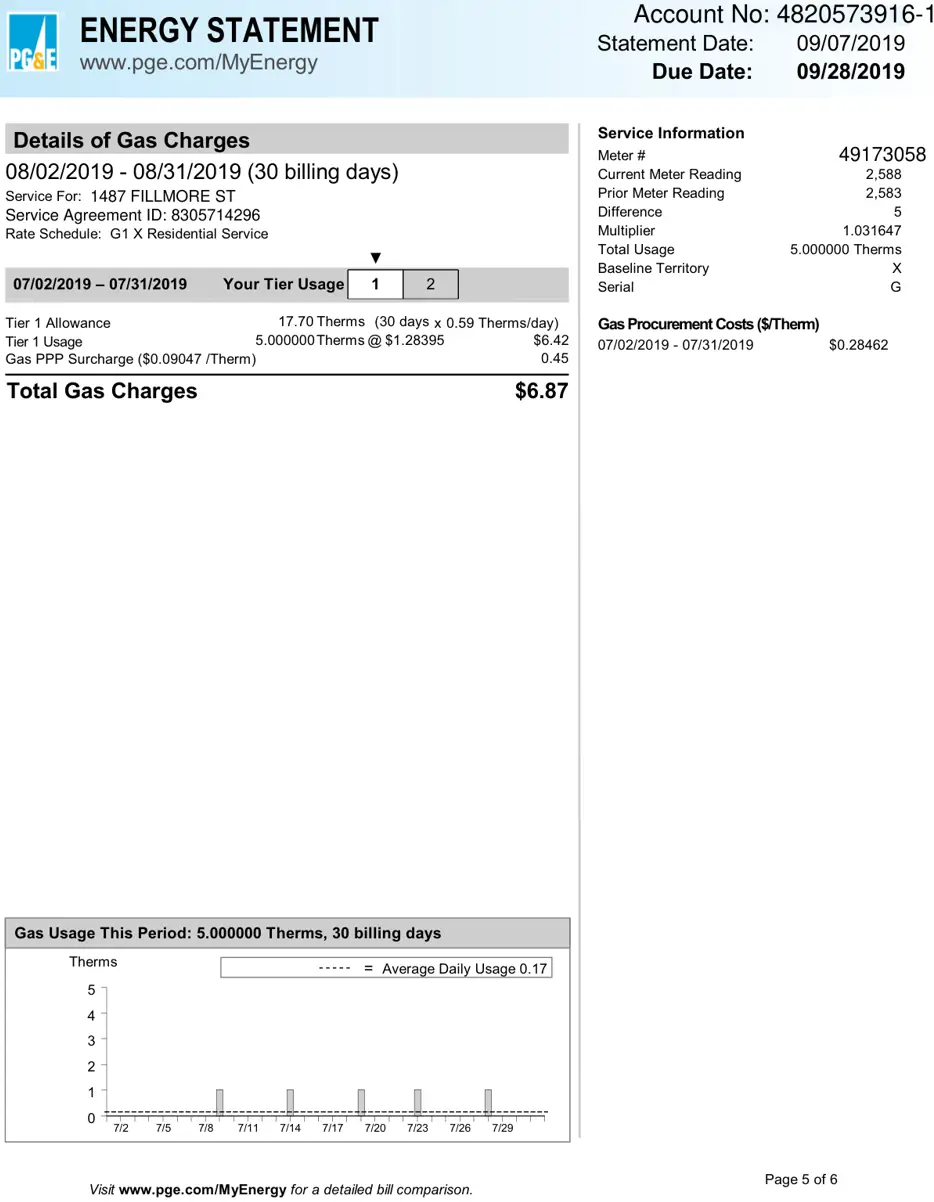
pge-sample-bill-sparky-joule.pdf
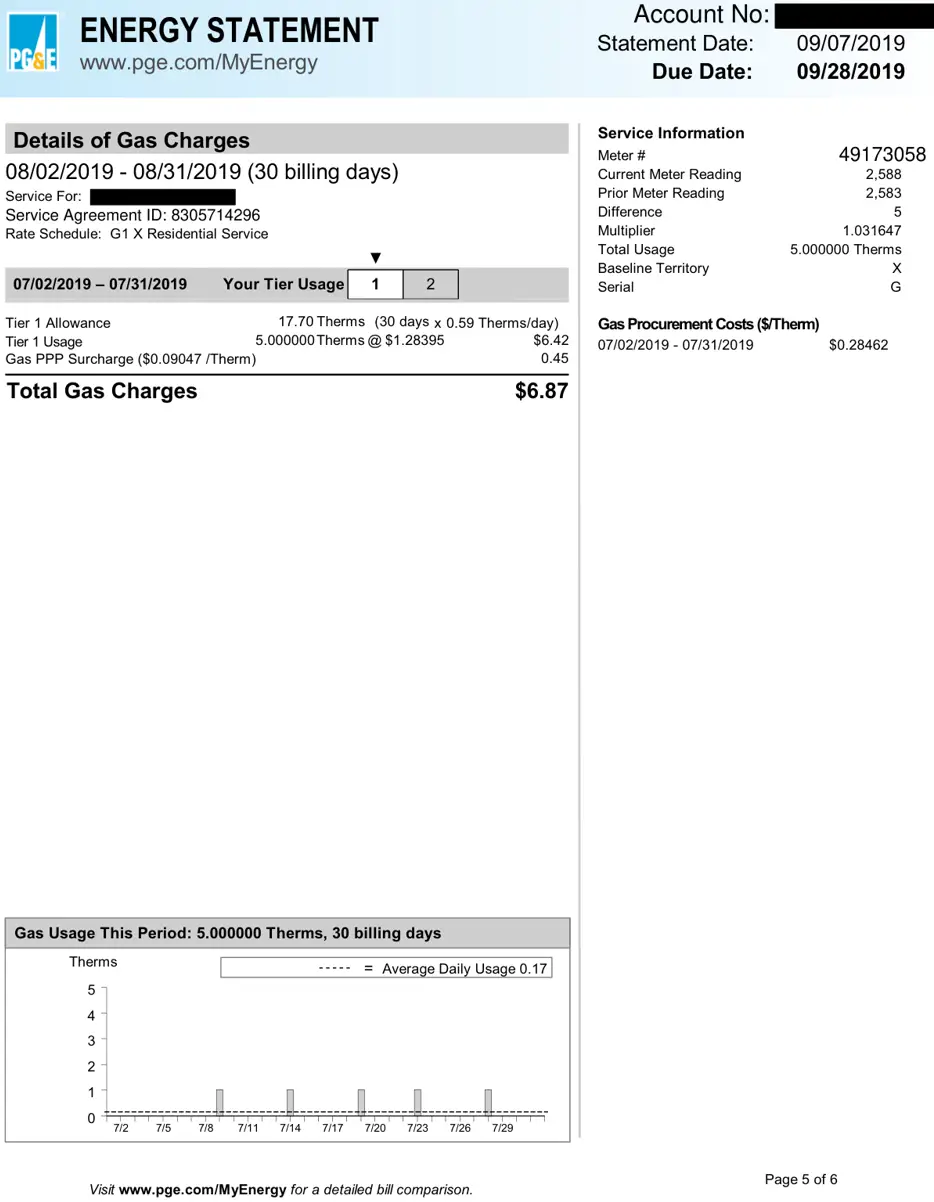
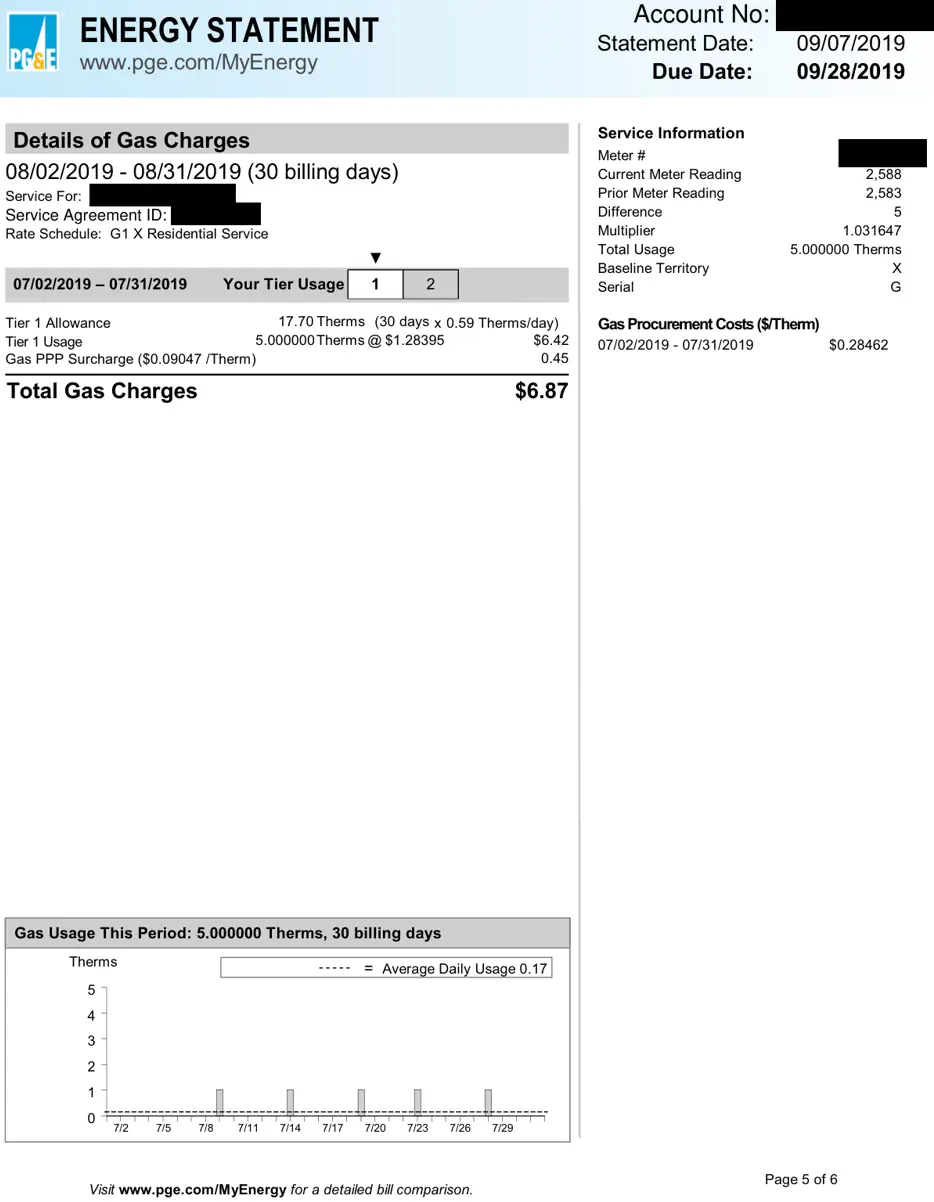
Full results
Cover v1.0.2 vs Alibaba Qwen 3 qwen3:latest · 18 real-world sample documents.
| metric · all 18 docs | Cover | Qwen 3 |
|---|---|---|
| Recall: PII correctly redacted | 100% | 75% |
| Leaks: confirmed PII left visible | 0 | 50 |
| Over-redaction: non-PII redacted by mistake | 12 | 188 |
| Speed: median time per PDF | ~3.2 sec/PDF | ~4.5 min/PDF |
Per-document breakdown: all 18 docs (one outlier can dominate the totals)
| document | Cover leaks | Qwen 3 leaks | Cover over | Qwen 3 over |
|---|---|---|---|---|
| ubs-portfolio-summary-sample | 0 | 4 | 0 | 90 |
| transunion-cameo-credit-report-sample | 0 | 18 | 0 | 35 |
| Fidelity-sample-statement | 0 | 3 | 2 | 22 |
| pershing-2024-sample-tax-yearend | 0 | 0 | 0 | 18 |
| 2025_Tax_Return_Okafor-Brennan | 0 | 1 | 0 | 14 |
| commercebank-sample-statement | 0 | 0 | 3 | 4 |
| allstate-auto-declarations-sample | 0 | 0 | 0 | 3 |
| att-uverse-sample-bill | 0 | 5 | 0 | 1 |
| medicare-sample-part-b-msn | 0 | 1 | 4 | 1 |
| Lease_Agreement_signed | 0 | 9 | 0 | 0 |
| WellsFargo-sample-statement | 0 | 0 | 2 | 0 |
| capitalone-sample-estatement | 0 | 2 | 0 | 0 |
| cfpb-draft-periodic-mortgage-statement | 0 | 1 | 0 | 0 |
| cfpb-ficus-bank-loan-estimate-sample | 0 | 4 | 0 | 0 |
| cfpb-sample-credit-card-statement-handout | 0 | 0 | 0 | 0 |
| cigna-eob-example | 0 | 1 | 0 | 0 |
| fidelity-large-print-sample-statement | 0 | 0 | 0 | 0 |
| pge-sample-bill-sparky-joule | 0 | 1 | 1 | 0 |
| TOTAL | 0 | 50 | 12 | 188 |
How the test works
Test set: 18 public sample documents (149 verified PII items), held fixed across runs so results stay comparable. Every engine redacted the same documents; each output is scored against a Claude-authored gold standard (confirmed + ambiguous tiers), and every counted over-redaction is kept auditable. Pages and the leaderboard use the same weighting: leaked private details weigh most, and over-redactions count too.